The Design and Implementation of Tiered Storage in RocketMQ
By Senze Zhang
With the official release of RocketMQ 5.1.0, tiered storage, as a new independent module of RocketMQ, has become a milestone in Technical Preview. RocketMQ 5.1.0 allows users to offload messages from local disks to other cheaper storage media, and it can extend the message retention duration at a lower cost. This article details the design and implementation of RocketMQ tiered storage.
Design Overview
The tiered storage of RocketMQ allows you to offload data to other storage media without affecting hot data reading and writing. The tiered storage of RocketMQ is suitable for the following scenarios:
- Separation of Hot and Cold Data: RocketMQ caches new messages in the page cache called hot data. When the cached data exceeds the memory capacity, hot data will be moved out and become cold data. If consumers try to consume cold data, cold data will be reloaded from the hard disk to the page cache, which will lead to read and write I/O competition and occupy the space of the page cache. This problem can be avoided by switching the read link of cold data to tiered storage.
- Extended Message Retention Duration: Offloading messages to a larger and cheaper storage medium allows for longer message retention duration at a lower cost. At the same time, tiered storage supports specifying different message retention durations for topics, and message TTL can be flexibly configured according to business needs.
The biggest difference between the implementation of tiered storage in RocketMQ and Kafka and Pulsar is that we upload messages in quasi-real-time instead of waiting for a CommitLog to be full before uploading, mainly based on the following considerations:
- Cost Sharing: For tiered storage in RocketMQ, you need to convert the global CommitLog file to the topic dimension and rebuild the message index. Processing the CommitLog file at one time will cause performance glitches.
- It Is More Friendly to Small-Specification Instances: Small-specification instances are often configured with a small amount of memory, which means hot data will be moved out and become cold data faster. Waiting for the CommitLog to be full before uploading has a risk of cold reading. The quasi-real-time upload method avoids the risk of cold reading during message upload and enables cold data to be read from tiered storage as soon as possible.
Quick Start
The tiered storage is designed to reduce the mental burden of users. Users can switch between hot and cold data read and write links without changing the client, and users can use tiered storage capabilities by simply modifying the server configuration. The following two steps are required to achieve the target above:
- Modify the Broker configuration and specify the org.apache.rocketmq.tieredstore.TieredMessageStore as the messageStorePlugIn
- Configure the storage medium you want to use. Take unloading the message to a hard disk as an example: configure tieredBackendServiceProvider to org.apache.rocketmq.tieredstore.provider.posix.PosixFileSegment and specify tieredStoreFilepath as the new file storage path:
Optional: You can modify the implementation of tieredMetadataServiceProvider to switch the metadata storage to json-based file storage.
More instructions and configuration items can be found on GitHub for the README[1] of tiered storage.
Technical Architecture
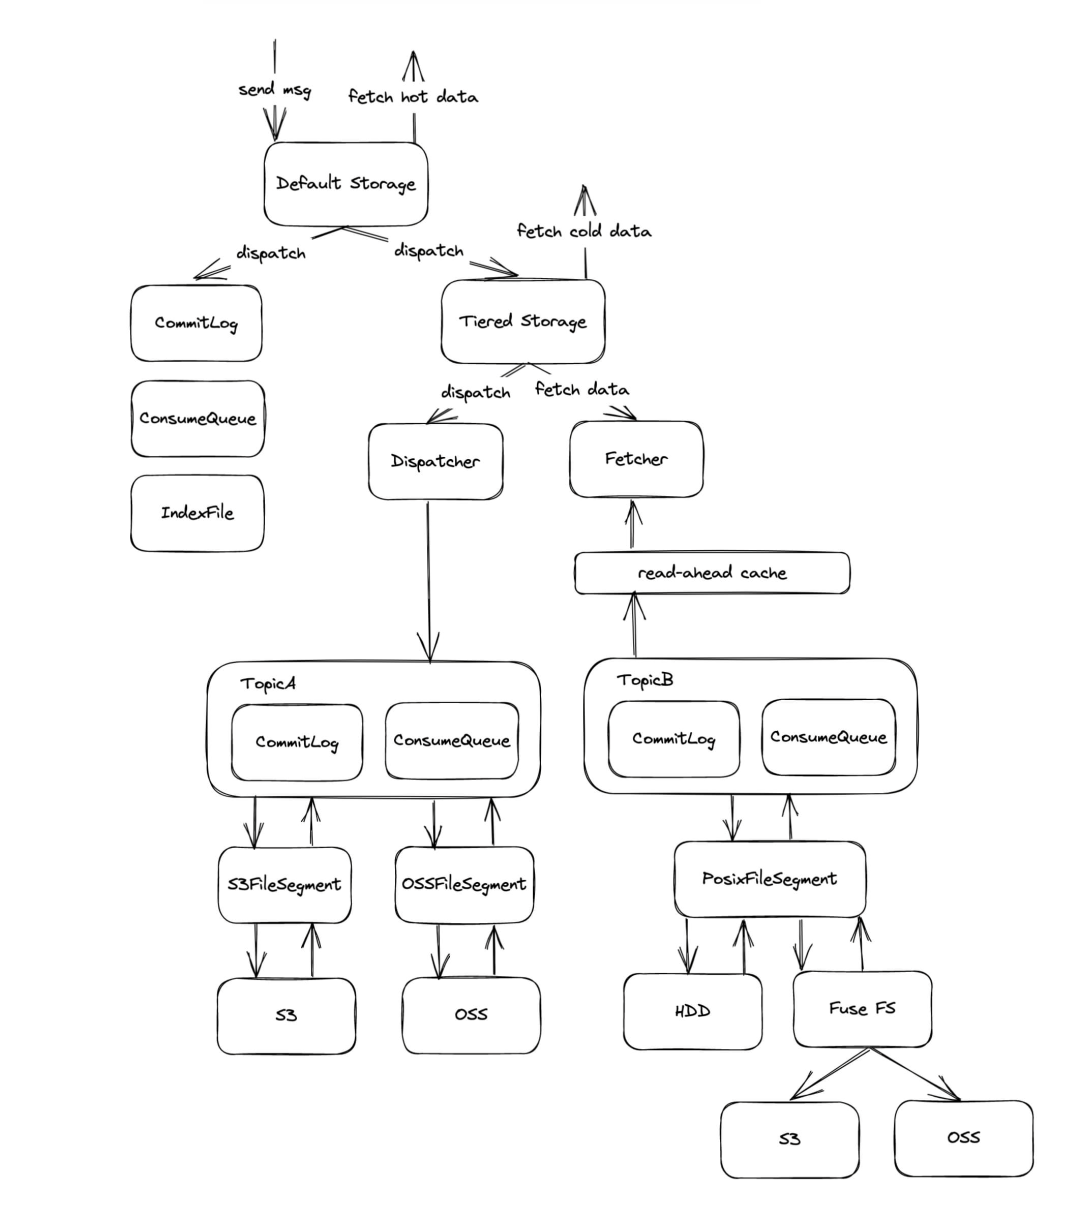
Architecture
Access Layer: TieredMessageStore/TieredDispatcher/TieredMessageFetcher
The access layer implements some of the read and write interfaces in MessageStore and adds asynchronous semantics to them. TieredDispatcher and TieredMessageFetcher implement the upload/download logic of tiered storage respectively. Compared with the underlying interface, more performance optimization has been done here, including using an independent thread pool to avoid slow I/O blocking access to hot data and using the read-ahead cache to optimize performance, etc.
Container Layer: TieredCommitLog/TieredConsumeQueue/TieredIndexFile/TieredFileQueue
The container layer implements logical file abstraction similar to DefaultMessageStore. It divides files into CommitLog, ConsumeQueue, and IndexFile, and each logical file type holds a reference to the underlying physical file through FileQueue. The difference is because the dimension of CommitLog in tiered storage is changed to the queue dimension.
Driver Layer: TieredFileSegment
The driver layer is responsible for maintaining the mapping between logical files and physical files and connecting TieredStoreProvider to the underlying file system read/write interfaces (POSIX, S3, OSS, and MinIO). Currently, PosixFileSegment implementations are provided to transfer data to other hard disks or mount data to OSS through FUSE.
Message Upload
Message upload for tiered storage in RocketMQ is triggered by the dispatch mechanism. When the tiered storage is initialized, TieredDispatcher is registered as the dispatcher of CommitLog. This way, whenever a message is sent to the Broker, the Broker calls TieredDispatcher to dispatch the message, and the TieredDispatcher writes the message to the upload buffer and returns success immediately. The entire dispatch process does not contain any blocking logic to ensure that the construction of the local ConsumeQueue is not affected.
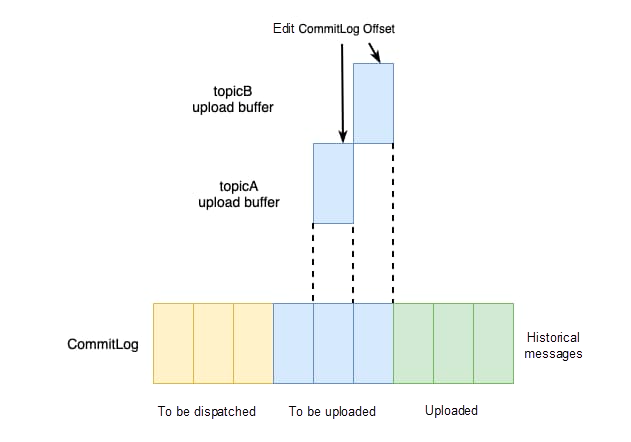
TieredDispatcher
The content written to the upload buffer by TieredDispatcher is only a reference to the message, and the message body will not be buffered into the memory. The CommitLog is created based on the queue dimension for tiered storage. In this case, the commitLog offset field needs to be regenerated.
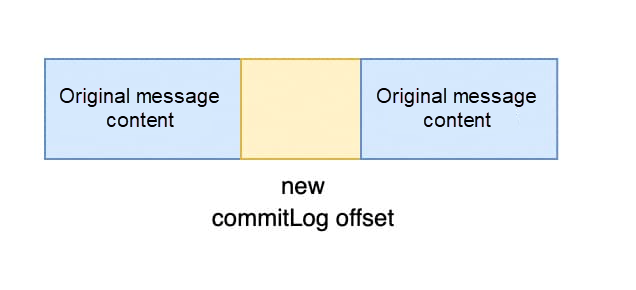
Upload Buffer
When the upload buffer is triggered to read the commitLog offset field of each message, the new commitLog offset is embedded into the original message by concatenating.
Upload Progress Control
Each queue has two key offsets to control the upload progress:
- dispatch offset: The offset that has been written to the cache but not uploaded.
- commit offset: The offset that has been uploaded.
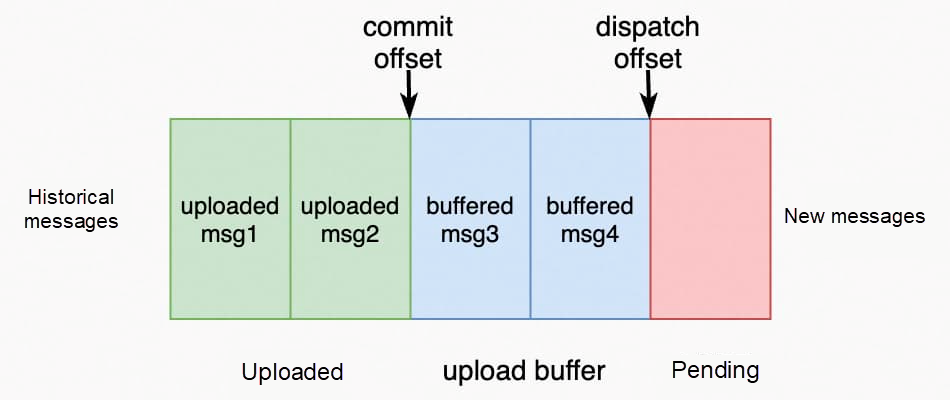
Upload Progress
Let’s take Consumer as an example. The dispatch offset is the offset for pulling messages, and the commit offset is the offset for confirming consumption. The portion between the commit offset and the dispatch offset is the pulled but unconsumed messages.
Message Reading
TieredMessageStore implements the interface related to message reading in MessageStore. It determines whether to read messages from tiered storage through queue offset in the request. The following policies are available based on the configuration (tieredStorageLevel):
- DISABLE: Reading messages from tiered storage is disabled.
- NOT_IN_DISK: Messages not in DefaultMessageStore are read from tiered storage.
- NOT_IN_MEM: Messages not in the page cache (cold data) are read from tiered storage.
- FORCE: All messages must be read from tiered storage. Currently, this parameter is only used for testing.
/**
  * Asynchronous get message
  * @see #getMessage(String, String, int, long, int, MessageFilter)
  getMessage
  *
  * @param group Consumer group that launches this query.
  * @param topic Topic to query.
  * @param queueId Queue ID to query.
  * @param offset Logical offset to start from.
  * @param maxMsgNums Maximum count of messages to query.
  * @param messageFilter Message filter used to screen desired
  messages.
  * @return Matched messages.
  */
CompletableFuture<GetMessageResult> getMessageAsync(final String group, final String topic, final int queueId,
    final long offset, final int maxMsgNums, final MessageFilter
messageFilter);
Messages that need to be read from tiered storage are processed by TieredMessageFetcher. First, TieredMessageFetcher checks whether the parameters are valid and then initiates a pull request based on the queue offset. TieredConsumeQueue or TieredCommitLog converts the queue offset to the physical offset of the corresponding file to read messages from TieredFileSegment.
// TieredMessageFetcher#getMessageAsync similar with
TieredMessageStore#getMessageAsync
public CompletableFuture<GetMessageResult> getMessageAsync(String
group, String topic, int queueId,
        long queueOffset, int maxMsgNums, final MessageFilter
messageFilter)
TieredFileSegment maintains each physical file offset stored in the file system and reads required data through interfaces implemented for the different storage media.
/**
  * Get data from backend file system
  *
  * @param position the index from where the file will be read
  * @param length the data size will be read
  * @return data to be read
  */
CompletableFuture<ByteBuffer> read0(long position, int length);
Read-Ahead Cache
When TieredMessageFetcher reads messages, more messages are read in advance for the next use. These messages are temporarily stored in the read-ahead cache.
protected final Cache<MessageCacheKey /* topic, queue id and queue
offset */,
SelectMappedBufferResultWrapper /* message data */> readAheadCache;
The design of the read-ahead cache refers to TCP Tahoe. The number of messages read ahead each time is controlled by the additive-increase and multiplicative-decrease mechanism, similar to the congestion window:
- Additive Increase: Starting from the smallest window, the number of messages increased each time is equal to the batchSize on the client.
- Multiplicative Decrease: If all cached messages are not pulled within the cache expiration time, the number of pre-read messages is reduced by half when the cache is cleared.
The read-ahead cache supports sharding and concurrent requests when a large number of messages are read to achieve higher bandwidth and lower latency.
The read-ahead cache of a topic message is shared by all groups that consume this topic. The cache invalidation policy is listed below:
- All groups that subscribe to this topic have accessed the cache.
- The cache expires after the cache expiration time.
Failback
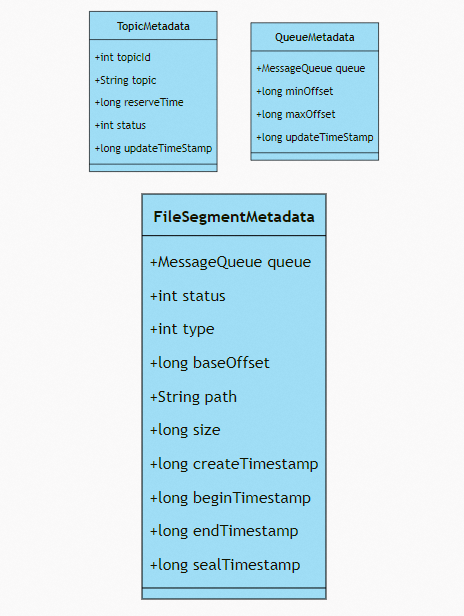
The upload progress is controlled by commit offset and dispatch offset. Tiered storage creates metadata for each topic, queue, and fileSegment and persists these two offsets. When Broker restarts, it resumes from the metadata and continues to upload messages from the commit offset. Previously cached messages are re-uploaded and not lost.
Development Plan
Cloud-native-oriented storage systems are expected to maximize the value of cloud storage, and OSS is the dividend of cloud computing. The tiered storage of RocketMQ is expected to take advantage of the low cost of OSS to extend the message storage time and expand the value of data. It also aims to use its shared storage features to obtain both cost and data reliability in a multi-replica architecture and evolve to a Serverless architecture in the future.
Tag Filtering
When tiered storage pulls messages without calculating whether the tag of the message matches, the tag filtering is performed by the client. This will bring additional network overhead. We plan to add tag filtering capabilities on the server in the future.
Broadcasting Consumption and Multiple Consumers with Different Consumption Schedules
Read-ahead cache invalidation requires that all groups that subscribe to this topic have accessed the cache. This is difficult to trigger when the consumption progress of multiple groups is inconsistent, resulting in the accumulation of useless messages in the cache.
You need to calculate the consumption QPS of each group to estimate whether a group can use cached messages before the cache expires. If a cached message is not expected to be accessed before it expires, it should be expired immediately. Correspondingly, for broadcasting consumption, the message expiration policy should be optimized so the message expires after all clients have read the message.
Integration with High-availability Architecture
Currently, we mainly face the following three problems:
- Metadata Synchronization: The problems with metadata are how to reliably synchronize metadata among multiple nodes and how to calibrate and complete missing metadata when slave nodes are promoted.
- Prohibit Uploading Messages after Confirm Offset: In order to avoid message rollback, the maximum offset to be uploaded cannot exceed the confirm offset.
- Quick Start of Tiered Storage When Slave Nodes Are Promoted: Only master nodes have write permissions. The tiered storage needs to be quickly pulled up to perform resumable upload after slave nodes are promoted.
Related Links
[1] README
https://github.com/apache/rocketmq/blob/develop/tieredstore/README.md
Read previous post:
Read next post:
-

-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Comments
-
-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Related Products
-
 ApsaraMQ for RocketMQ
 is a distributed message queue service that supports reliable message-based asynchronous communication among microservices, distributed systems, and serverless applications.
Learn More -
ApsaraMQ for MQTT
A message service designed for IoT and mobile Internet (MI).
Learn More -
Message Queue for RabbitMQ
A distributed, fully managed, and professional messaging service that features high throughput, low latency, and high scalability.
Learn More -
 Message Queue for Apache Kafka
A fully-managed Apache Kafka service to help you quickly build data pipelines for your big data analytics.
Learn More
More Posts by Alibaba Cloud Native Community
- Best Practices for Skill Evaluation and Optimization Based on Alibaba Cloud AgentLoop
- DeepSeek Harness Evaluation Practice Based on Alibaba Cloud AgentLoop
- 97.1% Lower Gateway Latency: Open-Source Higress vs. Alibaba Cloud AI Gateway Serverless Enterprise Edition
- Alibaba Cloud's Open-Source AI Agent Handbook, 3K+ GitHub Stars
- DeepSeek Harness: A Practical Guide to Comprehensive Observability
- Alibaba Cloud AI Gateway Intelligent Routing Is Now Live
- After Everything Becomes a Plugin: A New Paradigm for Agent Engineering
- AgentScope Service: Open-Source Agent Control Plane with DeepSeek Harness Support
- Seamless AI Safety: Integrating Qwen3Guard into Higress with Zero Code Changes
- DeepSeek's SuperAgent and Our Practice