Track Winner, Global AI Hackathon Series with Qwen Cloud
There is a word in Vietnamese — Quên — that means "to forget." It also happens to sound almost exactly like "Qwen." For solo builder Pham Thanh Hang, that coincidence was too good to pass up, and it became the name and the entire thesis of a hackathon project: an AI memory layer whose superpower is not what it remembers, but what it deliberately lets go.
Almost every agent memory system on the market is append-only. It writes everything down and forgets nothing — which sounds safe until you realize that a pile of stale facts eventually gets asserted as truth. Quên takes the opposite bet: it treats trust as a _runtime decision_, not a stored property, and it genuinely forgets.
Consider what goes wrong with a memory that never forgets. A user changes their mind; the old preference is still in the store. A fact was true last quarter; the agent still repeats it this quarter with total confidence. The memory becomes a liability dressed up as an asset.
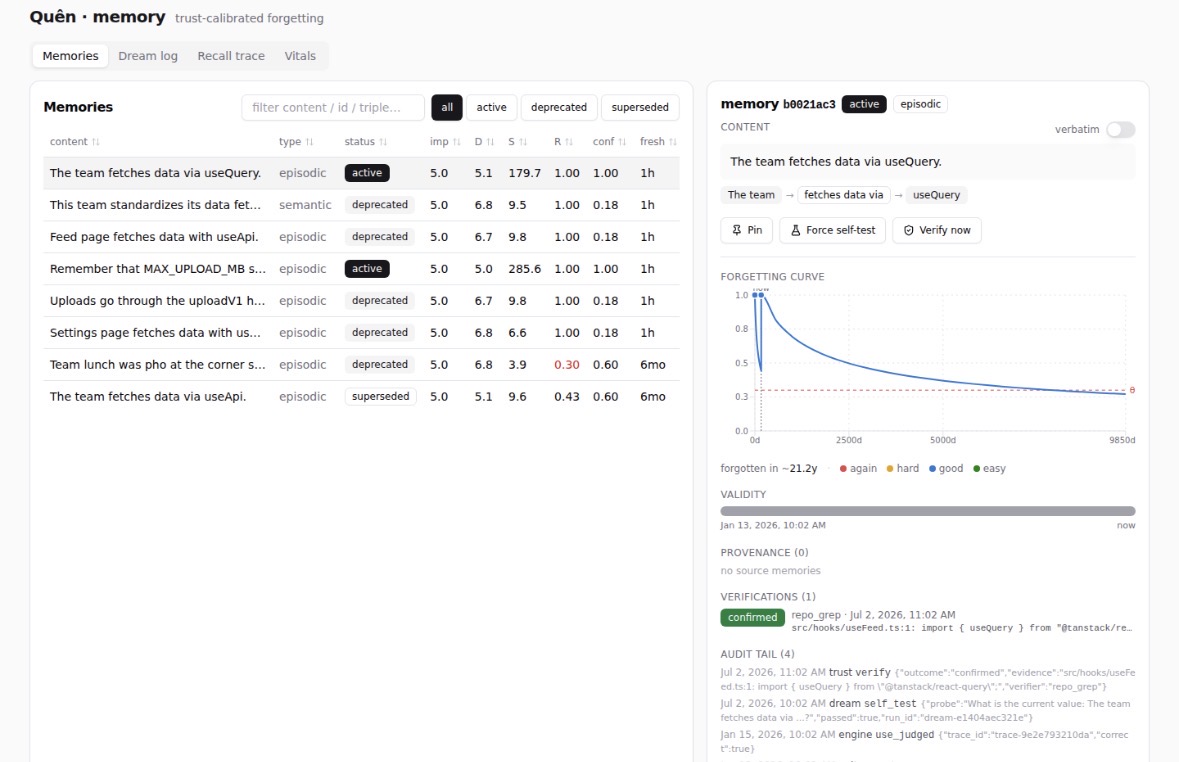
Quên solves this with a design that is unusually rigorous for a hackathon build. On the write path, Qwen extracts only salient facts as (subject, relation, object) triples, and a salience gate skips whatever a base model already knows — so the store fills with signal, not noise. Confidence is derived from source authority, ranked so a press release outweighs a doc and a doc outweighs a casual chat message. A background "dream" pass periodically consolidates episodic memories into generalizations, resolves contradictions, and evicts what has decayed below usefulness. And nothing is ever hard-deleted — Quên keeps tombstones, so the forgetting is auditable rather than destructive.
The cleverest part happens at answer time. Retrieval is relevance-dominant and token-budgeted, and each memory carries FSRS spaced-repetition retention state — the same forgetting-curve math used by serious flashcard apps, imported verbatim — plus bi-temporal validity and confidence. Stated confidence tracks each memory's freshness, so the agent sounds less certain about things it learned a while ago.
Then comes the closed loop almost nobody else ships: _verify-before-answer_. When a memory's trust is low, Quên checks it against the live source before the agent asserts it. Confirmed → confidence rises and an FSRS "good" review is logged. Refuted → the memory is tombstoned on the spot and a "fail" review is recorded. Unverifiable → the answer explicitly hedges. Contradictions are resolved deterministically first (a same-subject, same-relation, new-object slot rule for functional relations — zero LLM calls, fully auditable), with a Qwen natural-language-inference fallback where augmentation never supersedes the deterministic answer.
And it is measured, not vibes. On the team's staleness probe, Quên scored FAMA 0.933 versus 0.400 for append-only RAG — meaning near-zero reliance on invalidated facts. On the LongMemEval-S haystack it scored 0.423 versus 0.253. The headline metric, FAMA, is defined as the presence of valid facts and the absence of invalidated ones. Honesty, quantified.
Every single LLM and embedding call runs on Qwen through Alibaba Cloud Model Studio (DashScope, international endpoint) via one client module — no other provider anywhere in the stack. qwen3.7-plus powers the reader, the NLI contradiction detection, and the benchmark judging; qwen3.6-flash handles fact extraction, salience rating, and scoring; and text-embedding-v4 drives semantic retrieval and deduplication.
The full evaluation — the FAMA staleness probe, the LongMemEval oracle and full-haystack runs, calibration, and budget curves, amounting to tens of millions of tokens — ran live on DashScope with per-model token and cost accounting. DashScope's implicit context cache quietly cut the cost of repeat prefixes across those enormous runs. The live demo, a FastAPI + React dashboard where you can literally watch memories decay in real time, is deployed on an Alibaba Cloud ECS instance. The client was even hardened against real DashScope edge cases — transient-error retries and content-filter handling — during those long benchmark sessions.
Quên is the work of a solo builder, Pham Thanh Hang, who set out to prove a contrarian point: an agent's memory should be as disciplined about forgetting as it is about remembering. The result is a system that doesn't just store your facts — it keeps them honest.
This project was developed as part of the Global AI Hackathon Series with Qwen Cloud.
From Idea to Incorporated: How Corpus Formation Autopilot Turns Plain Language Into a Company

136 posts | 29 followers
FollowTran Phuc Hau - April 23, 2023
Regional Content Hub - December 15, 2025
Nguyen Phuc Khang - July 13, 2024
Alibaba Cloud Vietnam - January 1, 2024
Regional Content Hub - August 5, 2024
Regional Content Hub - June 4, 2026
136 posts | 29 followers
Follow QwenWork
 is dedicated to helping employees strengthen their professional competitiveness in the AI era and to enabling enterprises to improve organizational effectiveness.
Learn More Token Plan
Build more, spend less. One plan, every modality.
Learn More Qwen
Full-range, open-source, multimodal, and multi-functional
Learn More
Alibaba Cloud Model Studio
A one-stop generative AI platform to build intelligent applications that understand your business, based on Qwen model series such as Qwen-Max and other popular models
Learn MoreMore Posts by Alibaba Cloud Project Hub

