All Products
Search
Document Center

Dataphin:Data source table

Last Updated:Nov 03, 2026

This topic describes how to view the details of a metadata asset.

Limitations

  • To view metadata asset details, enable the metadata collection and management feature.

  • To use the data preview feature for a data source table, you must first configure a data source encoding. For more information about how to configure data source encoding, see Data source management.

  • For information about the differences in supported operations, such as data preview and viewing DDL statements, across different data sources, see Supported operations for different types of collection sources.

Accessing data source table details

  1. In the top navigation bar of the Dataphin homepage, choose Governance > Asset List.

  2. Select Assets of Other Systems, and then click the name of the target metadata asset or the image icon in the Actions column to go to the object details page.

Data source table
image

Section

Description

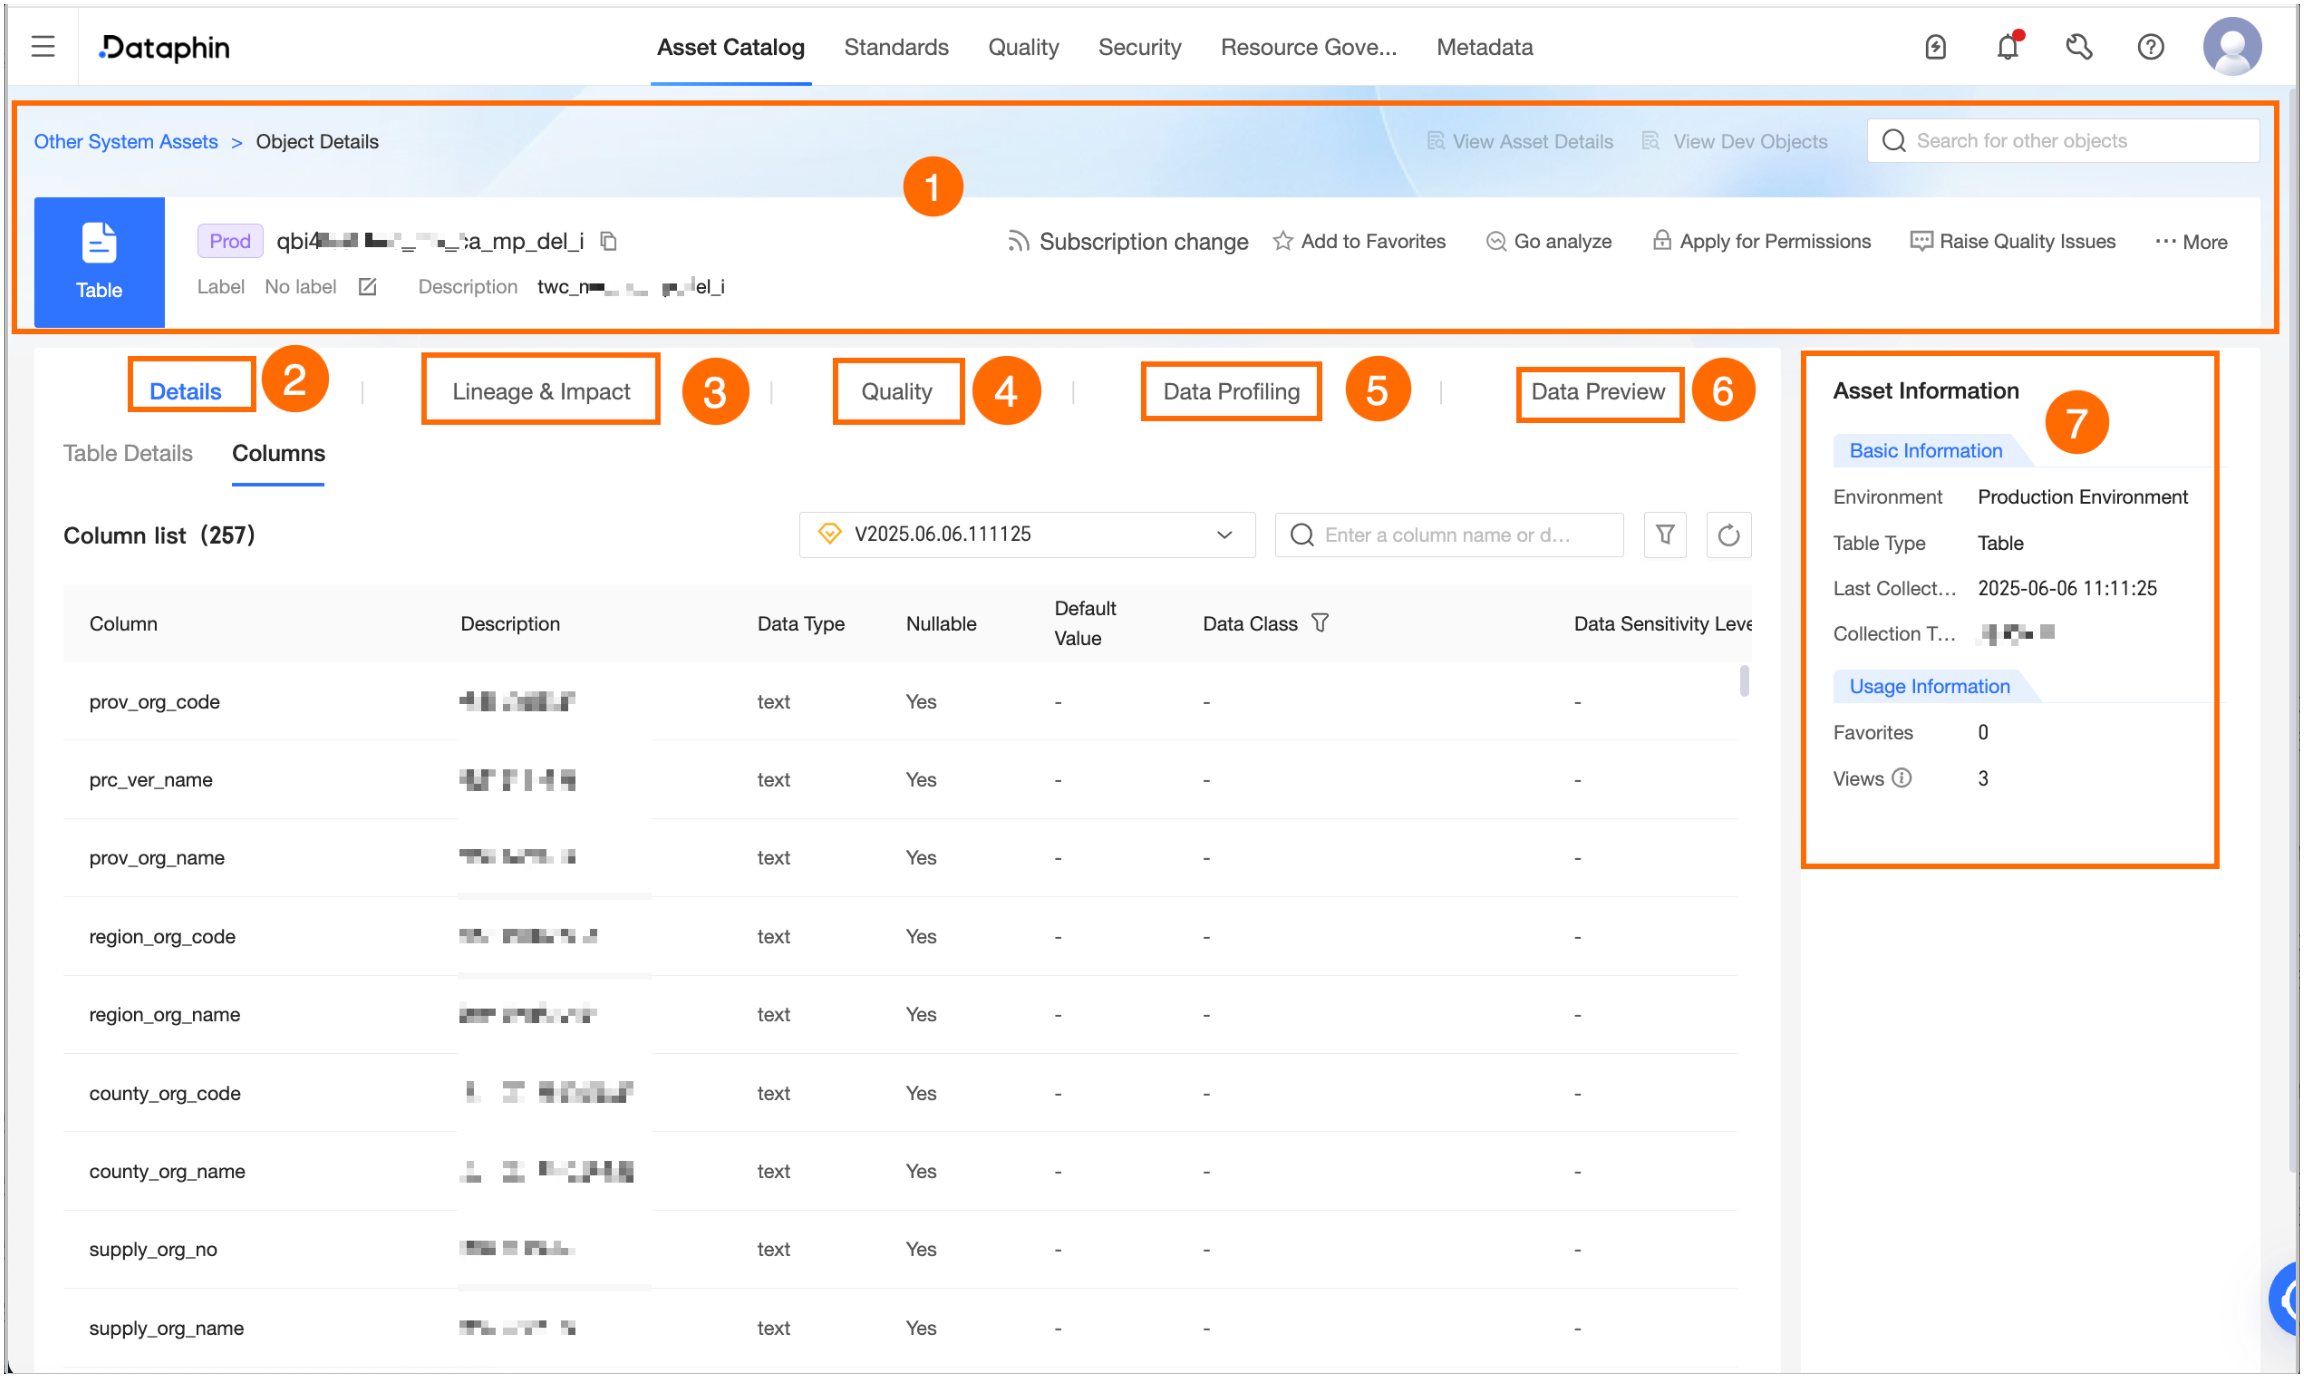
① Basic information

This section displays basic information about the metadata asset, such as its name, environment, tags, and description. You can also perform the following actions:

For a data source table from an Elasticsearch data source, you can search metadata, view asset details, view the production or development object, modify tags, add the asset to your favorites, report a data quality issue, apply for data source permissions, and export fields (only for table objects).

  • If the metadata has been deleted from the source system, its name is grayed out. Click the image icon next to the name to go to the Metadata List page and delete any unused metadata.

  • Search metadata: In the search box in the upper-right corner, enter a keyword, such as a table name, to search for a data source table. You can also switch to view the details of other assets.

  • View Asset Details: If the current object is published to Data Catalog, you can go to the catalog details page to view the published information.

  • View production/development object: Click View production/development object in the upper-right corner to quickly switch to the details page of the corresponding object in the production or development environment.

  • Tags: Displays the tag values configured for the current asset. To modify the tags, click Edit.

    • Each tag value can be up to 128 characters in length.

    • Each asset object can have up to 20 tag values.

  • Subscribe to changes: To use this operation, you must purchase the asset operations, metadata collection, and metadata management features. Select the data table to which you want to subscribe. In the New Subscription dialog box, configure the subscription content, notification method, and frequency. You can subscribe only to tables for which you have view permissions. Otherwise, the subscription fails. For more information, see New Subscription.

  • Unsubscribe: Unsubscribe from a data table to stop receiving status change notifications for it.

  • Favorite: Click to add or remove an asset from your favorites. After you favorite an asset, you can view the 30 most recently favorited assets on the Asset List-My Footprints tab for quick access. You can also view all your favorited assets in the Personal Data Center. For more information, see View and manage my favorite assets.

  • Analyze: Click to go to the Notebook page, where a corresponding Notebook task is automatically created. You can perform visual analysis on the asset. For more information, see Create a Notebook.

    Note

    For some data source tables, you can create a Notebook task after you apply for consumption permissions. For a list of supported data sources, see Supported operations for different types of assets.

  • Apply for permissions: Click to go to the permission application page for the current data table. For more information, see Apply for, renew, and release table permissions.

  • Report quality issue: This action is not supported if the metadata has been deleted. Use this feature to report data quality issues that you encounter, such as unstable data output or inaccurate data content, to the person in charge of data quality. This helps them make timely corrections and helps improve asset usability and health. For more information about how to configure this, see Add and manage issue lists.

    To use this feature, you must enable the data quality module. Only data source tables in the production environment support reporting quality issues. You can then view the handling process and results for the reported issues in the issue list of the data quality module.

  • Generate SELECT statement: Click to generate a query statement for the current table. You can choose whether to add escape characters. You can copy the query statement and run it on the ad hoc query or analysis page to query data.

  • View DDL statement: In the upper-right corner, click More and select View DDL statement to view the DDL statement for the current metadata asset in its data source. You can also select a Data Source Type and click Generate DDL statement. The system generates a DDL statement to create a table with the same structure as the current metadata asset in the specified type of data source. If you select Automatically Add Escape Characters, the system adds the appropriate escape characters to the generated DDL statement based on the selected source type. This helps prevent issues such as keyword misinterpretation.

  • Apply for data source permissions: In the upper-right corner, click More and select Apply for data source permissions to go to the permission application page for the current data source. For more information, see Apply for, renew, and release data source permissions.

  • Export fields: In the upper-right corner, click More and select Export fields to export the field information of the metadata asset in CSV format. This allows developers or business analysts to quickly analyze and use the information.

② Details

This section displays the attributes and field information for tables and views.

  • Table details: Displays the business and technical attributes of the metadata asset.

    • Business attributes: Includes source system information.

    • Technical attributes: Includes the source data source, number of rows, highest data sensitivity level (requires the data security feature), whether the table is a lake table, lake table format, table storage mode, storage type (internal table or external table), storage usage, and Location information.

      • Table storage mode: If a data table is a lake table with the Hudi format, this information can be collected from the table's source data source. This information cannot be collected from StarRocks, SelectDB, and Doris data sources.

      • Location: The storage path of the current table, for example, hdfs://node01.exp5:8020/user/hive/warehouse.

        Note
        • For views, only the source data source information is available in the technical attributes.

        • Storage type information is not available for MySQL and Microsoft SQL Server data sources.

        • For Oracle tables, storage usage is estimated based on the number of rows and the average space used per row in bytes. This estimate does not include statistics for indexes, unused space, or fragmentation. Therefore, the statistical value is lower than the actual space occupied.

        • For partitioned tables, the row count is for reference only, as Dataphin does not currently collect the row count for the main table.

        • Location information is available for Hive and Greenplum data sources when the storage type is external table.

        • For Amazon Redshift data sources, only the source data source and storage type information are available.

        • If the data source is Elasticsearch and the object is a table (that is, an index), only the document count and storage usage technical attributes are available.

  • Field information: Displays field information for the table or view, including field name, data type, description, nullability, default value, and data category/data classification (requires the data security module). If the data source is Elasticsearch and the object is a table (that is, an index), only the field name and data type information are displayed.

    Search and filter: You can search for fields by name or description. You can also filter fields by data category or data classification (requires the data security feature).

  • Partition information: Displays the partition information of the data table. Multi-level partitions are displayed as a combination of all partition levels, separated by forward slashes (/). For example: ds=20221001/pt1=a/pt2=b.

    Note
    • Partition record count and storage usage information are for reference only.

    • Partition information is not available for Elasticsearch data sources.

③ Lineage and impact

  • Lineage: Displays the lineage relationships between tables and fields.

    • Table-level lineage: The lineage source includes integration and synchronization tasks, compute tasks with custom lineage, and SQL compute and logical table tasks for which the system can automatically parse lineage. For more information, see Table-level lineage.

    • Field-level lineage: The lineage source includes compute tasks with custom lineage, and SQL compute and logical table tasks for which the system can automatically parse lineage. For more information, see Field-level lineage.

      Note

      The system parses lineage when a task is submitted (for the development environment) or published (for the production environment). A single task submission or publication can parse up to 100,000 lineage relationships. If this limit is exceeded, the lineage is not recorded and will not be displayed in the Data Catalog.

  • Impact: Divided into data table impact and integration and synchronization impact.

    • Data table impact: Displays direct downstream tables (which reference the current table) and indirect downstream tables (which reference the direct ones). You can export data and choose to show direct downstream tables only.

      • Export data: Exports data to an Excel file for business users to browse.

      • Show direct downstream tables only: When selected, Dataphin shows only the downstream tables directly impacted by the current table. When cleared, it shows all downstream impacted tables up to 15 levels deep (level 1 is the direct downstream).

    • Integration and synchronization impact: Displays integration and synchronization tasks that use the current table and its downstream tables as source tables. You can export data and choose to show the impact of the current table only.

      • Export data: Exports data to an Excel file for business users to browse.

      • Show impact of current table only: When selected, Dataphin shows only integration tasks that use the current table as an input table. When cleared, it shows integration tasks that use the current table and all downstream impacted tables as input tables, up to 15 levels (the direct downstream of the current table is level 1).

④ Quality overview

To view the rule check overview and the list of quality monitoring rules for the current data table, you must activate the data quality feature. You can click View Report Details or View Rule Details to go to the corresponding page in the data quality module for more details. The quality overview is available only for data tables that support data quality monitoring. For a list of supported data sources, see Data sources supported by Dataphin.

Only data source tables in the production environment support creating quality rules and viewing the quality overview.

⑤ Data profiling

If you have activated the data quality feature, you can initiate and view data profiling for supported data source tables. This allows you to quickly get an overview of the data and assess its usability and potential risks in advance. To enable automatic profiling, go to Governance > Metadata Center > Profiling and Analysis to configure the settings. For more information about how to configure a profiling task, see Create a data profiling task. For lists of supported data sources, see Supported data sources and partitions for data profiling.

⑥ Data preview

To use the data preview feature, you must have data query permissions for the current table. The preview shows results only for the fields for which you have SELECT permissions and is limited to the first 50 rows. To apply for query permissions, see Apply for, renew, and release table permissions.

You can search or filter the data by field, view the details of a single row, auto-fit column widths, expand or collapse field names, and switch between row and column views. You can also click the sort icon next to a field to sort the data in ascending or descending order, or select Unsorted. Double-click a field value to copy it.

Note

For Hive internal tables with the Iceberg format (Hive version EMR 5.x 3.1.x) or Hudi format (Hive version CDP 7.x Hive 3.1.3), to query data, you must enable the Spark configuration for the table's data source.

Asset information

This section displays the basic and usage information of the data source table.

  • Basic information: Includes the environment, table type, last collection time, and collection task for the data source table.

    • Last collection time: The end time of the last successful run of the collection task for the data source table, in YYYY-MM-DD hh:mm:ss format.

    • Collection task: Information about the collection task for the data source table.

  • Usage information: Includes the number of favorites and page views (PV) for the data source table.

    • Favorites: The number of users who have favorited the data source table. This value is updated in real time.

    • Page views (PV): The number of page views (PV) for the data source table. The count increases by one each time the page is refreshed. This value is updated in real time.

Table-level lineage

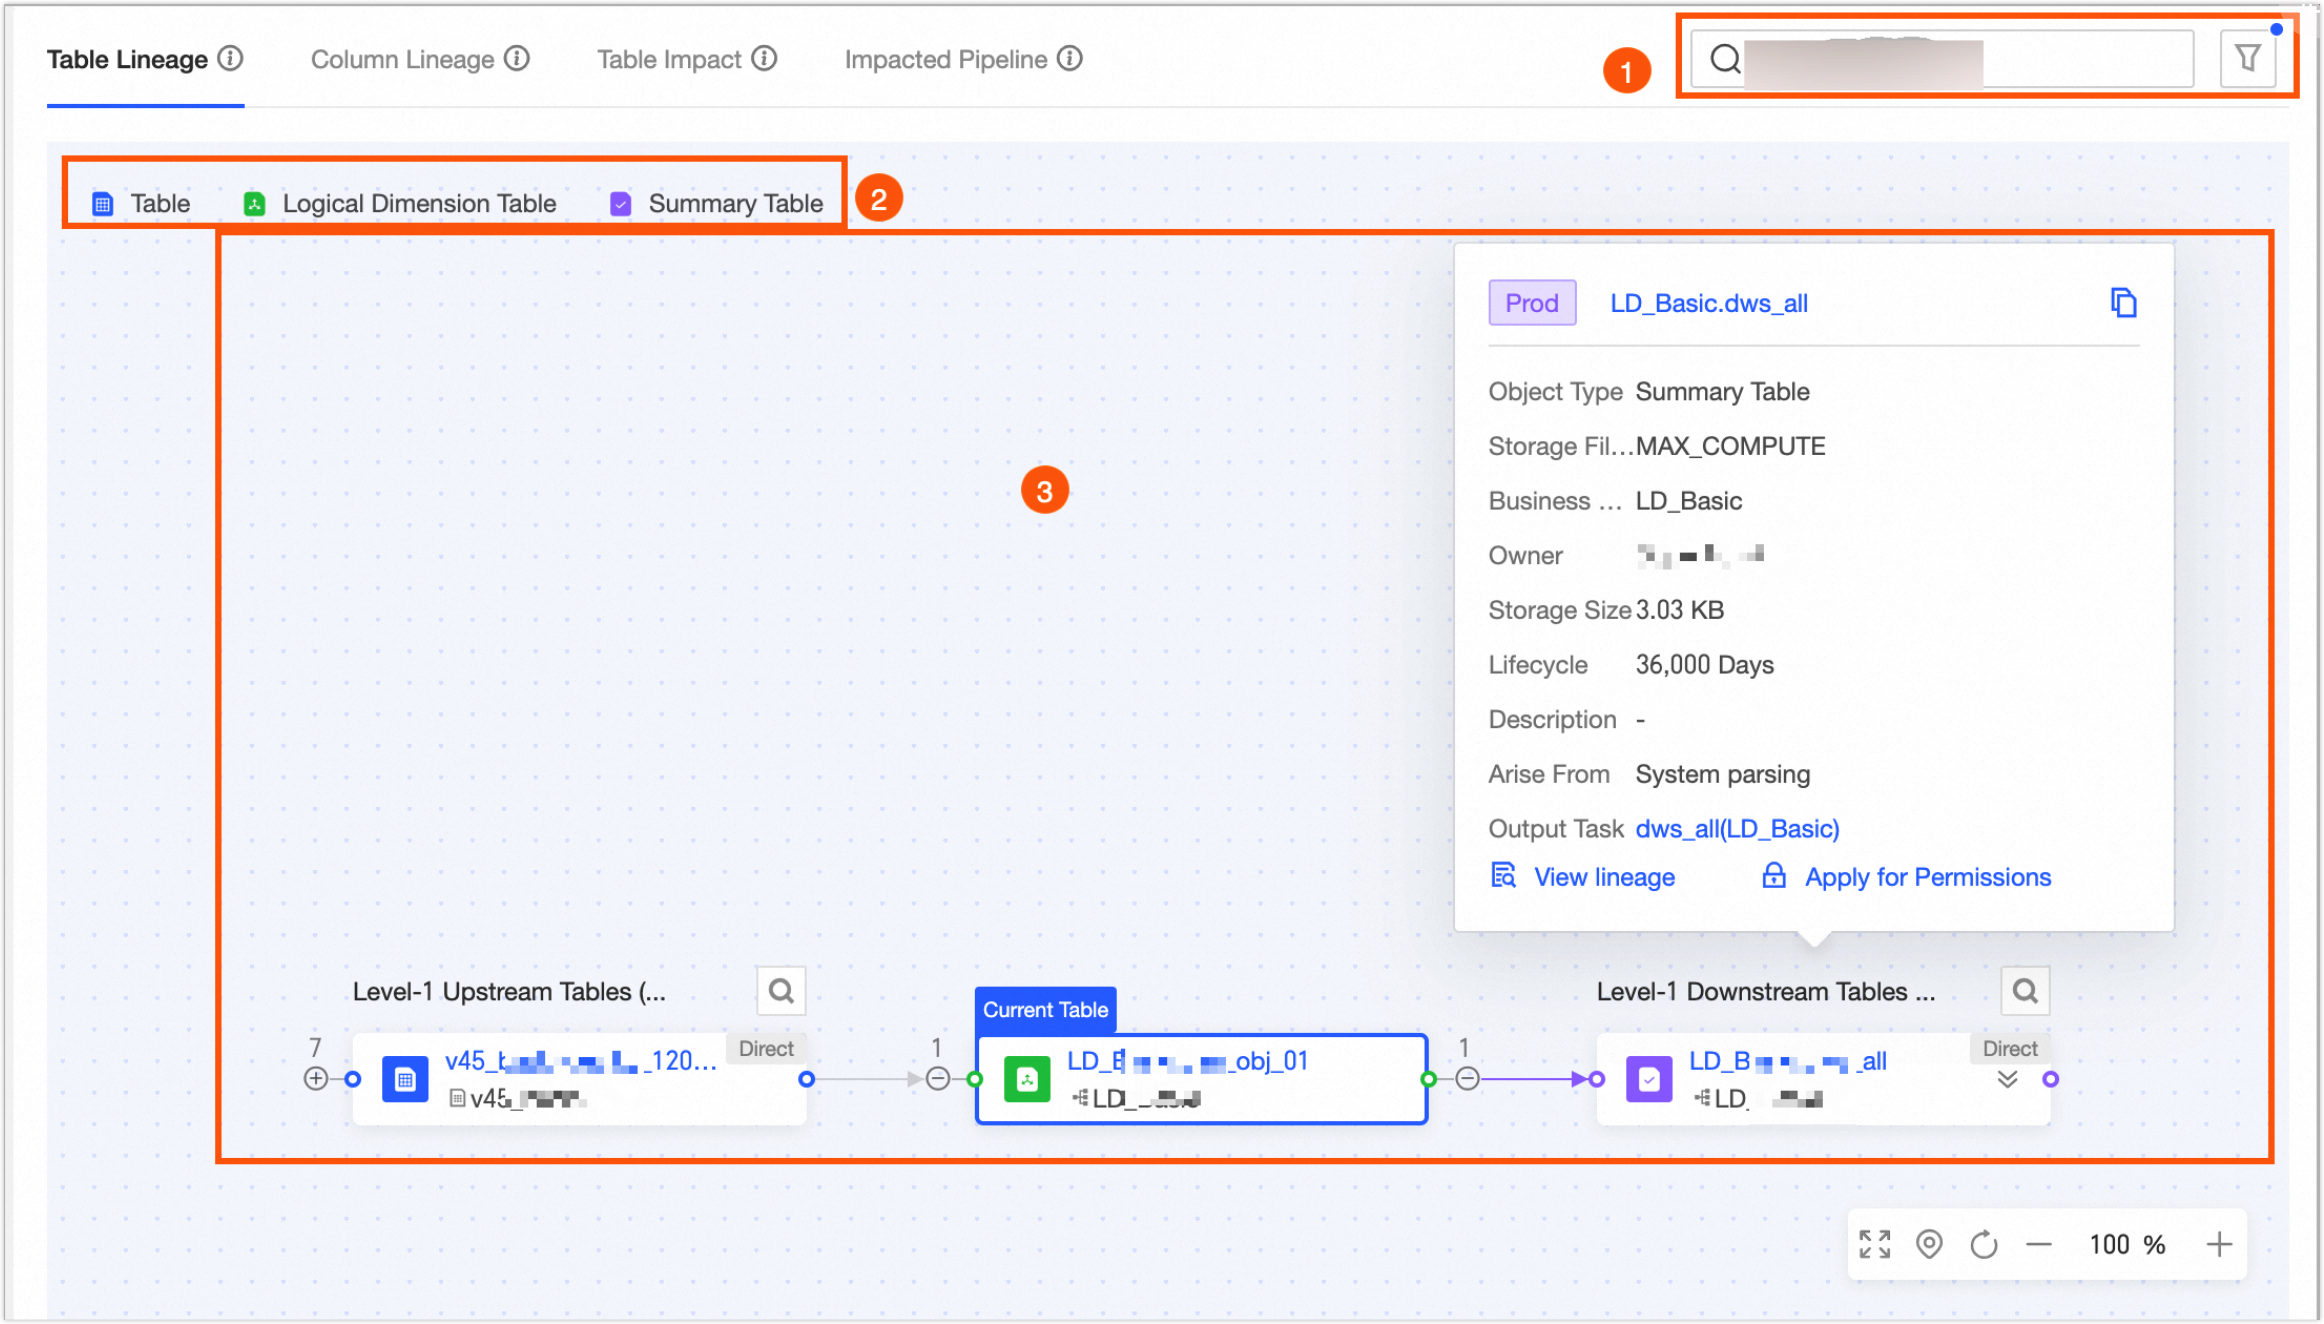
The table-level lineage page displays a lineage graph that includes integration and synchronization tasks, compute tasks with custom lineage, and SQL compute and logical table tasks for which the system can automatically parse lineage.
image

No.

Description

① Quick actions

  • Search: Search for expanded nodes on the current page by table name keyword. You can click the left or right arrows next to the search box to switch between matched nodes. The system automatically locates the first matched node.

  • Show direct lineage only: Click Filter > Show direct lineage only to display only the upstream and downstream tables that have a direct lineage relationship with the current table.

    Note
    • Direct lineage refers to upstream and downstream assets that are read from or written to by using statements such as SELECT and INSERT.

    • Associated lineage refers to related assets that are referenced by using methods such as JOIN, GROUP BY, or WHERE conditions.

    • In table-level lineage, a direct lineage indicator is shown if any field has direct lineage.

  • Hide data source tables: Click Filter > Hide data source tables to hide tables from data sources and their downstream dependencies.

  • Hide uncollected nodes: Lineage is not updated if a table is deleted outside of a Dataphin scheduled task (for example, if it is deleted by using an ad hoc query or directly in the engine). Such tables may appear in the lineage graph as uncollected nodes. Select this option to hide tables that have been deleted or have not yet been collected.

② Legend

Table-level lineage supports the following table types: physical table, dimension logical table, fact logical table, aggregate logical table, tag logical table, physical view, materialized view, logical view, metatable, mirror table, and data source table.

③ Lineage graph display area

Displays the complete lineage graph. You can manually expand multiple levels of upstream or downstream nodes. You can also perform a fuzzy search by data table name. If a circular dependency exists, you cannot expand the node further and must view its downstream from the starting node.

  • Center node: Displays the name of the current asset and is marked with the Current Table identifier in the upper-left corner.

  • Fields in the table: Hover over a node and click the drop-down arrow on the right. You can perform a fuzzy search for a field by name. Click a field name to go to the current asset's details page and view its lineage.

④ Object details area

Hover over a table to view its details.

For a data source table, the details include its Name, Object Type, Data Source Type, Data Source, and Lineage Source. You can also perform the View lineage, View DDL statement, and Apply for permissions actions.

  • If the metadata has been deleted from the source system, you can click the image icon next to the name to go to the Metadata List page and delete the unused metadata.

  • View lineage: Click to quickly view the table-level lineage of the table.

  • View DDL statement: For a physical table, physical view, or mirror table, click to view the table's DDL statement.

  • Apply for permissions: This action is not supported if the metadata has been deleted. For metadata with a normal status, you can click to go to the table permission application page.

Field-level lineage

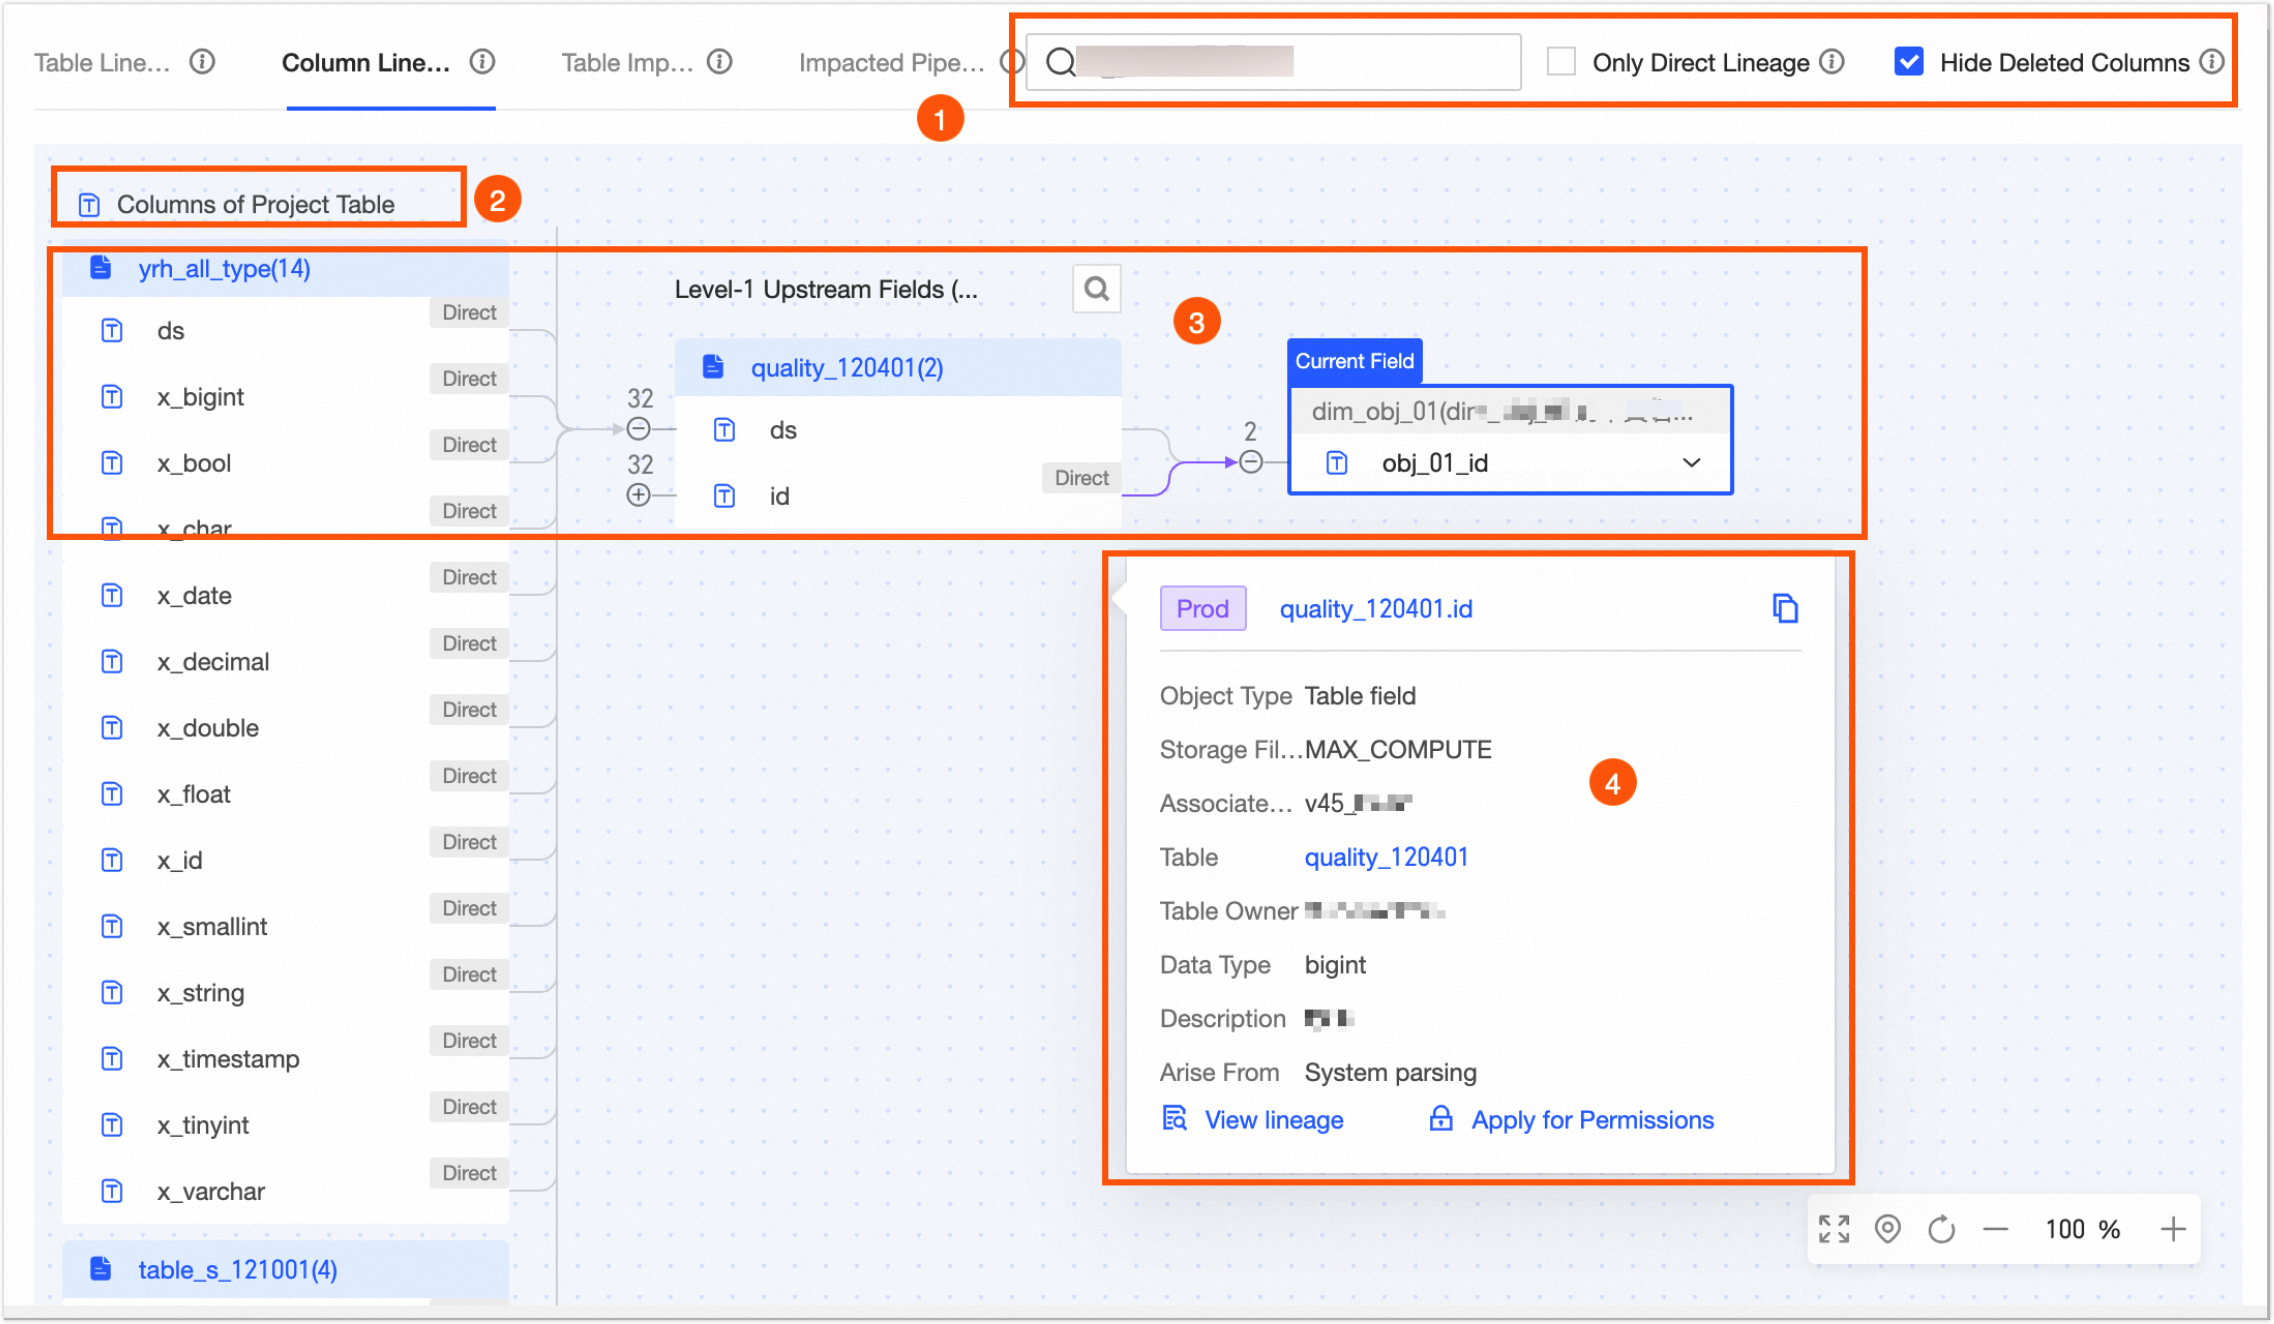
The field-level lineage page displays a lineage graph for compute tasks with custom lineage, and SQL compute and logical table tasks for which the system can automatically parse lineage.
image

No.

Description

① Quick actions

  • Search: Search for expanded nodes on the current page by field name keyword. You can click the left or right arrows next to the search box to switch between matched nodes. The system automatically locates the first matched node.

  • Show direct lineage only: When selected, this option displays only the upstream and downstream fields that have a direct lineage relationship with the current field.

    Note
    • Direct lineage also includes computation logic that processes a field using a WHERE condition (in a filter component) or a built-in function (in a field computation component).

    • Associated lineage refers to related assets that are referenced by using methods such as JOIN, GROUP BY, or WHERE conditions.

  • Hide uncollected nodes: Lineage is not updated if a table is deleted outside of a Dataphin scheduled task (for example, if it is deleted by using an ad hoc query or directly in the engine). Such tables may appear in the lineage graph as uncollected nodes. Select this option to hide tables that have been deleted or have not yet been collected.

② Legend

Supported fields for field-level lineage include source computing table field and data source table field.

③ Lineage graph display area

Displays the complete lineage graph. You can manually expand multiple levels of upstream or downstream nodes. You can also perform a fuzzy search by field name. If a circular dependency exists, you cannot expand the node further and must view its downstream from the starting node.

Center node: Displays the name of the current field and its table, and is marked with the Current Field identifier in the upper-left corner. You can perform a fuzzy search by field keyword to switch to the lineage graph of a different field.

④ Object details area

Hover over a field to view its Name, Object Type, Data Source Type, Table, Table Owner, Data Type, Description, and Lineage Source. You can also perform the View lineage action.

  • Table: If a collection task is configured for the table, clicking the table name opens its data source details page.

  • Apply for permissions: For metadata with a normal status, you can click to go to the table permission application page.

  • View lineage: Click to quickly view the lineage information with this field as the center field.

Note

If a metadata collection task has not been configured for a data source table, you cannot click to view its asset details. You can only view some basic information, including the field's name, object type, table, data source type, and lineage source.