AnalyticDB for MySQL is a real-time, high-concurrency Online Analytical Processing (OLAP) service developed by Alibaba Cloud. It performs multidimensional analysis and exploration of petabytes of data with millisecond-level latency. You can use Data Transmission Service (DTS) to synchronize data from a PolarDB for MySQL cluster to an AnalyticDB for MySQL cluster. This helps you quickly build internal business intelligence (BI) systems, interactive query platforms, and real-time reporting applications.
Prerequisites
-
A destination AnalyticDB for MySQL cluster has been created. For more information, see Create a cluster.
-
Make sure that the destination AnalyticDB for MySQL cluster has sufficient storage space.
Binary logging is enabled for the source PolarDB for MySQL cluster. For more information, see Enable binary logging.
Limitations
During full data initialization, DTS consumes read and write resources of the source and destination databases, which may increase the database load. When the databases have low performance, low specifications, or heavy workloads (for example, a large number of slow SQL statements, tables without primary keys, or deadlocks on the destination database), the database pressure may be further increased and services may become unavailable. Therefore, you must evaluate the performance of the source and destination databases before starting data synchronization, and it is recommended that you perform data synchronization during off-peak hours (for example, when the CPU load of both the source and destination databases is below 30%).
-
Do not use tools such as gh-ost or pt-online-schema-change to perform online DDL operations on the objects to be synchronized in the source database during data synchronization. Otherwise, the synchronization task fails.
-
Due to the AnalyticDB for MySQLusage limitation, if the disk usage of any node in the cluster exceeds 80%, the cluster is locked. Before you start, estimate the storage space required for the objects to be synchronized and make sure that the destination cluster has sufficient capacity.
-
Prefix indexes cannot be synchronized. If the source database contains prefix indexes, data synchronization may fail.
-
If the destination AnalyticDB for MySQL 3.0 cluster is backing up while the DTS task runs, the task fails.
Billing
|
Synchronization type |
Pricing |
|
Schema synchronization and full data synchronization |
Free of charge. |
|
Incremental data synchronization |
Charged. For more information, see Billing overview. |
Supported SQL operations
-
DDL operations: CREATE TABLE, DROP TABLE, RENAME TABLE, TRUNCATE TABLE, ADD COLUMN, DROP COLUMN, and MODIFY COLUMN
-
DML operations: INSERT, UPDATE, and DELETE
If a field's data type in the source table changes during data synchronization, the task reports an error and stops. You can manually fix this issue. For more information, see Fix a synchronization failure caused by a data type change.
Database account permissions
Database | Required permissions |
PolarDB for MySQL | Read permissions on the objects to be synchronized. |
AnalyticDB for MySQL | Read and write permissions. |
For more information about how to create and authorize a database account, see Create a PolarDB for MySQL database account or Create a database account for Cloud-native Data Warehouse AnalyticDB for MySQL.
Data type mappings
For more information, see Data type mappings for initial schema synchronization.
Procedure
Purchase a data synchronization task.
NoteWhen purchasing the task, set Source Instance to Apsara PolarDB, Target Instance to AnalyticDB MySQL, and Synchronization Topology to One-way synchronization.
- Log on to the Data Transmission Service console.
Note
If you are automatically redirected to the Data Management (DMS) console, you can click the
 icon in the lower-right corner and then click
 to return to the classic DTS console.
- In the navigation pane on the left, click Data Synchronization.
- In the top navigation bar of the Data Synchronization page, select the region where the destination instance is located.
- Find the purchased data synchronization instance and click Configure Synchronization Channel.
Configure the source and destination instances for the synchronization channel.
Section
Parameter
Description
N/A
Synchronization task name
DTS automatically generates a task name. For easy identification, we recommend using a descriptive name. The name does not need to be unique.
Source instance details
Instance type
Set to PolarDB Instance. This parameter cannot be changed.
Instance region
The region of the source instance that you selected when you purchased the task. This parameter cannot be changed.
PolarDB instance ID
Select the ID of the source PolarDB for MySQL cluster.
Database account
Enter the database account for the PolarDB for MySQL cluster. For information about the required permissions, see Database account permissions.
Database password
Enter the password for the database account.
Destination instance details
Instance type
Set to ADS. This parameter cannot be changed.
Instance region
The region of the destination instance that you selected when you purchased the task. This parameter cannot be changed.
Version
Select 3.0.
Database
Select the cluster ID of the destination AnalyticDB for MySQL instance.
Database account
Enter the database account for the AnalyticDB for MySQL instance. For information about the required permissions, see Database account permissions.
Database password
Enter the password for the database account.
-
In the lower-right corner of the page, click Set Whitelist and Next.
If the source or destination database is an Alibaba Cloud database instance, such as an ApsaraDB RDS for MySQL or ApsaraDB for MongoDB instance, DTS automatically adds the CIDR blocks of DTS servers to the IP address whitelist of the instance. If the source or destination database is a self-managed database hosted on an Elastic Compute Service (ECS) instance, DTS automatically adds the CIDR blocks of DTS servers to the security group rules of the ECS instance, and you must make sure that the ECS instance can access the database. If the self-managed database is hosted on multiple ECS instances, you must manually add the CIDR blocks of DTS servers to the security group rules of each ECS instance. If the source or destination database is a self-managed database that is deployed in a data center or provided by a third-party cloud service provider, you must manually add the CIDR blocks of DTS servers to the IP address whitelist of the database to allow DTS to access the database. For more information, see Whitelist DTS server IP addresses.
WarningAdding the public IP address blocks of the DTS service, either automatically or manually, may pose security risks. Using this product, you acknowledge that you understand and accept the potential security risks and that you must implement basic security measures. These measures include, but are not limited to, strengthening password security, limiting the ports open to each CIDR block, using authentication for internal API calls, and regularly checking and restricting unnecessary CIDR blocks. Alternatively, you can connect through a private network using a leased line, VPN Gateway, or Smart Access Gateway.
Configure the synchronization policy and objects.
Parameter
Description
Synchronization initialization
By default, both Initial schema synchronization and Initial full data synchronization are selected. After the precheck is complete, DTS initializes the schema and data of the synchronized objects in the destination cluster. This process creates a baseline for subsequent incremental data synchronization.
Action on existing tables in destination
Precheck and report error: Checks if a table with the same name exists in the destination database. If no such table exists, the check passes. If a table with the same name exists, an error is reported during the precheck phase, and the data synchronization task will not start.
NoteIf you cannot delete or rename the conflicting table in the destination database, you can map the table to a new name in the destination. For more information, see Set object names in the destination instance.
Ignore Errors and Proceed: Skips the check for tables with the same name in the destination database.
WarningSelecting Ignore Errors and Proceed can lead to data inconsistencies and business risks. For example:
If a record in the destination cluster has the same primary key as a source record, the destination record is kept, and the source record is not synchronized.
If the table schemas are different, the data might not initialize, only some columns might be synchronized, or the task might fail.
Merge multiple tables
Select Yes: DTS adds the
__dts_data_sourcecolumn to each table to store the data source and no longer supports DDL synchronization.No: The default option. DDL synchronization is supported.
NoteThe table merge feature is applied at the task level, not the table level. If you need to merge some tables but not others, create two separate data synchronization tasks.
Synchronization operation types
Select the operation types to synchronize. For more information about supported operations, see Supported SQL operations. By default, all operation types are selected.
Select synchronization objects
In the Available objects box, click the objects you want to synchronize, and then click the
 icon to move them to the Selected objects box.
You can select databases and tables as synchronization objects.
NoteIf you select an entire database, all schema change operations for objects within that database are synchronized to the destination.
If you select a specific table, only
ADD COLUMNoperations on that table are synchronized to the destination.By default, the names of the synchronization objects remain the same. If you need to change the object names in the destination cluster, use the object name mapping feature. For more information, see Set object names in the destination instance.
Rename object mappings
Change the names of synchronized objects in the destination instance. For more information, see Map databases, tables, and columns.
Replicate temporary tables during online DDL process in DMS
If you use Data Management (DMS) to perform online DDL changes on the source database, you can choose whether to synchronize the temporary tables generated by the DDL changes.
-
Yes: Synchronizes the temporary tables generated by online DDL changes.
NoteIf a large amount of temporary table data is generated by online DDL changes, the data synchronization task may be delayed.
-
No: Does not synchronize the temporary tables generated by online DDL changes. Only the original DDL operations from the source database are synchronized.
NoteThis option causes tables in the destination database to be locked.
Connection retry timeout
If DTS cannot connect to the source or destination instance, it retries for 720 minutes (12 hours) by default. You can also specify a custom retry duration. If DTS reconnects to the source or destination instance within the specified duration, the synchronization task automatically resumes. Otherwise, the task fails.
NoteYou are billed for task run time during connection retries. Customize the retry duration based on your business needs, or release the DTS instance as soon as the source and destination instances are released.
- After you complete the preceding configurations, click Next in the lower-right corner of the page.
-
Set the types of the tables to be synchronized in the destination database.
The configuration table also includes the ADB Table Group, ADB Table Name, Number of Partitions, and Definition Status columns. When you hover over a database or table name, DTS shows the source table name.
NoteIf you select Initial Schema Synchronization, you must define the tables to be synchronized in AnalyticDB for MySQL, including the Type, primary key column, and partition column. For more information, see CREATE TABLE.
After you complete the preceding configurations, click Precheck and Start in the lower-right corner of the page.
NoteBefore the synchronization task is officially started, a precheck is performed. The synchronization task can only be started after the precheck passes.
If the precheck fails, click the
 icon next to a specific check item to view the failure details.
Follow the prompt to fix the issue and run the precheck again.
If you do not need to fix the warning check items, you can also select Ignore, Ignore Warning Items and Rerun Precheck to skip the warning check items and run the precheck again.
- After Precheck Passed is displayed in the Precheck dialog box, close the dialog box. The synchronization task starts automatically.
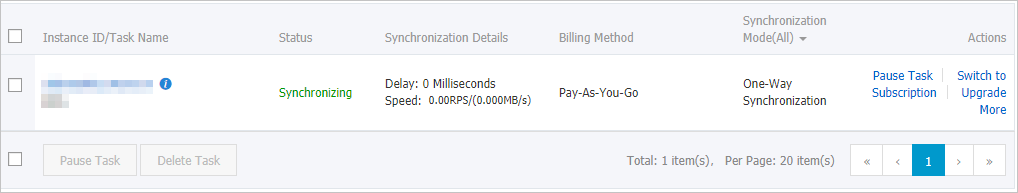
- Wait until the synchronization channel is initialized and the task enters the Synchronizing state.
The Data Synchronization page displays the status of data synchronization jobs.