Create a Kubernetes-based EMR cluster to run big data engines such as Spark, Flink, and Presto on ACK.
Prerequisites
-
The AliyunOSSFullAccess and AliyunDLFFullAccess policies have been granted. For more information, see Grant permissions to access OSS and DLF.
-
A Kubernetes cluster has been created. For more information, see Create an ACK dedicated cluster (discontinued) or Create an ACK managed cluster.
-
A node pool has been created. For more information, see Create and manage a node pool.
-
Object Storage Service (OSS) has been activated. For more information, see Activate OSS.
Procedure
-
Log in to the EMR on ACK console.
-
On the EMR on ACK page, click Create Cluster.
-
On the EMR on ACK page, configure the cluster parameters.
Parameter
Description
Region
The region in which to deploy the cluster. Cannot be changed after creation.
Cluster Type
The following cluster types are supported:
-
Shuffle Service: an EMR extension component that provides a remote shuffle service. It enables Spark jobs to run on nodes without local disks and supports dynamic resource allocation, making it ideal for Spark clusters in an ACK environment. For more information, see Celeborn.
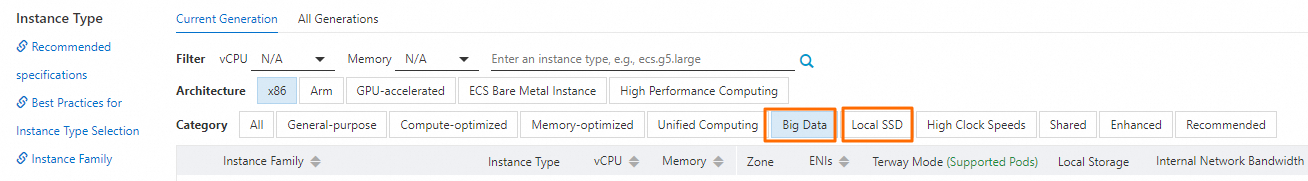
ImportantWhen you create a Shuffle Service cluster, the instance specification of the dedicated node pool or nodes in the associated ACK cluster must be big data or local SSD. Otherwise, the RSS deployment fails.
 Note
This job optimizes storage management and prevents waste by removing invalid or redundant PVCs.
-
Presto: an in-memory distributed SQL engine for interactive queries.
Supports multiple data sources and is suitable for petabyte-scale analysis and cross-data-source queries.
-
Spark: a general-purpose, distributed big data processing engine for ETL, offline batch processing, and data modeling.
ImportantTo associate a Spark cluster with a Shuffle Service cluster, their major product versions must match. For example, a Spark cluster of version EMR-5.x-ack can be associated only with a Shuffle Service cluster of version EMR-5.x-ack.
-
Flink: a distributed processing engine for stateful computations over bounded and unbounded data streams. Built on EMR on ACK and the community Flink Kubernetes Operator 1.0.1, Flink on ACK uses the enterprise kernel from the official Flink team by default for an out-of-the-box Flink on Kubernetes experience.
Product Version
Defaults to the latest software version.
Component Version
Lists the components and versions included in the selected cluster type.
ACK cluster
Select an existing ACK cluster, or create a new one in the Container Service for Kubernetes (ACK) console.
Click Configure Dedicated Nodes to configure EMR-dedicated nodes. This applies EMR-specific taints and labels to a node pool or individual nodes, reserving them exclusively for EMR.
NoteWe recommend configuring dedicated nodes using a node pool. If no node pool is available, create one. For more information, see Create a node pool.
OSS bucket
Select an existing bucket, or create a new one in the Object Storage Service (OSS) console.
Cluster Name
Must be 1 to 64 characters long and can contain only Chinese characters, letters, digits, hyphens (-), and underscores (_).
-
-
Click create.
The cluster is ready when its status changes to Running.