Deploy a Qwen3-32B inference service on Container Service for Kubernetes (ACK) using the SGLang engine with Prefill/Decode separation. This deployment uses RoleBasedGroup (RBG) to orchestrate a 2P1D architecture (2 prefill servers, 1 decode server) across 6 GPUs.
When to use this architecture
Prefill/Decode separation assigns the two core stages of LLM inference to dedicated GPUs. Evaluate whether your workload benefits from this approach before committing to the additional infrastructure.
Choose Prefill/Decode separation when:
Your workload has long input prompts and requires consistent, low inter-token latency.
You need to tune time-to-first-token (TTFT) and time per output token (TPOT) independently.
Tail latency spikes during decoding are unacceptable.
Choose standard (aggregated) inference when:
Your input prompts are short and output sequences are long.
Latency consistency is less critical than maximizing raw throughput.
You have fewer than 6 GPUs with 32 GB memory each.
Prefill/Decode separation reduces the average time per output token (TPOT) and increases system throughput by allowing each GPU pool to specialize. The architecture requires RDMA for KV cache transfer between prefill and decode servers. Without RDMA, transfer latency degrades significantly, making the separation ineffective.
How it works
LLM inference has two stages with different compute profiles:
Prefill stage: Processes the entire user prompt in one pass. The model calculates attention for all input tokens in parallel and generates the initial KV cache. This stage is compute-intensive and runs once per request.
Decode stage: Generates tokens one at a time based on the KV cache. Each step loads large model weights and the KV cache from GPU memory, making this stage memory-bound.
When both stages run on the same GPU, they compete for resources. Compute-heavy prefill tasks increase latency for decode tasks in the same batch, leading to higher TPOT and reduced efficiency.
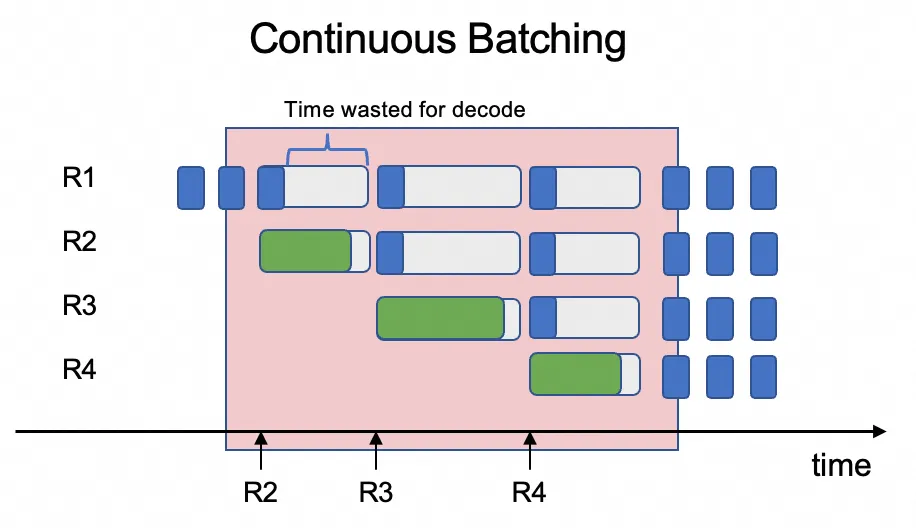
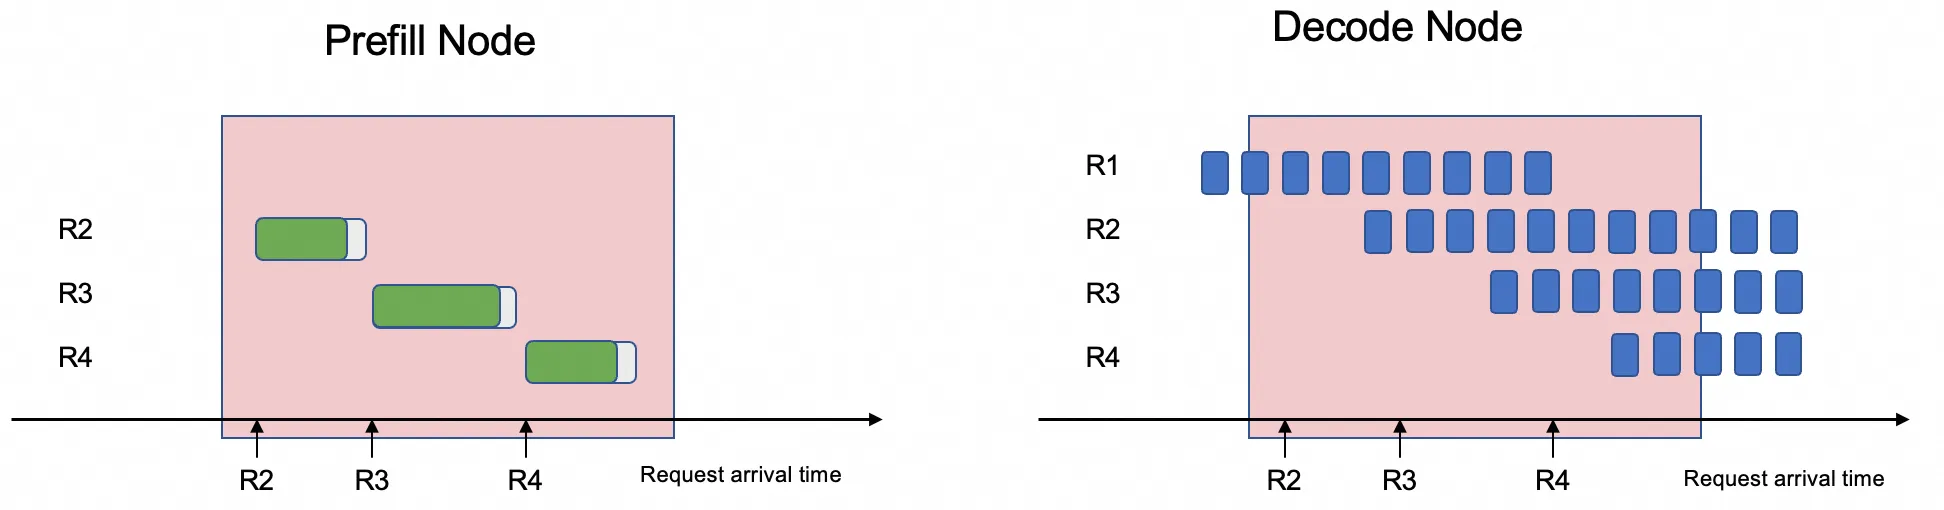
Prefill/Decode separation solves this by running each stage on dedicated GPUs:
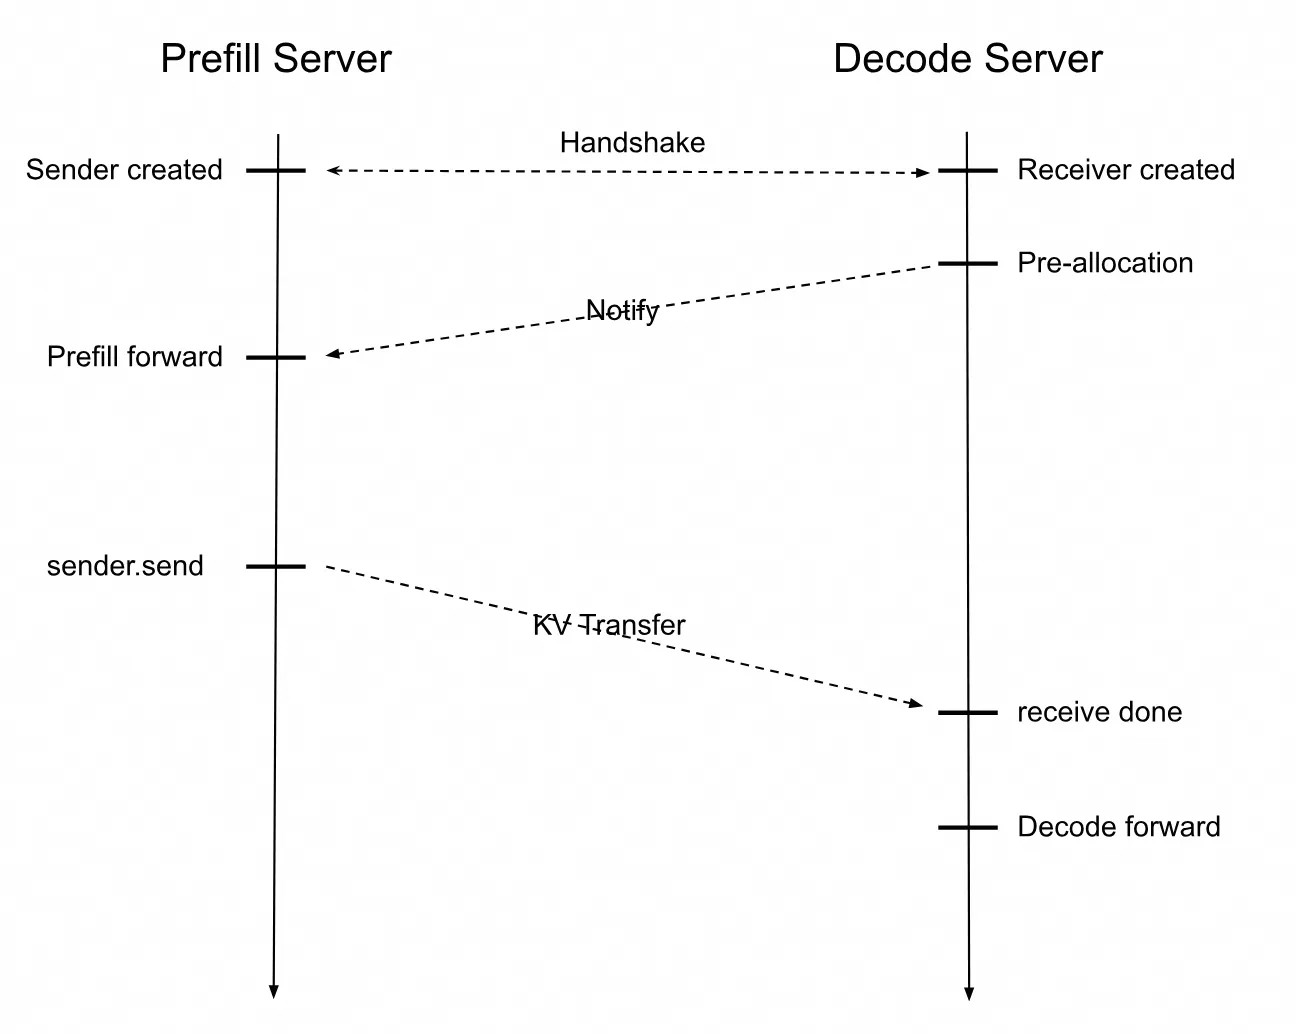
The following sequence shows how the prefill and decode servers interact for each request:
A user request arrives at the scheduler, which routes it to a prefill server.
The prefill server processes the full prompt, generates the KV cache, and creates a Sender object.
The decode server creates a Receiver object and allocates GPU memory for the incoming KV cache.
The prefill and decode servers complete a handshake. The prefill server transfers the KV cache to the decode server over RDMA.
The decode server generates tokens autoregressively until the response is complete.
This separation lets each GPU pool optimize for its stage's compute profile, reducing TPOT and increasing system throughput.
Key components
The deployment relies on the following components:
Component | Description |
Qwen3-32B | A 32.8B-parameter dense model with a 32,000-token context window (extendable to 131,000 tokens with YaRN). Supports over 100 languages. Strengths include logical reasoning, math, code generation, instruction following, multi-turn dialog, creative writing, and tool use for AI agent tasks. For more information, see the Qwen3 blog, GitHub, and documentation. |
SGLang | An inference engine with RadixAttention-based caching, continuous batching, speculative decoding, Prefill/Decode separation, and multi-LoRA batching. Supports tensor, pipeline, data, and expert parallelism, and FP8, INT4, AWQ, and GPTQ quantization. Frontend features include chained generation, control flow, parallel processing, native multimodal support, and external tool interaction. Supports generative (Qwen, DeepSeek, Llama), embedding (E5-Mistral), and reward (Skywork) models. For more information, see the SGLang GitHub. |
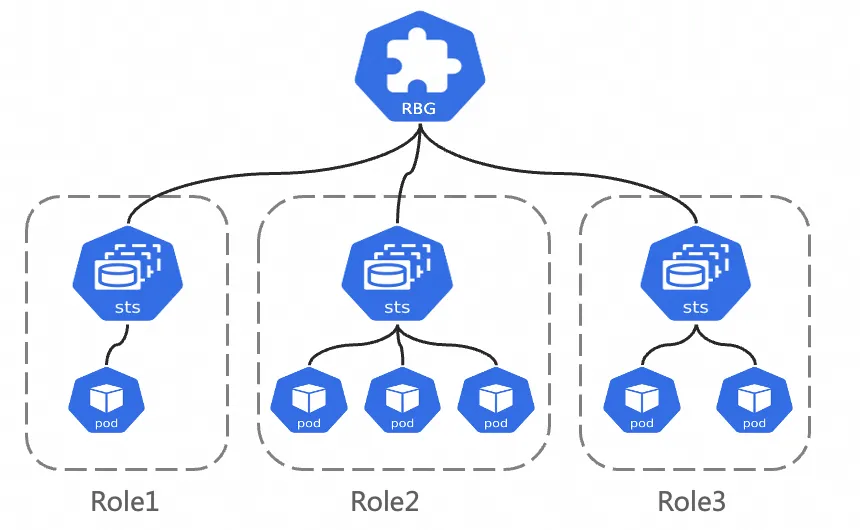
RoleBasedGroup (RBG) | An open-source Kubernetes workload from the ACK team for deploying multi-role architectures. Defines a group of roles (each based on a StatefulSet, Deployment, or LeaderWorkerSet), with dependency management, automatic service discovery, rolling updates, and gang scheduling. For more information, see the RBG GitHub. |
Prerequisites
Before you begin, ensure that you have:
An ACK managed cluster (version 1.22 or later) with GPU nodes. For more information, see Create an ACK managed cluster and Add GPU nodes to a cluster
At least 6 GPUs with at least 32 GB of memory each. The framework relies on GPUDirect RDMA for KV cache transfer between prefill and decode servers
Node specifications that support elastic RDMA (eRDMA). Use the
ecs.ebmgn8is.32xlargeECS Bare Metal Instance type. For more information, see ECS Bare Metal Instance typesAlibaba Cloud Linux 3 64-bit OS image (pre-installed with the eRDMA software stack). For more information, see Add eRDMA nodes in ACK
The ACK eRDMA Controller component installed and configured. For more information, see Use eRDMA to accelerate container networks
The ack-rbgs component installed (see Install ack-rbgs below)
Install ack-rbgs
Log on to the Container Service Management Console. In the left-side navigation pane, click Clusters.
Click the name of your target cluster to open the cluster details page.
Install the ack-rbgs component using Helm. Leave the Application Name and Namespace fields empty.
Click Next. In the Confirm to use default settings? dialog box, click Yes to accept the default application name (
ack-rbgs) and namespace (rbgs-system).Select the latest Chart version and click OK.
Step 1: Prepare the Qwen3-32B model files
Download the model
Install Git LFS if not already installed: For other methods, see Installing Git Large File Storage.
   # For RHEL/CentOS
   yum install git-lfs

   # For Debian/Ubuntu
   apt-get install git-lfs
Clone and download the model from ModelScope:
   git lfs install
   GIT_LFS_SKIP_SMUDGE=1 git clone https://www.modelscope.cn/Qwen/Qwen3-32B.git
   cd Qwen3-32B/
   git lfs pull
Upload the model to OSS
Log on to the OSS console and record your bucket name. To create a bucket, see Create buckets.
Upload the model files to Object Storage Service (OSS): For more information about ossutil, see Install ossutil.
   ossutil mkdir oss://<your-bucket-name>/Qwen3-32B
   ossutil cp -r ./Qwen3-32B oss://<your-bucket-name>/Qwen3-32B
Create a persistent volume (PV) and persistent volume claim (PVC)
Create a PV named llm-model and a PVC to mount the model files into your cluster. For detailed instructions, see Create a PV and a PVC.
Option A: Use the console
Create a PV:
Log on to the ACK console. In the left-side navigation pane, click Clusters.
On the Clusters page, click the name of your cluster. In the left-side pane, choose Volumes > Persistent Volumes.
In the upper-right corner, click Create.
In the Create PV dialog box, configure the following parameters:
Parameter
Value
PV Type
OSS
Volume Name
llm-model
Access Certificate
Your AccessKey ID and AccessKey secret for OSS access
Bucket ID
The OSS bucket you created
OSS Path
/Qwen3-32B
Create a PVC:
In the left-side pane, choose Volumes > Persistent Volume Claims.
In the upper-right corner, click Create.
In the Create PVC dialog box, configure the following parameters:
Parameter
Value
PVC Type
OSS
Name
llm-model
Allocation Mode
Existing Volumes
Existing Volumes
Click Select PV and select the PV you created
Option B: Use kubectl
Create a file named
llm-model.yamlwith the following content: Replace the placeholders with your values:Placeholder
Description
Example
<your-oss-ak>AccessKey ID for OSS access
LTAI5tXxx
<your-oss-sk>AccessKey secret for OSS access
xXxXxXx
<your-bucket-name>OSS bucket name
my-model-bucket
<your-bucket-endpoint>OSS endpoint (use internal endpoint)
oss-cn-hangzhou-internal.aliyuncs.com
<your-model-path>Path to the model directory in OSS
/Qwen3-32B/
   apiVersion: v1
   kind: Secret
   metadata:
     name: oss-secret
   stringData:
     akId: <your-oss-ak>       # AccessKey ID for the OSS bucket
     akSecret: <your-oss-sk>   # AccessKey secret for the OSS bucket
   ---
   apiVersion: v1
   kind: PersistentVolume
   metadata:
     name: llm-model
     labels:
       alicloud-pvname: llm-model
   spec:
     capacity:
       storage: 30Gi
     accessModes:
       - ReadOnlyMany
     persistentVolumeReclaimPolicy: Retain
     csi:
       driver: ossplugin.csi.alibabacloud.com
       volumeHandle: llm-model
       nodePublishSecretRef:
         name: oss-secret
         namespace: default
       volumeAttributes:
         bucket: <your-bucket-name>       # OSS bucket name
         url: <your-bucket-endpoint>      # e.g., oss-cn-hangzhou-internal.aliyuncs.com
         otherOpts: "-o umask=022 -o max_stat_cache_size=0 -o allow_other"
         path: <your-model-path>          # e.g., /Qwen3-32B/
   ---
   apiVersion: v1
   kind: PersistentVolumeClaim
   metadata:
     name: llm-model
   spec:
     accessModes:
       - ReadOnlyMany
     resources:
       requests:
         storage: 30Gi
     selector:
       matchLabels:
         alicloud-pvname: llm-model
Apply the configuration:
kubectl create -f llm-model.yaml
Step 2: Deploy the inference service
This deployment uses RBG to create a 2P1D architecture: 2 prefill server replicas, 1 decode server replica, and 1 scheduler. Each server uses tensor parallelism across 2 GPUs, totaling 6 GPUs.
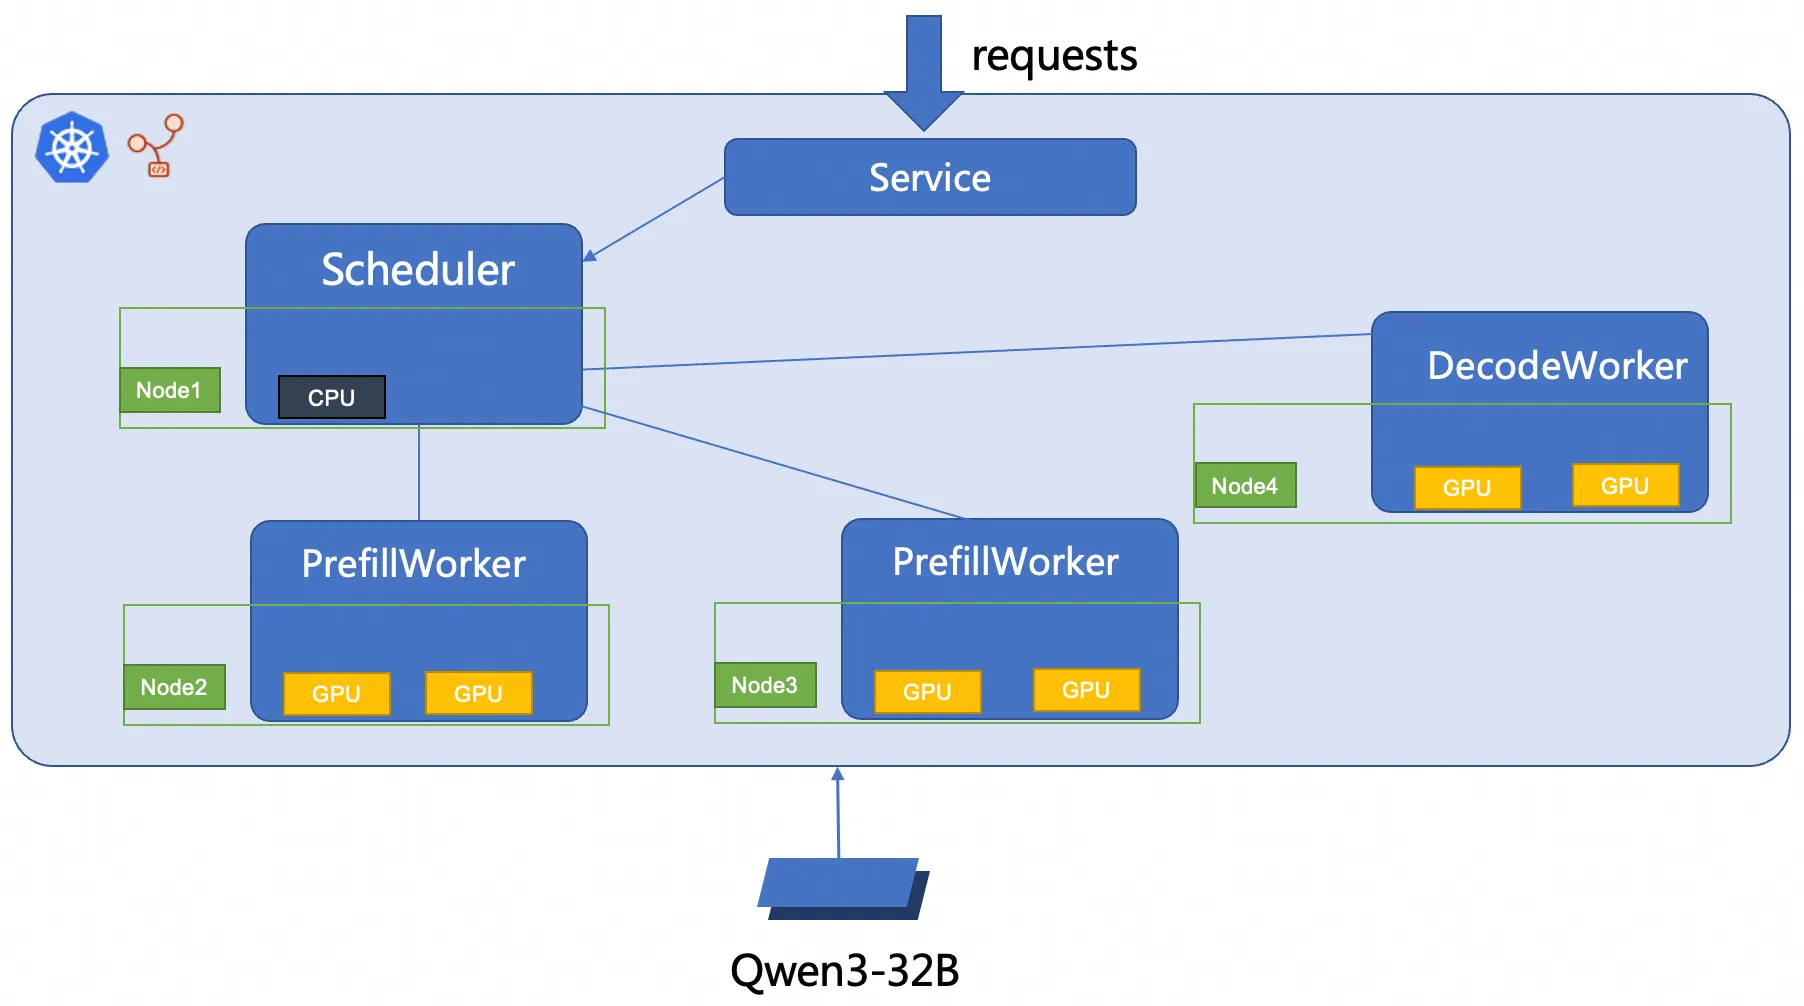
The following table explains the key parameters in the deployment:
Parameter | Value | Purpose |
| Tensor parallelism across 2 GPUs | Splits model across 2 GPUs per server |
| Prefill mode | Configures the server for prefill-only workloads |
| Decode mode | Configures the server for decode-only workloads |
| Bootstrap port for KV cache transfer | Used by the prefill server to establish RDMA connections |
| Enable Prometheus metrics | Exposes inference metrics for monitoring |
| eRDMA device request | Allocates one eRDMA device for high-speed KV cache transfer |
| Shared memory allocation | Required for inter-process communication within the inference engine |
Create a file named
sglang_pd.yaml:Deploy the service:
kubectl create -f sglang_pd.yamlWait for all Pods to reach the
Readystate:kubectl get pods -l rolebasedgroup.workloads.x-k8s.io/name=sglang-pd --watch
Step 3: Verify the inference service
Set up port forwarding
Forward the scheduler Service to your local machine for testing:
kubectl port-forward svc/sglang-pd 8000:8000Expected output:
Forwarding from 127.0.0.1:8000 -> 8000
Forwarding from [::1]:8000 -> 8000Port forwarding via kubectl port-forward is for development and debugging only. It lacks the reliability, security, and scalability required for production. For production networking, see Ingress management.
Send a test request
Send an inference request to the /v1/chat/completions endpoint:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "/models/Qwen3-32B",
    "messages": [{"role": "user", "content": "test"}],
    "max_tokens": 30,
    "temperature": 0.7,
    "top_p": 0.9,
    "seed": 10
  }'
Expected output:
{
  "id": "29f3fdac693540bfa7808fc1a8701758",
  "object": "chat.completion",
  "created": 1753695366,
  "model": "/models/Qwen3-32B",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "<think>\nOkay, the user wants me to do a test. I need to first confirm their specific needs. Maybe they want to test my functions, such as answering questions or generating content.",
        "reasoning_content": null,
        "tool_calls": null
      },
      "logprobs": null,
      "finish_reason": "length",
      "matched_stop": null
    }
  ],
  "usage": {
    "prompt_tokens": 10,
    "total_tokens": 40,
    "completion_tokens": 30,
    "prompt_tokens_details": null
  }
}
A successful response confirms that the prefill and decode servers are communicating correctly and generating output.
Measure inference performance
The deployment YAML includes the --enable-metrics flag, which exposes Prometheus-compatible metrics on each server. To validate that Prefill/Decode separation delivers the expected latency improvements, monitor these metrics:
Metric | Description | What to look for |
TTFT | Time to first token | Reflects prefill server performance |
TPOT | Time per output token | Should be lower and more consistent than aggregated deployment |
Throughput | Requests per second | Overall system throughput |
For full monitoring setup, see Configure Prometheus monitoring for LLM inference services in References.
References
Configure Prometheus monitoring for LLM inference services Integrate with Managed Service for Prometheus to collect inference metrics, detect failures and performance bottlenecks, troubleshoot issues with real-time data, and analyze long-term performance trends for resource optimization.
Accelerate model loading with Fluid distributed caching Large model files (>10 GB) stored in OSS or File Storage NAS can cause slow Pod startups due to long download times. Fluid creates a distributed caching layer across cluster nodes to accelerate model loading through parallel data throughput and reduced I/O latency from local caching.
Implement intelligent routing and traffic management by using Gateway with Inference Extension ACK Gateway with Inference Extension provides model-aware load balancing, intelligent model routing based on request payload, and request prioritization for production inference workloads.