Qwen3-TTS Family is Now Open Sourced: Voice Design, Clone, and Generation!
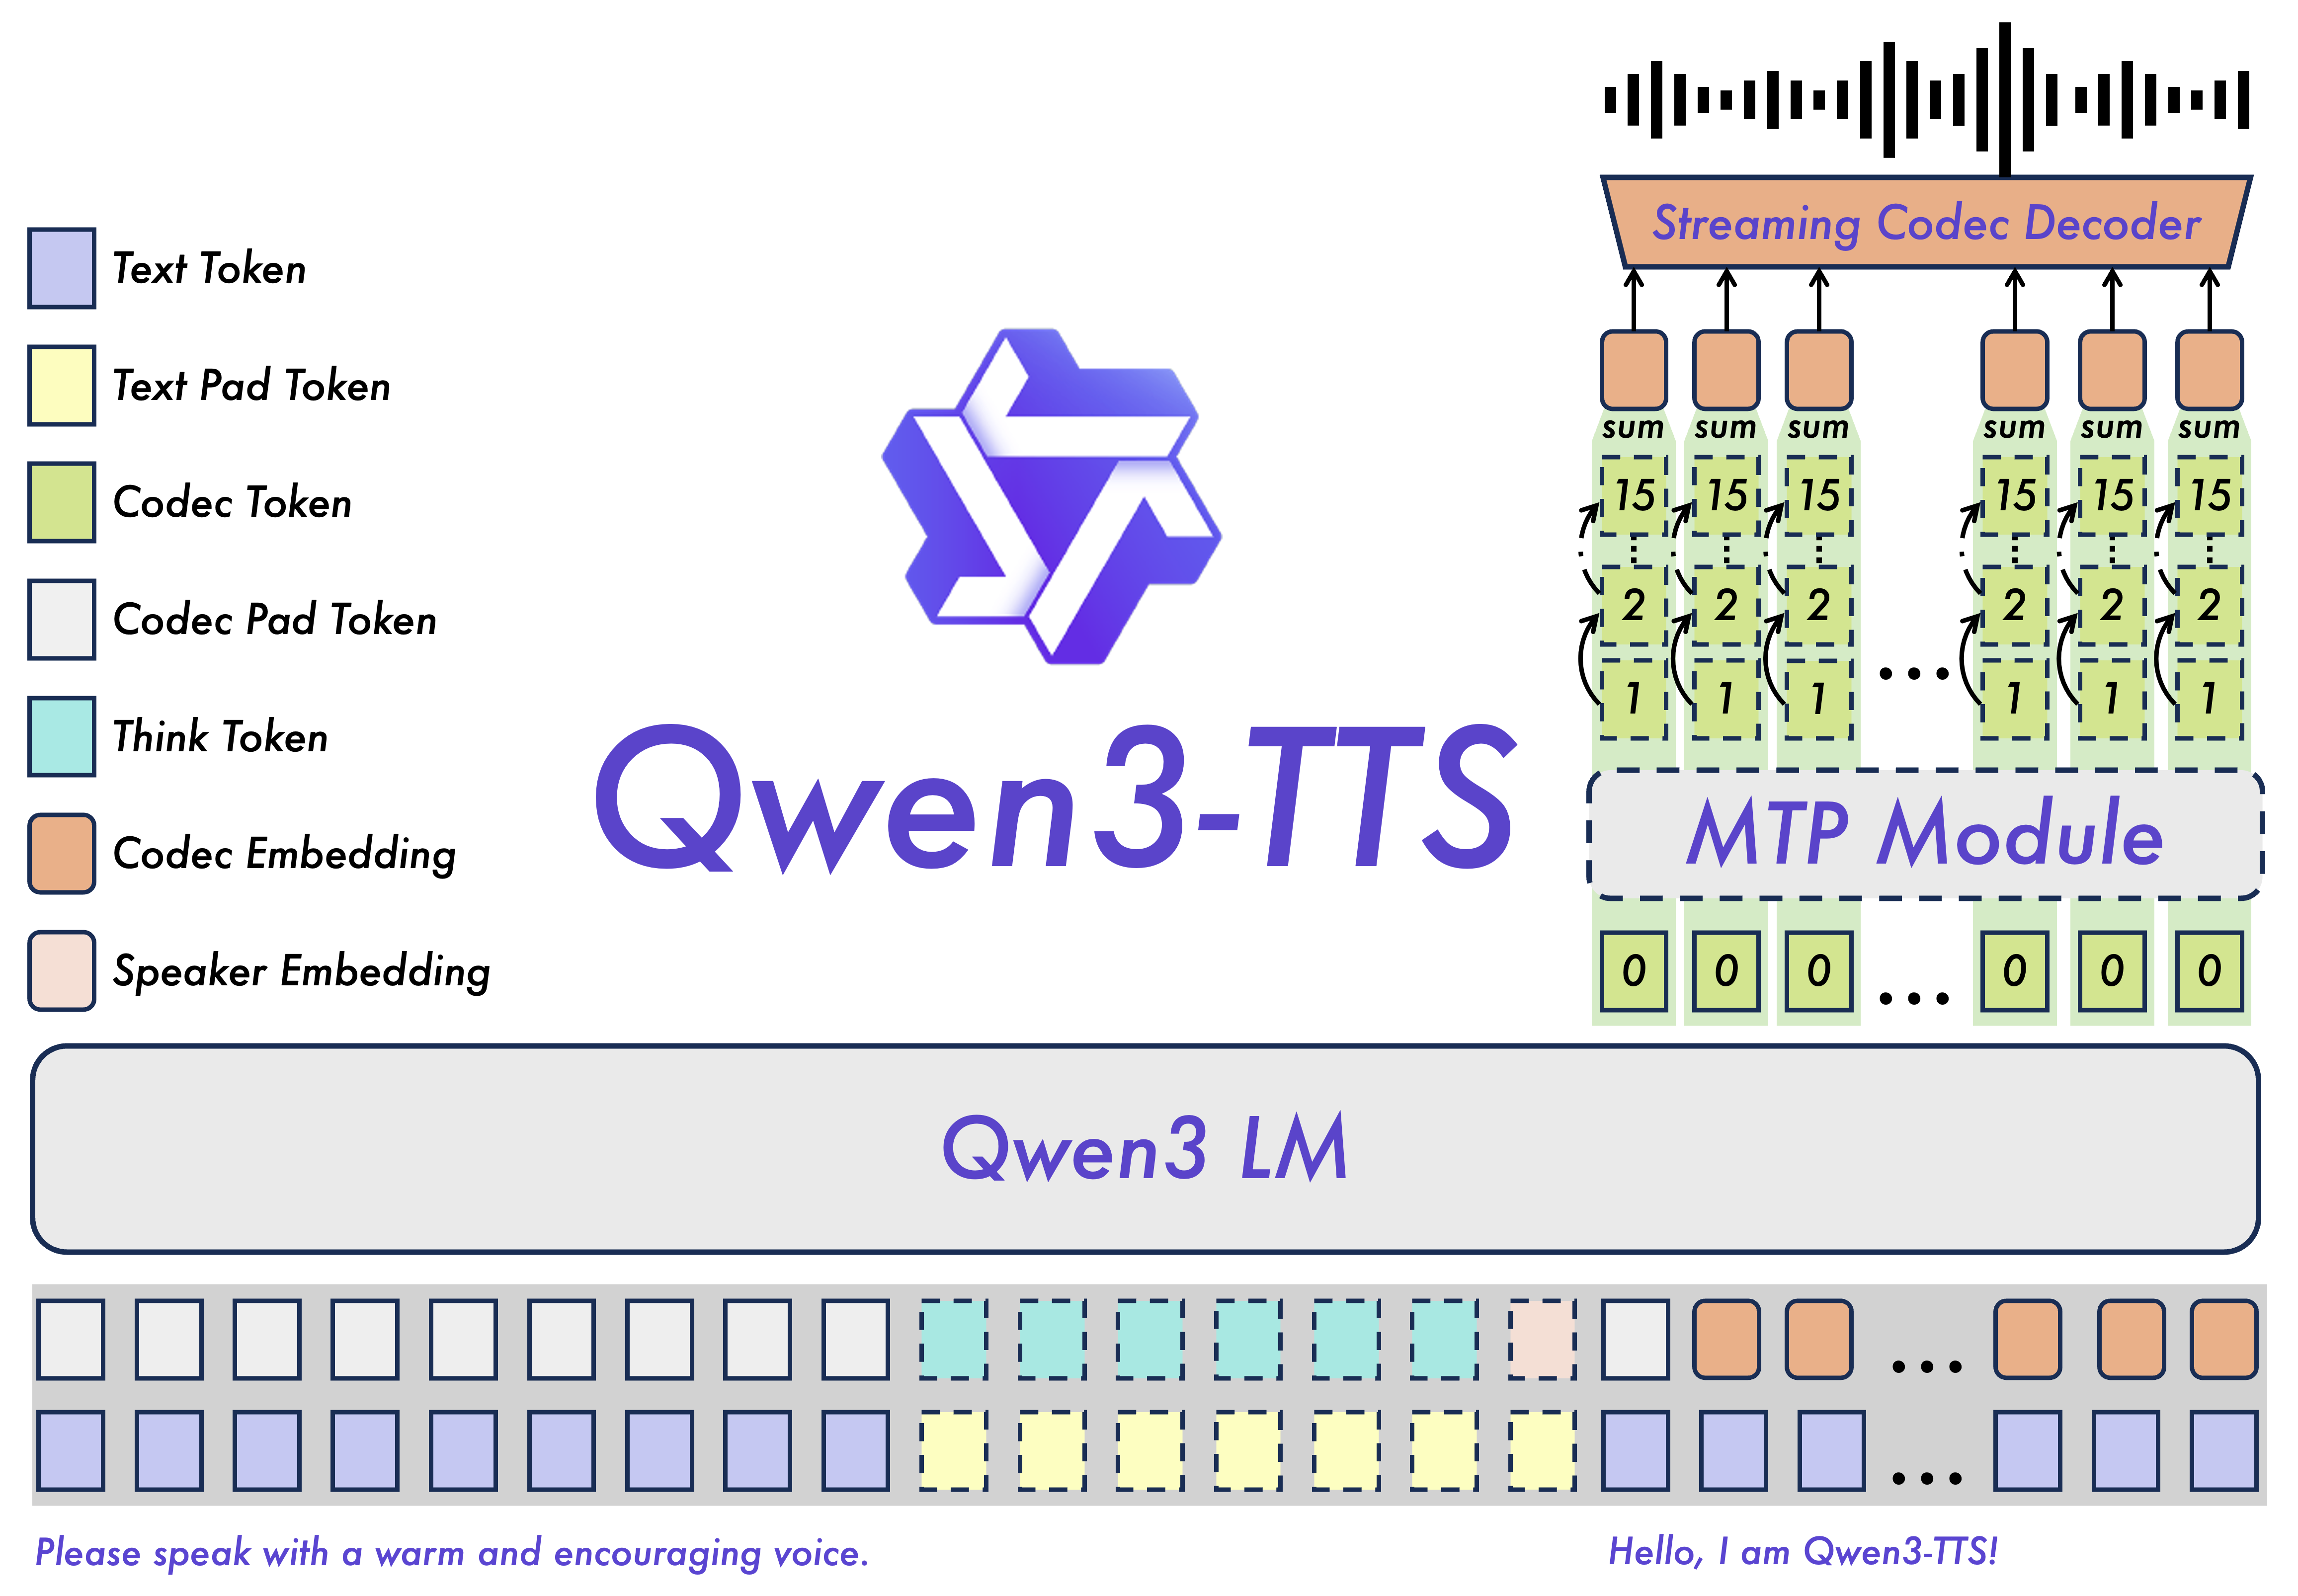
Qwen3-TTS is a series of powerful speech generation capabilities developed by Qwen, offering comprehensive support for voice clone, voice design, ultra-high-quality human-like speech generation, and natural language-based voice control. It provides developers and users with the most extensive set of speech generation features available. Powered by the innovative Qwen3-TTS-Tokenizer-12Hz multi-codebook speech encoder, Qwen3-TTS achieves efficient compression and robust representation of speech signals. This not only fully preserves paralinguistic information and acoustic environmental features but also enables high-speed, high-fidelity speech reconstruction via a lightweight non-DiT architecture. Utilizing Dual-Track modeling, Qwen3-TTS achieves extreme bidirectional streaming generation speeds, where the first audio packet is delivered after processing just a single character. The entire Qwen3-TTS multi-codebook model series is now open-sourced, featuring two sizes: 1.7B and 0.6B. The 1.7B model delivers peak performance and powerful control capabilities, while the 0.6B model offers an ideal balance between performance and efficiency. The models support 10 mainstream languages (Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian) along with various dialects to meet global application demands. Furthermore, the models exhibit strong contextual understanding, allowing them to adapt tone, rhythm, and emotional expression based on instructions and text semantics, while significantly improving robustness to input text noise. Now open-sourced on GitHub and accessible via the Qwen API.
Model List
1.7B Model
| Model | Features | Language Support | Streaming | Instruction Control |
|---|---|---|---|---|
| Qwen3-TTS-12Hz-1.7B-VoiceDesign | Performs voice design based on user-provided descriptions. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | ✅ |
| Qwen3-TTS-12Hz-1.7B-CustomVoice | Provides style control over target timbres via user instructions; supports 9 premium timbres covering various combinations of gender, age, language, and dialect. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | ✅ |
| Qwen3-TTS-12Hz-1.7B-Base | Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
0.6B Models
| Model | Features | Language Support | Streaming | Instruction Control |
|---|---|---|---|---|
| Qwen3-TTS-12Hz-0.6B-CustomVoice | Supports 9 premium timbres covering various combinations of gender, age, language, and dialect. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
| Qwen3-TTS-12Hz-0.6B-Base | Base model capable of 3-second rapid voice clone from user audio input; can be used for fine-tuning (FT) other models. | Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, Italian | ✅ | |
Qwen3-TTS Key Features
Main Features:
- Powerful Speech Representation: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, it achieves efficient acoustic compression and high-dimensional semantic modeling of speech signals. It fully preserves paralinguistic information and acoustic environmental features, enabling high-speed, high-fidelity speech reconstruction through a lightweight non-DiT architecture.
- Universal End-to-End Architecture: Utilizing a discrete multi-codebook LM architecture, it realizes full-information end-to-end speech modeling. This completely bypasses the information bottlenecks and cascading errors inherent in traditional LM+DiT schemes, significantly enhancing the model’s versatility, generation efficiency, and performance ceiling.
- Extreme Low-Latency Streaming Generation: Based on the innovative Dual-Track hybrid streaming generation architecture, a single model supports both streaming and non-streaming generation. It can output the first audio packet immediately after a single character is input, with end-to-end synthesis latency as low as 97ms, meeting the rigorous demands of real-time interactive scenarios.
- Intelligent Text Understanding and Voice Control: Supports speech generation driven by natural language instructions, allowing for flexible control over multi-dimensional acoustic attributes such as timbre, emotion, and prosody. By deeply integrating text semantic understanding, the model adaptively adjusts tone, rhythm, and emotional expression, achieving lifelike “what you imagine is what you hear” output.
Model Performance
We have conducted a comprehensive evaluation of Qwen3-TTS across dimensions such as voice clone, voice design, and control. The results demonstrate that it has achieved SOTA performance across multiple metrics. Specifically:
- In voice design tasks: Qwen3-TTS-VoiceDesign outperformed the MiniMax-Voice-Design closed-source model in both instruction-following capability and generative expressiveness on the InstructTTS-Eval benchmark, while significantly leading other open-source models.
- In voice control tasks: Qwen3-TTS-Instruct demonstrates single-speaker multilingual generalization with an average Word Error Rate (WER) of 2.34%. It also features the ability to maintain timbre while providing precise style control, achieving a score of 75.4% on InstructTTS-Eval. Furthermore, it shows exceptional long-form speech generation capabilities, with a WER of 2.36% (Chinese) and 2.81% (English) during continuous 10-minute synthesis.
- In voice clone tasks: Qwen3-TTS-VoiceClone surpassed MiniMax and SeedTTS in speech stability for both Chinese and English cloning on Seed-tts-eval. On the TTS multilingual test set across 10 languages, it achieved an average WER of 1.835% and a speaker similarity of 0.789, outperforming MiniMax and ElevenLabs. Its cross-lingual voice clone capabilities also reached SOTA, surpassing CosyVoice3.
Tokenizer Performance
We evaluated Qwen-TTS-Tokenizer for speech reconstruction. Results on the LibriSpeech test-clean set demonstrate that it achieves SOTA performance across all key metrics. Specifically, in Perceptual Evaluation of Speech Quality (PESQ), Qwen-TTS-Tokenizer achieved scores of 3.21 and 3.68 in wideband and narrowband respectively, significantly leading similar tokenizers. In Short-Time Objective Intelligibility (STOI) and UTMOS, Qwen-TTS-Tokenizer achieved scores of 0.96 and 4.16, demonstrating superior reconstruction quality. In speaker similarity, Qwen-TTS-Tokenizer achieved a score of 0.95, significantly surpassing comparison models, indicating its near-lossless speaker information preservation capability.
Read previous post:
Read next post:
-

-
Alibaba Cloud Community
1,605 posts | 526 followers
Follow
Comments
-
-
Alibaba Cloud Community
1,605 posts | 526 followers
Follow
Related Products
-
 QwenWork
 is dedicated to helping employees strengthen their professional competitiveness in the AI era and to enabling enterprises to improve organizational effectiveness.
Learn More -
 Token Plan
Build more, spend less. One plan, every modality.
Learn More -
Alibaba Cloud Model Studio
A one-stop generative AI platform to build intelligent applications that understand your business, based on Qwen model series such as Qwen-Max and other popular models
Learn More -
 Qoder
From Assisted to Autonomous — Adapting to Every Programming Need
Learn More
More Posts by Alibaba Cloud Community
- The Easiest Way to Try the Latest Models in One Place: Token Plan Starting at $3 for the First Month
- 一個平台輕鬆試用最新 AI 模型:Token Plan 首月低至 $3
- Alibaba Cloud Advances AI Adoption in Malaysia with Nationwide Youth Contest and Industry Collaborations
- Alibaba Cloud Unveils New AI Initiatives at Hong Kong Summit to Advance the City’s AI Ecosystem
- QoderWake: Digital Workers Take the Initiative — No Need to @ Every Time
- What Is Model Thinking Effort? Should You Choose Low, High, or Maximum?
- High-Risk PHP and Node.js Vulnerabilities: A Scan Costs Pennies. A Miss Could Cost a Fortune.
- Alibaba Unveils Qwen4-Max: New AI Teammate for Work, Creativity, and Discovery
- Alibaba Brings Cloud and AI to the First Youth Olympic Games in Africa
- Introducing Qoder Lite: Start creating with Qoder for $10 a month