Le modèle Qwen-Omni accepte des entrées multimodales et génère des réponses sous forme de texte ou de parole. Il produit des voix naturelles et prend en charge la sortie vocale dans plusieurs langues et dialectes. Les cas d'usage incluent la modération de contenu, la création de texte, la reconnaissance visuelle et l'interaction audio-vidéo.
Régions prises en charge : Singapour, Pékin. Utilisez la clé API correspondant à votre région.
Prise en main
Prérequis- Obtenez une clé API et définissez-la comme variable d'environnement.
- Le modèle Qwen-Omni prend uniquement en charge les appels compatibles avec OpenAI. Vous devez donc installer le dernier SDK. Les versions minimales requises sont 1.52.0 pour le SDK Python OpenAI et 4.68.0 pour le SDK Node.js.
Cet exemple envoie une invite textuelle à l'API Qwen-Omni et retourne une réponse en streaming contenant à la fois du texte et de l'audio.
import os
import base64
import soundfile as sf
import numpy as np
from openai import OpenAI

# 1. Initialize the client
client = OpenAI(
    api_key=os.getenv("DASHSCOPE_API_KEY"),  # Confirm that the environment variable is set
    # Singapore region. Replace {WorkspaceId} with your Bailian workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

# 2. Send the request
try:
    completion = client.chat.completions.create(
        model="qwen3.5-omni-plus",
        messages=[{"role": "user", "content": "Who are you?"}],
        modalities=["text", "audio"],  # Specify text and audio output
        audio={"voice": "Tina", "format": "wav"},
        stream=True,  # Must be set to True
        stream_options={"include_usage": True},
    )

    # 3. Process the streaming response and decode the audio
    print("Model response:")
    audio_base64_string = ""
    for chunk in completion:
        # Process the text part
        if chunk.choices and chunk.choices[0].delta.content:
            print(chunk.choices[0].delta.content, end="")

        # Collect the audio part
        if chunk.choices and hasattr(chunk.choices[0].delta, "audio") and chunk.choices[0].delta.audio:
            audio_base64_string += chunk.choices[0].delta.audio.get("data", "")

    # 4. Save the audio file
    if audio_base64_string:
        wav_bytes = base64.b64decode(audio_base64_string)
        audio_np = np.frombuffer(wav_bytes, dtype=np.int16)
        sf.write("audio_assistant.wav", audio_np, samplerate=24000)
        print("\nAudio file saved to: audio_assistant.wav")

except Exception as e:
    print(f"Request failed: {e}")
// Before you run this code:
// For Windows/Mac/Linux:
// 1. Ensure Node.js version >= 14 is installed.
// 2. Run the following command to install necessary dependencies:
//    npm install openai wav

import OpenAI from "openai";
import { createWriteStream } from 'node:fs';
import { Writer } from 'wav';

// Define a function to convert a Base64 string and save it as a standard WAV audio file
async function convertAudio(audioString, audioPath) {
    try {
        // Decode the Base64 string into a Buffer
        const wavBuffer = Buffer.from(audioString, 'base64');
        // Create a WAV file write stream
        const writer = new Writer({
            sampleRate: 24000,  // Sample rate
            channels: 1,        // Mono
            bitDepth: 16        // 16-bit depth
        });
        // Create an output file stream and establish a pipe connection
        const outputStream = createWriteStream(audioPath);
        writer.pipe(outputStream);

        // Write PCM data and end writing
        writer.write(wavBuffer);
        writer.end();

        // Use a Promise to wait for the file to finish writing
        await new Promise((resolve, reject) => {
            outputStream.on('finish', resolve);
            outputStream.on('error', reject);
        });

        // Add extra wait time to ensure audio integrity
        await new Promise(resolve => setTimeout(resolve, 800));

        console.log(`\nAudio file saved to: ${audioPath}`);
    } catch (error) {
        console.error('Error during processing:', error);
    }
}

//  1. Initialize the client
const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
// 2. Send the request
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus",
    messages: [
        {
            "role": "user",
            "content": "Who are you?"
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

let audioString = "";
console.log("Model response:")

// 3. Process the streaming response and decode the audio
for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        // Process text content
        if (chunk.choices[0].delta.content) {
            process.stdout.write(chunk.choices[0].delta.content);
        }
        // Process audio content
        if (chunk.choices[0].delta.audio) {
            if (chunk.choices[0].delta.audio["data"]) {
                audioString += chunk.choices[0].delta.audio["data"];
            }
        }
    }
}
// 4. Save the audio file
convertAudio(audioString, "audio_assistant.wav");
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
        {
            "role": "user",
            "content": "Who are you?"
        }
    ],
    "stream":true,
    "stream_options":{
        "include_usage":true
    },
    "modalities":["text","audio"],
    "audio":{"voice":"Tina","format":"wav"}
}'
Réponse
Après l'exécution du code Python ou Node.js, la réponse textuelle s'affiche dans la console et un fichier audio nommé audio_assistant.wav est enregistré dans le même répertoire que votre fichier de code.
Model response:
I am a large language model developed by Alibaba Cloud. My name is Qwen. How can I help you?
L'exécution du code HTTP retourne directement du texte et des données audio encodées en Base64 dans le champ audio.
data: {"choices":[{"delta":{"content":"I"},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757647879,"system_fingerprint":null,"model":"qwen3.5-omni-plus","id":"chatcmpl-a68eca3b-c67e-4666-a72f-73c0b4919860"}
data: {"choices":[{"delta":{"content":"am"},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757647879,"system_fingerprint":null,"model":"qwen3.5-omni-plus","id":"chatcmpl-a68eca3b-c67e-4666-a72f-73c0b4919860"}
......
data: {"choices":[{"delta":{"audio":{"data":"/v8AAAAAAAAAAAAAAA...","expires_at":1757647879,"id":"audio_a68eca3b-c67e-4666-a72f-73c0b4919860"}},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757647879,"system_fingerprint":null,"model":"qwen3.5-omni-plus","id":"chatcmpl-a68eca3b-c67e-4666-a72f-73c0b4919860"}
data: {"choices":[{"finish_reason":"stop","delta":{"content":""},"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1764763585,"system_fingerprint":null,"model":"qwen3.5-omni-plus","id":"chatcmpl-e8c82e9e-073e-4289-a786-a20eb444ac9c"}
data: {"choices":[],"object":"chat.completion.chunk","usage":{"prompt_tokens":207,"completion_tokens":103,"total_tokens":310,"completion_tokens_details":{"audio_tokens":83,"text_tokens":20},"prompt_tokens_details":{"text_tokens":207}},"created":1757940330,"system_fingerprint":null,"model":"qwen3.5-omni-plus","id":"chatcmpl-9cdd5a26-f9e9-4eff-9dcc-93a878165afc"}
Sélection du modèle
-
Série Qwen3.5-Omni : Idéale pour l'analyse de vidéos longues, les résumés de réunions, la génération de sous-titres, la modération de contenu et l'interaction audio-vidéo.
- Limites d'entrée : jusqu'à 3 heures d'audio ou 1 heure de vidéo.
- Contrôle audio : permet d'ajuster le volume, la vitesse d'élocution et l'émotion via des instructions.
- Capacité visuelle : équivalente à celle de Qwen3.5. Comprend les images, la parole, les effets sonores et autres entrées multimodales.
- Entrée multimodale combinée : accepte toute combinaison de texte avec des images, de l'audio et de la vidéo dans une seule requête.
- Clonage vocal : prend en charge les voix personnalisées (uniquement qwen3.5-omni-plus et qwen3.5-omni-flash ; les versions snapshot ne sont pas prises en charge). Pour plus de détails, consultez Clonage vocal.
-
Série Qwen3-Omni-Flash : Conçue pour l'analyse de vidéos courtes et les scénarios sensibles aux coûts.
- Limites d'entrée : entrées audio et vidéo jusqu'à 150 secondes.
- Mode réflexion : seul modèle de la série Qwen-Omni à prendre en charge ce mode.
- Modalité d'entrée : accepte uniquement une combinaison de texte avec une seule autre modalité (image, audio ou vidéo).
| Série | Description audio-vidéo | Réflexion approfondie | Recherche Web | Langues audio d'entrée | Langues audio de sortie | Voix prises en charge |
|---|---|---|---|---|---|---|
Qwen3.5-Omni Modèle omni-modal de dernière génération | Élevée | Non pris en charge | Pris en charge | 113 74 langues et 39 dialectes Langues : Chinois, Anglais, Allemand, Français, Italien, Tchèque, Indonésien, Thaï, Coréen, Polonais, Japonais, Vietnamien, Finnois, Portugais, Espagnol, Néerlandais, Russe, Malais, Catalan, Suédois, Turc, Ukrainien, Roumain, Slovaque, Danois, Islandais, Norvégien (Bokmål), Macédonien, Grec, Hongrois, Galicien, Filipino, Croate, Bosniaque, Slovène, Bulgare, Kazakh, Biélorusse, Letton, Estonien, Azéri, Ouïghour, Swahili, Hindi, Espéranto, Kirghize, Tadjik, Cebuano, Afrikaans, Arabe, Lituanien, Javanais, Bengali, Persan, Hébreu, Pendjabi, Gujarati, Mongol, Asturien, Kannada, Marathi, Interlingua, Malayalam, Maltais, Norvégien Nynorsk, Télougou, Ourdou, Géorgien, Basque, Tamoul, Odia, Serbe, Maori Dialectes : | 36 29 langues et 7 dialectes Langues :Chinois, Anglais, Allemand, Italien, Portugais, Espagnol, Japonais, Coréen, Français, Russe, Thaï, Indonésien, Arabe, Vietnamien, Turc, Finnois, Polonais, Hindi, Néerlandais, Tchèque, Ourdou, Tagalog, Suédois, Danois, Hébreu, Islandais, Malais, Norvégien, Persan Dialectes :Dialecte du Sichuan, Dialecte de Pékin, Dialecte de Tianjin, Dialecte de Nanjing, Dialecte du Shaanxi, Cantonais, Minnan | 55 |
Qwen3-Omni-Flash Modèle à réflexion hybride | Plus faible | Pris en charge | Non pris en charge | 19 11 langues et 8 dialectes Langues : Chinois, Anglais, Allemand, Français, Italien, Thaï, Coréen, Japonais, Russe, Espagnol, Portugais Dialectes :Dialecte du Sichuan, Shanghaïen, Cantonais, Minnan, Dialecte du Shaanxi, Dialecte de Nanjing, Dialecte de Tianjin, Dialecte de Pékin | 19 11 langues et 8 dialectes Langues : Chinois, Anglais, Allemand, Français, Italien, Thaï, Coréen, Japonais, Russe, Espagnol, Portugais Dialectes :Sichuanais, Shanghaïen, Cantonais, Hokkien, Dialecte du Shaanxi, Dialecte de Nanjing, Dialecte de Tianjin, Dialecte de Pékin | 17 à 49
|
Pour les noms des modèles, les fenêtres de contexte, les tarifs et les versions snapshot, consultez la console Model Studio. Pour les limites de taux, reportez-vous à Limitation du taux .
Performances du modèle
Analyse de contenu audio et vidéo
| 00:00.000 – 00:02.500 Une rue urbaine trempée par la pluie remplit le cadre grand angle. La photographie à longue exposition crée des traînées de lumières rouges et bleues de voitures sur le pavé mouillé. Un homme solitaire, vêtu d'un trench-coat sombre mi-long et d'une chemise claire avec cravate, marche vers la caméra sur le trottoir de droite. Des gouttes de pluie s'accrochent à ses épaules et à ses cheveux. Chaque pas produit un bruit sourd sur le béton humide. Un bourdonnement électronique grave et menaçant souligne les sons ambiants, tandis qu'une pluie régulière crépite tout autour. Des graffitis colorés couvrent le mur de briques à côté de lui, et des enseignes néon brillent au loin — l'une affiche clairement une écriture cursive orange-rouge indiquant « Nice », tandis qu'une autre enseigne verticale montre les lettres « AT » à sa base. ...... 00:12.300 – 00:14.533La caméra bascule vers le bas. Dans le faisceau d'une lampe torche, une feuille unique jaunie et vieillie repose dans une flaque peu profonde, ses bords carbonisés et ses coins recroquevillés. Des paragraphes encrés couvrent la majeure partie de sa surface, mais l'humidité et les traces de brûlure rendent le texte illisible. L'homme s'agenouille, tendant ses doigts gantés vers le document. Des ondulations se propagent vers l'extérieur alors que sa main s'approche. Les sirènes atteignent leur apogée puis commencent à s'estomper légèrement, tandis que le bourdonnement ambiant reste constant. La scène se fige juste avant que le papier tremblant ne soit touché, terminant ainsi le clip.
|
Compréhension multidialectale
| Cet extrait audio présente des performances de rap par des chanteurs de diverses régions de Chine, mettant en valeur une riche diversité dialectale. Voici les descriptions détaillées des traits vocaux, de l'état émotionnel et des paroles correspondantes pour chaque chanteur : Dialecte de Hangzhou (Wu)Traits vocaux :La voix du chanteur masculin est douce et suave, avec la fluidité et la chaleur distinctives du dialecte Wu. Son intonation monte et descend doucement, et son rythme est léger et rapide, créant un effet de narration détendu. État émotionnel :Détendu, confortable et ancré dans le quotidien. Il décrit le rythme de vie lent de Hangzhou et les changements urbains, exprimant son attachement à sa ville natale et ses réflexions sur le développement moderne. Globalement, il dégage une atmosphère chaleureuse et familière. Paroles :> Dialecte de Hangzhou, écoutez bien ! Notre culture inclut la prononciation locale avec erhua. > Comme des fleurs qui éclosent au bord du lac de l'Ouest, pas besoin d'enquête culturelle — nous comprenons cela mieux que quiconque. > Aucun de vous ne comprend. « San bu da men », « ge'r », « lao'r », « fen'r », « ya'r »... comment un étranger pourrait-il les distinguer ? > Allons-y ! Les transports sont rapides — des métros partout. On va jeter un œil. > Bienvenue à l'Asie du Sud-Est et à la Thaïlande, en regardant les émissions « Thirteen Ta ». Fiers de notre ville, directs dans notre personnalité. > Alors vous n'êtes venus que pour l'expérience du « passage du pont », et parce que la saveur est différente, vous ne revenez pas ?
|
Génération de sous-titres de paroles
| [00:00:12,680 --> 00:00:16,960] Cat thread sways past moonlight on trees. [00:00:18,400 --> 00:00:22,800] Radiators hum 1998 chart hits. [00:00:24.160 → 00:00:28.080] Time parts the mist-like heat waves. [00:00:28,920 --> 00:00:33,000] Neon from the screen shines on my nose bridge. ...... [00:03:16,720 --> 00:03:21,680] We nestle in the softest ring of the tree trunk. [00:03:22,400 --> 00:03:27,000] Breathing turns residual warmth into honey-sugar. [00:03:28,160 --> 00:03:33,200] The sofa sinks into cloud-fluff shape. [00:03:34,000 --> 00:03:38,800] Every pore soaks in sunshine. [00:04:09,000 --> 00:04:10,020] (End)
|
Programmation audio-vidéo
Utilisation
Sortie en streaming
Toutes les requêtes adressées à Qwen-Omni doivent définir stream=True.
Configuration du modèle
Configurez les paramètres, les invites et la durée des médias pour trouver l'équilibre entre coût, rapidité et qualité.
Compréhension audio-vidéo
| Cas d'usage | Durée vidéo recommandée | Invite recommandée | max_pixels recommandé |
Examen rapide, faible coût | ≤ 60 minutes | Invite simple de moins de 50 mots | 230 400 |
Extraction de contenu (segmentation vidéo longue) | ≤ 60 minutes | 921 600 ~ 2 073 600 | |
Analyse standard (tagging vidéo courte) | ≤ 4 minutes | Utilisez l'invite structurée ci-dessous Invite recommandée | 921 600 ~ 2 073 600 |
Analyse fine (plusieurs intervenants / scènes complexes) | ≤ 2 minutes | 2 073 600 |
RemarqueVous pouvez segmenter au préalable les vidéos longues afin d'obtenir des descriptions plus précises.
Compréhension audio
Il est possible d'équilibrer coût et qualité en contrôlant la durée de l'audio et la complexité de l'invite.
| Cas d'usage | Durée audio recommandée | Invite recommandée |
Examen rapide, faible coût | ≤ 60 minutes | Invite simple de moins de 50 mots |
Extraction de contenu (segmentation audio long) | ≤ 60 minutes | |
Analyse standard (tagging audio) | ≤ 2 minutes | Utilisez une invite structurée Invite structurée |
Analyse fine (plusieurs intervenants / scènes complexes) | ≤ 1 minute |
RemarqueVous pouvez segmenter au préalable les fichiers audio longs afin d'obtenir des descriptions plus précises.
Entrée multimodale combinée
RemarqueL'entrée multimodale combinée est prise en charge uniquement par la série Qwen3.5-Omni. Vous avez la possibilité de fournir des données dans plusieurs modalités au sein d'une même requête, par exemple une combinaison d'images, d'audio et de texte, ou encore de vidéos, d'images et de texte.
L'exemple suivant illustre comment soumettre une image et un fichier audio dans une requête unique pour une analyse multimodale.
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # China (Beijing) region. Replace {WorkspaceId} with your Bailian workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.cn-beijing.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
                    },
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    },
                },
                {"type": "text", "text": "Describe the image content and tell me what the audio is about."},
            ],
        },
    ],
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        apiKey: process.env.DASHSCOPE_API_KEY,
        // China (Beijing) region. Replace {WorkspaceId} with your Bailian workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.cn-beijing.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus",
    messages: [
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": { "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg" },
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    },
                },
                { "type": "text", "text": "Describe the image content and tell me what the audio is about." }
            ]
        }
    ],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
curl -X POST https://{WorkspaceId}.cn-beijing.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
                    }
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    }
                },
                {
                    "type": "text",
                    "text": "Describe the image content and tell me what the audio is about."
                }
            ]
        }
    ],
    "stream": true,
    "stream_options": {
        "include_usage": true
    },
    "modalities": ["text", "audio"],
    "audio": {"voice": "Tina", "format": "wav"}
}'
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
                    },
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    },
                },
                {"type": "text", "text": "Describe the image content and tell me what the audio is about."},
            ],
        },
    ],
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus",
    messages: [
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": { "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg" },
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    },
                },
                { "type": "text", "text": "Describe the image content and tell me what the audio is about." }
            ]
        }
    ],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
                    }
                },
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav"
                    }
                },
                {
                    "type": "text",
                    "text": "Describe the image content and tell me what the audio is about."
                }
            ]
        }
    ],
    "stream": true,
    "stream_options": {
        "include_usage": true
    },
    "modalities": ["text", "audio"],
    "audio": {"voice": "Tina", "format": "wav"}
}'
Entrée unimodale
Chaque requête comprend du texte ainsi qu'une autre modalité (vidéo, audio ou image). Tous les modèles Qwen-Omni prennent en charge ce fonctionnement.
Entrée vidéo et texte
Fournissez la vidéo sous forme de liste d'images ou de fichier vidéo (avec prise en charge de l'audio).
Fichier vidéo (prend en charge l'audio intégré)
-
Nombre de fichiers :
- Série Qwen3.5-Omni : jusqu'à 512 fichiers via des URL publiques et jusqu'à 250 fichiers avec l'encodage Base64.
- Séries Qwen3-Omni-Flash : un seul fichier autorisé.
-
Taille des fichiers :
-
Via des URL publiques :
- Série Qwen3.5-Omni : jusqu'à 2 Go
- Qwen3-Omni-Flash : jusqu'à 256 Mo
-
Avec l'encodage Base64 : la chaîne Base64 encodée doit être inférieure à 10 Mo
-
-
Limites de durée :
- Série Qwen3.5-Omni : 1 heure
- Qwen3-Omni-Flash : 150 secondes
-
Formats de fichiers pris en charge : MP4, AVI, MKV, MOV, FLV et WMV.
-
Les informations visuelles et audio du fichier vidéo sont facturées séparément.
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "video_url",
                    "video_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241115/cqqkru/1.mp4"
                    },
                },
                {"type": "text", "text": "What is the video about?"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "video_url",
                "video_url": { "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241115/cqqkru/1.mp4" },
            },
            { "type": "text", "text": "What is the video about?" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
    {
      "role": "user",
      "content": [
        {
          "type": "video_url",
          "video_url": {
            "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241115/cqqkru/1.mp4"
          }
        },
        {
          "type": "text",
          "text": "What is the video about"
        }
      ]
    }
  ],
    "stream":true,
    "stream_options": {
        "include_usage": true
    },
    "modalities":["text","audio"],
    "audio":{"voice":"Tina","format":"wav"}
}'
Format de liste d'images
Nombre d'images- Série Qwen3.5-Omni : 2 images minimum et 2048 images maximum
- Qwen3-Omni-Flash : 2 images minimum et 128 images maximum
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "video",
                    "video": [
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/xzsgiz/football1.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/tdescd/football2.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/zefdja/football3.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/aedbqh/football4.jpg",
                    ],
                },
                {"type": "text", "text": "Describe the process shown in this video"},
            ],
        }
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [{
        role: "user",
        content: [
            {
                type: "video",
                video: [
                    "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/xzsgiz/football1.jpg",
                    "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/tdescd/football2.jpg",
                    "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/zefdja/football3.jpg",
                    "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/aedbqh/football4.jpg"
                ]
            },
            {
                type: "text",
                text: "Describe the process shown in this video"
            }
        ]
    }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
        {
            "role": "user",
            "content": [
                {
                    "type": "video",
                    "video": [
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/xzsgiz/football1.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/tdescd/football2.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/zefdja/football3.jpg",
                        "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241108/aedbqh/football4.jpg"
                    ]
                },
                {
                    "type": "text",
                    "text": "Describe the process shown in this video"
                }
            ]
        }
    ],
    "stream": true,
    "stream_options": {
        "include_usage": true
    },
    "modalities": ["text", "audio"],
    "audio": {
        "voice": "Tina",
        "format": "wav"
    }
}'
Entrée audio et texte
-
Nombre de fichiers :
- Série Qwen3.5-Omni : jusqu'à 2048 fichiers via des URL publiques et jusqu'à 250 fichiers avec l'encodage Base64.
- Séries Qwen3-Omni-Flash : un seul fichier autorisé.
-
Taille des fichiers :
-
Via des URL publiques :
- Série Qwen3.5-Omni : jusqu'à 2 Go
- Qwen3-Omni-Flash : jusqu'à 100 Mo
-
Avec l'encodage Base64 : la chaîne Base64 encodée doit être inférieure à 10 Mo
-
-
Limites de durée :
- Série Qwen3.5-Omni : jusqu'à 3 heures
- Qwen3-Omni-Flash : jusqu'à 20 minutes
-
Formats de fichiers pris en charge : AMR, WAV, 3GP, 3GPP, AAC et MP3.
Cet exemple utilise une URL audio publique. Pour utiliser un fichier local, consultez la section Envoyer des fichiers locaux avec l'encodage Base64. Seul le flux de sortie (streaming) est pris en charge pour cet appel.
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus",# For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
                        "format": "wav",
                    },
                },
                {"type": "text", "text": "What is this audio about"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "input_audio",
                "input_audio": { "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav", "format": "wav" },
            },
            { "type": "text", "text": "What is this audio about" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
    {
      "role": "user",
      "content": [
        {
          "type": "input_audio",
          "input_audio": {
            "data": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20250211/tixcef/cherry.wav",
            "format": "wav"
          }
        },
        {
          "type": "text",
          "text": "What is this audio about"
        }
      ]
    }
  ],
    "stream":true,
    "stream_options":{
        "include_usage":true
    },
    "modalities":["text","audio"],
    "audio":{"voice":"Tina","format":"wav"}
}'
Entrée image et texte
Les modèles Qwen-Omni acceptent plusieurs images par requête. Exigences relatives aux images :
-
Nombre d'images :
- Via une URL publique : jusqu'à 2048 images
- Avec l'encodage Base64 : jusqu'à 250 images
-
Taille des images :
-
Via des URL publiques :
- Série Qwen3.5-Omni : chaque fichier image ne doit pas dépasser 20 Mo
- Séries Qwen3-Omni-Flash : chaque fichier image ne doit pas dépasser 10 Mo
-
Avec l'encodage Base64 : la chaîne Base64 encodée doit être inférieure à 10 Mo.
-
-
La largeur et la hauteur doivent toutes deux dépasser 10 pixels. Le rapport d'aspect ne doit pas excéder 200:1 ni 1:200.
-
Types d'images pris en charge : consultez la rubrique Compréhension d'images et de vidéos.
Cet exemple utilise une URL d'image publique. Pour utiliser un fichier local, reportez-vous à la section Entrée de fichier local encodé en Base64. Le flux de sortie (streaming) est obligatoire.
Compatible OpenAI
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
                    },
                },
                {"type": "text", "text": "What scene is depicted in the image?"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={
        "include_usage": True
    }
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "image_url",
                "image_url": { "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg" },
            },
            { "type": "text", "text": "What scene is depicted in the image?" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
    {
      "role": "user",
      "content": [
        {
          "type": "image_url",
          "image_url": {
            "url": "https://help-static-aliyun-doc.aliyuncs.com/file-manage-files/zh-CN/20241022/emyrja/dog_and_girl.jpeg"
          }
        },
        {
          "type": "text",
          "text": "What scene is depicted in the image?"
        }
      ]
    }
  ],
    "stream":true,
    "stream_options":{
        "include_usage":true
    },
    "modalities":["text","audio"],
    "audio":{"voice":"Tina","format":"wav"}
}'
Recherche web
La série Qwen3.5-Omni prend en charge la recherche web pour récupérer des informations en temps réel et effectuer un raisonnement.
- Cette fonctionnalité est disponible uniquement avec la série Qwen3.5-Omni. Le paramètre
search_strategyaccepte exclusivement la valeuragent. - Pour plus de détails sur la facturation, consultez la politique
agentdans la rubrique Facturation.
Pour activer la recherche web, définissez les paramètres enable_search et search_strategy sur agent :
OpenAI compatible
# Prerequisites:
# pip install openai

import os
from openai import OpenAI

# Initialize the client
client = OpenAI(
    # API Keys differ between Singapore and Beijing regions. Get API Key:https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

# Send request (with web search enabled)
try:
    completion = client.chat.completions.create(
        model="qwen3.5-omni-plus",
        messages=[{
            "role": "user",
            "content": "What is today's date and day of the week, and what important holidays are there today?"
        }],
        stream=True,
        stream_options={"include_usage": True},
        # Enable web search
        extra_body={
            "enable_search": True
        }
    )

    print("Model response (with real-time information):")
    for chunk in completion:
        if chunk.choices and chunk.choices[0].delta.content:
            print(chunk.choices[0].delta.content, end="")
    print()

except Exception as e:
    print(f"Request failed:{e}")
// Prerequisites:
// npm install openai

import OpenAI from "openai";

// Initialize the client
const openai = new OpenAI({
    // API Keys differ between Singapore and Beijing regions. Get API Key:https://www.alibabacloud.com/help/en/model-studio/get-api-key
    apiKey: process.env.DASHSCOPE_API_KEY,
    // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
});

// Send request (with web search enabled)
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus",
    messages: [{
        "role": "user",
        "content": "What is today's date and day of the week, and what important holidays are there today?"
    }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    // Enable web search
    extra_body: {
        enable_search: true
    }
});

console.log("Model response (with real-time information):");

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        if (chunk.choices[0].delta.content) {
            process.stdout.write(chunk.choices[0].delta.content);
        }
    }
}
console.log();
# ======= Important =======
# API Keys differ between Singapore and Beijing regions. Get API Key:https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Remove this comment before running ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3.5-omni-plus",
    "messages": [
        {
            "role": "user",
            "content": "What is today's date and day of the week, and what important holidays are there today?"
        }
    ],
    "stream": true,
    "stream_options": {
        "include_usage": true
    },
    "enable_search": true
}'
Activer ou désactiver le mode de réflexion
Au sein de la série Qwen-Omni, seul le modèle Qwen3-Omni-Flash est un modèle de réflexion hybride. Utilisez le paramètre enable_thinking pour activer ou désactiver ce mode :
truefalse(valeur par défaut)
En mode de réflexion, la sortie audio n'est pas prise en charge.
OpenAI compatible
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3-omni-flash",
    messages=[{"role": "user", "content": "Who are you?"}],

    extra_body={'enable_thinking': True},

    # Set the output modality. Two options are supported in non-thinking mode: ["text","audio"] and ["text"]. Only ["text"] is supported in thinking mode.
    modalities=["text"],

    # Set the voice. The audio parameter is not supported in thinking mode.
    # audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3-omni-flash",
    messages: [
        { role: "user", content: "Who are you?" }
    ],

    // stream must be set to True, otherwise an error occurs.
    stream: true,
    stream_options: {
        include_usage: true
    },
    // Enable or disable thinking mode. Audio output is not supported in thinking mode
    extra_body:{'enable_thinking': true},
    //  Set the output modality. Two options are supported in non-thinking mode: ["text","audio"] and ["text"]. Only ["text"] is supported in thinking mode.
    modalities: ["text"],
    // Set the voice. The audio parameter is not supported in thinking mode.
    //audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
    "model": "qwen3-omni-flash",
    "messages": [
        {
            "role": "user",
            "content": "Who are you?"
        }
    ],
    "stream":true,
    "stream_options":{
        "include_usage":true
    },
    "modalities":["text"],
    "enable_thinking": true
}'
Réponse
data: {"choices":[{"delta":{"content":null,"role":"assistant","reasoning_content":""},"index":0,"logprobs":null,"finish_reason":null}],"object":"chat.completion.chunk","usage":null,"created":1757937336,"system_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
data: {"choices":[{"finish_reason":null,"logprobs":null,"delta":{"content":null,"reasoning_content":"Hmm"},"index":0}],"object":"chat.completion.chunk","usage":null,"reated":1757937336,"system_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
data: {"choices":[{"delta":{"content":null,"reasoning_content":","},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"reated":1757937336,"system_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
......
data: {"choices":[{"delta":{"content":"Tell me"},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757937336,"tem_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
data: {"choices":[{"delta":{"content":"!"},"finish_reason":null,"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757937336,"systm_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
data: {"choices":[{"finish_reason":"stop","delta":{"content":"","reasoning_content":null},"index":0,"logprobs":null}],"object":"chat.completion.chunk","usage":null,"created":1757937336,"system_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
data: {"choices":[],"object":"chat.completion.chunk","usage":{"prompt_tokens":11,"completion_tokens":363,"total_tokens":374,"completion_tokens_details":{"reasoning_tokens":195,"text_tokens":168},"prompt_tokens_details":{"text_tokens":11}},"created":1757937336,"system_fingerprint":null,"model":"qwen3-omni-flash","id":"chatcmpl-ce3d6fe5-e717-4b7e-8b40-3aef12288d4c"}
Conversation multi-tours
Lors de l'utilisation des modèles Qwen-Omni pour des conversations multi-tours, tenez compte des points suivants :
-
Message de l'assistant
Les messages de l'assistant dans le tableau
messagesne peuvent contenir que des données textuelles. -
Message utilisateur
Un message utilisateur peut combiner du texte avec une autre modalité. Au fil des tours de conversation, il est possible d'intégrer différentes modalités dans des messages utilisateurs distincts.
OpenAI compatible
import os
from openai import OpenAI

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://dashscope.oss-cn-beijing.aliyuncs.com/audios/welcome.mp3",
                        "format": "mp3",
                    },
                },
                {"type": "text", "text": "What is this audio about"},
            ],
        },
        {
            "role": "assistant",
            "content": [{"type": "text", "text": "This audio says: Welcome to Alibaba Cloud"}],
        },
        {
            "role": "user",
            "content": [{"type": "text", "text": "Tell me about this company."}],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text"],
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": "https://dashscope.oss-cn-beijing.aliyuncs.com/audios/welcome.mp3",
                        "format": "mp3",
                    },
                },
                { "type": "text", "text": "What is this audio about" },
            ],
        },
        {
            "role": "assistant",
            "content": [{ "type": "text", "text": "This audio says: Welcome to Alibaba Cloud" }],
        },
        {
            "role": "user",
            "content": [{ "type": "text", "text": "Tell me about this company." }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text"]
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
# ======= Important note =======
# API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
# The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
# === Delete this comment before execution ===

curl -X POST https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1/chat/completions \
-H "Authorization: Bearer $DASHSCOPE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
  "model": "qwen3.5-omni-plus",
  "messages": [
    {
      "role": "user",
      "content": [
        {
          "type": "input_audio",
          "input_audio": {
            "data": "https://dashscope.oss-cn-beijing.aliyuncs.com/audios/welcome.mp3"
          }
        },
        {
          "type": "text",
          "text": "What is this audio about"
        }
      ]
    },
    {
      "role": "assistant",
      "content": [
        {
          "type": "text",
          "text": "This audio says: Welcome to Alibaba Cloud"
        }
      ]
    },
    {
      "role": "user",
      "content": [
        {
          "type": "text",
          "text": "Tell me about this company."
        }
      ]
    }
  ],
  "stream": true,
  "stream_options": {
    "include_usage": true
  },
  "modalities": ["text"]
}'
Analyse des données audio encodées en Base64 issues de la sortie
Les modèles Qwen-Omni produisent l'audio sous forme de flux de données encodées en Base64. Pendant la génération, maintenez une variable chaîne de caractères et ajoutez-y les données Base64 de chaque fragment retourné. Une fois la génération terminée, décodez la chaîne complète en Base64 pour obtenir le fichier audio. Vous pouvez également décoder et lire chaque fragment en temps réel.
# Installation instructions for pyaudio:
# APPLE Mac OS X
#   brew install portaudio
#   pip install pyaudio
# Debian/Ubuntu
#   sudo apt-get install python-pyaudio python3-pyaudio
#   or
#   pip install pyaudio
# CentOS
#   sudo yum install -y portaudio portaudio-devel && pip install pyaudio
# Microsoft Windows
#   python -m pip install pyaudio

import os
from openai import OpenAI
import base64
import numpy as np
import soundfile as sf

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[{"role": "user", "content": "Who are you?"}],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

# Method 1: Decode after generation is complete
audio_string = ""
for chunk in completion:
    if chunk.choices:
        if hasattr(chunk.choices[0].delta, "audio"):
            try:
                audio_string += chunk.choices[0].delta.audio["data"]
            except Exception as e:
                print(chunk.choices[0].delta.content)
    else:
        print(chunk.usage)

wav_bytes = base64.b64decode(audio_string)
audio_np = np.frombuffer(wav_bytes, dtype=np.int16)
sf.write("audio_assistant_py.wav", audio_np, samplerate=24000)

# Method 2: Decode while generating (comment out the code for Method 1 to use Method 2)
# # Initialize PyAudio
# import pyaudio
# import time
# p = pyaudio.PyAudio()
# # Create an audio stream
# stream = p.open(format=pyaudio.paInt16,
#                 channels=1,
#                 rate=24000,
#                 output=True)

# for chunk in completion:
#     if chunk.choices:
#         if hasattr(chunk.choices[0].delta, "audio"):
#             try:
#                 audio_string = chunk.choices[0].delta.audio["data"]
#                 wav_bytes = base64.b64decode(audio_string)
#                 audio_np = np.frombuffer(wav_bytes, dtype=np.int16)
#                 # Play the audio data directly
#                 stream.write(audio_np.tobytes())
#             except Exception as e:
#                 print(chunk.choices[0].delta.content)

# time.sleep(0.8)
# # Clean up resources
# stream.stop_stream()
# stream.close()
# p.terminate()
// Before running:
// For Windows/Mac/Linux:
// 1. Ensure Node.js version >= 14 is installed.
// 2. Run the following command to install necessary dependencies:
//    npm install openai wav
//
// To use the real-time playback feature (Method 2), you also need:
// Windows:
//    npm install speaker
// Mac:
//    brew install portaudio
//    npm install speaker
// Linux (Ubuntu/Debian):
//    sudo apt-get install libasound2-dev
//    npm install speaker

import OpenAI from "openai";

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);
const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": "Who are you?"
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

// Method 1: Decode after generation is complete
// Requires installation: npm install wav
import { createWriteStream } from 'node:fs';  // node:fs is a built-in Node.js module, no installation required
import { Writer } from 'wav';

async function convertAudio(audioString, audioPath) {
    try {
        // Decode the Base64 string into a Buffer
        const wavBuffer = Buffer.from(audioString, 'base64');
        // Create a WAV file write stream
        const writer = new Writer({
            sampleRate: 24000,  // Sample rate
            channels: 1,        // Mono
            bitDepth: 16        // 16-bit depth
        });
        // Create an output file stream and establish a pipe connection
        const outputStream = createWriteStream(audioPath);
        writer.pipe(outputStream);

        // Write PCM data and end writing
        writer.write(wavBuffer);
        writer.end();

        // Use a Promise to wait for the file to finish writing
        await new Promise((resolve, reject) => {
            outputStream.on('finish', resolve);
            outputStream.on('error', reject);
        });

        // Add extra wait time to ensure audio integrity
        await new Promise(resolve => setTimeout(resolve, 800));

        console.log(`Audio file successfully saved as ${audioPath}`);
    } catch (error) {
        console.error('An error occurred during processing:', error);
    }
}

let audioString = "";
for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        if (chunk.choices[0].delta.audio) {
            if (chunk.choices[0].delta.audio["data"]) {
                audioString += chunk.choices[0].delta.audio["data"];
            }
        }
    } else {
        console.log(chunk.usage);
    }
}
// Execute the conversion
convertAudio(audioString, "audio_assistant_mjs.wav");

// Method 2: Generate and play in real time
// Install necessary components according to your system's instructions above.
// import Speaker from 'speaker'; // Import the audio playback library

// // Create a speaker instance (configuration matches WAV file parameters)
// const speaker = new Speaker({
//     sampleRate: 24000,  // Sample rate
//     channels: 1,        // Number of sound channels
//     bitDepth: 16,       // Bit depth
//     signed: true        // Signed PCM
// });
// for await (const chunk of completion) {
//     if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
//         if (chunk.choices[0].delta.audio) {
//             if (chunk.choices[0].delta.audio["data"]) {
//                 const pcmBuffer = Buffer.from(chunk.choices[0].delta.audio.data, 'base64');
//                 // Write directly to the speaker for playback
//                 speaker.write(pcmBuffer);
//             }
//         }
//     } else {
//         console.log(chunk.usage);
//     }
// }
// speaker.on('finish', () => console.log('Playback complete'));
// speaker.end(); // Call based on the actual end of the API stream
Fichier local encodé en Base64 en entrée
Lors de l'envoi de fichiers via un encodage Base64, la chaîne Base64 résultante ne doit pas dépasser 10 Mo.
Images
Cet exemple utilise le fichier enregistré localement eagle.png.
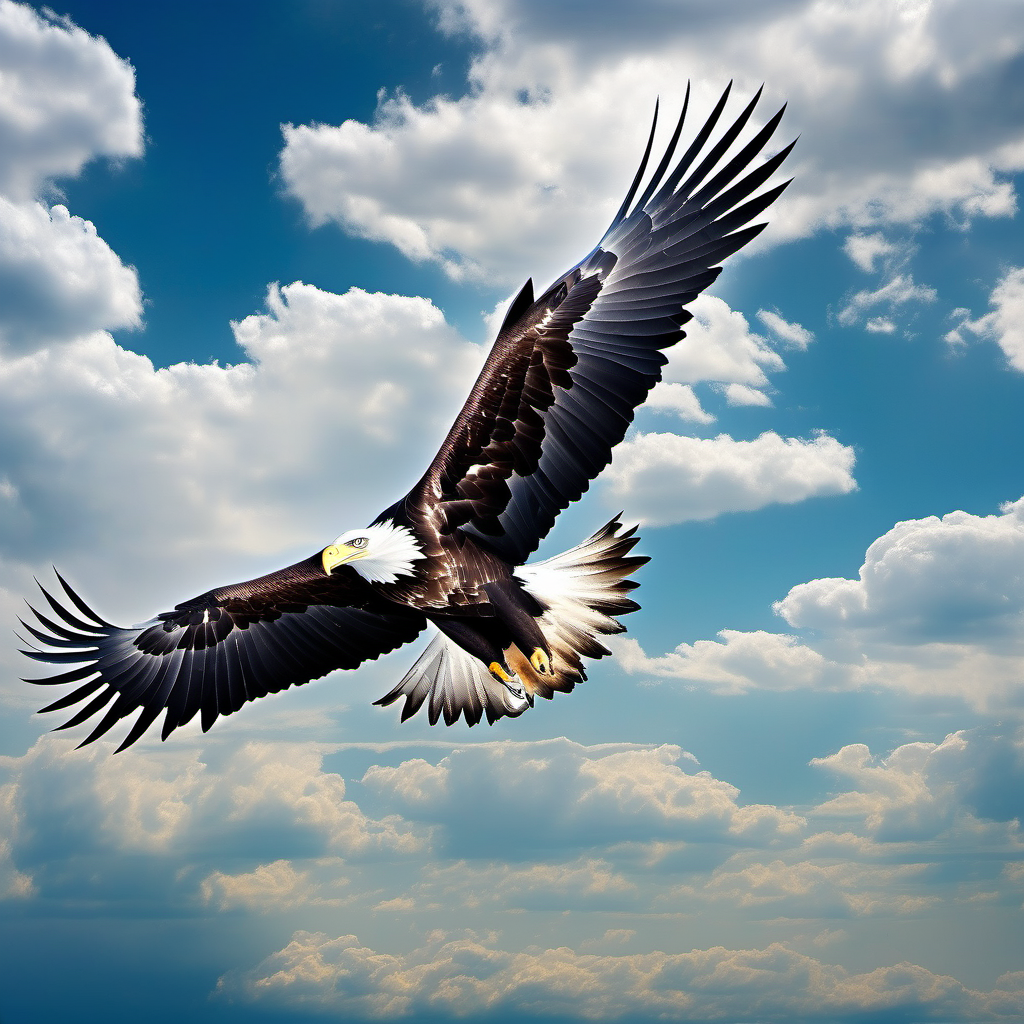
import os
from openai import OpenAI
import base64

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

# Base64 encoding format
def encode_image(image_path):
    with open(image_path, "rb") as image_file:
        return base64.b64encode(image_file.read()).decode("utf-8")

base64_image = encode_image("eagle.png")

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {"url": f"data:image/png;base64,{base64_image}"},
                },
                {"type": "text", "text": "What scene is depicted in the image?"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";
import { readFileSync } from 'fs';

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const encodeImage = (imagePath) => {
    const imageFile = readFileSync(imagePath);
    return imageFile.toString('base64');
};
const base64Image = encodeImage("eagle.png")

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus",// For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "image_url",
                "image_url": { "url": `data:image/png;base64,${base64Image}` },
            },
            { "type": "text", "text": "What scene is depicted in the image?" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
Audio
Cet exemple s'appuie sur le fichier enregistré localement welcome.mp3.
import os
from openai import OpenAI
import base64
import numpy as np
import soundfile as sf
import requests

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

def encode_audio(audio_path):
    with open(audio_path, "rb") as audio_file:
        return base64.b64encode(audio_file.read()).decode("utf-8")

base64_audio = encode_audio("welcome.mp3")

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "input_audio",
                    "input_audio": {
                        "data": f"data:;base64,{base64_audio}",
                        "format": "mp3",
                    },
                },
                {"type": "text", "text": "What is this audio about"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";
import { readFileSync } from 'fs';

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const encodeAudio = (audioPath) => {
    const audioFile = readFileSync(audioPath);
    return audioFile.toString('base64');
};
const base64Audio = encodeAudio("welcome.mp3")

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "input_audio",
                "input_audio": { "data": `data:;base64,${base64Audio}`, "format": "mp3" },
            },
            { "type": "text", "text": "What is this audio about" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
Vidéo
Fichier vidéo
L'exemple suivant exploite le fichier enregistré localement spring_mountain.mp4.
import os
from openai import OpenAI
import base64
import numpy as np
import soundfile as sf

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
    base_url="https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1",
)

# Base64 encoding format
def encode_video(video_path):
    with open(video_path, "rb") as video_file:
        return base64.b64encode(video_file.read()).decode("utf-8")

base64_video = encode_video("spring_mountain.mp4")

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "video_url",
                    "video_url": {"url": f"data:;base64,{base64_video}"},
                },
                {"type": "text", "text": "What is she singing?"},
            ],
        },
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";
import { readFileSync } from 'fs';

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const encodeVideo = (videoPath) => {
    const videoFile = readFileSync(videoPath);
    return videoFile.toString('base64');
};
const base64Video = encodeVideo("spring_mountain.mp4")

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [
        {
            "role": "user",
            "content": [{
                "type": "video_url",
                "video_url": { "url": `data:;base64,${base64Video}` },
            },
            { "type": "text", "text": "What is she singing?" }]
        }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
Liste d'images
Prenons par exemple les fichiers enregistrés localement suivants : football1.jpg, football2.jpg, football3.jpg et football4.jpg.
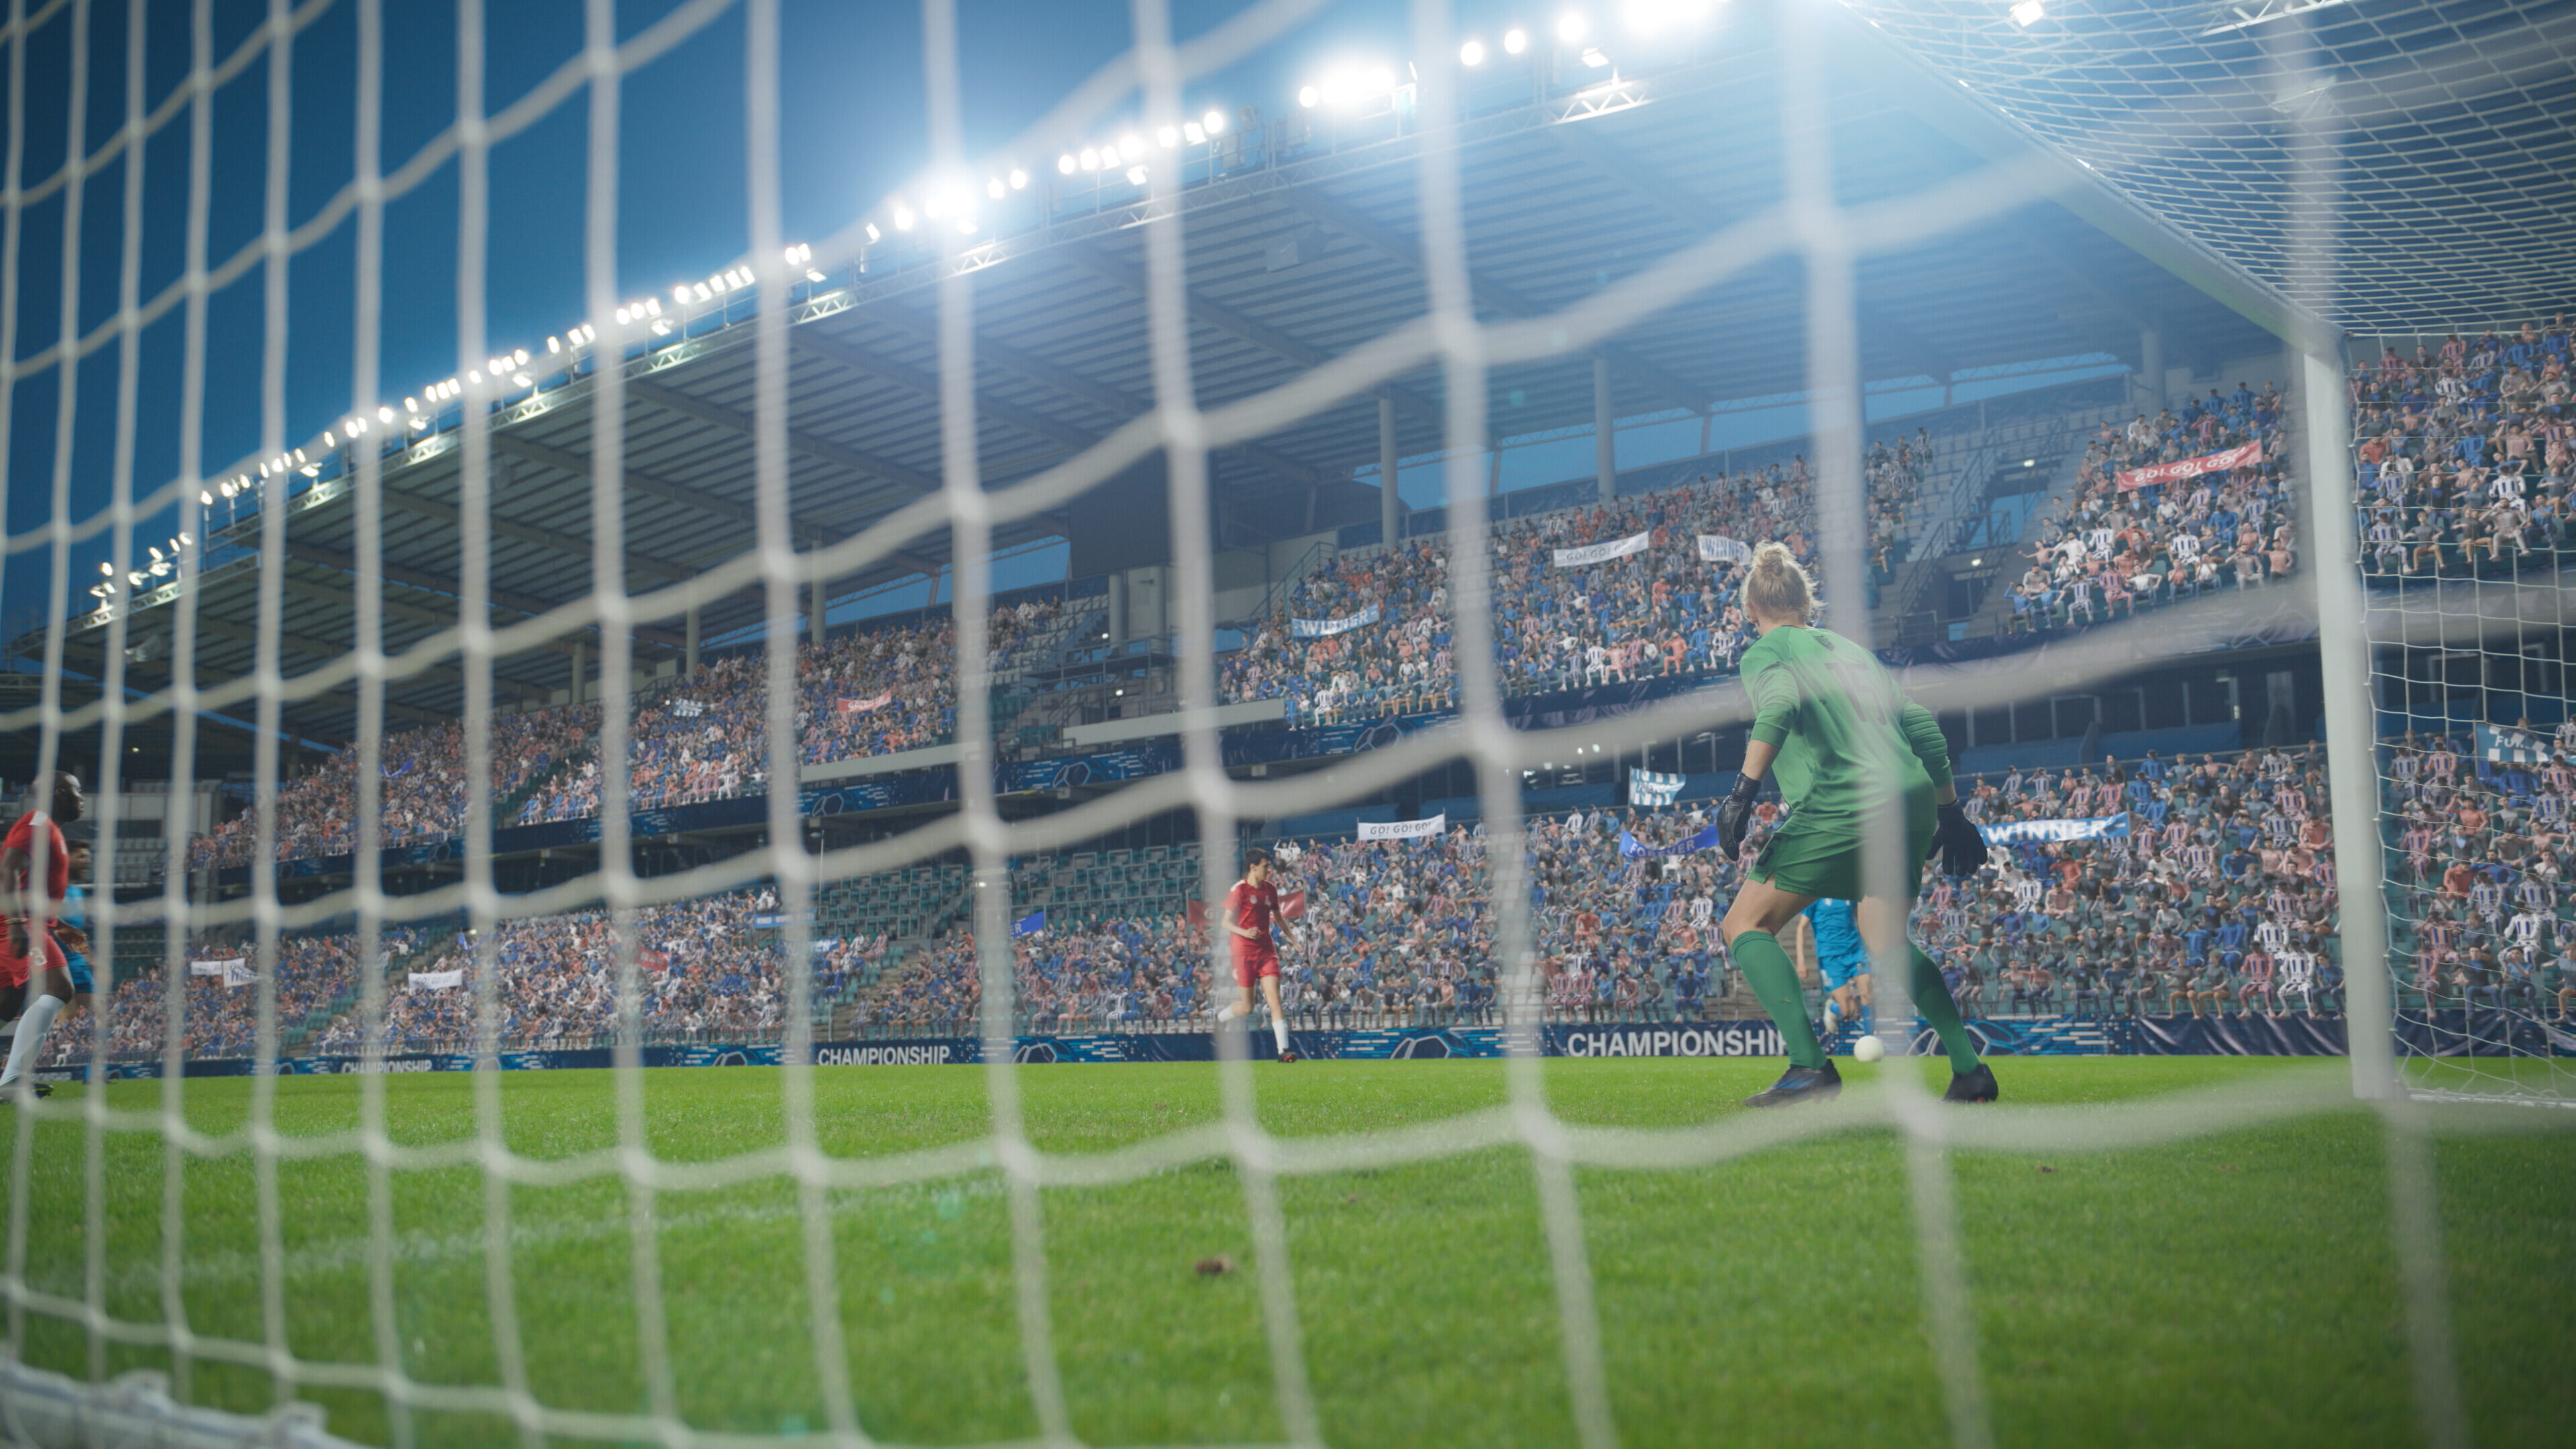
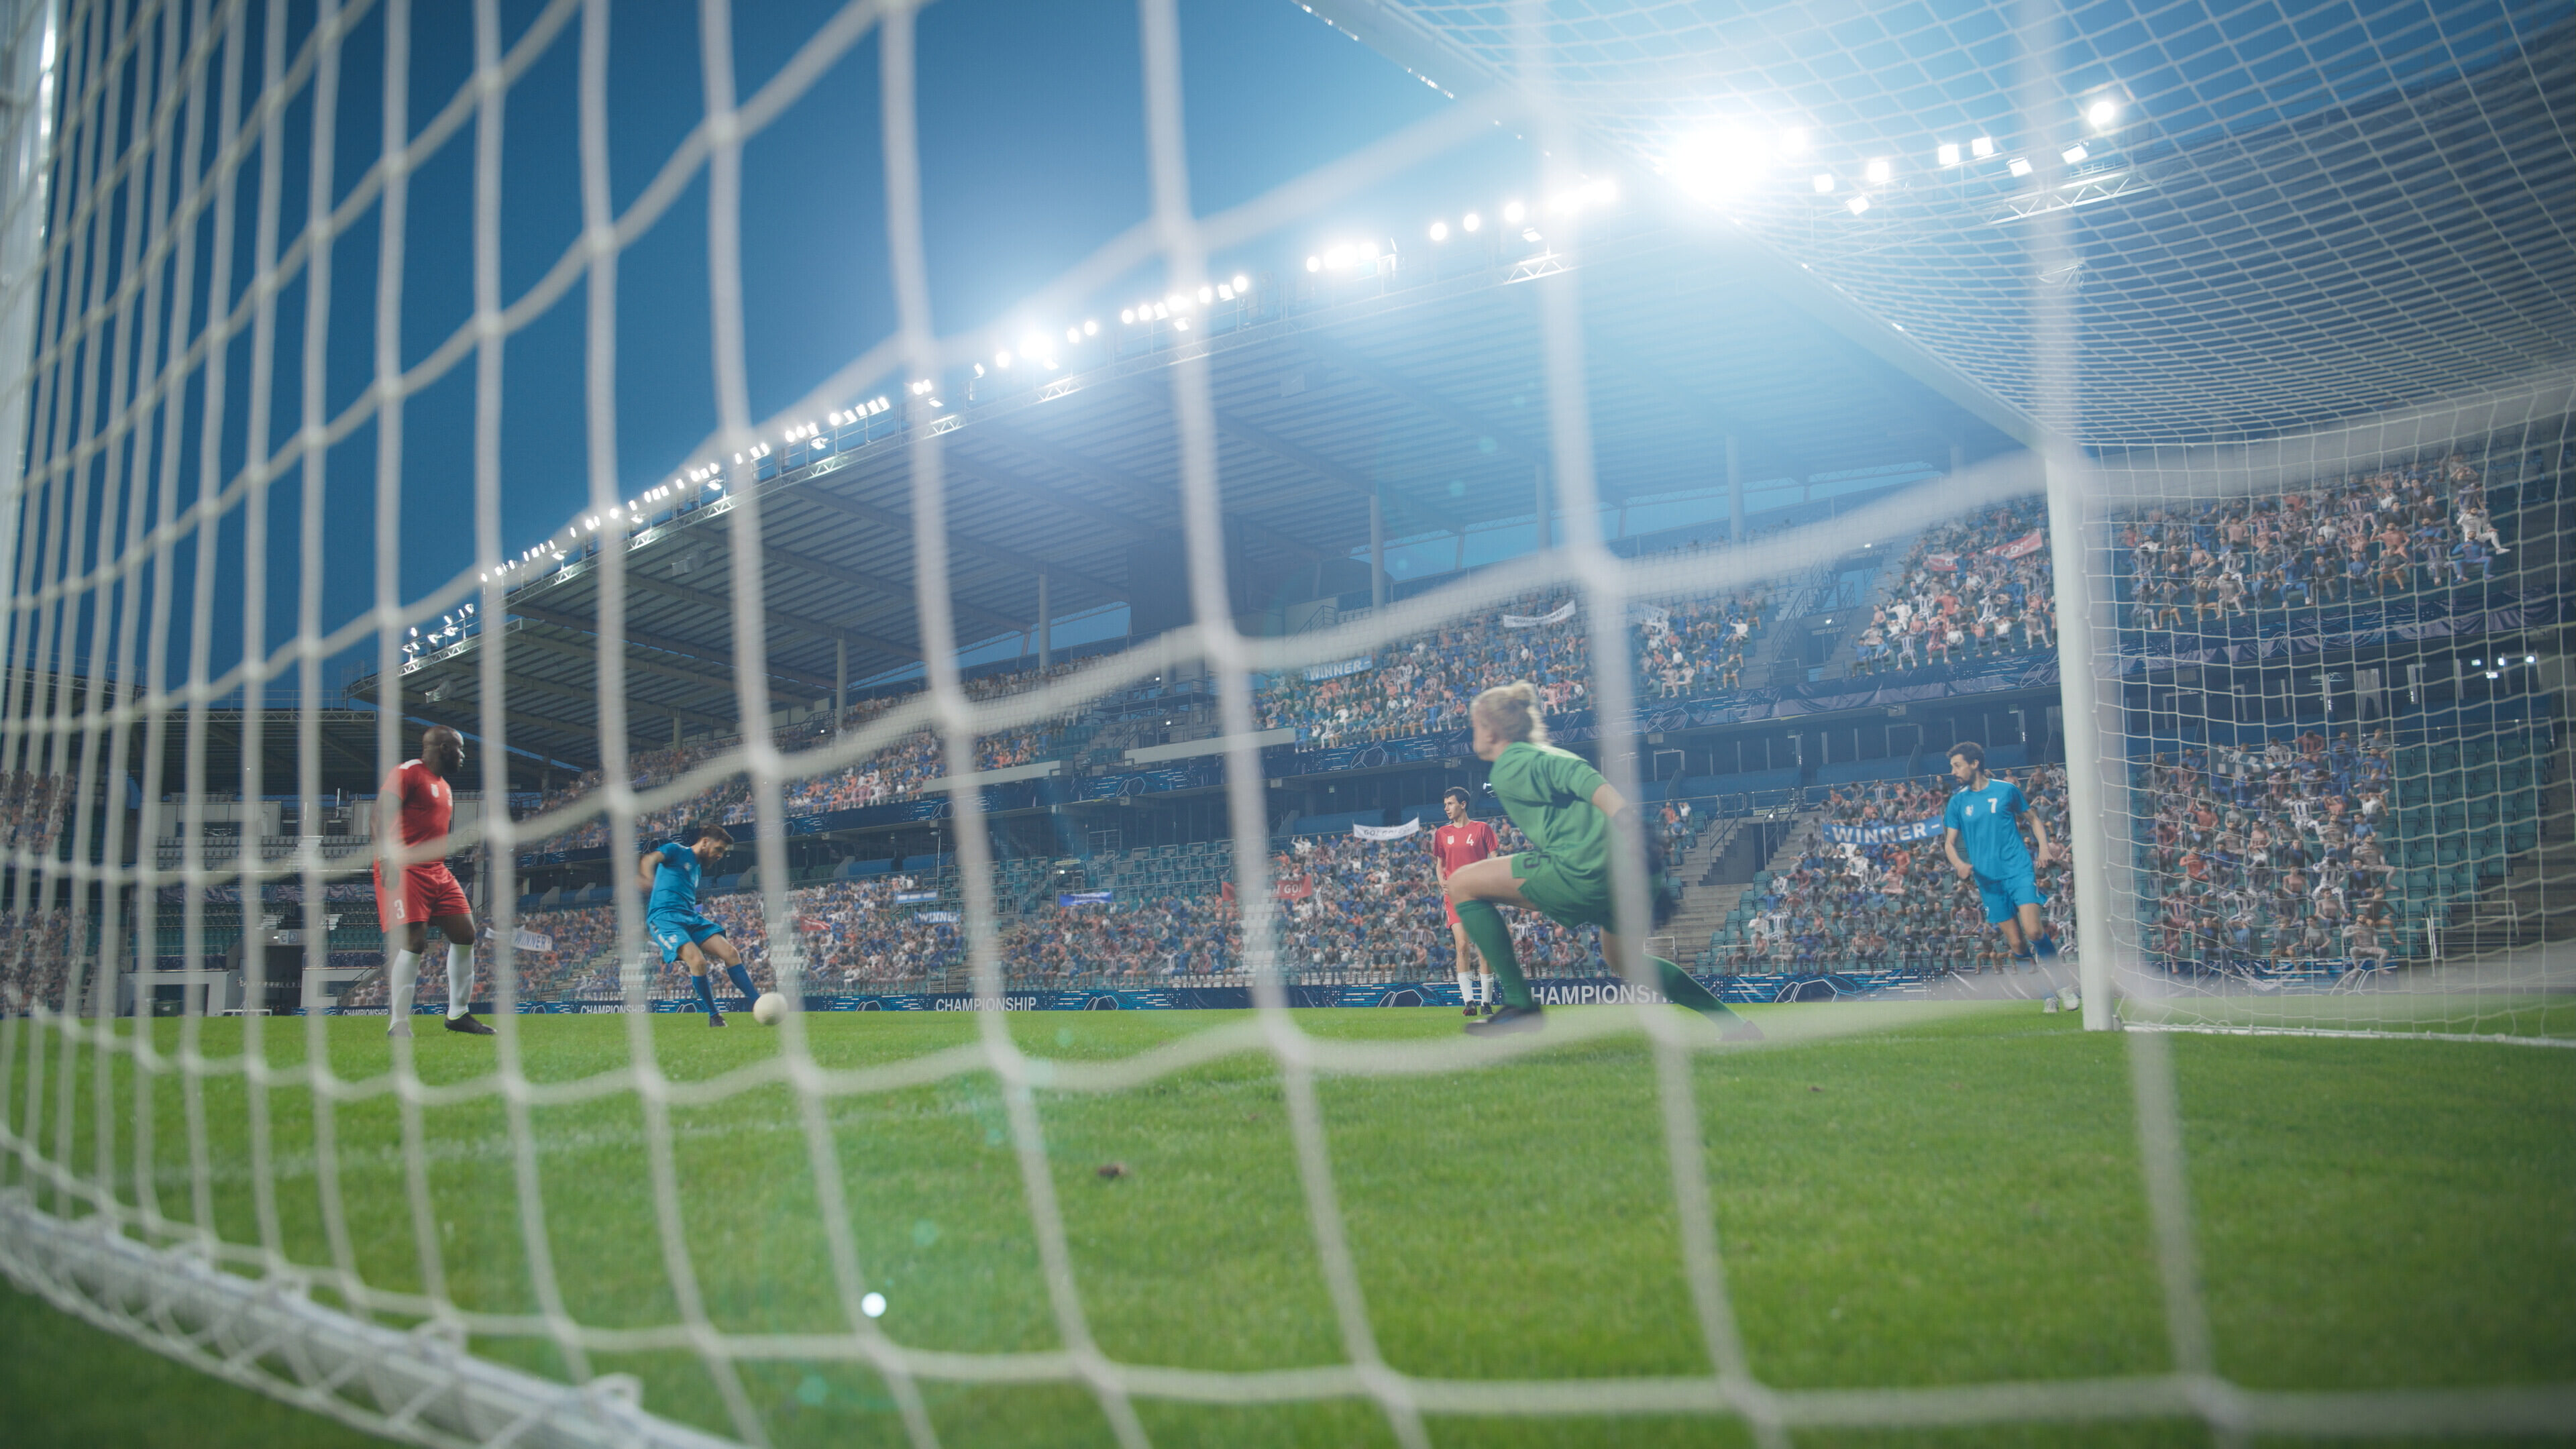
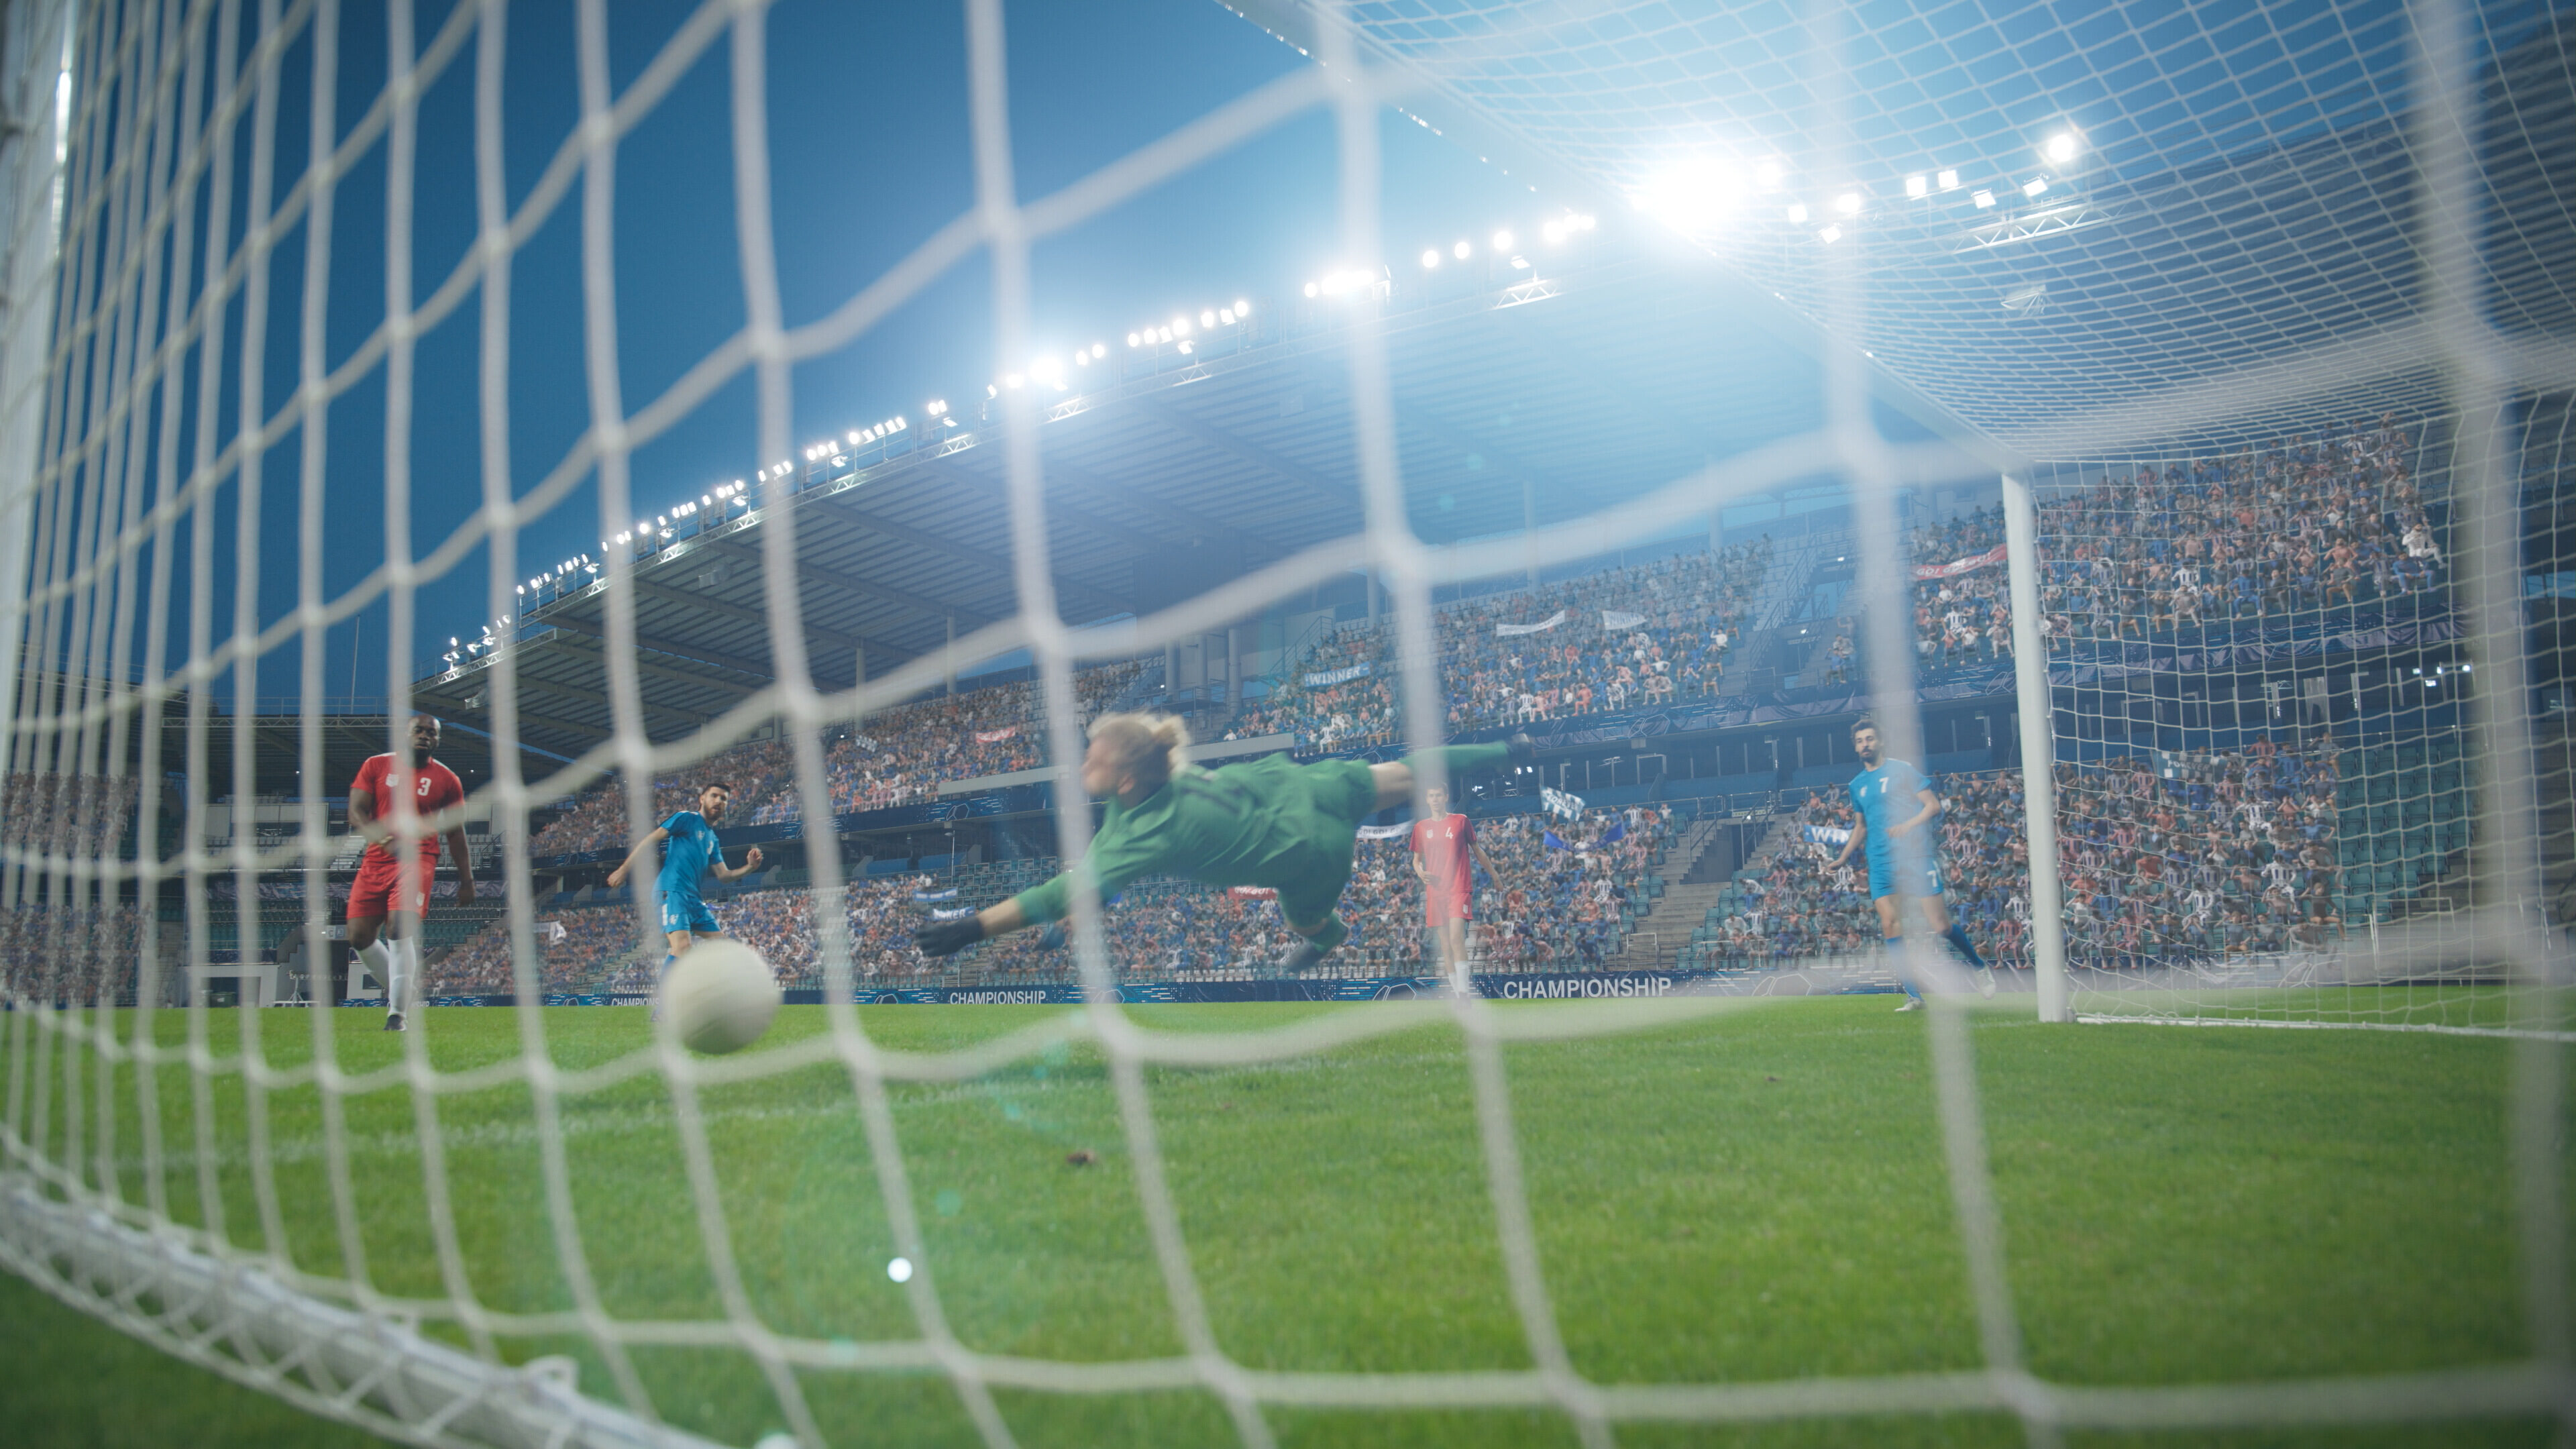
import os
from openai import OpenAI
import base64
import numpy as np
import soundfile as sf

client = OpenAI(
    # API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    # The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
)

# Base64 encoding format
def encode_image(image_path):
    with open(image_path, "rb") as image_file:
        return base64.b64encode(image_file.read()).decode("utf-8")

base64_image_1 = encode_image("football1.jpg")
base64_image_2 = encode_image("football2.jpg")
base64_image_3 = encode_image("football3.jpg")
base64_image_4 = encode_image("football4.jpg")

completion = client.chat.completions.create(
    model="qwen3.5-omni-plus", # For Qwen3-Omni-Flash, run in non-thinking mode.
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "video",
                    "video": [
                        f"data:image/jpeg;base64,{base64_image_1}",
                        f"data:image/jpeg;base64,{base64_image_2}",
                        f"data:image/jpeg;base64,{base64_image_3}",
                        f"data:image/jpeg;base64,{base64_image_4}",
                    ],
                },
                {"type": "text", "text": "Describe the process shown in this video"},
            ],
        }
    ],
    # Set the output modality. Two options are currently supported: ["text","audio"] and ["text"]
    modalities=["text", "audio"],
    audio={"voice": "Tina", "format": "wav"},
    # stream must be set to True, otherwise an error occurs.
    stream=True,
    stream_options={"include_usage": True},
)

for chunk in completion:
    if chunk.choices:
        print(chunk.choices[0].delta)
    else:
        print(chunk.usage)
import OpenAI from "openai";
import { readFileSync } from 'fs';

const openai = new OpenAI(
    {
        // API keys for the Singapore and Beijing regions are different. Get an API key: https://www.alibabacloud.com/help/en/model-studio/get-api-key
        apiKey: process.env.DASHSCOPE_API_KEY,
        // The following URL is for the Singapore region. When calling, replace {WorkspaceId} with your actual workspace ID. URLs vary by region.
        baseURL: "https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1"
    }
);

const encodeImage = (imagePath) => {
    const imageFile = readFileSync(imagePath);
    return imageFile.toString('base64');
  };
const base64Image1 = encodeImage("football1.jpg")
const base64Image2 = encodeImage("football2.jpg")
const base64Image3 = encodeImage("football3.jpg")
const base64Image4 = encodeImage("football4.jpg")

const completion = await openai.chat.completions.create({
    model: "qwen3.5-omni-plus", // For Qwen3-Omni-Flash, run in non-thinking mode.
    messages: [{
        role: "user",
        content: [
            {
                type: "video",
                video: [
                    `data:image/jpeg;base64,${base64Image1}`,
                    `data:image/jpeg;base64,${base64Image2}`,
                    `data:image/jpeg;base64,${base64Image3}`,
                    `data:image/jpeg;base64,${base64Image4}`
                ]
            },
            {
                type: "text",
                text: "Describe the process shown in this video"
            }
        ]
    }],
    stream: true,
    stream_options: {
        include_usage: true
    },
    modalities: ["text", "audio"],
    audio: { voice: "Tina", format: "wav" }
});

for await (const chunk of completion) {
    if (Array.isArray(chunk.choices) && chunk.choices.length > 0) {
        console.log(chunk.choices[0].delta);
    } else {
        console.log(chunk.usage);
    }
}
Référence de l'API
Pour consulter les paramètres d'entrée et de sortie, reportez-vous à Compatible OpenAI - Chat.
Facturation et limites de taux
Règles de facturationLa facturation de Qwen-Omni repose sur les tokens consommés selon les modalités (audio, image et vidéo). Consultez les détails de facturation dans la console.
Règles de conversion des tokens pour l'audio, les images et les vidéos
Audio
-
Qwen3.5-Omni series:- Formule pour l'audio en entrée :
Total tokens = Audio duration (seconds) * 7 - Formule pour l'audio en sortie :
Total tokens = Audio duration (seconds) * 12.5
- Formule pour l'audio en entrée :
-
Qwen3-Omni-Flash: Pour l'audio en entrée comme en sortie,Total tokens = Audio duration (seconds) * 12.5
Toute durée audio inférieure à 1 seconde est comptabilisée comme 1 seconde.
Images
Qwen3.5-Omni seriesetQwen3-Omni-Flash: 1 token pour32x32pixels
Pour la série Qwen3.5-Omni, chaque image nécessite au minimum 24 tokens ; pour les autres modèles, le minimum est de 4 tokens. Le maximum par défaut s'élève à 1 280 tokens. La série Qwen3.5-Omni prend en charge le paramètre vl_high_resolution_images afin de porter ce maximum à 16 384 tokens (Qwen3-Omni-Flash ne prennent pas en charge ce paramètre). Utilisez le code ci-dessous pour estimer le nombre de tokens d'une image unique :
import math
from PIL import Image  # pip install Pillow

# ============ Model configuration (modify as needed) ============

# Image factor: 32 for Qwen3.5-Omni series and Qwen3-Omni-Flash
IMAGE_FACTOR = 32

# Min tokens: 24 for Qwen3.5-Omni series; 4 for Qwen3-Omni-Flash
MIN_TOKENS = 24

# High-resolution mode (Qwen3.5-Omni series only; not supported by Qwen3-Omni-Flash)
# True  → max tokens = 16384
# False → max tokens = 1280 (default)
VL_HIGH_RESOLUTION_IMAGES = False

# ============ Pixel range (auto-calculated from above) ============

MIN_PIXELS = MIN_TOKENS * IMAGE_FACTOR * IMAGE_FACTOR
MAX_PIXELS = (16384 if VL_HIGH_RESOLUTION_IMAGES else 1280) * IMAGE_FACTOR * IMAGE_FACTOR

def smart_resize(height, width, factor=IMAGE_FACTOR,
                 min_pixels=MIN_PIXELS, max_pixels=MAX_PIXELS):
    """Align image dimensions to multiples of factor and scale to [min_pixels, max_pixels]."""
    h_bar = max(factor, round(height / factor) * factor)
    w_bar = max(factor, round(width / factor) * factor)

    if h_bar * w_bar > max_pixels:
        beta = math.sqrt((height * width) / max_pixels)
        h_bar = math.floor(height / beta / factor) * factor
        w_bar = math.floor(width / beta / factor) * factor
    elif h_bar * w_bar < min_pixels:
        beta = math.sqrt(min_pixels / (height * width))
        h_bar = math.ceil(height * beta / factor) * factor
        w_bar = math.ceil(width * beta / factor) * factor

    return h_bar, w_bar

if __name__ == "__main__":
    image = Image.open("xxx/test.jpg")
    print(f"Original size: {image.width}x{image.height}")

    resized_h, resized_w = smart_resize(image.height, image.width)
    token = int(resized_h * resized_w / (IMAGE_FACTOR * IMAGE_FACTOR)) + 2
    print(f"Resized: {resized_w}x{resized_h}, tokens: {token}")
Vidéo
Les tokens associés aux fichiers vidéo se répartissent en video_tokens et audio_tokens.
-
video_tokensLe calcul est complexe. Référez-vous au code suivant :
# pip install opencv-python import math import cv2 # ============ Model configuration (modify as needed) ============ # Image factor: 32 for Qwen3.5-Omni series and Qwen3-Omni-Flash IMAGE_FACTOR = 32 FRAME_FACTOR = 2 FPS = 2 MAX_RATIO = 200 # Min pixels per video frame VIDEO_MIN_PIXELS = 64 * IMAGE_FACTOR * IMAGE_FACTOR # Max pixels per video frame # Qwen3.5-Omni series: 640 * 32 * 32 # Qwen3-Omni-Flash: 768 * 32 * 32 VIDEO_MAX_PIXELS = 640 * IMAGE_FACTOR * IMAGE_FACTOR # Min extracted frames: 2 for Qwen3.5-Omni series and Qwen3-Omni-Flash FPS_MIN_FRAMES = 2 # Max extracted frames: 2048 for Qwen3.5-Omni series; 128 for Qwen3-Omni-Flash FPS_MAX_FRAMES = 2048 # Max total pixels for video input # Qwen3.5-Omni series: 180224 * 32 * 32 # Qwen3-Omni-Flash: 16384 * 32 * 32 VIDEO_TOTAL_PIXELS = 180224 * IMAGE_FACTOR * IMAGE_FACTOR # ============ Core functions ============ def get_video_info(video_path): """Read basic video info: height, width, total frames, fps.""" cap = cv2.VideoCapture(video_path) height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)) width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)) total_frames = int(cap.get(cv2.CAP_PROP_FRAME_COUNT)) fps = cap.get(cv2.CAP_PROP_FPS) cap.release() return height, width, total_frames, fps def smart_nframes(total_frames, video_fps): """Calculate the number of frames to extract based on video duration and fps.""" min_frames = math.ceil(FPS_MIN_FRAMES / FRAME_FACTOR) * FRAME_FACTOR max_frames = min(FPS_MAX_FRAMES, total_frames) // FRAME_FACTOR * FRAME_FACTOR duration = total_frames / video_fps if video_fps else 0 if duration - int(duration) > (1 / FPS): total_frames = math.ceil(duration * video_fps) else: total_frames = math.ceil(int(duration) * video_fps) nframes = total_frames / video_fps * FPS nframes = int(min(max(nframes, min_frames), max_frames, total_frames)) if not (FRAME_FACTOR <= nframes <= total_frames): raise ValueError(f"nframes should in [{FRAME_FACTOR}, {total_frames}], got {nframes}") return nframes def smart_resize(height, width, nframes, factor=IMAGE_FACTOR): """Scale video frames to a reasonable pixel range, aligning to multiples of factor.""" max_pixels = max( min(VIDEO_MAX_PIXELS, VIDEO_TOTAL_PIXELS / nframes * FRAME_FACTOR), int(VIDEO_MIN_PIXELS * 1.05) ) if max(height, width) / min(height, width) > MAX_RATIO: raise ValueError(f"aspect ratio exceeds {MAX_RATIO}") h_bar = max(factor, round(height / factor) * factor) w_bar = max(factor, round(width / factor) * factor) if h_bar * w_bar > max_pixels: beta = math.sqrt((height * width) / max_pixels) h_bar = math.floor(height / beta / factor) * factor w_bar = math.floor(width / beta / factor) * factor elif h_bar * w_bar < VIDEO_MIN_PIXELS: beta = math.sqrt(VIDEO_MIN_PIXELS / (height * width)) h_bar = math.ceil(height * beta / factor) * factor w_bar = math.ceil(width * beta / factor) * factor return h_bar, w_bar # ============ Calculate tokens ============ if __name__ == "__main__": video_path = "spring_mountain.mp4" height, width, total_frames, video_fps = get_video_info(video_path) print(f"Video info: {width}x{height}, {total_frames} frames, {video_fps:.1f} fps") nframes = smart_nframes(total_frames, video_fps) resized_h, resized_w = smart_resize(height, width, nframes) video_tokens = int( math.ceil(nframes / FPS) * resized_h / IMAGE_FACTOR * resized_w / IMAGE_FACTOR ) + 2 print(f"Extracted frames: {nframes}, resized: {resized_w}x{resized_h}, video_tokens: {video_tokens}") -
audio_tokens-
Qwen3.5-Omni series:- Audio en entrée :
Total tokens = Audio duration (seconds) * 7 - Audio en sortie :
Total tokens = Audio duration (seconds) * 12.5
- Audio en entrée :
-
Qwen3-Omni-Flash: Pour l'audio en entrée comme en sortie,Total tokens = Audio duration (seconds) * 12.5
Toute durée audio inférieure à 1 seconde est comptabilisée comme 1 seconde.
-
Pour réclamer, consulter ou utiliser votre quota gratuit, reportez-vous à Quota gratuit pour les nouveaux utilisateurs.
Limites de tauxPour connaître les règles de limitation de taux et consulter la FAQ, reportez-vous à Limitation de taux.
Codes d'erreur
Si l'appel du modèle échoue et renvoie un message d'erreur, consultez la rubrique Codes d'erreur pour obtenir une solution.
Liste des voix
Pour consulter la liste des voix disponibles pour le modèle Qwen-Omni, reportez-vous à la Liste des voix.