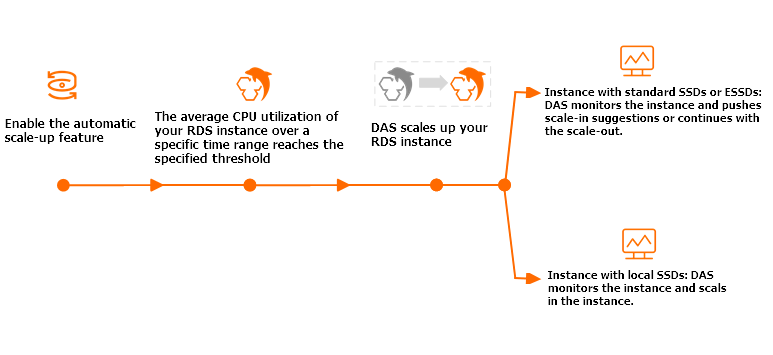
When business growth leads to increased database traffic and insufficient computing resources, scaling up the compute specifications, such as CPU and memory, of your database is an effective solution. Database Autonomy Service (DAS) lets you automatically scale the compute specifications of your database instances to quickly handle traffic peaks. When traffic subsides, DAS can also automatically scale down the specifications to prevent resource waste.
Features
Item | Cloud disk instance | Premium local disk instance |
Items to scale up |
|
Important If host resources are insufficient, which happens in less than 1% of cases, the scale-up does not occur. |
Automatic scale-down | The system automatically scales down the instance specifications in steps to the pre-scale-up specifications when both of the following conditions are met:
| During the scale-down observation window, if the CPU utilization is less than 30% for more than 99% of the time, the system automatically scales down the CPU and IOPS in steps to the pre-scale-up level. |
Availability impact | When the configuration change takes effect, a transient disconnection of up to 15 seconds may occur. Perform this operation during off-peak hours and ensure that your application has a connection retry mechanism. | No primary/secondary failover occurs. Note Automatic scaling operations complete within 30 seconds and are imperceptible to users. |
Prerequisites
The ApsaraDB RDS for MySQL instance meets the following requirements:
Billing method: subscription or pay-as-you-go. A Serverless instance scales automatically and requires no configuration.
Storage type: cloud disks (general-purpose or dedicated) or premium local disks (general-purpose).
Edition: High-Availability Edition
Category: Standard Edition
Region: The automatic performance scaling feature relies on anomaly detection. Therefore, the instance must be in a region that supports the DAS anomaly detection feature.
Your account balance is sufficient to cover the costs of the scale-up.
The automatic performance scaling feature does not support ApsaraDB RDS for MySQL instances that run on phased-out instance types and use cloud disks. To use this feature, first change the instance type to a current one.
Notes
Relationship between primary and read-only instances
DAS does not automatically apply the auto scaling settings of a primary instance to its read-only instances. You must manually configure auto scaling for read-only instances.
Scale-up operations are performed only on the primary instance. If a primary/secondary failover is triggered after the primary instance is scaled up:
If the new primary instance (the original secondary instance) meets the conditions for a scale-up or scale-down, the system automatically performs the corresponding adjustment.
If the new secondary instance (the original primary instance) meets the conditions for a scale-down, the system automatically scales it down to its original specifications.
Impact of configuration changes
When you change the configurations, the system upgrades the minor engine version of the instance to the latest version unless it is already running the latest version. This ensures optimal performance and stability.
To ensure that DAS can access the required cloud database resources, the system assigns the AliyunServiceRoleForDAS service-linked role to DAS after you enable the auto scaling feature.
Billing
Premium local disks (general-purpose): billed on a pay-as-you-go basis per hour.
Billing formula: (Price per core × Number of added CPU cores) × Duration of scale-up (in hours)
For example, consider an instance in the China (Hangzhou) region with 4 CPU cores. After an automatic performance scale-up is triggered, the number of cores increases to 8. The scale-up duration is 30 minutes (0.5 hours). The unit price in the China (Hangzhou) region is USD 0.083 per core-hour. The fee is calculated as follows: 0.083 (unit price) x 4 (added cores) x 0.5 (hours) = USD 0.166.
Cloud disks (general-purpose and dedicated): You are charged for the new instance specifications after a scale-up. The fees for the specification upgrade vary based on factors such as the region and the new specifications. For more information, visit the buy page.
Procedure
Cloud disks
Go to the RDS Instances page. In the top navigation bar, select the region where your RDS instance is located. Then, find the instance and click its ID.
In the Configuration Information section, click Settings next to Automatic Performance Scaling.
In the dialog box that appears, configure the parameters and click OK.
Parameter
Description
Automatic Performance Scaling
Turn on the switch to enable automatic performance scaling.
Observation Window
The period during which the system periodically checks the CPU utilization of the instance to determine whether to trigger a scale-up.
ImportantThe duration of the scale-down observation window is
observation window + 10 minutes. For example, if you set the Observation Window to 30 minutes, the scale-down observation window is 40 minutes.The automatic scale-down feature is guaranteed to run stably only on instances that use the new architecture (kindcode=18). You can call the DescribeDBInstanceAttribute operation to query the architecture version of your instance.
CPU Trigger Threshold
The CPU utilization threshold for triggering an automatic scale-up. An automatic scale-up is triggered when the average CPU utilization is greater than or equal to this threshold.
Maximum Specifications
The upper limit for automatic scale-up. The specifications you configure, including CPU and memory, must be higher than the current specifications of the instance. Otherwise, the setting does not take effect. The settings display the current instance specifications.
Cool-down Period
The minimum interval between two consecutive scaling events (either scale-up or scale-down).
NoteDuring the cooldown period, DAS continues to monitor the instance but does not trigger any scaling events.
If the cooldown period and the observation window end at the same time, and the CPU utilization reaches the trigger threshold within that observation window, DAS triggers a scaling event.
Automatic scale-down
The system automatically scales down the instance specifications in steps to the pre-scale-up specifications when both of the following conditions are met:
The instance is not in a Cool-down Period.
During the scale-down observation window (the
observation window + 10 minutes), the instance's CPU utilization is below 30% for more than 99% of the time.
Premium local disks
Go to the RDS Instances page. In the top navigation bar, select the region where your RDS instance is located. Then, find the instance and click its ID.
In the Configuration Information section, click Settings next to Automatic Performance Scaling.
In the dialog box that appears, configure the parameters and click OK.
Parameter
Description
Automatic Performance Scaling
Turn on the switch to enable automatic performance scaling.
Scale-up Observation Window
The period during which the system periodically checks the CPU utilization of the instance to determine whether to trigger a scale-up.
CPU Trigger Threshold
The CPU utilization threshold for triggering an automatic scale-up. An automatic scale-up is triggered when the average CPU utilization is greater than or equal to this threshold.
Scale-down Observation Window
The period during which the system monitors the CPU utilization of the instance to determine whether to trigger a scale-down. A scale-down is triggered if the CPU utilization remains below 30% for more than 99% of this window.