This article introduces the capabilities, supported models, and access methods of Qwen real-time speech/audio-video translation models. These models combine audio and image inputs for real-time translation and output text or speech in the target language, making them suitable for scenarios such as real-time speech communication and video translation.
For an online experience, see One-click deployment via FC.
Functions and features
- Multilingual support: Supports translation between 60 languages, among which 29 support audio + text output and 31 support text-only output, covering major languages such as Chinese, English, French, German, Russian, Japanese, Korean, Spanish, Portuguese, and Arabic.
- Visual enhancement: Uses visual content to improve translation accuracy. By analyzing lip movements, gestures, and on-screen text, the model improves translation quality in noisy environments or polysemous scenarios.
- 2.3-second latency: Achieves simultaneous interpretation latency as low as 2.3 seconds.
- Real-time speaker separation: Distinguishes different speakers and their utterances when multiple people take turns speaking, so listeners can clearly understand "who said what".
- Lossless simultaneous interpretation: Resolves cross-language word-order issues through semantic unit prediction. Real-time translation quality approaches offline translation results.
- Natural voice: Generates natural, human-like speech. The model adaptively adjusts tone and emotion based on the source speech content.
- Configure hotwords: Improves translation accuracy for specific terms through hotwords.
- Voice Cloning: Supports cloning a speaker's voice for translated playback, making the output sound like the speaker speaking a foreign language. Supports real-time cloning and pre-cloned fixed voices.
How to use
1. Configure the connection
Specify the supported model via model when connecting. The following connection example uses qwen3.8-livetranslate-flash-realtime.
When connecting via WebSocket, the following configuration items are required:
NoteYou can connect via the AOQ, WebRTC, and WebSocket protocols. For client-side integration where you prioritize stable latency, interaction capability on weak networks, and real-time full-duplex noise suppression and echo cancellation, consider AOQ first. For protocol comparison and selection, see the API reference.
| Configuration items | Description |
|---|---|
Endpoint | China (Beijing) region: Singapore region: When making calls, replace |
Query parameter | The query parameter is model, which must be set to the name of the model to access. Example: |
Headers | Use Bearer Token authentication: Authorization: Bearer DASHSCOPE_API_KEY
|
You can establish a connection with the following Python sample code.
# pip install websocket-client
import json
import websocket
import os

API_KEY=os.getenv("DASHSCOPE_API_KEY")
API_URL = "wss://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/api-ws/v1/realtime?model=qwen3.8-livetranslate-flash-realtime"

headers = [
    "Authorization: Bearer " + API_KEY
]

def on_open(ws):
    print(f"Connected to server: {API_URL}")
def on_message(ws, message):
    data = json.loads(message)
    print("Received event:", json.dumps(data, indent=2))
def on_error(ws, error):
    print("Error:", error)

ws = websocket.WebSocketApp(
    API_URL,
    header=headers,
    on_open=on_open,
    on_message=on_message,
    on_error=on_error
)

ws.run_forever()
2. Configure language, output modality, and voice
Configure the session via session.update:
-
Target language: Configured via
session.translation.language; for example,enindicates English. When usingqwen3.8-livetranslate-flash-realtime, the source language is automatically detected by the model.NoteWhen using
qwen3.5-livetranslate-flash-realtime, if you need to specify the source language, configure it viasession.input_audio_transcription.language; if omitted, it is automatically detected. -
Output modality: When using
qwen3.8-livetranslate-flash-realtime, configure it viasession.output_modalities;["text"]means text only, and["text", "audio"]means both text and audio (default).NoteWhen using
qwen3.5-livetranslate-flash-realtime, the output modality field issession.modalities, with the same available values and default value. -
Source speech recognition: When using
qwen3.8-livetranslate-flash-realtime, source speech recognition is always on and cannot be disabled. The source text is output directly by the simultaneous interpretation model, and relevant information in images can help the model resolve ambiguity. Receive recognition increments viaconversation.item.input_audio_transcription.delta, and the complete result viaconversation.item.input_audio_transcription.completed.NoteWhen using
qwen3.5-livetranslate-flash-realtime, source speech recognition is enabled by default. The source text is generated from the input audio by a separate ASR model. To adjust it, configuresession.input_audio_transcription.model:qwen3-asr-flash-realtimeenables it, andnulldisables it. Recognition increments are returned viaconversation.item.input_audio_transcription.text, and the complete result viaconversation.item.input_audio_transcription.completed. -
Audio and voice: When using
qwen3.8-livetranslate-flash-realtime, the default input is 16000 Hz PCM; the translated audio is output as PCM with a fixed sample rate of 24000 Hz, and the default voice isTina. You can also input Opus audio by settingsession.audio.input.format.typetoopus. You can view the voice viasession.audio.output.voicereturned by session.created. To preserve the speaker's voice, see Voice Cloning.NoteWhen using
qwen3.5-livetranslate-flash-realtime, configure audio viasession.sample_rate,session.input_audio_format, andsession.output_audio_format, and configure the voice viasession.voice; the default voice is alsoTina. -
Hotwords: Configure fixed translations via
session.translation.corpus.phrases. For more information, see Configure hotwords.NoteIt is recommended to keep the number of hotwords within 1000.
3. Input audio and images
The client sends Base64-encoded audio and image data via the input_audio_buffer.append and input_image_buffer.append events. Audio input is required; image input is optional.
To process images with qwen3.8-livetranslate-flash-realtime, first set session.input_modalities to ["audio", "video"] in session.update. If this field is omitted, the model processes only audio.
Images can come from local files or be captured in real time from a video stream.
When using qwen3.8-livetranslate-flash-realtime, the default is session.audio.input.turn_detection.type = speaker_detection: after audio is continuously sent, the server automatically detects the start and end of speech and generates translation responses, without requiring manual submission per sentence. For configuration methods and speaker identity handling, see Distinguish speakers.
qwen3.5-livetranslate-flash-realtime: VAD and Manual modes
How the model determines that an utterance is "finished" depends on the VAD mode or Manual mode configured by the turn_detection parameter:
- VAD mode (default): The client continuously sends input_audio_buffer.append events; when the server detects the start/end of speech, it returns the input_audio_buffer.speech_started and input_audio_buffer.speech_stopped events respectively, automatically commits the audio buffer, and triggers translation. Translation responses are generated synchronously with the streaming speech and usually begin while the speech is still being input, without waiting for the speech to end.
- Manual mode: Set
session.turn_detectiontonull. After the client finishes sending a complete utterance, it actively sends an input_audio_buffer.commit event to commit the audio buffer; once the server returns the input_audio_buffer.committed event as confirmation, it automatically starts generating the translation response, and the client does not need to send any other event to trigger the response. To clear uncommitted audio before committing, you can send an input_audio_buffer.clear event.
4. Receive model responses
When using qwen3.8-livetranslate-flash-realtime, receive responses according to the output modality:
- Text only: Append the
deltafield ofresponse.text.deltato the end of the subtitle in order, without overwriting the displayed text. - Text and audio: Accumulate the
deltafield ofresponse.audio_transcript.deltato obtain the translation, and Base64-decode thedeltafield ofresponse.audio.deltato obtain audio chunks.
Receiving response.done indicates the end of the current response. For event fields, see Server events.
qwen3.5-livetranslate-flash-realtime: Response event differences
-
Output source language recognition results
Configured via the
session.input_audio_transcription.modelparameter. When set toqwen3-asr-flash-realtime, the server returns the speech recognition results of the input audio (the source language text) along with the translation.Once enabled, the server returns the following events:
conversation.item.input_audio_transcription.text: Returns recognition results in a streaming manner.conversation.item.input_audio_transcription.completed: Returns the final result after recognition completes.conversation.item.input_audio_transcription.failed: Returns error information when recognition fails.
Translation responses are generated synchronously with the streaming speech, usually without waiting for the speech to end (see the VAD/Manual mode description in the previous section). The model's response format depends on the configured output modality.
-
Text output only
The server returns incremental translated text (including confirmed text and pending predicted text) in a streaming manner via the response.text.text event; after the translation completes, it returns the complete translated text via the response.text.done event.
stashis a temporary translation that allows subtitles to appear earlier, but it may be rewritten later. As needed, the client can display the concatenation oftextandstash, or display only the confirmedtext. Update the corresponding subtitle byitem_id, and display the complete translation after receivingresponse.text.done. -
Output text and audio
-
Text
Incremental translated text is returned as a stream via the response.audio_transcript.text event; after the translation is complete, the full translated text is returned via the response.audio_transcript.done event.
-
Audio
Base64-encoded incremental audio data is returned via the response.audio.delta event.
-
Text
Importantqwen3.5-livetranslate-flash-realtime uses the response.text.text event to return incremental text, which differs from the response.text.delta event used by full-duplex voice conversation (Omni) models — the two differ in field structure and semantics, so do not mix them up.
Associating the source text with the translation
When displaying the source text and the translation at the same time, you can establish the correspondence via the conversation.item.created event of the translation. Specifically, item.id is the translation ID, and the top-level previous_item_id of the event is the corresponding source text ID.
The arrival order of the source text and the translation is not fixed. Your application can first save the results separately, then pair them according to the relationship described above, and update the corresponding subtitles based on their respective item_id. For field descriptions, see Source text and translation association.
5. End the session
After all audio has been sent, the client must send the session.finish event to notify the server, and then wait for the server to return the session.finished event before closing the WebSocket connection.
ImportantIf session.finish is not sent, the server cannot know that the audio input is complete, which causes the recognition and translation results of the last segment of speech to be lost, and the connection may remain in a waiting state for a long time. Make sure to send this event before closing the connection.
Supported models
Featured models
| Model | Version | Context Length | Maximum input | Maximum output |
|---|---|---|---|---|
| (Token count) | ||||
| qwen3.8-livetranslate-flash-realtime | Stable version | 53248 | 49152 | 4096 |
qwen3.5-livetranslate-flash-realtime
| Stable version | 53248 | 49152 | 4096 |
qwen3.5-livetranslate-flash-realtime-2026-05-19 | Snapshot version | |||
QuickStart
Real-time translation of microphone input
-
Use Python 3.10 or later and install
pyaudio:macOS
brew install portaudio && pip install pyaudioDebian/Ubuntu
sudo apt-get install python3-pyaudioCentOS
sudo yum install -y portaudio portaudio-devel && pip install pyaudioWindows
pip install pyaudioInstall the WebSocket dependency:
pip install websocket-client. -
Set the environment variables below. The API Key and workspace must belong to the region used by the endpoint:
DASHSCOPE_API_KEY: The API Key for the corresponding region and workspace. For how to obtain one, see Obtain an API Key.
Fill in the
WorkspaceIdin the code below. -
Save the following code as
livetranslate_client.py, runpython livetranslate_client.py, and then speak into the microphone.
The example uses qwen3.8-livetranslate-flash-realtime to translate microphone input into English, printing the translation in real time and playing the translated audio. The input is 16000 Hz, mono, 16-bit PCM, and the translated audio played back is 24000 Hz, mono, 16-bit PCM. After you press Ctrl+C to stop recording, the example sends session.finish, continues to receive and play the remaining results, and closes the connection upon receiving session.finished. Using headphones is recommended to prevent the translated audio from re-entering the microphone.
import base64
import json
import os
import signal
import threading
import time

import pyaudio
import websocket

model = "qwen3.8-livetranslate-flash-realtime"
api_key = os.environ["DASHSCOPE_API_KEY"]
url = (
    "wss://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com"
    f"/api-ws/v1/realtime?model={model}"
)
stop_recording = False
send_errors = []
ws = None
audio = None
input_stream = None
output_stream = None
sender = None
previous_sigint_handler = None


def receive():
    event = json.loads(ws.recv())
    if event.get("type") == "error" or event.get("code"):
        raise RuntimeError(event)
    return event


def stop_input(signum, frame):
    global stop_recording
    stop_recording = True


def send_audio():
    try:
        while not stop_recording:
            chunk = input_stream.read(1600)
            ws.send(json.dumps({
                "type": "input_audio_buffer.append",
                "audio": base64.b64encode(chunk).decode("ascii"),
            }))
    except Exception as error:
        send_errors.append(error)
    finally:
        try:
            ws.send(json.dumps({"type": "session.finish"}))
        except Exception as error:
            send_errors.append(error)
            ws.close()


def receive_translation():
    while True:
        event = receive()
        event_type = event.get("type")
        if event_type in ("response.text.delta", "response.audio_transcript.delta"):
            print(event["delta"], end="", flush=True)
        elif event_type == "response.audio.delta":
            output_stream.write(base64.b64decode(event["delta"]))
        elif event_type == "response.done":
            if event["response"]["status"] != "completed":
                raise RuntimeError(event["response"])
            print()
        elif event_type == "session.finished":
            return


try:
    ws = websocket.create_connection(
        url, header={"Authorization": f"Bearer {api_key}"}, timeout=30
    )
    while receive().get("type") != "session.created":
        pass
    ws.send(json.dumps({
        "type": "session.update",
        "session": {
            "output_modalities": ["text", "audio"],
            "translation": {"language": "en"},
        },
    }))
    while receive().get("type") != "session.updated":
        pass
    audio = pyaudio.PyAudio()
    input_stream = audio.open(
        format=pyaudio.paInt16, channels=1, rate=16000,
        input=True, frames_per_buffer=1600,
    )
    output_stream = audio.open(
        format=pyaudio.paInt16, channels=1, rate=24000, output=True,
    )
    print("请开始说话;按 Ctrl+C 停止录音并等待剩余翻译。")
    previous_sigint_handler = signal.signal(signal.SIGINT, stop_input)
    sender = threading.Thread(target=send_audio, daemon=True)
    sender.start()
    receive_translation()
    stop_recording = True
    sender.join()
    if send_errors:
        raise send_errors[0]
except Exception:
    if send_errors:
        raise send_errors[0]
    raise
finally:
    stop_recording = True
    if ws is not None:
        ws.close()
    if sender is not None:
        sender.join()
    for stream in (input_stream, output_stream):
        if stream is not None:
            stream.stop_stream()
            stream.close()
    if audio is not None:
        audio.terminate()
    if previous_sigint_handler is not None:
        signal.signal(signal.SIGINT, previous_sigint_handler)
Configure hotwords
For translation scenarios that require a fixed rendering or disambiguation of homophones, adding hot words can improve translation accuracy. For example:
- Fixed rendering: The Alibaba Cloud slogan “Computing, for the value beyond computation.” (in Chinese) has this agreed English version, and its wording and word order must be preserved.
- Homophone brand name: Qoder is pronounced the same as the common word coder. If the speaker means the product Qoder, the translation must keep the brand spelling.
The following compares the outputs of two test groups. Each group uses the same audio, with only the hot word configuration changed.
| Input audio content | Without hot words | With hot words |
|---|---|---|
| Computing, for the value beyond computation. | Calculate. For values that cannot be calculated. | Computing, for the value beyond computation. |
| Qoder is an agentic platform for real-world work. | Coder is an agentic system designed for real-world work. platform. | Qoder, is an agentic platform designed for real-world work. |
Configuration
Hot words are configured through session.translation.corpus.phrases, which maps source-language words or phrases to target renderings in key-value form.
In the first session.update request of the QuickStart, merge the following translation object into the existing session, keeping the session's existing settings such as output modality and voice.
{
  "event_id": "configure-hotwords",
  "type": "session.update",
  "session": {
    "translation": {
      "language": "en",
      "corpus": {
        "phrases": {
          "计算,为了无法计算的价值。": "Computing, for the value beyond computation.",
          "Qoder": "Qoder"
        }
      }
    }
  }
}
Complete the configuration before sending audio. After receiving session.updated from the server, start sending input_audio_buffer.append.
Speaker diarization
qwen3.8-livetranslate-flash-realtime can identify different speakers, indicated by speaker_id. After the source text and translation are associated by this identifier, subtitles can be displayed by speaker.
Keep the default speaker_detection in session.update, or explicitly configure it as follows. threshold distinguishes silence from valid human voice; sounds below the threshold are filtered out and never fed into the model. This threshold is fixed at 0.5.
{
  "type": "session.update",
  "session": {
    "audio": {
      "input": {
        "turn_detection": {"type": "speaker_detection", "threshold": 0.5}
      }
    }
  }
}
After receiving the events, associate them in the following order:
- Get
speaker_idanditem_idfrominput_audio_buffer.speech_started, and record the speaker of the source message item. - Get the source text of the same
item_idfromconversation.item.input_audio_transcription.delta. - Get
item.idfrom the translation'sconversation.item.createdand the top-levelprevious_item_idof the event, and associate the translation message item with the source message item. - After receiving a translation delta, find the source text and speaker by its
item_id, then update the corresponding subtitle.
Place the following variables and functions in the microphone example of the QuickStart, before def receive_translation():. Inside that function, call handle_speaker_event(event) right after event = receive(), and replace the original print(event["delta"], end="", flush=True) with pass, letting the snippet below handle subtitle output in a unified way. Each time the source text or translation is updated, the snippet prints the speaker identifier, the source text, and the translation, making it easy to display subtitles by speaker. Keep the original audio processing and session-end logic.
speaker_by_source = {}
source_by_translation = {}
source_text = {}
translation_text = {}


def show_subtitle(translation_id):
    source_id = source_by_translation.get(translation_id)
    if source_id not in speaker_by_source or translation_id not in translation_text:
        return
    print({
        "speaker_id": speaker_by_source[source_id],
        "source": source_text.get(source_id, ""),
        "translation": translation_text[translation_id],
    })


def handle_speaker_event(event):
    event_type = event.get("type")
    if event_type in ("response.text.delta", "response.audio_transcript.delta"):
        item_id = event["item_id"]
        translation_text[item_id] = translation_text.get(item_id, "") + event["delta"]
        show_subtitle(item_id)
        return
    if event_type == "conversation.item.created":
        item = event["item"]
        if any(part.get("type") == "input_audio" for part in item.get("content", [])):
            return
        source_id = event.get("previous_item_id")
        if item.get("role") == "assistant" and source_id is not None:
            source_by_translation[item["id"]] = source_id
            show_subtitle(item["id"])
        return
    if event_type == "input_audio_buffer.speech_started" and "speaker_id" in event:
        source_id = event["item_id"]
        speaker_by_source[source_id] = event["speaker_id"]
    elif event_type == "conversation.item.input_audio_transcription.delta":
        source_id = event["item_id"]
        source_text[source_id] = source_text.get(source_id, "") + event["delta"]
    elif event_type == "conversation.item.input_audio_transcription.completed":
        source_id = event["item_id"]
        source_text[source_id] = event["transcript"]
    else:
        return
    for translation_id, mapped_source in source_by_translation.items():
        if mapped_source == source_id:
            show_subtitle(translation_id)
For field definitions, see Speaker identification and Source and translation association.
Improving translation accuracy with images
Qwen realtime translation models support image input to assist audio translation, which is useful for homophone disambiguation and recognition of low-frequency proper nouns. It is recommended to send no more than 2 images per second.
Download the following sample images to your local machine: face-mask.pngmask.png
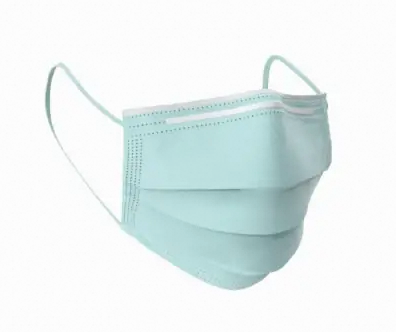
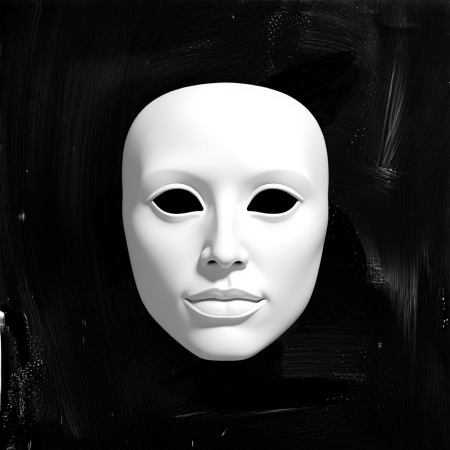
Reuse the microphone input and connection configuration from the QuickStart:
- Install the image processing dependency:
pip install Pillow. - In the
session.updaterequest of the microphone example, setsession.input_modalitiesto["audio", "video"]and changesession.translation.languagetozh. When running the example, sayWhat is mask?into the microphone. - Add the following image-reading code before
def send_audio():in the microphone example, and replace the original function with the newsend_audio(). The snippet uses the existinginput_stream,stop_recording,ws,send_errors, and imports.
import io
from PIL import Image

IMAGE_PATH = "口罩.png"
# IMAGE_PATH = "面具.png"
with Image.open(IMAGE_PATH) as image:
    buffer = io.BytesIO()
    image.convert("RGB").save(buffer, format="JPEG")
image_bytes = buffer.getvalue()
if len(image_bytes) > 500_000:
    raise ValueError("JPEG > 500 KB")
image_b64 = base64.b64encode(image_bytes).decode("ascii")


def send_audio():
    try:
        last_image_time = None
        while not stop_recording:
            chunk = input_stream.read(1600)
            ws.send(json.dumps({
                "type": "input_audio_buffer.append",
                "audio": base64.b64encode(chunk).decode("ascii"),
            }))
            now = time.monotonic()
            if last_image_time is None or now - last_image_time >= 0.5:
                ws.send(json.dumps({
                    "type": "input_image_buffer.append",
                    "image": image_b64,
                }))
                last_image_time = now
    except Exception as error:
        send_errors.append(error)
    finally:
        try:
            ws.send(json.dumps({"type": "session.finish"}))
        except Exception as error:
            send_errors.append(error)
            ws.close()
Images and audio are sent alternately, with at most one frame every 0.5 seconds. Use the face-mask and mask images separately, and check whether the word "mask" in the translation refers to the corresponding object; after pressing Ctrl+C to stop recording, the example requests to end the session and receives the remaining results.
Voice Cloning
The model supports speaker voice cloning: you can use a pre-cloned fixed voice, or clone in real time during translation, so the translated speech sounds like the speaker speaking a foreign language. It is suitable for cross-language speeches, individual streamers, video translation, and other scenarios that need to preserve the speaker's personal voice.
Real-time cloning: qwen3.8-livetranslate-flash-realtime and qwen3.5-livetranslate-flash-realtime clone the voice from the input audio during translation, with no additional cloning fee; model calls are still billed by token usage.
Create a voice in advance: Create a voice in advance through the Voice Cloning API, billed at $0.01 per voice; failed creations are not billed. For the regions, number of free quota uses, and validity period, see Billing Details. When translating with a created voice, you are still billed by token usage of model calls.
Set the following parameters in session.update to enable it:
-
session.enable_voice_clone: Set totrueto enable voice cloning. -
session.voice_clone_options.frequency: Controls when voice cloning occurs. Valid values are as follows:never: Use a pre-prepared fixed voice; the voice is not re-extracted during this translation session. In this case,session.voicemust be set to the user's own cloned voice ID.once: Extract the voice from the input audio once at the start of the session, and all subsequent translation outputs in this session reuse this voice. "Once" refers to the number of extractions, not that the translated audio is generated only once. Suitable for single-speaker scenarios. In this case,session.voicemust be set todefault.always: Re-extract the voice from the input audio each time translated audio is generated; when the speaker changes, the voice of the translated audio changes accordingly. Suitable for conversations with two or more speakers. In this case,session.voicemust be set todefault.
-
session.voice: Specifies the output voice; the value depends on thefrequencysetting.- Set to
default: Used withfrequencyset toonceoralways; clones the voice from the input audio, and uses the default voice as a transition until cloning completes. - Set to the user's cloned voice ID (for example,
qwen-translate-vc-xxx-yyy-zzz): Used withfrequencyset tonever. The voice must be prepared in advance through the Voice Cloning API, andtarget_modelmust be set to the translation model actually used.
- Set to
When
frequencyisonceoralways,voicemust be set todefaultand cannot be set to another preset voice; otherwise the server returns an error.
Voice Cloning configuration example
When using qwen3.8-livetranslate-flash-realtime, replace the corresponding session.update configuration into the model example in QuickStart.
NoteWhen using qwen3.5-livetranslate-flash-realtime, replace session.output_modalities in the example with session.modalities; the other cloning parameters are the same. When connecting, set model to this model and handle response events as described in Receiving model responses.
Use a pre-cloned voice (suitable for scenarios that require a fixed voice):
{
    "type": "session.update",
    "session": {
        "output_modalities": ["text","audio"],
        "voice": "qwen-translate-vc-xxx-yyy-zzz",
        "translation": {
            "language": "en"
        },
        "enable_voice_clone": true,
        "voice_clone_options": {
            "frequency": "never"
        }
    }
}
Reuse the same voice within the current session (suitable for a single speaker):
{
    "type": "session.update",
    "session": {
        "output_modalities": ["text","audio"],
        "voice": "default",
        "translation": {
            "language": "en"
        },
        "enable_voice_clone": true,
        "voice_clone_options": {
            "frequency": "once"
        }
    }
}
Let the translated voice follow the speaker (suitable for multi-person conversations):
{
    "type": "session.update",
    "session": {
        "output_modalities": ["text","audio"],
        "voice": "default",
        "translation": {
            "language": "en"
        },
        "enable_voice_clone": true,
        "voice_clone_options": {
            "frequency": "always"
        }
    }
}
One-click deployment through FC
The console does not currently support trying this feature. You can deploy it with one click in the following ways:
-
Open our ready-made FC template, fill in the API Key, and click Create and Deploy Default Environment to try it online.
-
Wait about one minute, obtain the access domain in Environment Details > Environment context, change
httpin the access domain tohttps(for example, https://qwen-livetranslate-flash-realtime-intl.fcv3.xxx.ap-southeast-1.fc.devsapp.net/), and interact with the model through this link.ImportantThis link uses a self-signed certificate and is for temporary testing only. On first access, the browser displays a security warning, which is expected behavior. Do not use it in a production environment. To continue, follow the browser prompts (for example, click "Advanced" → "Proceed (unsafe)").
To enable access control permissions, follow the on-page instructions.
View the project source code through Resource Information-Function Resources.
Both FC and Alibaba Cloud Model Studio offer free quotas for new users, which can cover the cost of simple debugging. After the quota is exhausted, you are billed based on usage. Fees are incurred only when it is accessed.
Interaction process
When using qwen3.8-livetranslate-flash-realtime, responses are generated by default through server-side sentence segmentation. The main interaction steps are as follows. For event fields, see Server events.
Phase | Client operations | Server events |
|---|---|---|
Create and configure the session | Establish the connection and send |
|
Input audio |
| The source text is returned incrementally via |
Receive the translation and audio | Continuously receive server events | The translation is returned via |
End the session |
| Close the connection after receiving |
qwen3.5-livetranslate-flash-realtime: Interaction process
The interaction process of real-time speech translation follows the standard WebSocket event-driven model. How the start and end of speech are determined depends on the VAD mode or Manual mode (see 3. Input audio and images). The following table uses VAD mode (default) as the main thread and marks the server events that differ in Manual mode.
| Lifecycle | Client events | Server events |
|---|---|---|
Session initialization | session.update
| session.created
session.updated
|
User audio input | input_audio_buffer.append
input_image_buffer.append
input_audio_buffer.commit
| VAD mode: input_audio_buffer.speech_started
input_audio_buffer.speech_stopped
Manual mode: input_audio_buffer.committed
|
Server audio output | None | response.created
response.output_item.added
conversation.item.created
response.content_part.added
response.text.text
response.audio_transcript.text
response.audio.delta
response.text.done
response.audio_transcript.done
response.audio.done
response.content_part.done
response.output_item.done
response.done
|
Session end | session.finish
| session.finished
|
ImportantAfter the audio transmission ends, you must send the session.finish event and wait for the session.finished response before disconnecting. If you close the WebSocket directly without sending session.finish, the server cannot know that the audio input has ended, and the recognition and translation results of the last segment of speech will be lost.
API Reference
For the process and examples of accessing via AOQ, see AOQ access. For protocol selection and reference entry points, see API reference.
Billing Details
-
Qwen3.8-LiveTranslate-Flash-Realtime、Qwen3.5-LiveTranslate-Flash-Realtime
-
Audio: Each second of input audio consumes 7 Tokens, and each second of output audio consumes 12.5 Tokens.
When server-side voice detection is used, billing is calculated based on the duration of the audio sent to the model after filtering, and the filtered silence is not counted toward this duration. You can view the actual audio input Token count in
response.usage.input_tokens_details.audio_tokensof theresponse.doneevent. -
Images: Every 32*32 pixels of input consumes 0.5 Tokens. For the Token unit price of each model, see Model invocation billing.
-
Real-time cloning: qwen3.8-livetranslate-flash-realtime and qwen3.5-livetranslate-flash-realtime clone the voice from the input audio during translation, with no additional cloning fee; model calls are still billed by token usage.
Create a voice in advance: Create a voice in advance through the Voice Cloning API, billed at $0.01 per voice; failed creations are not billed. For the regions, number of free quota uses, and validity period, see Billing Details. When translating with a created voice, you are still billed by token usage of model calls.
Rate limits
For the rate limiting rules of models, see Rate limits.
Supported languages
The language codes in the following table can be used to specify the source language and the target language.
Some target languages support text output only and do not support audio output.
Language code | Language | Supported output modalities |
|---|---|---|
zh | Chinese | Audio + text |
en | English | Audio + text |
ar | Arabic | Audio + text |
de | German | Audio + text |
fr | French | Audio + text |
es | Spanish | Audio + text |
pt | Portuguese | Audio + text |
id | Indonesian | Audio + text |
it | Italian | Audio + text |
ko | Korean | Audio + text |
ru | Russian | Audio + text |
th | Thai | Audio + text |
vi | Vietnamese | Audio + text |
ja | Japanese | Audio + text |
tr | Turkish | Audio + text |
hi | Hindi | Audio + text |
ms | Malay | Audio + text |
nl | Dutch | Audio + text |
ur | Urdu | Audio + text |
nb | Norwegian | Audio + text |
sv | Swedish | Audio + text |
da | Danish | Audio + text |
he | Hebrew | Audio + text |
fi | Finnish | Audio + text |
pl | Polish | Audio + text |
is | Icelandic | Audio + text |
cs | Czech | Audio + text |
fil | Filipino | Audio + text |
fa | Persian | Audio + text |
yue | Cantonese | Text |
el | Greek | Text |
af | Afrikaans | Text |
ast | Asturian | Text |
be | Belarusian | Text |
bg | Bulgarian | Text |
bn | Bengali | Text |
bs | Bosnian | Text |
ca | Catalan | Text |
ceb | Cebuano | Text |
et | Estonian | Text |
gl | Galician | Text |
gu | Gujarati | Text |
hr | Croatian | Text |
hu | Hungarian | Text |
jv | Javanese | Text |
kk | Kazakh | Text |
kn | Kannada | Text |
ky | Kyrgyz | Text |
lv | Latvian | Text |
mk | Macedonian | Text |
ml | Malayalam | Text |
mr | Marathi | Text |
pa | Punjabi | Text |
ro | Romanian | Text |
sk | Slovak | Text |
sl | Slovenian | Text |
sw | Swahili | Text |
tg | Tajik | Text |
az | Azerbaijani | Text |
uk | Ukrainian | Text |
Supported voices
For the voices supported by realtime translation and the values of the voice parameter, see Voice list.
FAQ
Am I billed even if I stay connected without speaking?
Maintaining a connection itself is not billed. Whether uploaded silence counts toward audio input usage depends on the mode you use:
- Server-side voice detection: Silence filtered out by the server does not count toward audio input usage.
- Manual mode: Silence manually submitted by the client counts toward audio input usage.
The number of audio input tokens is recorded in the response.done event, at the field path response → usage → input_tokens_details → audio_tokens. The model is billed by input and output tokens; for unit prices and metering rules, see Billing details.
How do I migrate from the Gummy model to Livetranslate?
gummy-realtime-v1 and qwen3.8-livetranslate-flash-realtime use different protocols; simply changing the model name does not complete the migration. The following example uses the Python SDK to output English subtitles. Existing 16 kHz mono, 16-bit PCM recordings can be used directly.
Stage | Gummy | LiveTranslate |
|---|---|---|
Connect and configure |
|
Start sending audio after receiving |
Send audio |
|
|
Display the translation |
|
Read events while sending audio, and append each |
End the session |
|
After the last subtitle is received, wait for |
Python example: translating a recording into English subtitles
Set DASHSCOPE_API_KEY to an API Key from the Beijing region, and set DASHSCOPE_WORKSPACE to the ID of the same workspace. Save the example as subtitles.py, save the recording as input.wav, and then run:
python -m pip install dashscope==2.0.2
python subtitles.py input.wav
import os
import sys
import time
import wave
from concurrent.futures import ThreadPoolExecutor

import dashscope


def send_audio(session, recording):
    while chunk := recording.readframes(1600):
        session.append_audio(chunk)
        time.sleep(len(chunk) / 32000)
    session.end_session()


def translate(path):
    client = dashscope.Client(api_key=os.environ["DASHSCOPE_API_KEY"],
                              workspace=os.environ["DASHSCOPE_WORKSPACE"],
                              region="cn-beijing")
    with wave.open(path, "rb") as recording:
        if (recording.getframerate(), recording.getnchannels(), recording.getsampwidth()) != (16000, 1, 2):
            raise ValueError("需要 16 kHz、单声道、16 位 PCM WAV 文件")
        with client.audio.realtime.connect(model="qwen3.8-livetranslate-flash-realtime", timeout=30) as session:
            events = session.events()
            for event in events:
                if event["type"] == "session.created":
                    session.update_session(output_modalities=["text"], translation_params={"language": "en"})
                elif event["type"] == "session.updated":
                    break
                elif event["type"] == "error":
                    raise RuntimeError(event["error"])
            else:
                raise RuntimeError("会话在配置完成前关闭")

            with ThreadPoolExecutor(max_workers=1) as pool:
                sender = pool.submit(send_audio, session, recording)
                try:
                    for event in events:
                        kind = event["type"]
                        if kind == "response.text.delta":
                            print(event["delta"], end="", flush=True)
                        elif kind == "response.text.done":
                            print(flush=True)
                        elif kind == "response.done" and event["response"]["status"] != "completed":
                            raise RuntimeError(event["response"].get("status_details"))
                        elif kind == "error":
                            raise RuntimeError(event["error"])
                        elif kind == "session.finished":
                            break
                    else:
                        raise RuntimeError("未收到 session.finished")
                except BaseException:
                    session.close()
                    raise
                sender.result()


if __name__ == "__main__":
    translate(sys.argv[1])
Use WebSocket directly
- Connection endpoint Gummy uses
/api-ws/v1/inference. LiveTranslate uses/api-ws/v1/realtime?model=qwen3.8-livetranslate-flash-realtime. - Send audio With Gummy, send binary frames directly. With LiveTranslate, encode PCM as Base64 and put it in the
audiofield of theinput_audio_buffer.appendevent. - Receive translations With Gummy, read translations from
result-generated. With LiveTranslate, readdeltafromresponse.text.deltaand append each segment to the end of the subtitles.
Send session.finish after all audio has been sent, and close the connection after receiving session.finished. Full example
What does RPM limit? Does it limit the total number of simultaneously open connections?
RPM limits the number of WebSocket connection requests per minute. Multiple rounds of responses within the same connection are not counted repeatedly; reconnections count as new requests. Currently, there is no separate limit on the total number of simultaneously open connections.
When establishing a connection, if the WebSocket is closed with 1007 and the reason is Requests rate limit exceeded, please try again later., it indicates that request rate limiting has been triggered. Reduce the connection frequency and reconnect with exponential backoff.
How do I resume translation after an interruption?
When you receive no semantic result after merged audio exceeded 60s and the WebSocket connection is closed, you need to create a new session to continue the translation:
- Stop sending audio to the old connection.
- Re-establish the connection, send
session.update, and restore the configuration such as the target language and output modality. - After receiving
session.updated, continue sending audio.
If a parameter error occurs and the connection is not closed, you can correct the request and continue using the original connection. When using dashscope.Client(), you also need to resume event receiving.