Creates a materialized view that supports clustering or partitioning based on the data for materialized view scenarios.
Background
A view is a virtual table defined by a query. A materialized view, by contrast, is a physical table that stores pre-computed query results and consumes storage resources. For billing details, see Billing rules.
Materialized views are suitable for the following scenarios:
Frequently executed queries with a fixed pattern.
Queries that involve time-consuming operations, such as aggregations and joins.
Queries that access only a small subset of data in a table.
The following table compares traditional queries with materialized view queries.
Item | Traditional query | Materialized view query |
Query statement | You query data directly by using SQL statements. | Create a materialized view and then query it. The following statement creates a materialized view: Query the materialized view: If query rewrite is enabled for the materialized view, the system automatically uses the materialized view when you run the following query: |
Query characteristics | The query reads tables, performs joins, and applies filters (WHERE clause). For large source tables, these operations are slow and resource-intensive. | The query reads the materialized view and applies filters. No joins are needed. MaxCompute automatically matches the query to the optimal materialized view and reads data directly from it, which significantly improves query performance. |
Billing rules
Materialized view costs consist of two components:
Storage fees
Materialized views consume physical storage, incurring storage fees on a pay-as-you-go basis. For more information, see Storage pricing (pay-as-you-go).
Computing costs
Creating, updating, and querying a materialized view — including query rewrites when the view is valid — consume computing resources and incur computing costs.
If your MaxCompute project is on a subscription plan, no separate fees are charged.
If your MaxCompute project is on a pay-as-you-go plan, MaxCompute calculates costs based on SQL complexity and input data volume. For more information, see Standard SQL pricing. Note the following:
The SQL statement used to refresh a materialized view is the same as its defining query. If the project is bound to a subscription computing resource group, the operation uses your purchased resources at no extra cost. If the project uses a pay-as-you-go resource group, the cost depends on input data volume and SQL complexity. After a refresh, storage fees are charged based on the actual size of the materialized view.
When a materialized view is valid, query rewrite reads data from the view. The input data volume depends on the materialized view, not the source table. If the view is invalid, query rewrite is unavailable and queries read from the source table directly. For more information, see Query materialized view status.
When a materialized view is built from multi-table joins, data bloat can occur. Reading from the materialized view does not always reduce costs compared to reading from the source tables.
Limitations
Window functions, user-defined table-valued functions (UDTFs), and non-deterministic functions such as user-defined scalar functions (UDFs) and user-defined aggregate functions (UDAFs) are not supported.
If you must use a non-deterministic function, set this session-level property: set odps.sql.materialized.view.support.nondeterministic.function=true;.
Precautions
If the query statement based on which you create a materialized view fails to be executed, you cannot create the materialized view.
Partition key columns in a materialized view must be derived from a source table. The sequence and number of the columns in the materialized view must be the same as the sequence and number of the columns in the source table. Column names can be different.
You must specify comments for all columns, including partition key columns. If you specify comments only for some columns, an error is returned.
You can specify both the partitioning and clustering attributes for a materialized view. In this case, the data in each partition has the specified clustering attribute.
If the query statement based on which you create a materialized view contains operators that are not supported by the materialized view, an error is returned. For more information about the operators that are supported by materialized views, see Perform a query rewrite operation based on a materialized view.
By default, MaxCompute does not allow you to create materialized views by using non-deterministic functions, such as UDFs or UDAFs. If you must use non-deterministic functions based on your business requirements, run the
set odps.sql.materialized.view.support.nondeterministic.function=true;command at the session level.If the source table of a materialized view contains an empty partition, you can refresh the materialized view to generate an empty partition in the materialized view.
Syntax
CREATE MATERIALIZED VIEW [IF NOT EXISTS] [project_name.]<mv_name>
[LIFECYCLE <days>]    --Specifies the lifecycle.
[BUILD DEFERRED]    --Creates the schema without populating data.
[(<col_name> [COMMENT <col_comment>], ...)]    --Column comments.
[DISABLE REWRITE]    --Specifies whether the materialized view can be used for query rewrite.
[COMMENT 'table comment']    --Table comment.
[PARTITIONED BY (<col_name> [, <col_name>, ...])]    --Creates the materialized view as a partitioned table.
[CLUSTERED BY | RANGE CLUSTERED BY (<col_name> [, <col_name>, ...])
  [SORTED BY (<col_name> [ASC | DESC] [, <col_name> [ASC | DESC] ...])]
    INTO <number_of_buckets> BUCKETS]    --Sets the shuffle and sort properties for a clustered table.
[REFRESH EVERY <num> {MINUTES | HOURS | DAYS}]
[TBLPROPERTIES("compressionstrategy"="{normal|high|extreme}",    --Specifies the data storage compression strategy for the table.
                "enable_auto_substitute"="true",    --Specifies whether to enable query passthrough to the source table when a partition does not exist.
                "enable_auto_refresh"="true",    --Specifies whether to enable automatic refresh.
                "refresh_interval_minutes"="120",    --Specifies the refresh interval.
                "only_refresh_max_pt"="true"    --For partitioned materialized views, automatically refreshes only the latest partition from the source table.
                )]
AS <select_statement>;
Parameters
Parameter | Required | Description |
IF NOT EXISTS | No | If you do not specify IF NOT EXISTS and the materialized view already exists, the operation fails with an error. |
project_name | No | The name of the MaxCompute project for the materialized view. If you omit this parameter, the current project is used.
|
mv_name | Yes | The name of the materialized view. |
days | No | The lifecycle of the materialized view in days. The value must be an integer from 1 to 37231. |
BUILD DEFERRED | No | If specified, creates the materialized view's schema without populating it with data. |
col_name | No | The name of a column in the materialized view. |
col_comment | No | The comment for a column. |
DISABLE REWRITE | No | Disables query rewrite for the materialized view. By default, query rewrite is enabled. You can run |
PARTITIONED BY | No | The partition key columns. Use this parameter to create a partitioned materialized view. |
CLUSTERED BY|RANGE CLUSTERED BY | No | The shuffle property for creating a clustered table. |
SORTED BY | No | The sort property for creating a clustered table. |
REFRESH EVERY | No | The scheduled refresh interval for the materialized view. Valid units are MINUTES, HOURS, or DAYS. |
number_of_buckets | No | The number of buckets when creating a clustered table. |
TBLPROPERTIES | No |
|
select_statement | Yes | The SELECT statement that defines the materialized view. For more information, see SELECT Syntax. |
Examples
Create a materialized view
Create tables named
mf_tandmf_t1and insert data into the tables.CREATE TABLE IF NOT EXISTS mf_t( id bigint, value bigint, name string) PARTITIONED BY (ds STRING); ALTER TABLE mf_t ADD PARTITION (ds='1'); INSERT INTO mf_t PARTITION (ds='1') VALUES (1,10,'kyle'),(2,20,'xia'); SELECT * FROM mf_t WHERE ds ='1'; -- The following result is returned. +------------+------------+------------+------------+ | id | value | name | ds | +------------+------------+------------+------------+ | 1 | 10 | kyle | 1 | | 2 | 20 | xia | 1 | +------------+------------+------------+------------+ CREATE TABLE IF NOT EXISTS mf_t1( id bigint, value bigint, name string) PARTITIONED BY (ds STRING); ALTER TABLE mf_t1 ADD PARTITION (ds='1'); INSERT INTO mf_t1 PARTITION (ds='1') VALUES (1,10,'kyle'),(3,20,'john'); SELECT * FROM mf_t1 WHERE ds ='1'; -- The following result is returned. +------------+------------+------------+------------+ | id | value | name | ds | +------------+------------+------------+------------+ | 1 | 10 | kyle | 1 | | 3 | 20 | john | 1 | +------------+------------+------------+------------+Create a materialized view.
Sample 1: Create a materialized view that contains a partition key column named ds.
CREATE MATERIALIZED VIEW mf_mv LIFECYCLE 7
(
  key comment 'unique id',
  value comment 'input value',
  ds comment 'partition'
  )
PARTITIONED BY (ds)
AS SELECT t1.id AS key, t1.value AS value, t1.ds AS ds
     FROM mf_t AS t1 JOIN mf_t1 AS t2
       ON t1.id = t2.id AND t1.ds=t2.ds AND t1.ds='1';
--Query the materialized view.
SELECT * FROM mf_mv WHERE ds =1;
+------------+------------+------------+
| key        | value      | ds         |
+------------+------------+------------+
| 1          | 10         | 1          |
+------------+------------+------------+
Sample 2: Create a non-partitioned materialized view that is clustered.
CREATE MATERIALIZED VIEW mf_mv2 LIFECYCLE 7
CLUSTERED BY (key) SORTED BY (value) INTO 1024 buckets
AS  SELECT t1.id AS key, t1.value AS value, t1.ds AS ds
      FROM mf_t AS t1 JOIN mf_t1 AS t2
        ON t1.id = t2.id AND t1.ds=t2.ds AND t1.ds='1';
Sample 3: Create a partitioned materialized view that is clustered.
CREATE MATERIALIZED VIEW mf_mv3 LIFECYCLE 7
PARTITIONED BY (ds)
CLUSTERED BY (key) SORTED BY (value) INTO 1024 buckets
AS  SELECT t1.id AS key, t1.value AS value, t1.ds AS ds
      FROM mf_t AS t1 JOIN mf_t1 AS t2
        ON t1.id = t2.id AND t1.ds=t2.ds AND t1.ds='1';
Implement query rewrite based on a materialized view
Scenario
Consider a page visit table named
visit_recordsthat logs the page ID, user ID, and visit time for each visit. A frequent analysis task is to count the number of visits for different pages.In this situation, you can create a materialized view on
visit_recordsthat groups by page ID and counts the visits for each page. You can then run subsequent queries against this materialized view.The structure of
visit_recordsis as follows:+------------------------------------------------------------------------------------+ | Field | Type | Label | Comment | +------------------------------------------------------------------------------------+ | page_id | string | | | | user_id | string | | | | visit_time | string | | | +------------------------------------------------------------------------------------+Create a materialized view.
-- Create a materialized view for the visit_records table that groups by page ID and counts the visits for each page.

CREATE MATERIALIZED VIEW count_mv AS SELECT page_id, count(*) FROM visit_records GROUP BY page_id;
Run the following query:
SET odps.sql.materialized.view.enable.auto.rewriting=true;
SELECT page_id, count(*) FROM visit_records GROUP BY page_id;
When this query statement is executed, MaxCompute automatically matches the materialized view
count_mvand reads the pre-aggregated data fromcount_mv.To verify that the query was rewritten using the materialized view, run the following
EXPLAINcommand:EXPLAIN SELECT page_id, count(*) FROM visit_records GROUP BY page_id;The following result is returned:
job0 is root job

In Job job0:
root Tasks: M1

In Task M1:
    Data source: doc_test_dev.count_mv
    TS: doc_test_dev.count_mv
        FS: output: Screen
            schema:
              page_id (string)
              _c1 (bigint)


OK
The
Data sourcein the returned result shows that the table read by the query is thedoc_test_devproject'scount_mv. This indicates that the materialized view is effective and the query rewrite was successful.
Perform a query rewrite operation based on a materialized view
The most important feature of materialized views is to perform query rewrite operations on query statements. To perform query rewrite operations on a query statement based on a materialized view, you must add set odps.sql.materialized.view.enable.auto.rewriting=true; before the query statement. If a materialized view is invalid, the materialized view cannot be used for query rewrite operations. In this case, data is queried from the source table, and the query speed is not accelerated.
By default, a MaxCompute project can use only its own materialized views for query rewrite operations. If you need to perform query rewrite operations on query statements based on the materialized views of other MaxCompute projects, you must add set odps.sql.materialized.view.source.project.white.list=<project_name1>,<project_name2>,<project_name3>; before the query statements to specify the MaxCompute projects.
The following table compares the query rewrite operator types supported by MaxCompute with those of other products.
Operator type | Classification | MaxCompute | BigQuery | Amazon Redshift | Hive |
FILTER | Full expression match | Supported | Supported | Supported | Supported |
Partial expression match | Supported | Supported | Supported | Supported | |
AGGREGATE | Single AGGREGATE | Supported | Supported | Supported | Supported |
Multiple AGGREGATEs | Not supported | Not supported | Not supported | Not supported | |
JOIN | JOIN type | INNER JOIN | Not supported | INNER JOIN | INNER JOIN |
Single JOIN | Supported | Not supported | Supported | Supported | |
Multiple JOINs | Supported | Not supported | Supported | Supported | |
AGGREGATE+JOIN | - | Supported | Not supported | Supported | Supported |
The query rewrite operations based on a materialized view require that the data in a query statement be obtained from the materialized view. The data includes output columns, the columns required by filter operations, the columns required by aggregate functions, and the columns required by JOIN operations. If the columns that are required in the query statement are not included in the materialized view or are not supported by the aggregate functions, you cannot perform query rewrite operations based on the materialized view.
Example 1: Rewrite with filter conditions
Create a materialized view.
CREATE MATERIALIZED VIEW mv AS SELECT a,b,c FROM src WHERE a>5;The following table provides rewrite examples for the materialized view.
Original query
Rewritten query
SELECT a,b FROM src WHERE a>5;SELECT a,b FROM mv;SELECT a, b FROM src WHERE a=10;SELECT a,b FROM mv WHERE a=10;SELECT a, b FROM src WHERE a=10 AND b='3';SELECT a,b FROM mv WHERE a=10 AND b=3;SELECT a, b FROM src WHERE a>3;(SELECT a,b FROM src WHERE a>3 AND a<=5) UNION (SELECT a,b FROM mv);SELECT a, b FROM src WHERE a=10 AND d=4;Rewrite fails because the materialized view does not contain the column
d.SELECT d, e FROM src WHERE a=10;Rewrite fails because the materialized view does not contain the columns
dande.SELECT a, b FROM src WHERE a=1;Rewrite fails because the materialized view does not contain data where
a=1.
Example 2: Rewrite with aggregate functions
All aggregate functions can be rewritten if the materialized view and the query share the same aggregation key. If the aggregation keys differ, only rewrites using SUM, MIN, and MAX are supported.
Create a materialized view.
CREATE MATERIALIZED VIEW mv AS
SELECT a, b, sum(c) AS sum, count(d) AS cnt FROM src GROUP BY a, b;
The following table shows how queries are rewritten based on the materialized view.
Original query
Rewritten query
SELECT a, sum(c) FROM src GROUP BY a;SELECT a, sum(sum) FROM mv GROUP BY a;SELECT a, count(d) FROM src GROUP BY a, b;SELECT a, cnt FROM mv;SELECT a, count(b) FROM (SELECT a, b FROM src GROUP BY a, b) GROUP BY a;SELECT a,count(b) FROM mv GROUP BY a;SELECT a,count(b) FROM mv GROUP BY a;Rewrite fails because the view has already aggregated columns
aandb, so columnbcannot be aggregated again.SELECT a, count(c) FROM src GROUP BY a;Rewrite fails because re-aggregation of the
COUNTfunction is not supported.
If an aggregate function contains DISTINCT, the query can be rewritten only if the materialized view and the original query have the same aggregation key. Otherwise, the rewrite is not possible.
Create a materialized view.
CREATE MATERIALIZED VIEW mv AS
SELECT a, b, sum(DISTINCT c) AS sum, count(DISTINCT d) AS cnt FROM src GROUP BY a, b;
The following table shows how queries are rewritten based on the materialized view.
Original query
Rewritten query
SELECT a, count(DISTINCT d) FROM src GROUP BY a, b;SELECT a, cnt FROM mv;SELECT a, count(c) FROM src GROUP BY a, b;Rewrite fails because re-aggregation of the
COUNTfunction is not supported.SELECT a, count(DISTINCT c) FROM src GROUP BY a;Rewrite fails because column
arequires another aggregation.
Example 3: Rewrite with a JOIN clause
Rewrite JOIN inputs
Create materialized views.
CREATE MATERIALIZED VIEW mv1 AS SELECT a, b FROM j1 WHERE b > 10;
CREATE MATERIALIZED VIEW mv2 AS SELECT a, b FROM j2 WHERE b > 10;
The following table shows how queries are rewritten based on the materialized views.
Original query
Rewritten query
SELECT j1.a,j1.b,j2.a FROM (SELECT a,b FROM j1 WHERE b > 10) j1 JOIN j2 ON j1.a=j2.a;SELECT mv1.a, mv1.b, j2.a FROM mv1 JOIN j2 ON mv1.a=j2.a;SELECT j1.a,j1.b,j2.a FROM (SELECT a,b FROM j1 WHERE b > 10) j1 JOIN (SELECT a,b FROM j2 WHERE b > 10) j2 ON j1.a=j2.a;SELECT mv1.a,mv1.b,mv2.a FROM mv1 JOIN mv2 ON mv1.a=mv2.a;
JOIN with filter conditions
Create materialized views.
--Create a non-partitioned materialized view.
CREATE MATERIALIZED VIEW mv1 AS SELECT j1.a, j1.b FROM j1 JOIN j2 ON j1.a=j2.a;
CREATE MATERIALIZED VIEW mv2 AS SELECT j1.a, j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j1.a > 10;
--Create a partitioned materialized view.
CREATE MATERIALIZED VIEW mv LIFECYCLE 7 PARTITIONED BY (ds) AS SELECT t1.id, t1.ds AS ds FROM t1 JOIN t2 ON t1.id = t2.id;
The following table shows how queries are rewritten based on the materialized views.
Original query
Rewritten query
SELECT j1.a,j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j1.a=4;SELECT a, b FROM mv1 WHERE a=4;SELECT j1.a,j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j1.a > 20;SELECT a,b FROM mv2 WHERE a>20;SELECT j1.a,j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j1.a > 5;(SELECT j1.a,j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j1.a > 5 AND j1.a <= 10) UNION SELECT * FROM mv2;SELECT key FROM t1 JOIN t2 ON t1.id= t2.id WHERE t1.ds='20210306';SELECT key FROM mv WHERE ds='20210306';SELECT key FROM t1 JOIN t2 ON t1.id= t2.id WHERE t1.ds>='20210306';SELECT key FROM mv WHERE ds>='20210306';SELECT j1.a,j1.b FROM j1 JOIN j2 ON j1.a=j2.a WHERE j2.a=4;Rewrite fails because the materialized view does not contain the column
j2.a.
Extend a JOIN
Create a materialized view.
CREATE MATERIALIZED VIEW mv AS SELECT j1.a, j1.b FROM j1 JOIN j2 ON j1.a=j2.a;The following table shows how queries are rewritten based on the materialized view.
Original query
Rewritten query
SELECT j1.a, j1.b FROM j1 JOIN j2 JOIN j3 ON j1.a=j2.a AND j1.a=j3.a;SELECT mv.a, mv.b FROM mv JOIN j3 ON mv.a=j3.a;SELECT j1.a, j1.b FROM j1 JOIN j2 JOIN j3 ON j1.a=j2.a AND j2.a=j3.a;SELECT mv.a,mv.b FROM mv JOIN j3 ON mv.a=j3.a;
These three JOIN rewrite scenarios can be combined.
Because the goal of materialized view query rewrite is to accelerate queries, MaxCompute prioritizes rewrite rules that offer the best performance. A rule is not applied if it introduces operations that would result in poor acceleration.
Example 4: Rewrite with a LEFT JOIN clause
Create a materialized view.
CREATE MATERIALIZED VIEW mv LIFECYCLE 7(
        user_id,
        job,
        total_amount
) AS SELECT t1.user_id, t1.job, sum(t2.order_amount) AS total_amount
      FROM user_info AS t1 LEFT JOIN sale_order AS t2 ON t1.user_id=t2.user_id GROUP BY t1.user_id;
The following table shows how a query is rewritten based on the materialized view.
Original query
Rewritten query
SELECT t1.user_id, sum(t2.order_amount) AS total_amount
FROM user_info AS t1
LEFT JOIN sale_order AS t2 ON t1.user_id=t2.user_id
GROUP BY t1.user_id;
SELECT user_id, total_amount FROM mv;
Example 5: Rewrite with a UNION ALL clause
Create a materialized view.
CREATE MATERIALIZED VIEW mv LIFECYCLE 7(
        user_id,
        tran_amount,
        tran_date
) AS SELECT user_id, tran_amount, tran_date FROM alipay_tran UNION ALL
SELECT user_id, tran_amount, tran_date FROM unionpay_tran;
The following table shows how a query is rewritten based on the materialized view.
Original query
Rewritten query
SELECT user_id, tran_amount FROM alipay_tran
UNION ALL SELECT user_id, tran_amount FROM unionpay_tran;
SELECT user_id, tran_amount FROM mv;
Materialized view query penetration
A partitioned materialized view may not contain data for all partitions — for example, if you refresh only the most recent ones. When a query targets a partition that lacks data in the materialized view, the system automatically falls back to the source partitioned table. The following figure illustrates this process.
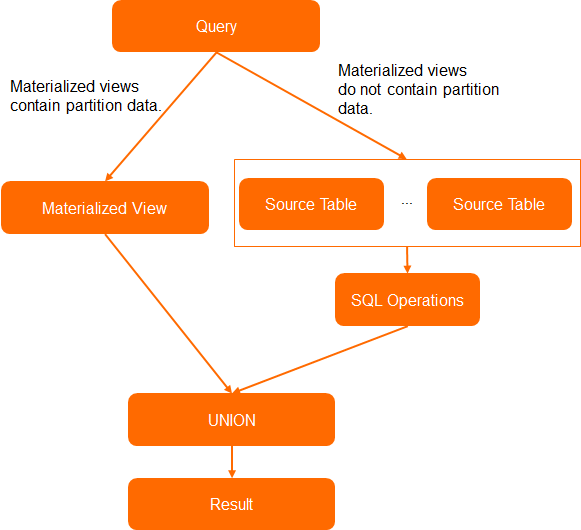
To enable the penetration query feature for a materialized view, set the following parameter:
When you create the materialized view, add the "enable_auto_substitute"="true" configuration to tblproperties.
The following example demonstrates how to use a materialized view that supports penetration queries.
Create a partitioned materialized view that supports penetration queries.
-- Create a source table named src.
CREATE TABLE src(id bigint,name string) PARTITIONED BY (dt string);
-- Insert data.
INSERT INTO src PARTITION(dt='20210101') VALUES(1,'Alex');
INSERT INTO src PARTITION(dt='20210102') VALUES(2,'Flink');

-- Create a partitioned materialized view that supports penetration query.
CREATE MATERIALIZED VIEW IF NOT EXISTS mv LIFECYCLE 7
PARTITIONED BY (dt)
tblproperties("enable_auto_substitute"="true")
AS SELECT id, name, dt FROM src;
Query data from the
20210101partition in the materialized viewmv.SELECT * FROM mv WHERE dt='20210101';Query data from the
20210102partition in the materialized viewmv. The system automatically performs a penetration query on the source table because this partition is not materialized.SELECT * FROM mv WHERE dt = '20210102'; -- Because the data for the 20210102 partition is not materialized, the query is rewritten to access the source table. This is equivalent to: SELECT * FROM (SELECT id, name, dt FROM src WHERE dt='20210102') t;Query data from a range of partitions in the materialized view
mv. The system automatically performs a penetration query on the source table for the non-materialized data and combines it with the materialized data using aUNIONoperation before returning the result.SELECT * FROM mv WHERE dt >= '20201230' AND dt<='20210102' AND id=5; -- Because data for partitions 20201230 and 20210102 is not materialized, the query is rewritten to access the source table. This is equivalent to: SELECT * FROM (SELECT id, name, dt FROM src WHERE dt='20201230' OR dt='20210102' UNION ALL SELECT * FROM mv WHERE dt='20210101' ) t WHERE id = 5;
Related statements
ALTER MATERIALIZED VIEW: updates a materialized view, changes the lifecycle of a materialized view, enables or disables the lifecycle feature for a materialized view, or drops partitions from a materialized view.
DESC TABLE/VIEW: views the information about a materialized view in a MaxCompute project.
SELECT MATERIALIZED VIEW: queries the status of a materialized view.
DROP MATERIALIZED VIEW: drops an existing materialized view.