The Doris Writer allows you to write data to Doris from an external database or copy data from a storage system on a big data platform for integration and processing.
Prerequisites
-
You have created a Doris data source. For more information, see Create a Doris data source.
-
Your account must have write permission for the Doris data source. If not, apply for it. For more information, see Apply for data source permissions.
Procedure
-
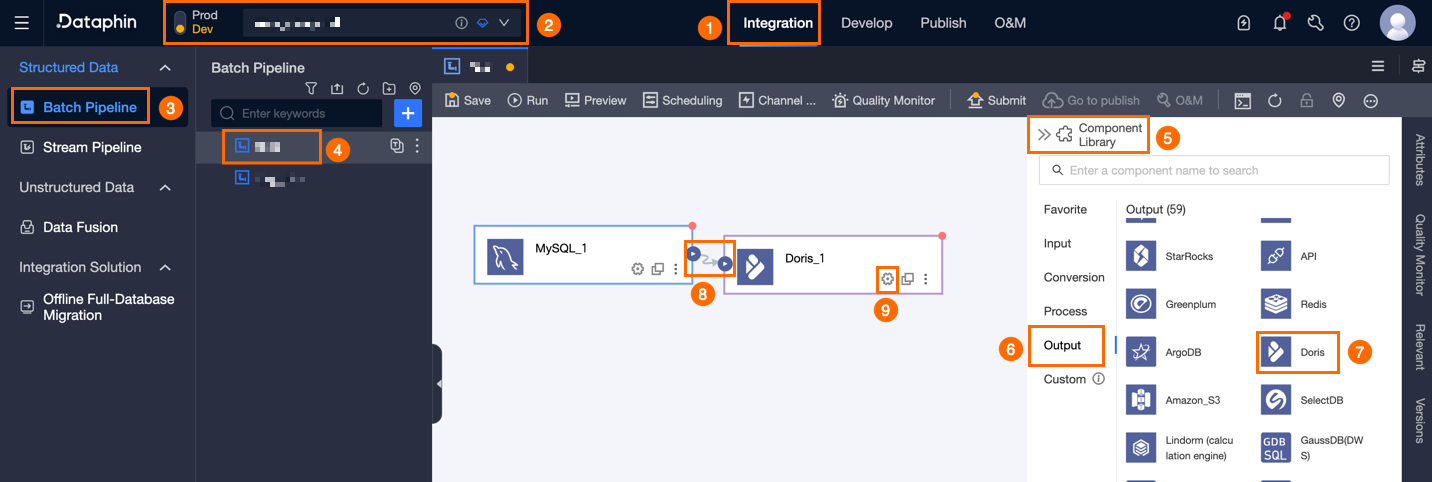
In the top navigation bar of the Dataphin homepage, choose Develop > Data Integration.
-
In the top navigation bar of the Data Integration page, select a Project. If you are in Dev-Prod mode, you also need to select an environment.
-
In the left-side navigation pane, click Batch Integration. In the Batch Integration list, click the batch pipeline you want to develop.
-
In the upper-right corner of the page, click Component Library to open the Component Library pane.
-
In the left-side navigation pane of the Component Library, select Writer. From the list of writers on the right, find and drag the Doris component to the canvas.
-
Click and drag the
 icon of a source, transformation, or process component to connect it to the Doris Writer.
-
Click the
 icon on the Doris Writer card to open the Doris Output Configuration dialog box.
-
In the Doris Output Configuration dialog box, configure the parameters as described in the following table.
Parameter
Description
Basic settings
Step name
The name of the Doris Writer. Dataphin automatically generates a step name, but you can change it for your business scenario. The name must follow these rules:
-
Can contain only Chinese characters, letters, underscores (_), and digits.
-
Cannot exceed 64 characters in length.
Data source
The drop-down list shows all Doris data sources, including those you have write permission for and those you do not. Click the
 icon to copy the name of the current data source.
-
If you lack write permission for a data source, click Apply next to it to request access. For more information, see Apply for data source permissions.
-
If you do not have a Doris data source, click New data source to create one. For more information, see Create a Doris data source.
Table
Select the destination table. You can search by entering a table name keyword, or enter the exact table name and click Exact search. After you select a table, the system automatically checks its status. Click the
 icon to copy the name of the selected table.
If the Doris data source lacks a suitable destination table, use the one-click table creation feature to generate one. Follow these steps:
-
Click one-click table creation. Dataphin automatically generates a table creation statement. This statement includes a default table name (from the source table) and field types mapped from the source.
-
Modify the table creation statement as needed, and then click Create. Dataphin automatically sets the newly created table as the destination.
Note-
If a table with the same name already exists in the development environment, Dataphin reports an error when you click Create.
-
If no match is found, you can still proceed with the integration by manually entering a table name.
-
Policy for missing production table
The policy for handling cases where the production table does not exist. You can select No action or Auto-create. The default is Auto-create. If you select No action, the production table is not created when the task is published. If you select Auto-create, the table is automatically created in the production environment when the task is published.
-
No action: If the destination table does not exist, you receive a warning upon submission, but you can still publish the task. In this case, you must manually create the destination table in the production environment before the task can run.
-
Auto-create: You must edit the table creation statement. Dataphin pre-fills the field with the table creation statement from the selected table, which you can modify. The table name in the table creation statement must use the placeholder
${table_name}, and only this placeholder is supported. This placeholder is replaced with the actual table name at runtime.If the destination table does not exist, the system first attempts to create it using the provided statement. If the creation fails, the deployment check fails. You can then modify the statement based on the error message and try to publish again. If the destination table already exists, the creation step is skipped.
NoteThis parameter is available only in projects that use Dev-Prod mode.
Data format
Select CSV or JSON.
If you select CSV, you must also configure CSV Import Column Delimiter and CSV Import Row Delimiter.
CSV import column delimiter (Optional)
Specifies the column delimiter for CSV data import by using StreamLoad. The default delimiter is
_@dp@_. If you use the default value, do not explicitly specify this parameter. If your data contains_@dp@_, you must specify a different character as the delimiter.CSV import row delimiter (Optional)
Specifies the row delimiter for StreamLoad CSV imports. The default is
#dp#. Do not specify this parameter if you use the default value. If your data contains#dp#, you must specify a different character as the delimiter.Batch Write (Optional)
If enabled, the system writes data to the destination in batches. It commits batches based on batch write size and batch write record count to reduce load on the destination and prevent oversized transactions. If disabled, the system writes all data in a single transaction, consuming more memory and increasing the risk of failure.
batch write size (Optional)
The maximum data size for a single batch. A batch is committed when either this size limit or the batch write record count is reached, whichever occurs first. The default is 32 MB.
batch write record count (Optional)
The default is 2048 records. When data is written synchronously, a batch write strategy is used. The parameters for this strategy include batch write record count and batch write size.
-
When the accumulated data reaches either of the specified limits (data size or record count), the system considers the batch full and writes it to the destination.
-
We recommend setting the batch write size to 32 MB. You can adjust the batch write record count based on the size of a single record. A larger value is generally better to take full advantage of batch writing. For example, if a single record is about 1 KB, you can set the batch write size to 16 MB and the batch write record count to a value greater than 16 MB divided by 1 KB (16,384 records), such as 20,000. With this configuration, the system triggers a write operation each time the accumulated data reaches 16 MB.
Preparatory statement (Optional)
The SQL script that runs on the database before the data import.
For example, to perform an atomic table swap, you can use a preparatory statement to create a temporary staging table. The data import job then populates this table.
Concluding statement (Optional)
An SQL script that is executed on the database after data is imported. For example, continuing the atomic swap scenario, you could use a concluding statement to rename the live table to a backup, rename the staging table to become the new live table, and then drop the backup.
Field Mapping
Input fields
Displays the input fields from the upstream component.
Output fields
Displays the output fields. You can perform the following operations:
-
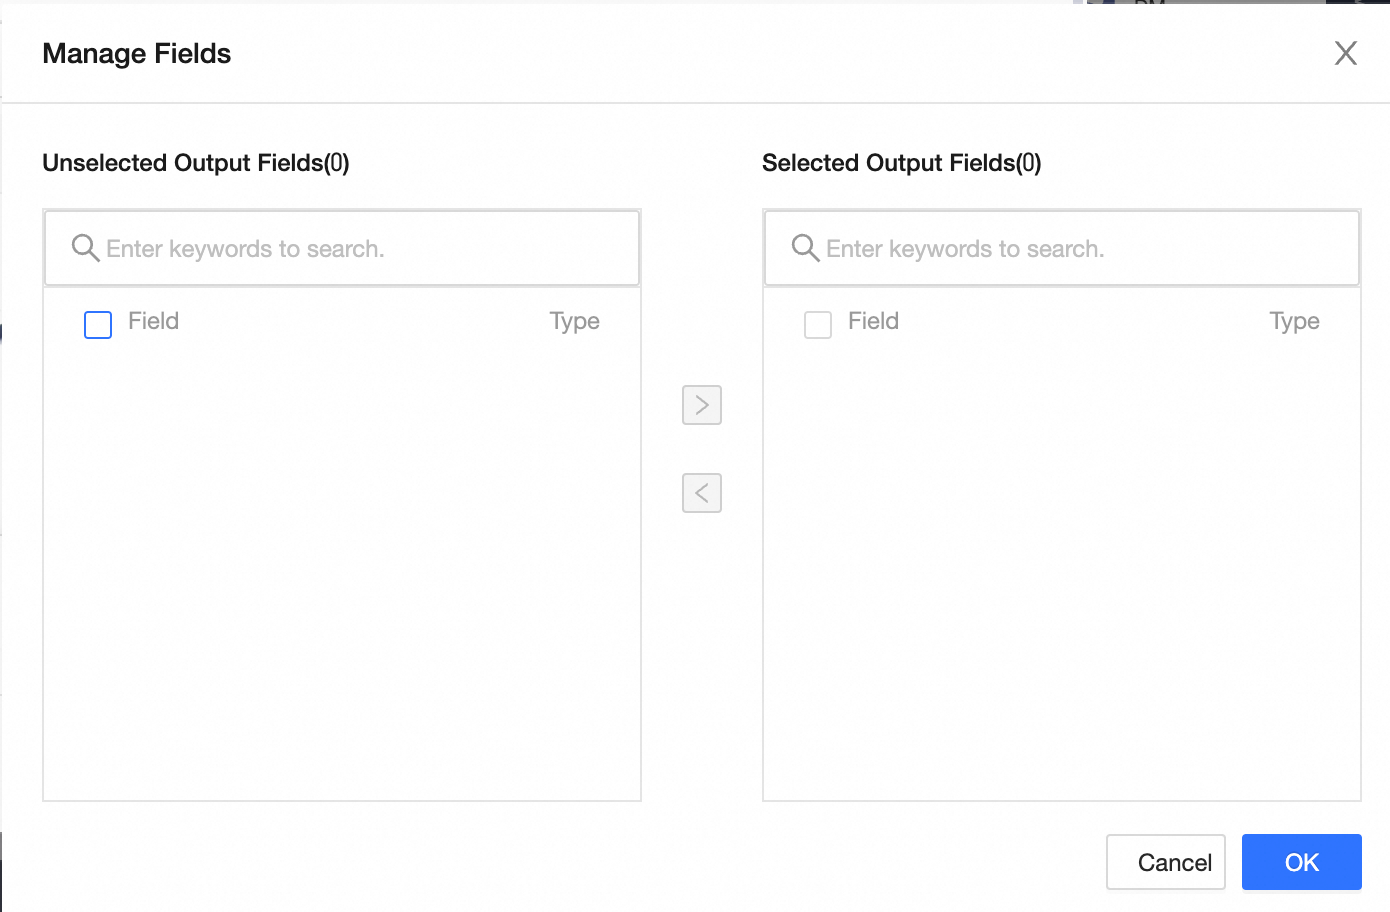
Manage fields: Click Manage fields to select output fields.
-
Click the
 icon to move fields from Selected Input Fields to Unselected Input Fields.
-
Click the
 icon to move fields from Unselected Input Fields to Selected Input Fields.
-
-
Batch add: Click Batch add to add fields in bulk by using JSON, TEXT, or DDL format.
-
To add fields in bulk by using JSON format, for example:
// Example: [{ "name": "user_id", "type": "String" }, { "name": "user_name", "type": "String" }]Notenamespecifies the name of the imported field, andtypespecifies the field type after import. For example,"name":"user_id","type":"String"imports the field nameduser_idand sets its type toString. -
To add fields in bulk by using TEXT format, for example:
// Example: user_id,String user_name,String-
The row delimiter separates each field definition. The default is a newline character (\n). The semicolon (;) and period (.) are also supported.
-
The column delimiter separates the field name and field type. The default is a comma (,).
-
-
To add fields in bulk by using DDL format, for example:
CREATE TABLE tablename (
    id INT PRIMARY KEY,
    name VARCHAR(50),
    age INT
);
-
-
New output field: Click + New output field, enter a Field name, and select a Type. After configuring the row, click the
 icon to save.
Mapping relationship
You can map input fields from the source to output fields in the destination. The Quick mapping options, Map by position and Map by name, can help automate this process.
-
Map by name: Maps fields that have the same name.
-
Map by position: Maps fields based on their order in the schema. This is useful when source and destination field names are different, but their column positions correspond.
-
-
Click Confirm to save the Doris Writer configuration.