These are the release notes for the training-nv-pytorch 25.12 image, a PyTorch environment for training and inference jobs in ACS and Lingjun multi-tenant environments. This release upgrades vLLM and flashinfer-python, and is published in two variants that target different CUDA and NVIDIA driver versions.
Supported environments
training-nv-pytorch 25.12 images are supported in ACS and Lingjun multi-tenant environments.
This image is not supported in Lingjun single-tenant deployments.
Main features and bug fixes
Main features
Upgraded vLLM to 0.12.0 and flashinfer-python to 0.5.3.
Bug fixes
None.
Image specifications
The following table lists the specifications of the two training-nv-pytorch 25.12 images. Use it as the reference for the driver version and CPU architectures that each tag requires.
Item | 25.12-cu130-serverless | 25.12-cu128-serverless |
Image name | training-nv-pytorch | training-nv-pytorch |
Use cases | Training/inference | Training/inference |
Framework | PyTorch | PyTorch |
Requirements | NVIDIA driver 580 or later | NVIDIA driver 575 or later |
Supported architectures | amd64 and aarch64 | amd64 |
Core components
The following table lists the core components and component versions in each image.
Component | 25.12-cu130-serverless | 25.12-cu128-serverless |
Ubuntu | 24.04 | 24.04 |
Python | 3.12.7+gc | 3.12.7+gc |
CUDA | 13.0.2 | 12.8.0 |
perf | 5.4.30 | 5.4.30 |
gdb | 15.0.50.20240403-git | 15.0.50.20240403-git |
torch | 2.9.0+ali.10.nv25.10 | 2.8.0.9+nv25.3 |
triton | 3.5.0 | 3.4.0 |
transformer_engine | 2.9.0+70f53666 | 2.9.0+70f53666 |
deepspeed | 0.18.1+ali | 0.18.1+ali |
flash_attn | 2.8.3 | 2.8.3 |
flash_attn_3 | not found | 3.0.0b1 |
transformers | 4.57.1+ali | 4.57.1+ali |
grouped_gemm | 1.1.4 | 1.1.4 |
accelerate | 1.11.0+ali | 1.11.0+ali |
diffusers | 0.34.0 | 0.34.0 |
mmengine | 0.10.3 | 0.10.3 |
mmcv | 2.1.0 | 2.1.0 |
mmdet | 3.3.0 | 3.3.0 |
opencv-python-headless | 4.11.0.86 | 4.11.0.86 |
ultralytics | 8.3.96 | 8.3.96 |
timm | 1.0.22 | 1.0.22 |
vllm | 0.12.0+cu130 | 0.12.0+cu128 |
flashinfer-python | 0.5.3 | 0.5.3 |
pytorch-dynamic-profiler | 0.24.11 | 0.24.11 |
peft | 0.16.0 | 0.16.0 |
ray | 2.52.1 | 2.52.1 |
megatron-core | 0.14.0 | 0.14.0 |
Assets
Public images
Each CUDA version of training-nv-pytorch 25.12 is published at its own image address. For the driver version and CPU architectures that each image requires, see the Image specifications section.
CUDA version | Image address |
13.0.2 | egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-nv-pytorch:25.12-cu130-serverless |
12.8.0 | egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-nv-pytorch:25.12-cu128-serverless |
VPC images
Replace the AI container image asset URI egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/{image:tag} specified in the YAML file of the ACS console with acs-registry-vpc.{region-id}.cr.aliyuncs.com/egslingjun/{image:tag} to quickly pull PG1 AI container images over the VPC.
Where
{region-id}is the available region where your ACS is activated, such as cn-beijing and cn-wulanchabu.{image:tag}is the name and tag of the image.
Driver requirements
training-nv-pytorch 25.12 supports two CUDA versions, each with its own minimum NVIDIA driver version. CUDA 13.0.2 requires NVIDIA driver 580 or later, and CUDA 12.8.0 requires NVIDIA driver 575 or later. For a complete list of supported drivers, see the CUDA Application Compatibility topic. For more information about driver compatibility, see CUDA Compatibility and Upgrades.
Key features and enhancements
PyTorch compilation optimization
torch.compile(), introduced in PyTorch 2.0, often delivers strong gains for small-scale, single-GPU workloads. But LLM training depends on GPU memory optimization and distributed frameworks such as FSDP or DeepSpeed, so torch.compile() may offer limited benefits or even degrade performance.
-
Control communication granularity in the DeepSpeed framework. This helps the compiler capture a more complete compute graph and apply broader compilation optimizations.
-
Use an optimized PyTorch build:
-
The PyTorch compiler frontend is improved to ensure that compilation succeeds even if a graph break occurs in the compute graph.
-
Pattern matching and dynamic shape support are strengthened to improve post-compilation performance.
-
With these optimizations, 8B-parameter LLM training typically achieves an end-to-end throughput gain of about 20%.
GPU memory optimization for recomputation
A predictive model for GPU memory overhead, built on large-scale performance data—including different models, clusters, and training parameter settings, as well as system metrics such as GPU memory utilization collected during benchmarking—recommends the optimal number of activation recomputation layers. This approach is integrated into PyTorch, allowing you to achieve the performance gains of GPU memory optimization with minimal effort. This feature is now supported in the DeepSpeed framework.
E2E performance gain evaluation
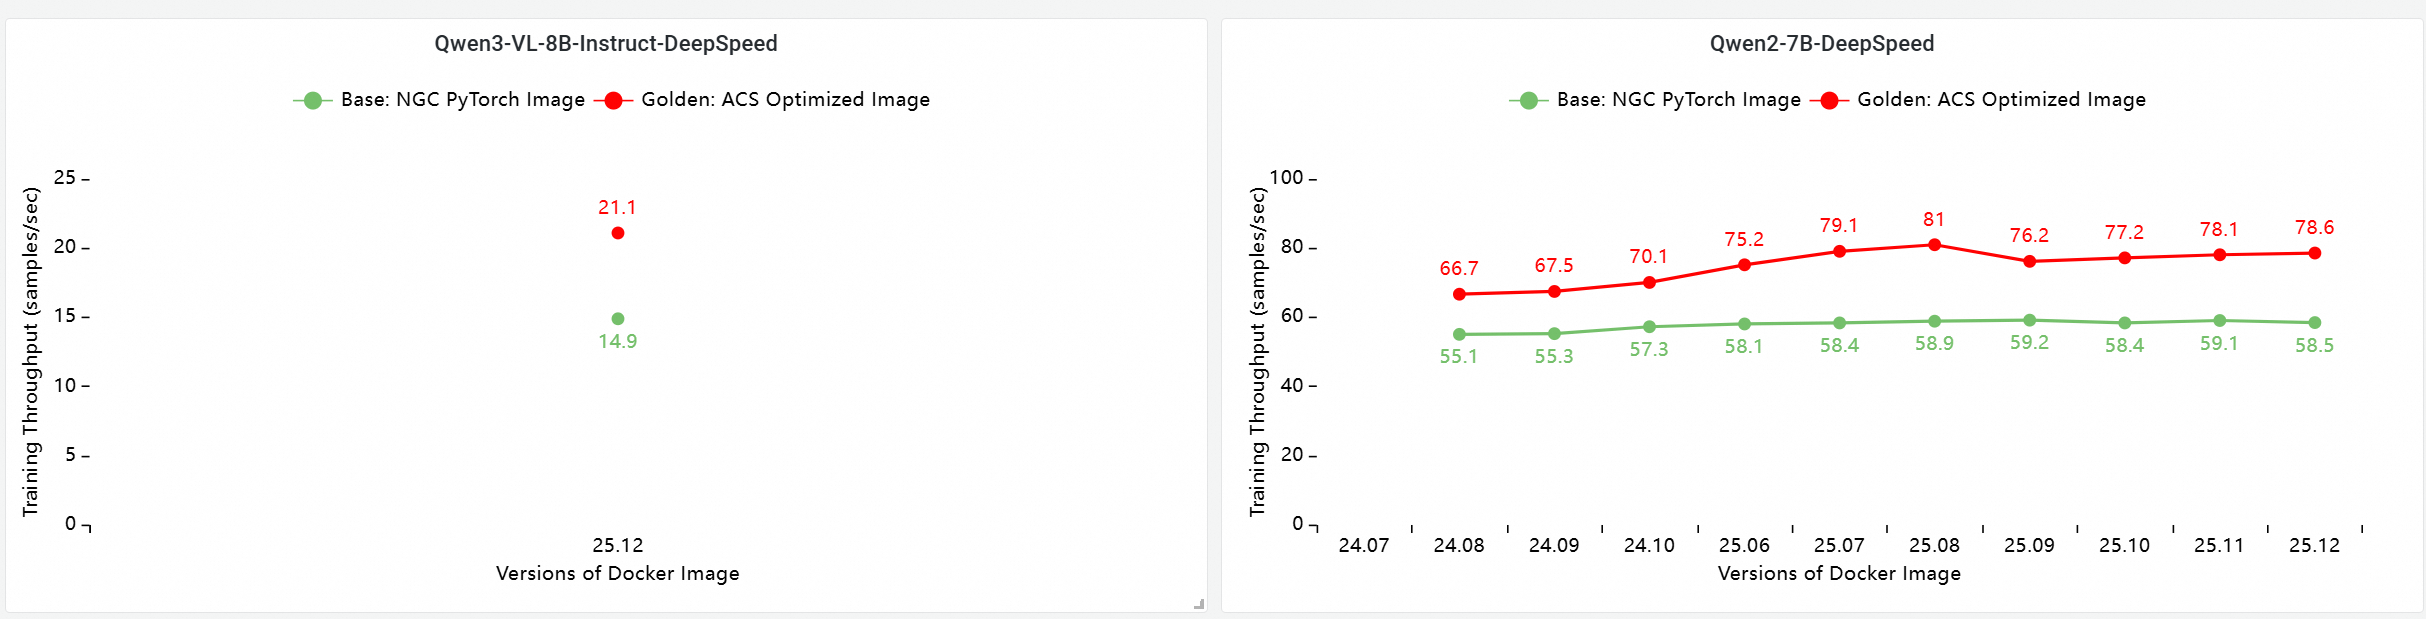
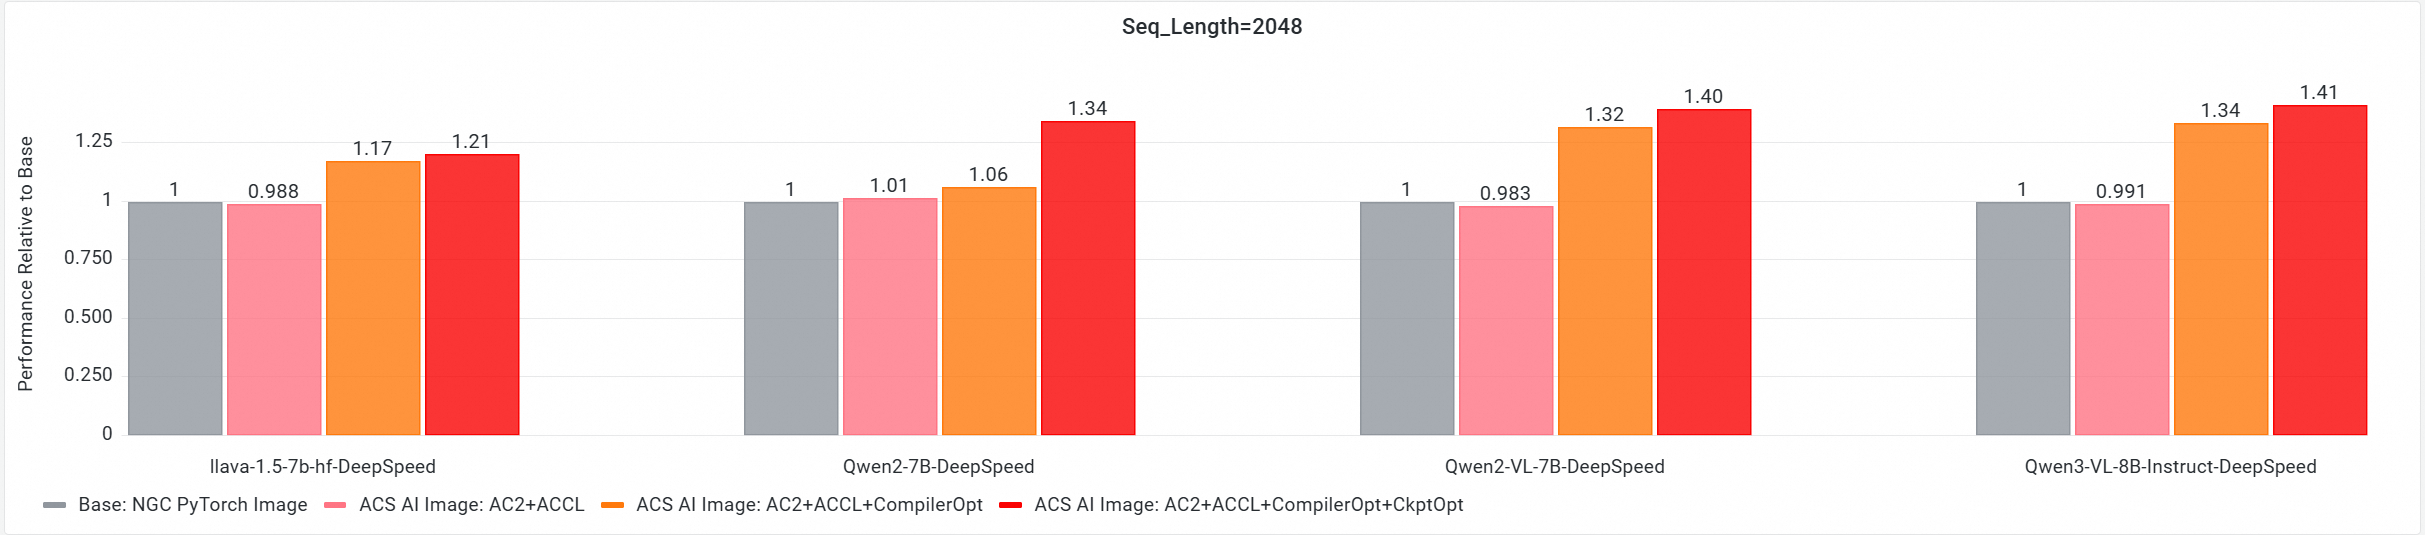
A comprehensive end-to-end (E2E) performance comparison against a standard base image was conducted by using the cloud-native AI performance evaluation and analysis tool (CNP), with mainstream open-source models and framework configurations. An ablation study further assessed how much each optimized component contributes to overall model training performance.
Comparison of this image with the base image across iterations
E2E performance contribution analysis of core GPU components
E2E training performance was evaluated on a multi-node GPU cluster running version 25.12 across the following configurations:
Base: The NGC PyTorch image.
ACS AI image (Base + ACCL): The base image with the ACCL communication library.
ACS AI image (AC2 + ACCL): AC2 BaseOS with ACCL and no optimizations enabled.
ACS AI image (AC2 + ACCL + CompilerOpt): AC2 BaseOS with ACCL and only the torch compile optimization enabled.
ACS AI image (AC2 + ACCL + CompilerOpt + CkptOpt): AC2 BaseOS with ACCL and both the torch compile and selective gradient checkpoint optimizations enabled.
Quick start
The following example shows how to pull the training-nv-pytorch image and run a training job by using Docker.
To use the training-nv-pytorch image in ACS, select the image on the Artifact Center page when you create a workload in the console, or reference the image in a YAML file.
Usage recommendations
The following restrictions and settings apply whenever you run the training-nv-pytorch image:
Bundled libraries — Do not reinstall libraries such as PyTorch and DeepSpeed. This image contains modified versions of these libraries.
DeepSpeed configuration — In the DeepSpeed configuration, leave
zero_optimization.stage3_prefetch_bucket_sizeempty or set it toauto.Network interface — Adjust the built-in
NCCL_SOCKET_IFNAMEenvironment variable in this image based on your scenario:When a single Pod requests 1, 2, 4, or 8 GPUs for a training or inference job, set
NCCL_SOCKET_IFNAME=eth0. This is the default configuration in this image.When a single Pod requests all 16 GPUs on a node for a training or inference job, you can use the HPN (High Performance Network). In this case, set
NCCL_SOCKET_IFNAME=hpn0.
1. Pull the image
Confirm the NVIDIA driver version and CPU architecture of your environment, and then run the following command to pull the image:
docker pull egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-nv-pytorch:[tag]Replace [tag] with one of the published tags:
25.12-cu130-serverless: CUDA 13.0.2, requires NVIDIA driver 580 or later, and supports amd64 and aarch64.25.12-cu128-serverless: CUDA 12.8.0, requires NVIDIA driver 575 or later, and supports amd64 only.
2. Enable compilation and recomputation optimizations
Enable compilation optimization
Set the following fields in the transformers TrainingArguments class:
training_args = TrainingArguments(
    bf16=True,
    gradient_checkpointing=True,
    torch_compile=True
)
Enable GPU memory optimization for recomputation
Set the following environment variable:
export CHECKPOINT_OPTIMIZATION=true3. Start the container
The ljperf model training tool is built into the image. The following commands use ljperf to start a container and run a training job.
LLMs
# Start and enter the container
docker run --rm -it --ipc=host --net=host  --privileged egslingjun-registry.cn-wulanchabu.cr.aliyuncs.com/egslingjun/training-nv-pytorch:[tag]
# Run the training demo
ljperf benchmark --model deepspeed/llama3-8b
Known issues
Compiling flash_attn_3 (fa3) directly in the CUDA 13.0.2 image of this release returns an error. This is a known community issue. In the Core components table, flash_attn_3 is listed as not found for the 25.12-cu130-serverless image.