ZooKeeper Practice: Solving Data Inconsistency Caused by ZooKeeper v3.4.6
By Zikui
Background
As the metadata center of a distributed system, ZooKeeper needs to ensure data consistency for external services. However, some old versions of ZooKeeper may not be able to ensure data consistency in some cases, resulting in problems in systems that rely on ZooKeeper.
A user uses ZooKeeper 3.4.6 to schedule tasks. The TPS and QPS of the ZooKeeper instance are relatively high, and the generation rate of transaction logs is very high. Even though the user has configured automatic cleanup parameters, the minimum interval of automatic cleanup is still unable to keep up with the data generation rate, resulting in full disk usage.
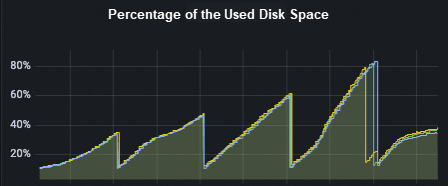
After the user cleaned up the old logs and restarts the node, some service machines reported errors of NodeExist and NoNode. This exception caused significant losses for the user's task scheduling system, including duplicated task scheduling and task losses.
Cause
Upon careful inspection of these clients, we find that these clients are all connected to the same ZooKeeper node. And after manually checking the data on the node through zkCli and comparing it with the data on the other ZooKeeper nodes that do not clean up the disk, we find that the data in the former are different from the latter. It was determined that the node had inconsistent data due to some reason, causing the clients connected to this node to read dirty data
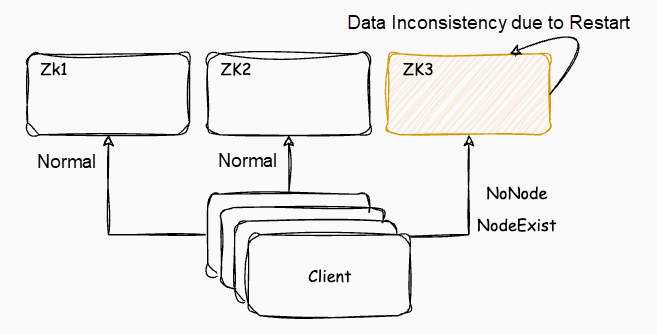
However, there are no exception logs found. Because the logs were cleared and restarted before this node, the data on the disk has been reloaded, it is suspected that some exceptions occurred in the process of starting ZooKeeper to load data. We continue to troubleshoot the specific cause by analyzing the code of loading data during ZooKeeper startup.
public long restore(DataTree dt, Map<Long, Integer> sessions,
            PlayBackListener listener) throws IOException {
        snapLog.deserialize(dt, sessions);
        FileTxnLog txnLog = new FileTxnLog(dataDir);
        TxnIterator itr = txnLog.read(dt.lastProcessedZxid+1);
        long highestZxid = dt.lastProcessedZxid;
        TxnHeader hdr;
        try {
            while (true) {
        ...
                try {
                    processTransaction(hdr,dt,sessions, itr.getTxn());
                } catch(KeeperException.NoNodeException e) {
                   throw new IOException("Failed to process transaction type: " +
                         hdr.getType() + " error: " + e.getMessage(), e);
                ...
        return highestZxid;
    }
Here is the code for loading disk data by ZooKeeper. The main function of this method is to first load the snapshot file in the disk into the memory, initialize the data structure in the memory of ZooKeeper, then load the modifications of data in transaction logs and application logs, and finally restore the state of the data in the disk.
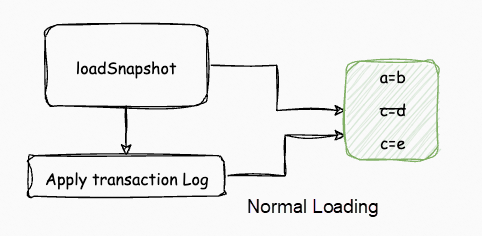
However, in the code of the 3.4.6 version, there is a return value of snapLog.deserialize(dt, sessions);, the code to load the snapshot file, and the return value verification is not performed here. As a result, the transaction log is loaded even if ZooKeeper cannot find a valid snapshot file, resulting in ZooKeeper applying the transaction log directly with empty data, which eventually leads to data inconsistencies between this node and other nodes.
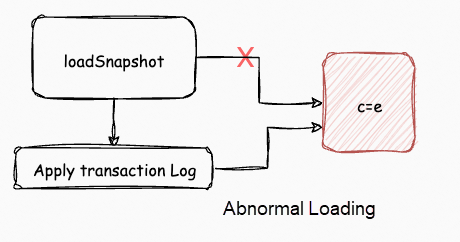
There is a corresponding issue in the ZooKeeper community. In cases where the file list for loading snapshot is empty, this issue has been fixed. However, this issue still exists in other special cases where snapshot files are incomplete due to a full disk. This issue needs to be addressed from a disk usage perspective.
Solution
To prevent the disk of ZooKeeper nodes from being filled up quickly, the disk capacity can be increased. ZooKeeper's cleaning mechanism can prevent full disk usage within a certain range of TPS. However, increasing the disk capacity can significantly increase usage cost. Even with an increased disk capacity, the disk may still fill up if ZooKeeper's cleaning mechanism fails to clean up data in a timely manner. Consequently, manual disk cleanup is required, which is complex, time-consuming, and labor-intensive, and does not significantly improve the cluster's stability.
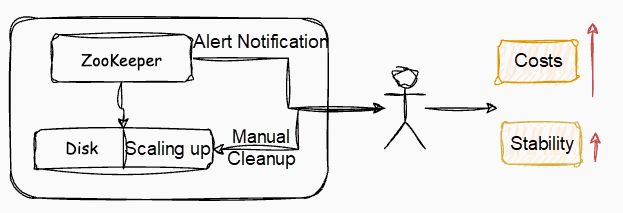
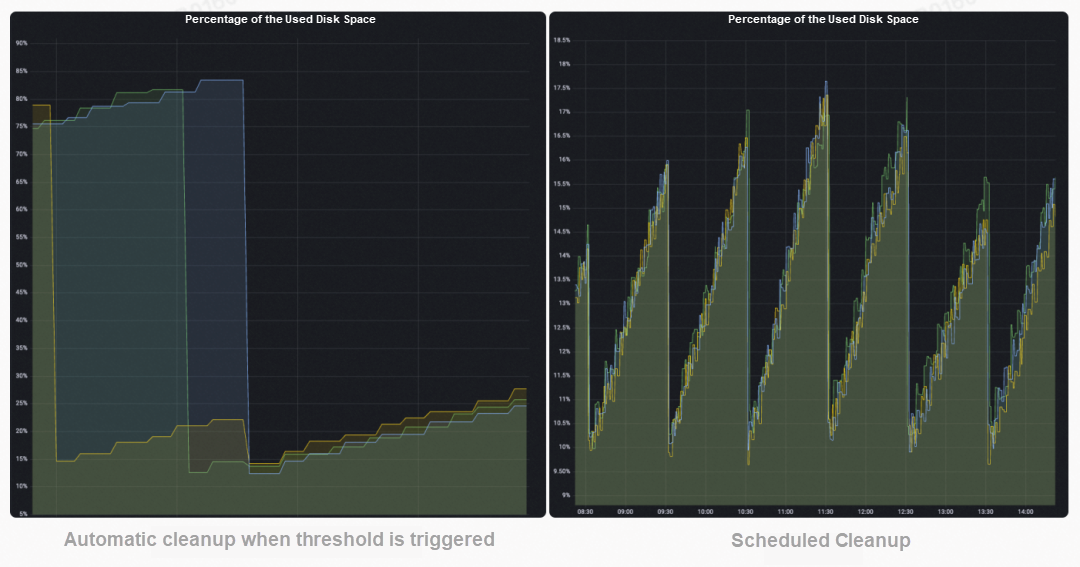
MSE ZooKeeper provides fully managed ZooKeeper instances. The disk usage of MSE ZooKeeper instances is completely transparent to users. Users do not need to worry about full disk usage or complex O&M during disk usage. MSE ZooKeeper uses scheduled cleanup and threshold cleanup to ensure that the disks of ZooKeeper instances are always at a safe level during use. This prevents data inconsistency and instance unavailability due to disk issues.
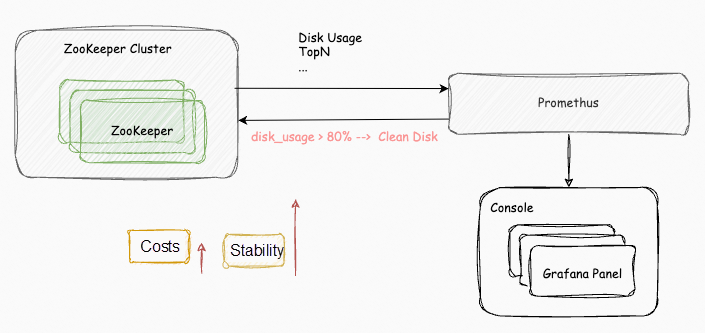
By default, MSE ZooKeeper integrates with Prometheus Monitoring to provide a wide range of metrics. In scenarios with a large number of data writes, MSE ZooKeeper provides a TopN dashboard to quickly view the hot data of businesses and clients with high TPS, and locate problems based on these statistics in the business.
Read previous post:
Koordinator V1.2.0 Supports Node Resource Reservation and Is Compatible with the Rescheduling Policy
Read next post:
-

-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Comments
-
-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Related Products
-
 Managed Service for Prometheus
Multi-source metrics are aggregated to monitor the status of your business and services in real time.
Learn More -
 Cloud-Native Applications Management Solution
Accelerate and secure the development, deployment, and management of containerized applications cost-effectively.
Learn More -
 Qoder
From Assisted to Autonomous — Adapting to Every Programming Need
Learn More -
 EventBridge
 is a serverless event bus service that connects to Alibaba Cloud services, custom applications, and SaaS applications as a centralized hub.
Learn More
More Posts by Alibaba Cloud Native Community
- Best Practices for Skill Evaluation and Optimization Based on Alibaba Cloud AgentLoop
- DeepSeek Harness Evaluation Practice Based on Alibaba Cloud AgentLoop
- 97.1% Lower Gateway Latency: Open-Source Higress vs. Alibaba Cloud AI Gateway Serverless Enterprise Edition
- Alibaba Cloud's Open-Source AI Agent Handbook, 3K+ GitHub Stars
- DeepSeek Harness: A Practical Guide to Comprehensive Observability
- Alibaba Cloud AI Gateway Intelligent Routing Is Now Live
- After Everything Becomes a Plugin: A New Paradigm for Agent Engineering
- AgentScope Service: Open-Source Agent Control Plane with DeepSeek Harness Support
- Seamless AI Safety: Integrating Qwen3Guard into Higress with Zero Code Changes
- DeepSeek's SuperAgent and Our Practice