Qwen3-ASR & Qwen3-ForcedAligner is Now Open Sourced: Robust, Streaming and Multilingual!
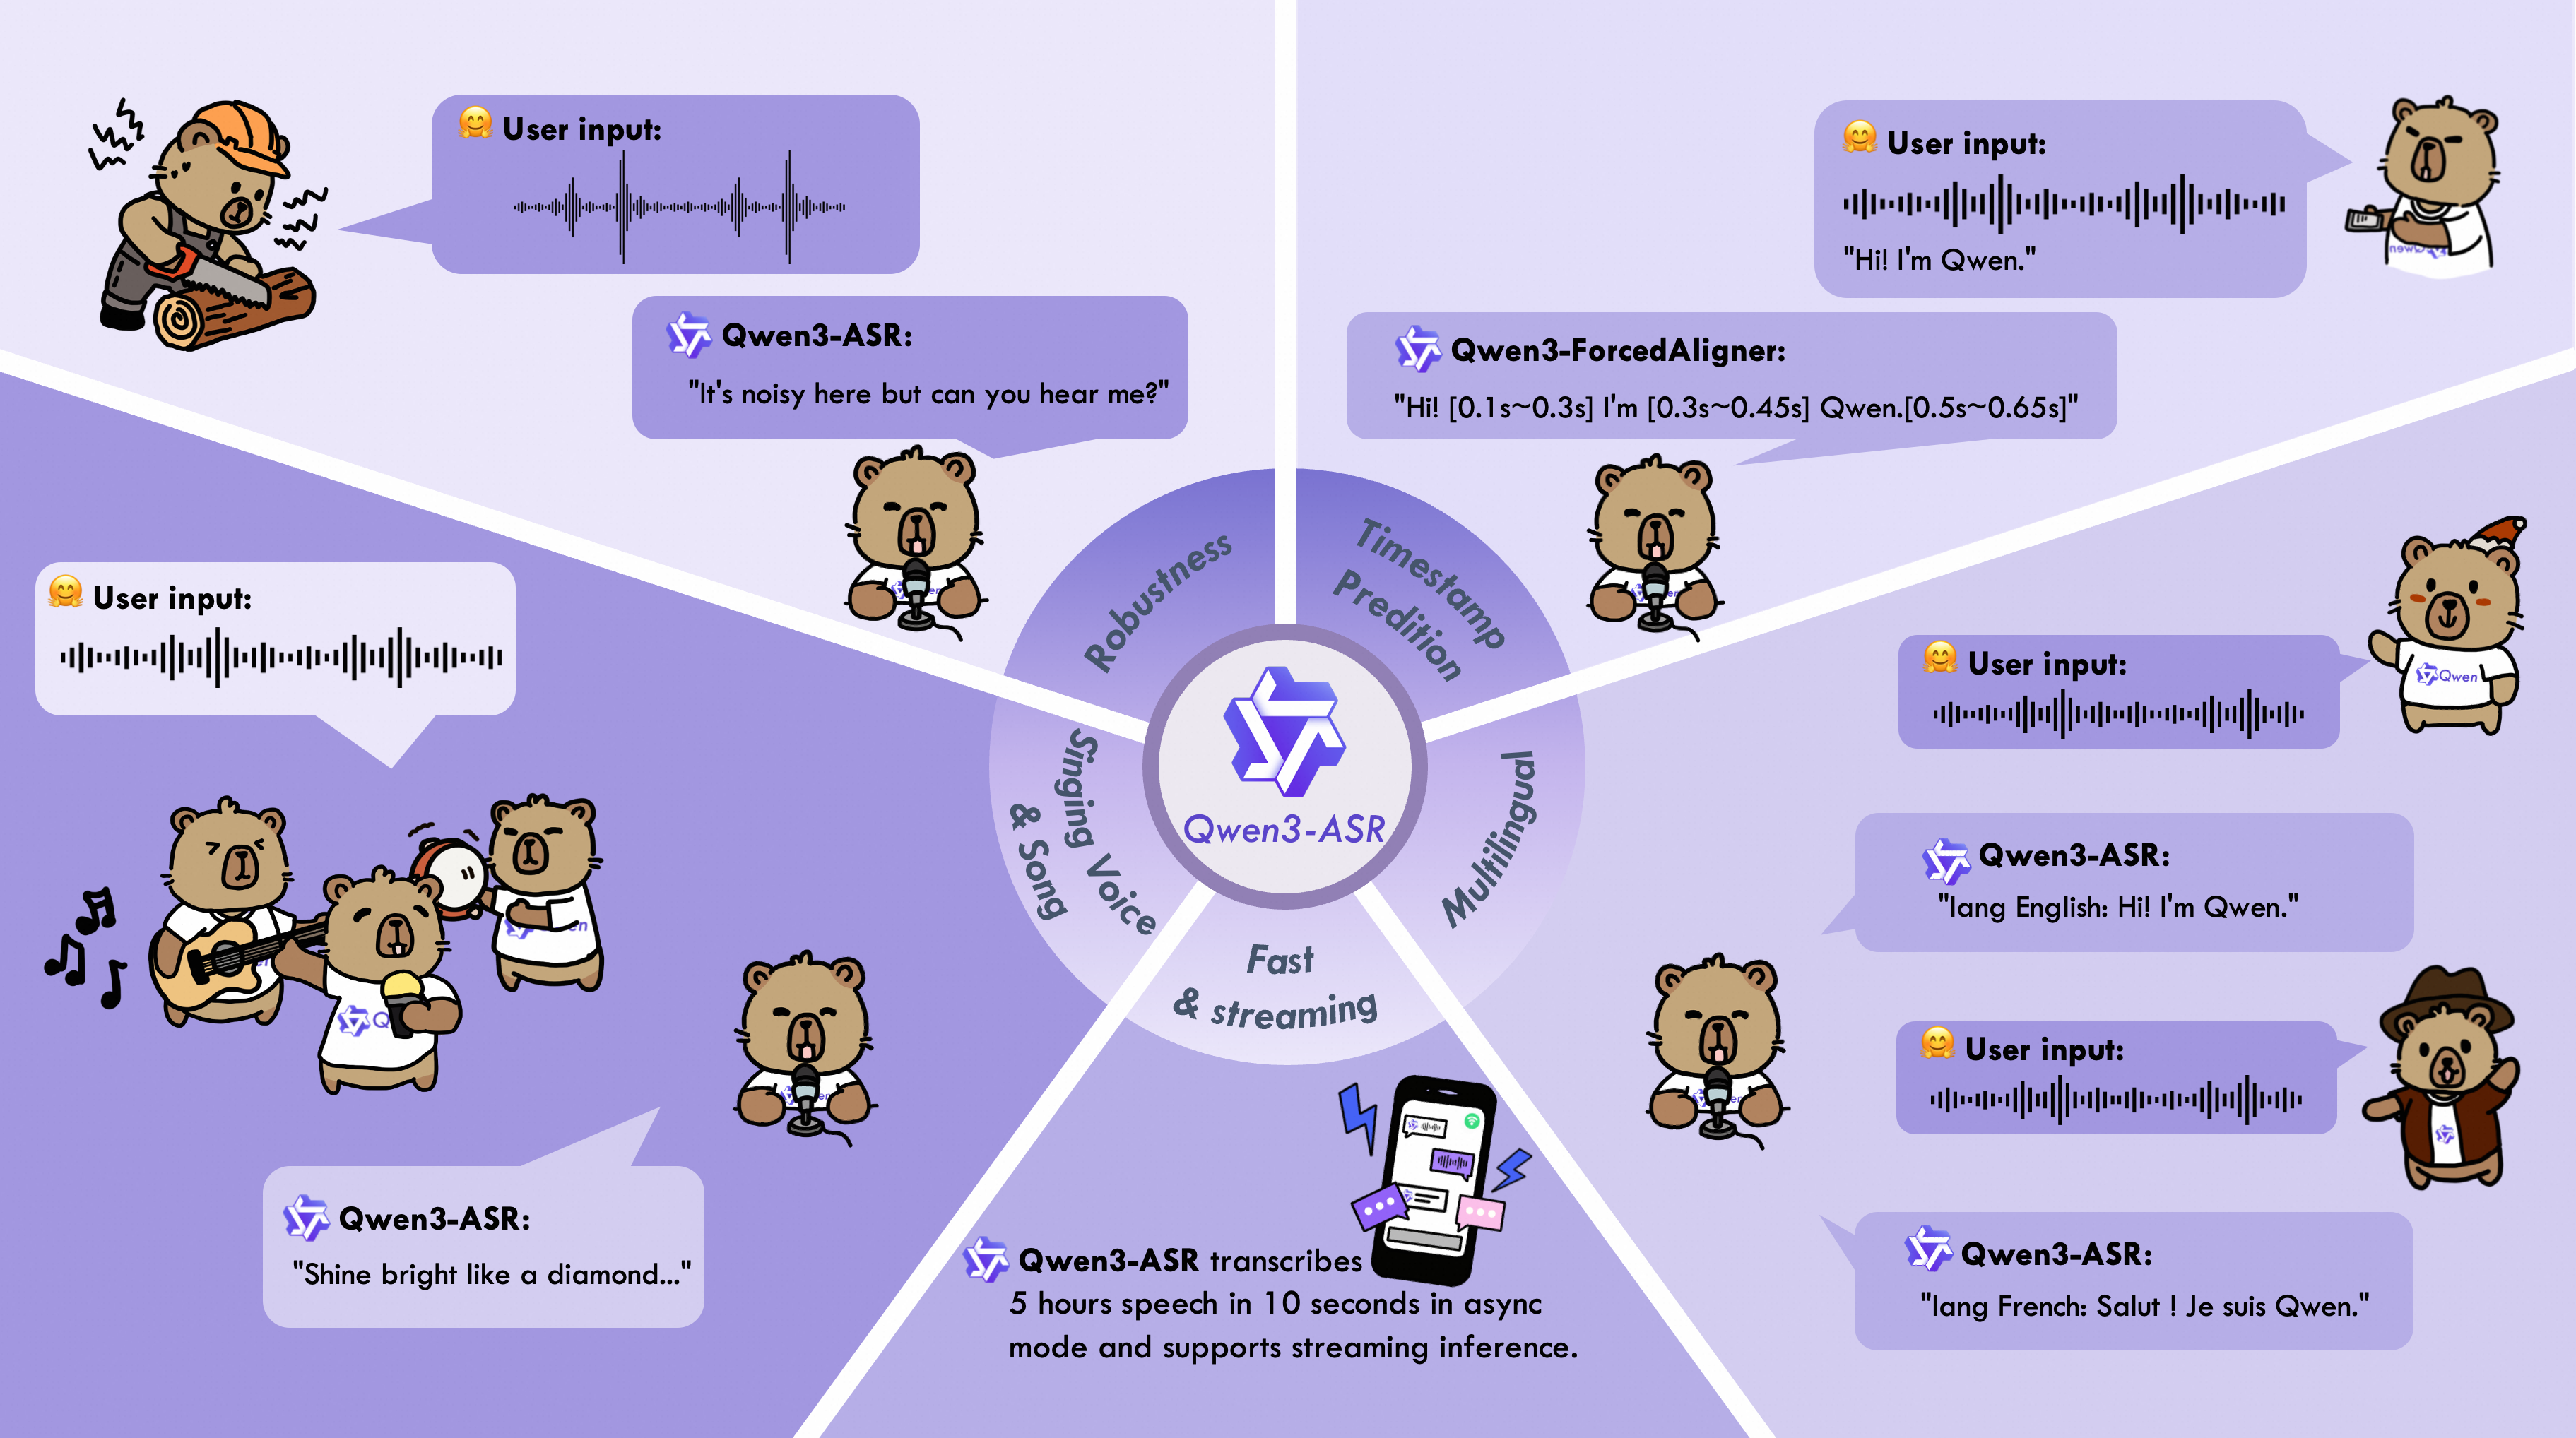
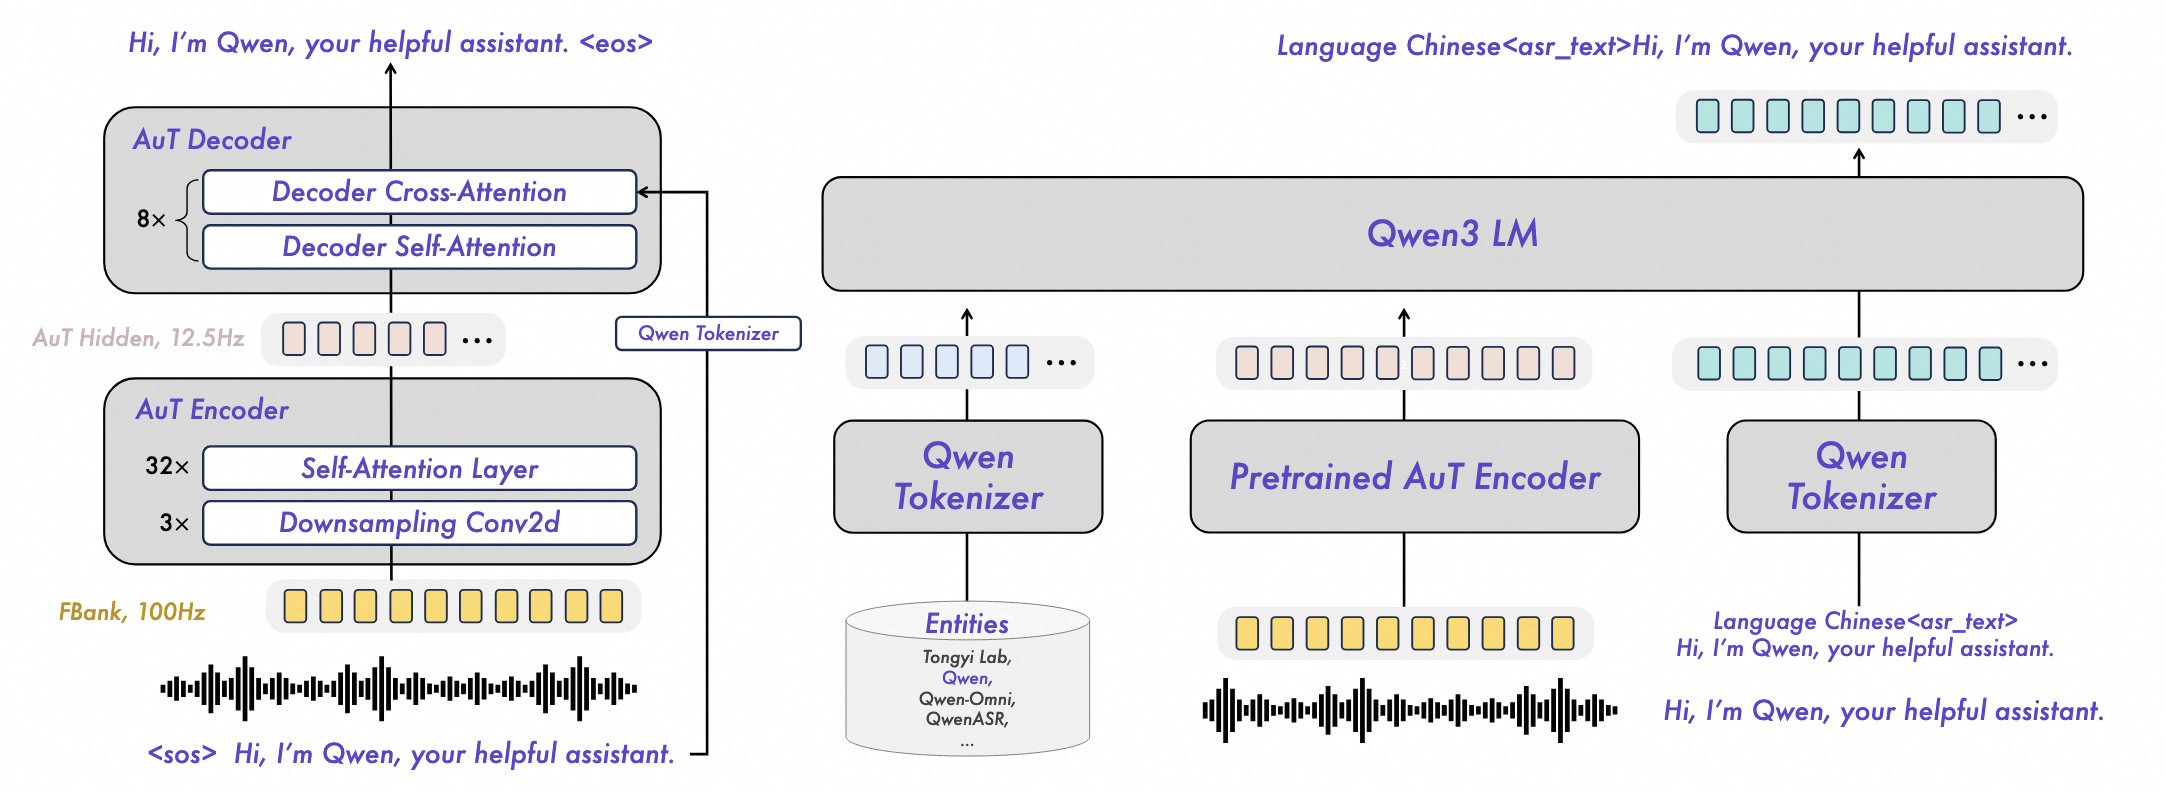
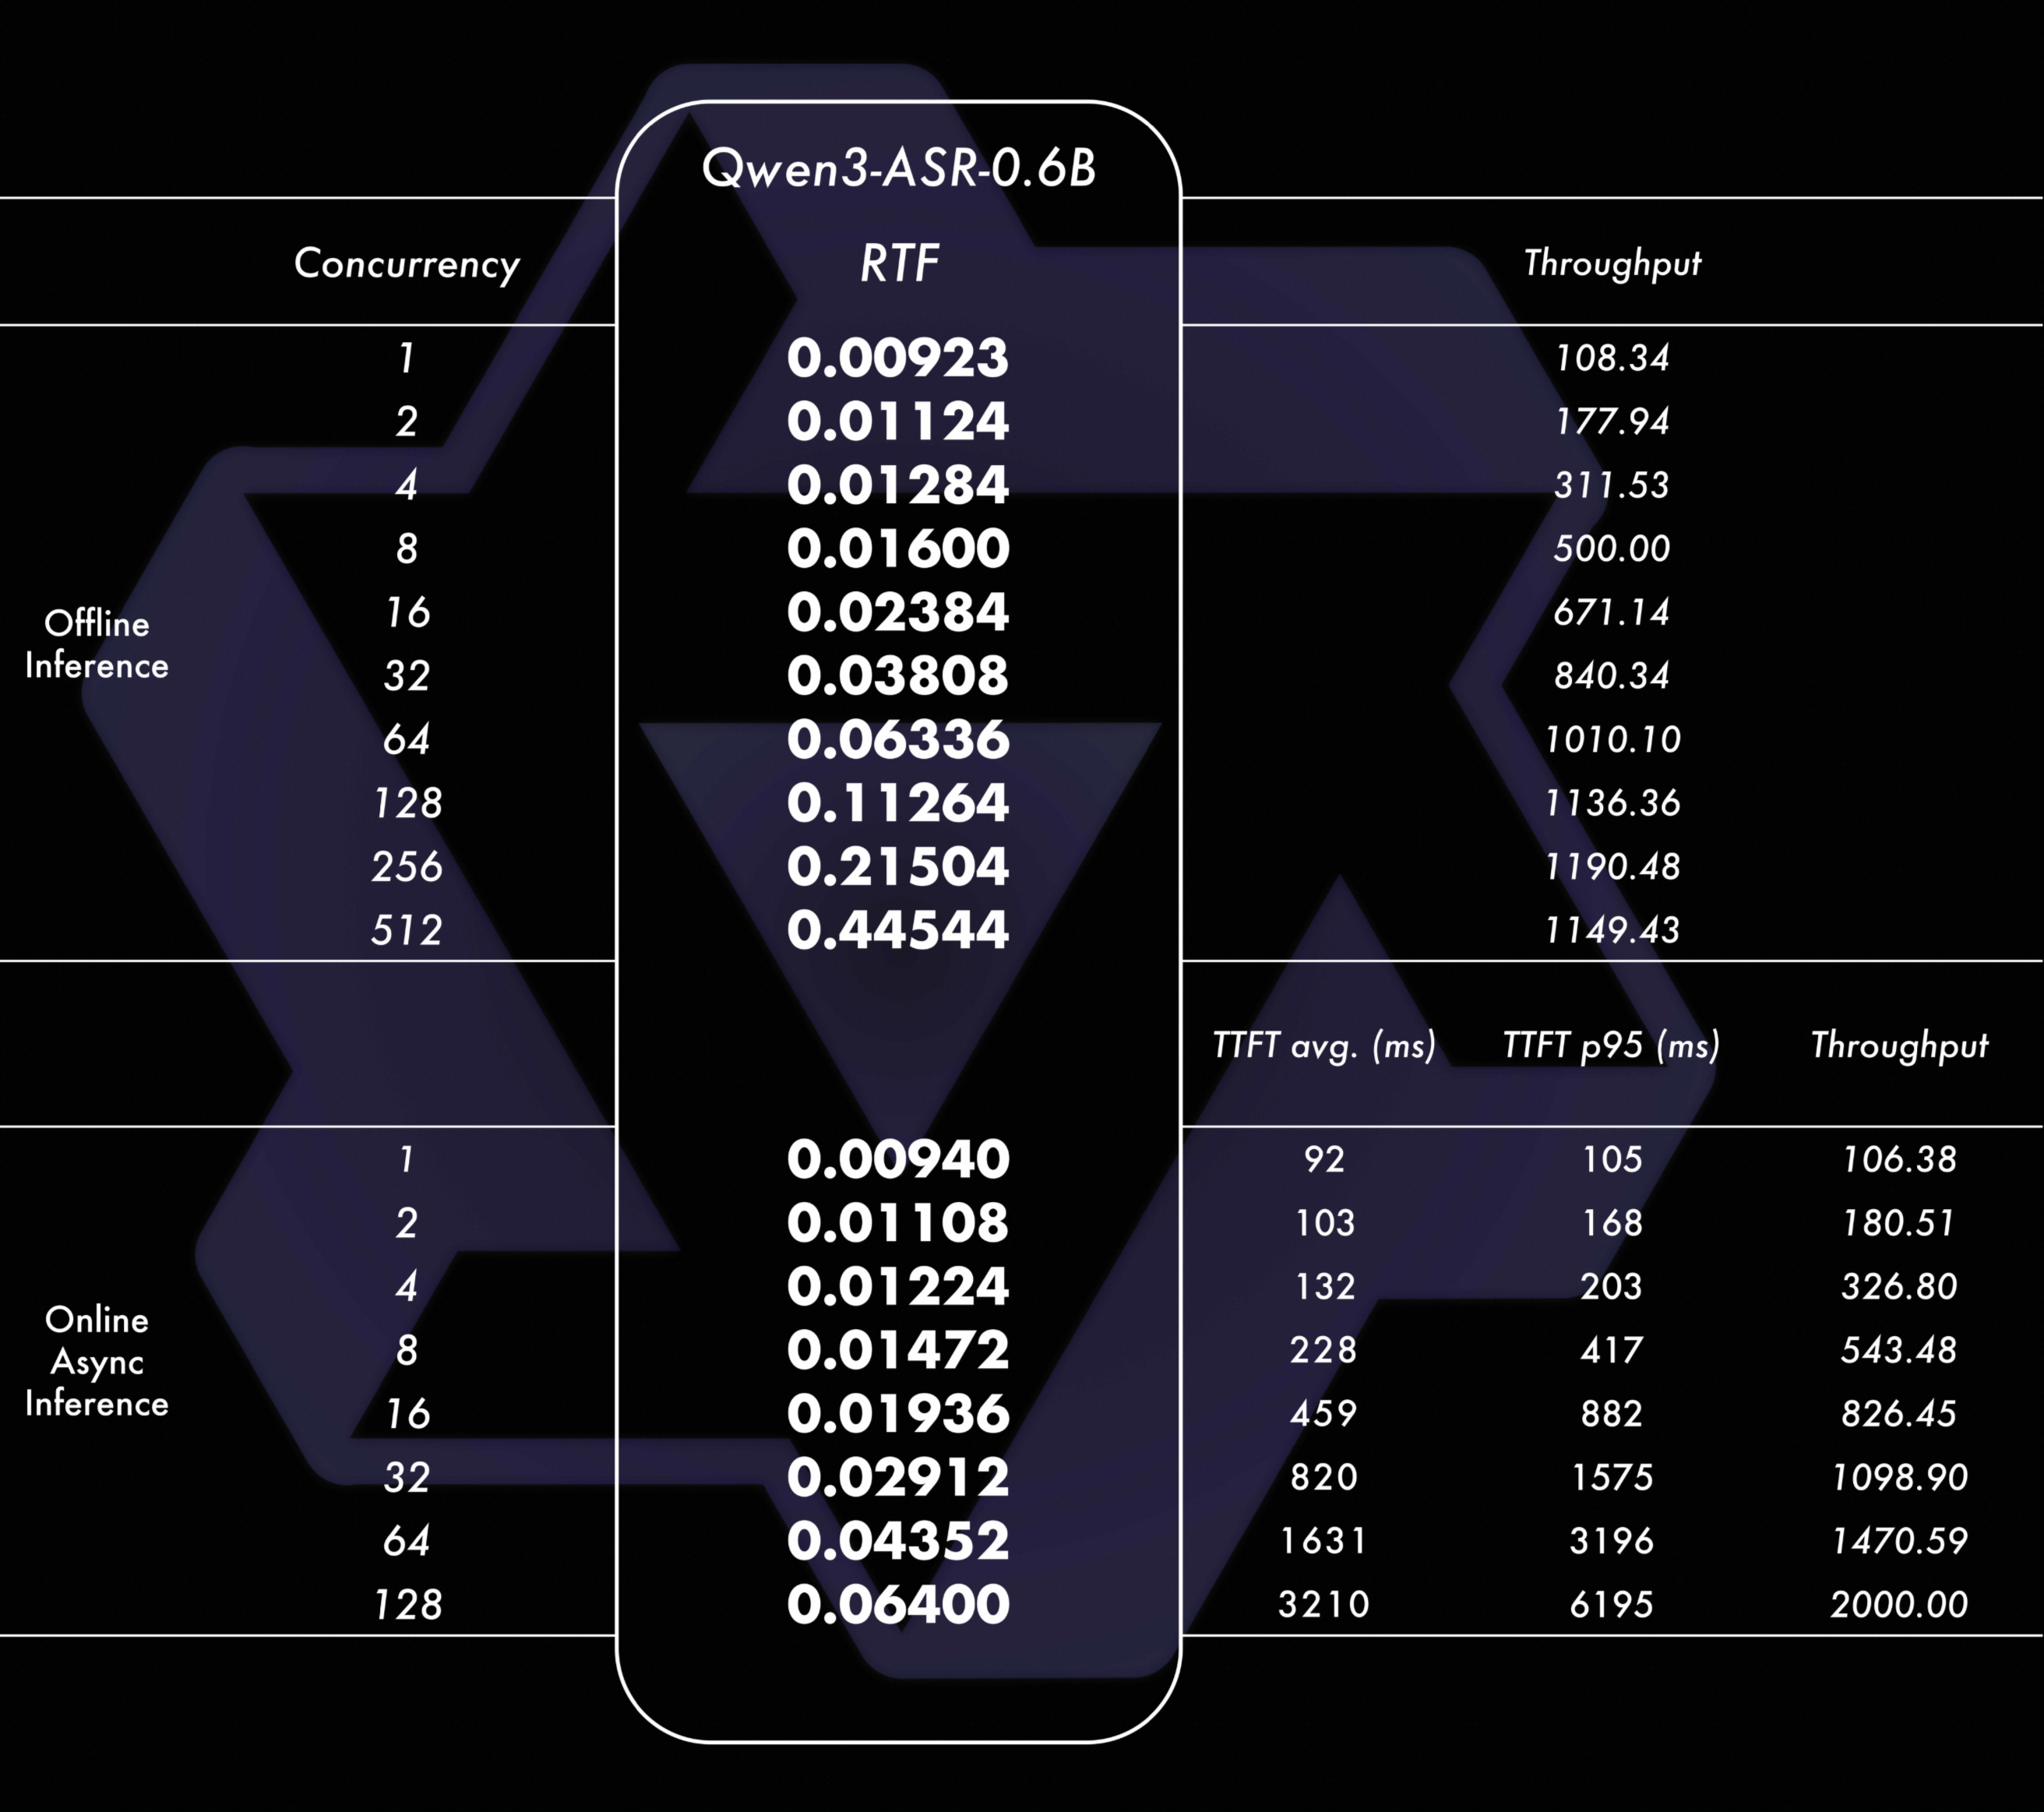
Qwen3-ASR family includes two powerful all-in-one speech recognition models and a novel non-autoregressive speech forced alignment model. Qwen3-ASR-1.7B and Qwen3-ASR-0.6B are ASR models that support language identification and ASR for 52 languages and accents. Both of them leverage large-scale speech training data and the strong audio understanding ability of their foundation model Qwen3-Omni. We conduct comprehensive internal evaluation besides the open-sourced benchmarks as ASR models might differ little on open-sourced benchmark scores but exhibit significant quality differences in real-world scenarios. The experiments reveal that the 1.7B version achieves state-of-the-art performance among open-sourced ASR models and is competitive with the strongest proprietary commercial APIs while the 0.6B version offers the best accuracy–efficiency trade-off. Qwen3-ASR-0.6B can achieve an average time-to-first-token as low as 92 ms and transcribe 2,000 seconds speech in 1 second at online async mode and a concurrency of 128. Qwen3-ForcedAligner-0.6B is an LLM based NAR timestamp predictor that is able to align text-speech pairs in 11 languages. Timestamp accuracy experiments show that the proposed model outperforms the three strongest force alignment models and takes more advantages in efficiency and versatility. To further accelerat the community research of ASR and audio understanding, we open-source the weights of the three models so as to a powerful and easy-using inference-finetune framework under the Apache 2.0 license.
Model List
| Model | Supported Languages | Supported Dialects | Inference Mode | Audio Types |
|---|---|---|---|---|
| Qwen3-ASR-1.7B & Qwen3-ASR-0.6B | Chinese (zh), English (en), Cantonese (yue), Arabic (ar), German (de), French (fr), Spanish (es), Portuguese (pt), Indonesian (id), Italian (it), Korean (ko), Russian (ru), Thai (th), Vietnamese (vi), Japanese (ja), Turkish (tr), Hindi (hi), Malay (ms), Dutch (nl), Swedish (sv), Danish (da), Finnish (fi), Polish (pl), Czech (cs), Filipino (fil), Persian (fa), Greek (el), Hungarian (hu), Macedonian (mk), Romanian (ro) | Anhui, Dongbei, Fujian, Gansu, Guizhou, Hebei, Henan, Hubei, Hunan, Jiangxi, Ningxia, Shandong, Shaanxi, Shanxi, Sichuan, Tianjin, Yunnan, Zhejiang, Cantonese (Hong Kong accent), Cantonese (Guangdong accent), Wu language, Minnan language. | Offline / Streaming | Speech, Singing Voice, Songs with BGM |
| Qwen3-ForcedAligner-0.6B | Chinese, English, Cantonese, French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish | – | NAR | Speech |
Qwen3-ASR Key Features
Main Features:
- All-in-one: Qwen3-ASR-1.7B and Qwen3-ASR-0.6B support language identification and speech recognition for 30 languages and 22 Chinese dialects, so as to English accents from multiple countries and regions.
- Excellent and Fast: The Qwen3-ASR family ASR models maintains high-quality and robust recognition under complex acoustic environments and challenging text patterns. Qwen3-ASR-1.7B achieves strong performance on both open-sourced and internal benchmarks. While the 0.6B version achieves accuracy-efficient trade-off, it reaches 2000 times throughput at a concurrency of 128. They both achieve streaming / offline unified inference with single model and support transcribe single long audio up to 20 minutes.
- Novel and strong forced alignment Solution: We introduce Qwen3-ForcedAligner-0.6B, which supports timestamp prediction for arbitrary units within up to 5 minutes of speech in 11 languages. Evaluations show its timestamp accuracy surpasses E2E based forced-alignment models.
- Comprehensive inference toolkit: In addition to open-sourcing the architectures and weights of the Qwen3-ASR series, we also release a powerful, full-featured inference framework that supports vLLM-based batch inference, asynchronous serving, streaming inference, timestamp prediction, and more.
ASR Model Performance
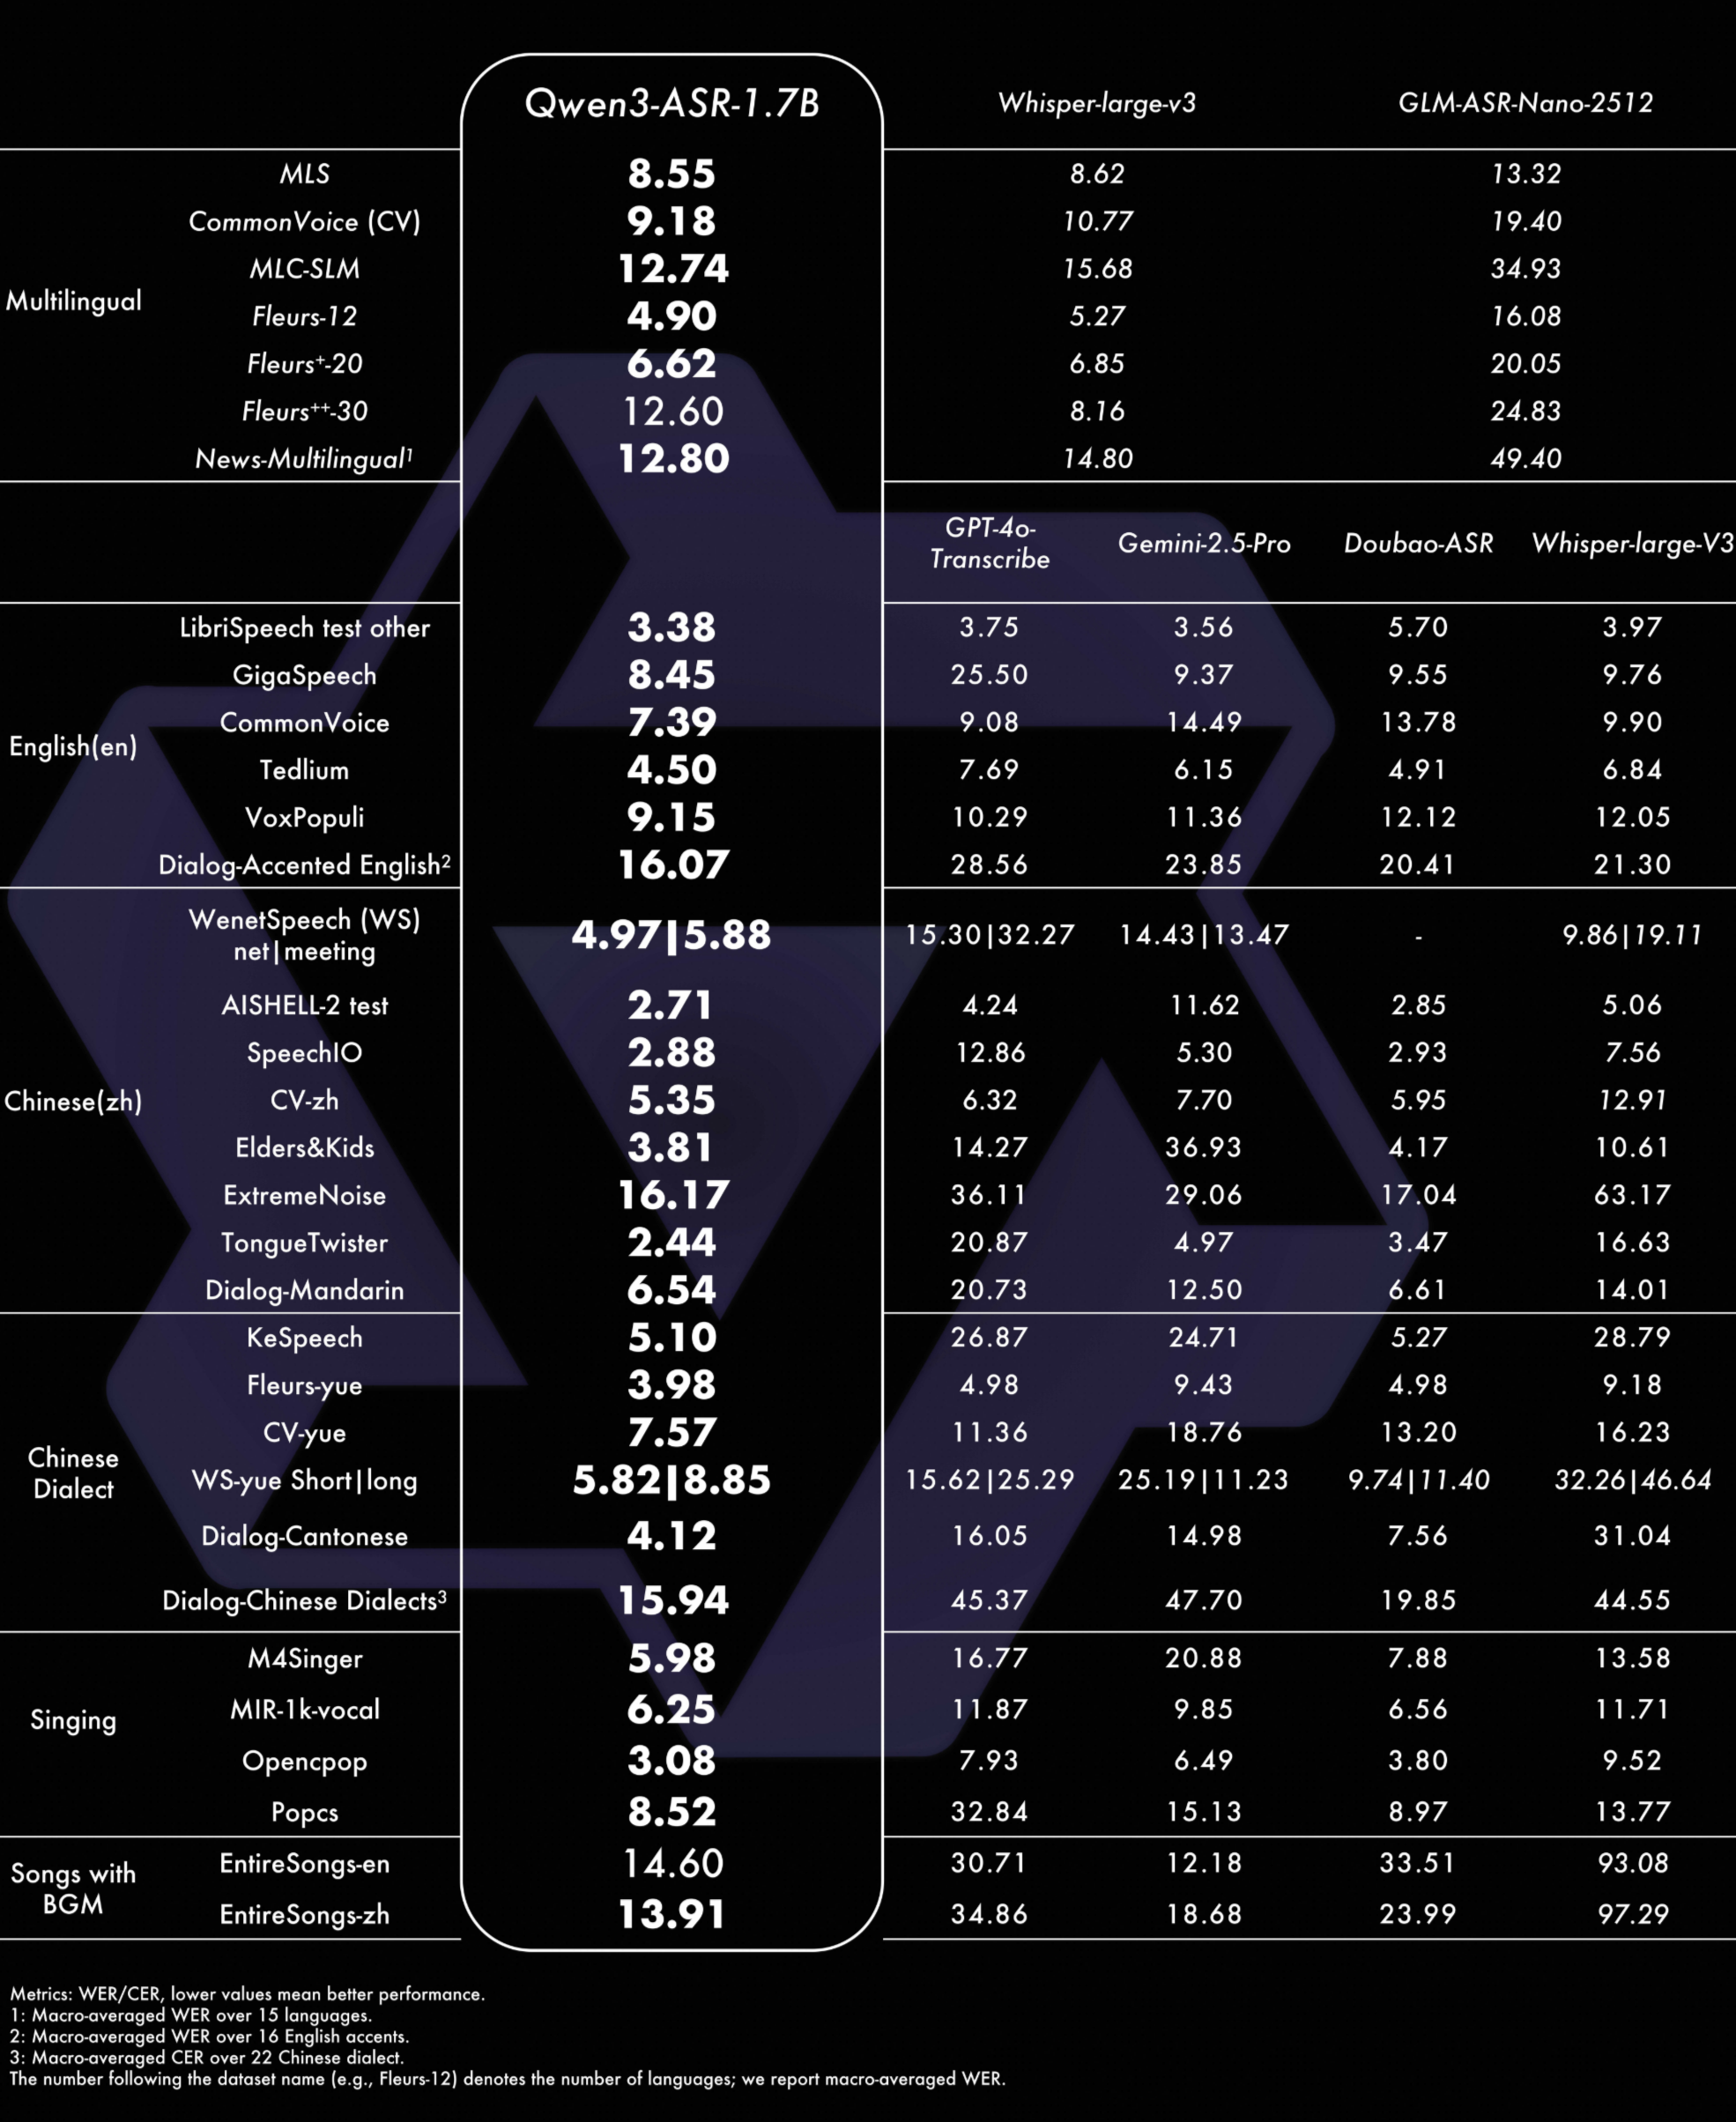
We conducted a systematic evaluation of the Qwen3-ASR series across Chinese/English, multilingual settings, Chinese dialects, singing voice recognition, and challenging acoustic and linguistic scenarios. The results show that Qwen3-ASR-1.7B achieves open-source SOTA on multiple public and internal benchmarks across several dimensions. Moreover, compared with the latest ASR APIs from multiple commercial providers, it also delivers the best performance on a number of benchmarks. Specifically:
- English: In addition to achieving top performance on common public benchmarks, we evaluated on an internally built English test set covering accents from 16 countries. Overall, it consistently outperforms GPT-4o Transcribe, the Gemini series, the Doubao ASR series, and the strongest general-purpose open-source model, Whisper-large-v3.
- Multilingual: Supports up to 30 languages. On 20 major languages, Qwen3-ASR-1.7B surpasses existing open-source models across the board, achieving the best average WER.
- Chinese and dialects: On Mandarin, Cantonese, and 22 regional dialects, Qwen3-ASR-1.7B overall leads both commercial APIs and open-source models.
- Challenging acoustic/linguistic scenarios: It remains stable and produces reliable outputs under challenging conditions such as elderly/child speech, extremely low SNR, maintaining very low character/word error rates.
- Singing voice recognition: Supports full-song transcription (Chinese/English) with background music (BGM); it achieves average WERs of 13.91% (Chinese) and 14.60% (English), respectively.
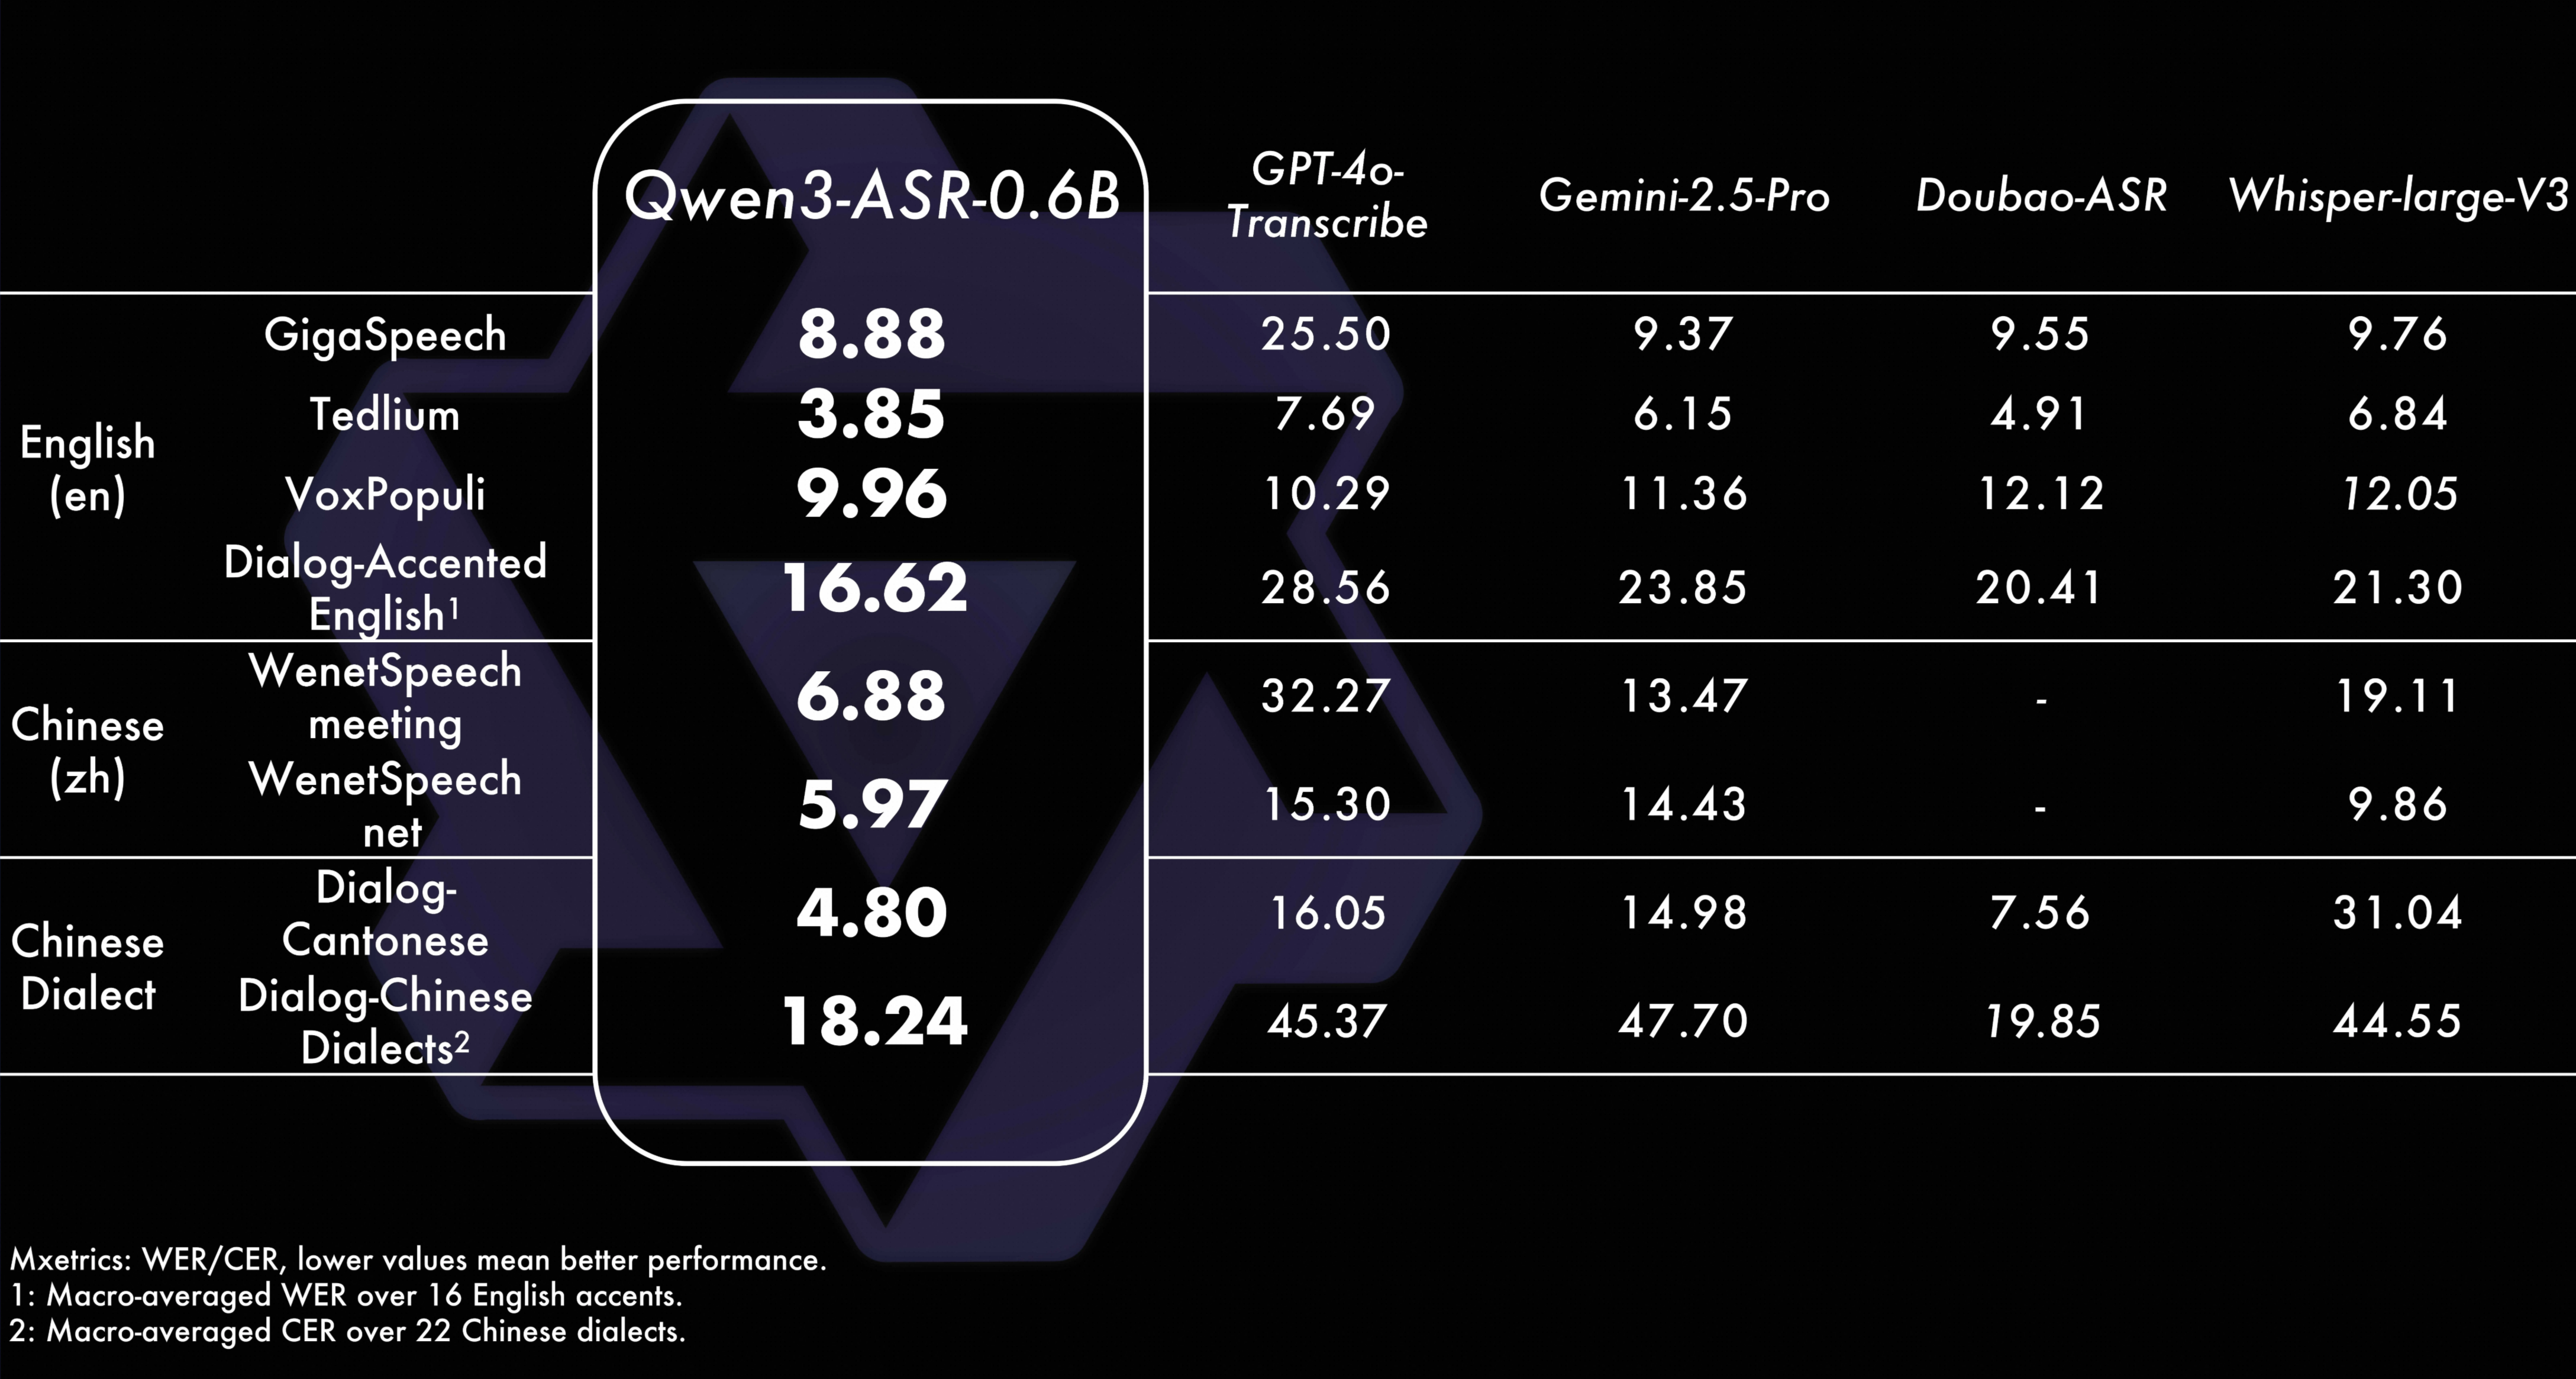
Qwen3-ASR-0.6B strikes a strong balance between accuracy and efficiency: it delivers robust performance on multiple Chinese and English benchmarks, and maintains extremely low RTF and high throughput under high concurrency in both offline batch and online async inference. At concurrency 128, Qwen3-ASR-0.6b can transcribe 5 hours speech at online async mode.
FA Model Performance
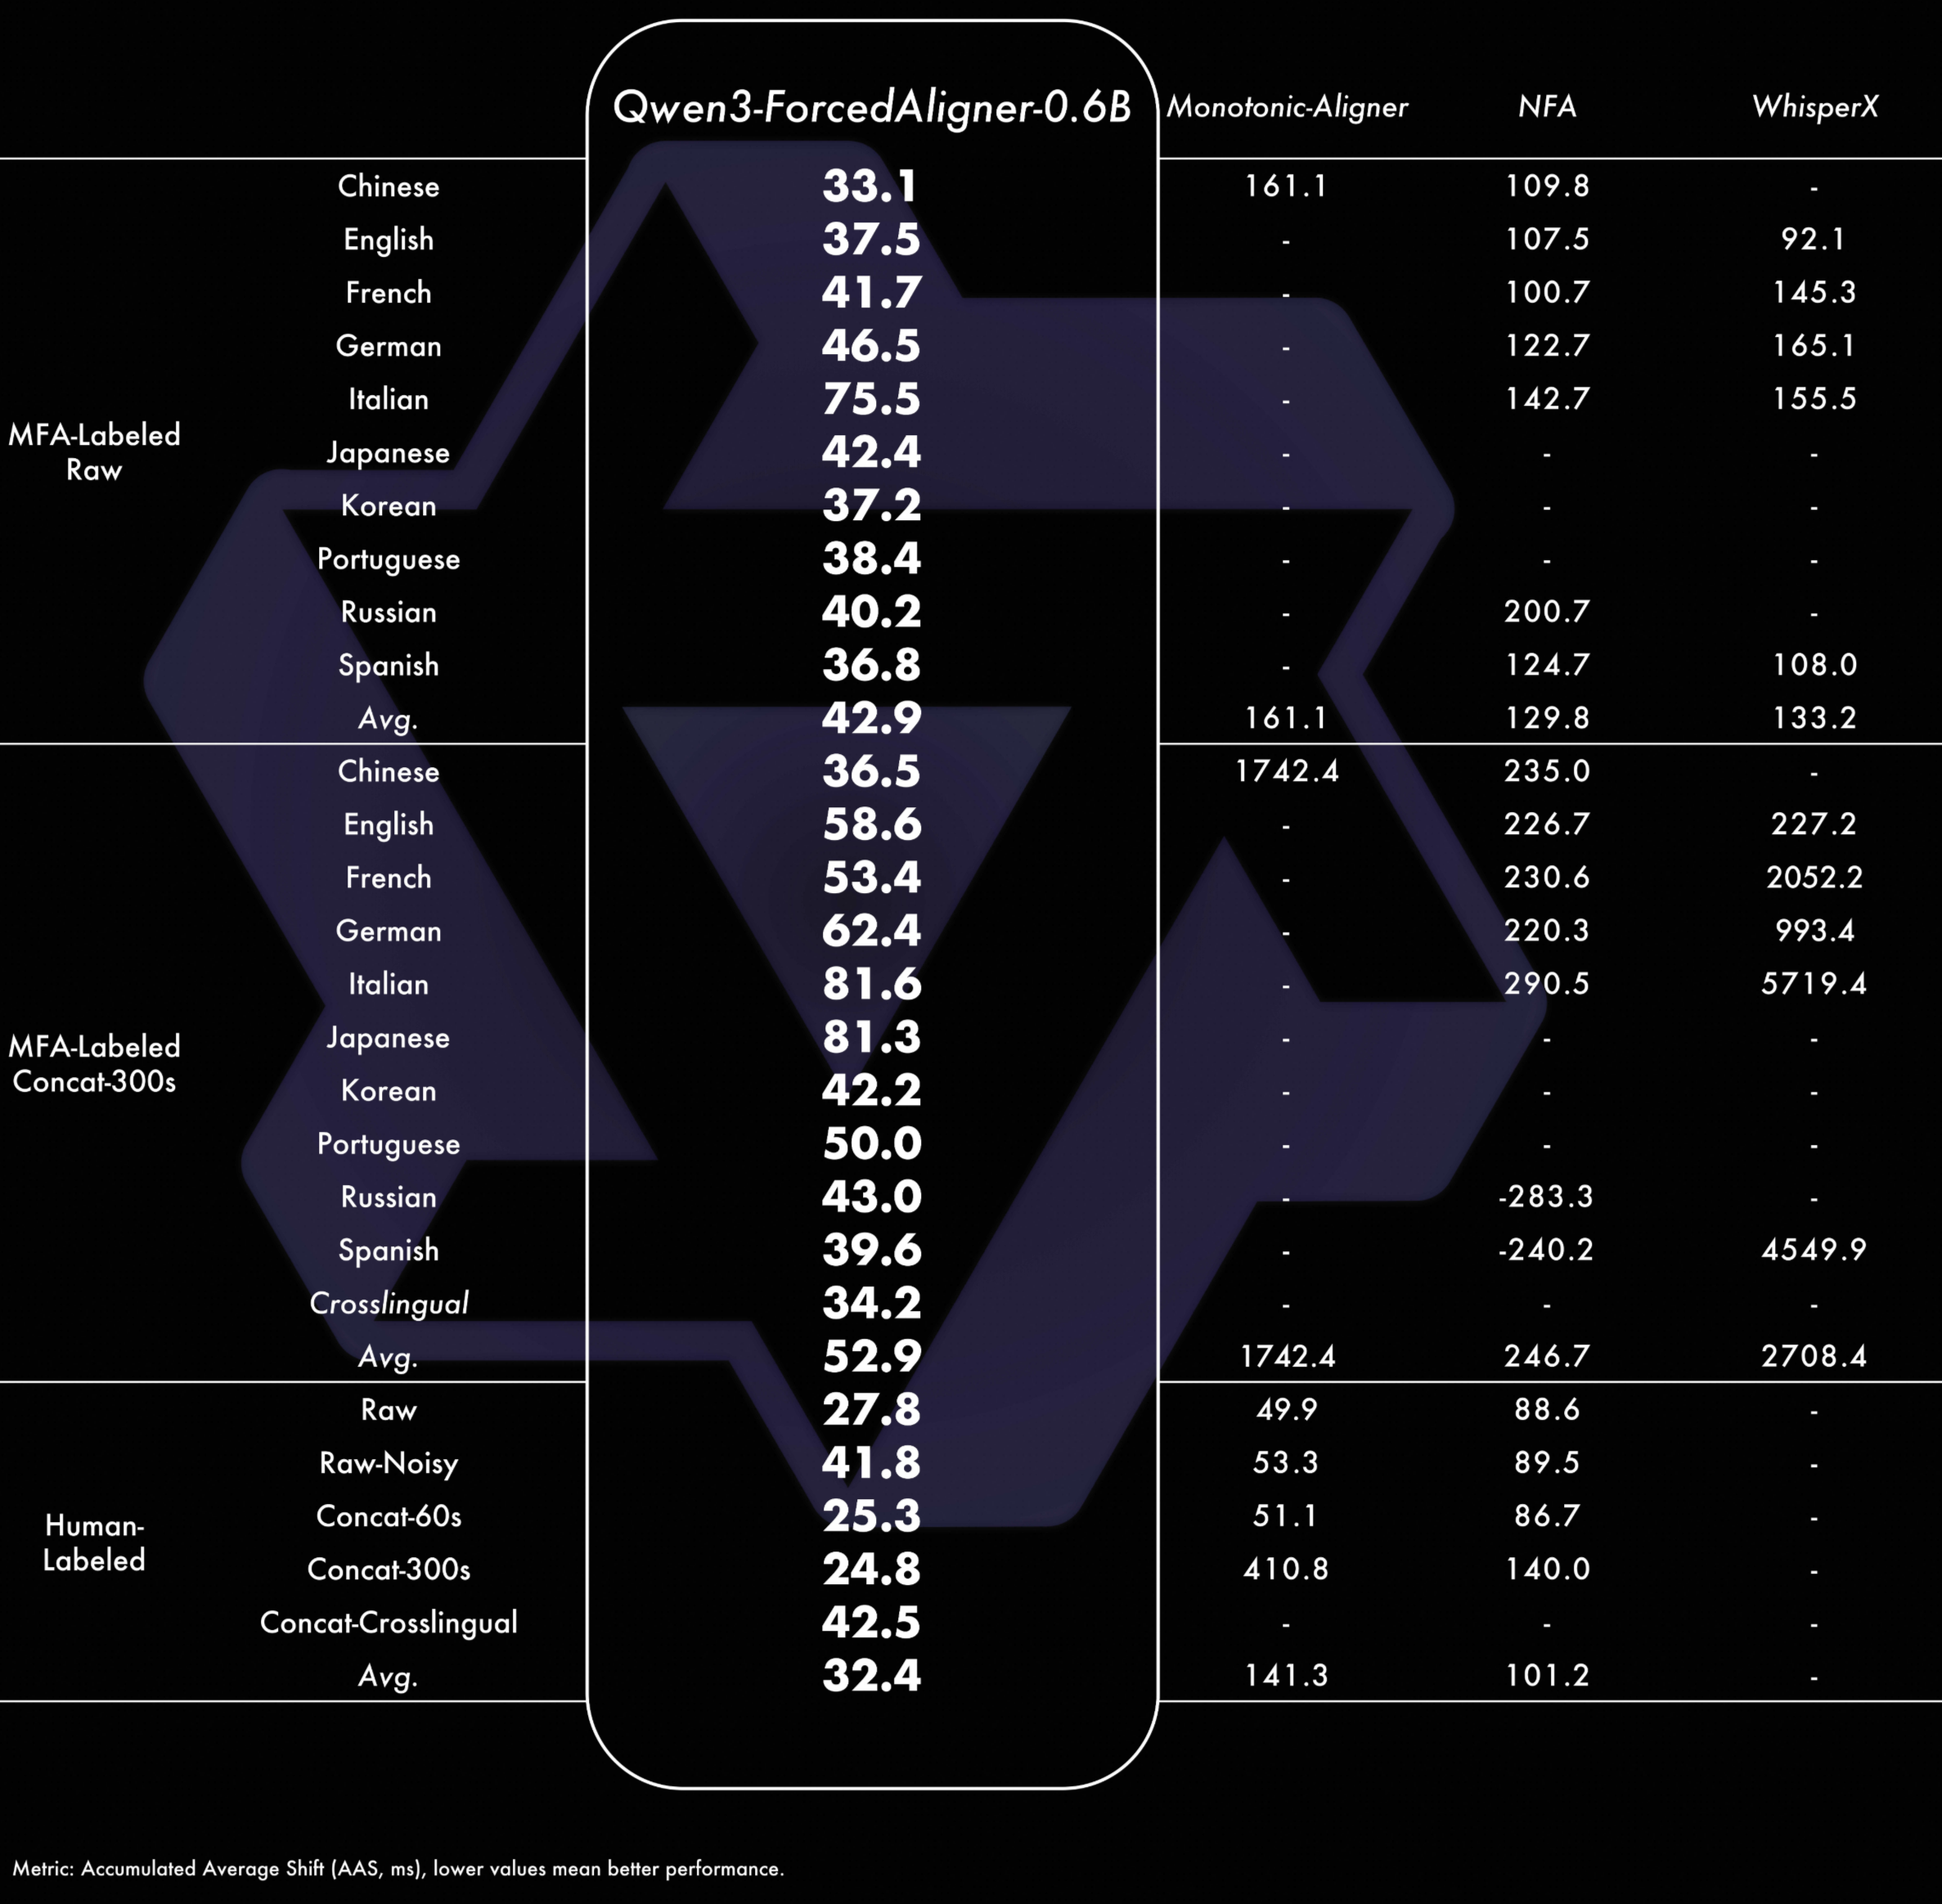
Qwen3-ForcedAligner-0.6B outperforms Nemo-Forced-Aligner, WhisperX and Monotonic-Aligner, which are three strong E2E based forced-alignment models. And it is also proved of taking great advantages on aspects of language coverage, timestamp accuracy, speech and audio length supported.
Find more detailed results in our paper.
Read previous post:
Read next post:
OpenClaw Launches on Alibaba Cloud Simple Application Server
-

-
Alibaba Cloud Community
1,605 posts | 526 followers
Follow
Comments
-
-
Alibaba Cloud Community
1,605 posts | 526 followers
Follow
Related Products
-
 QwenWork
 is dedicated to helping employees strengthen their professional competitiveness in the AI era and to enabling enterprises to improve organizational effectiveness.
Learn More -
 Token Plan
Build more, spend less. One plan, every modality.
Learn More -
Alibaba Cloud Model Studio
A one-stop generative AI platform to build intelligent applications that understand your business, based on Qwen model series such as Qwen-Max and other popular models
Learn More -
 Qoder
From Assisted to Autonomous — Adapting to Every Programming Need
Learn More
More Posts by Alibaba Cloud Community
- The Easiest Way to Try the Latest Models in One Place: Token Plan Starting at $3 for the First Month
- 一個平台輕鬆試用最新 AI 模型:Token Plan 首月低至 $3
- Alibaba Cloud Advances AI Adoption in Malaysia with Nationwide Youth Contest and Industry Collaborations
- Alibaba Cloud Unveils New AI Initiatives at Hong Kong Summit to Advance the City’s AI Ecosystem
- QoderWake: Digital Workers Take the Initiative — No Need to @ Every Time
- What Is Model Thinking Effort? Should You Choose Low, High, or Maximum?
- High-Risk PHP and Node.js Vulnerabilities: A Scan Costs Pennies. A Miss Could Cost a Fortune.
- Alibaba Unveils Qwen4-Max: New AI Teammate for Work, Creativity, and Discovery
- Alibaba Brings Cloud and AI to the First Youth Olympic Games in Africa
- Introducing Qoder Lite: Start creating with Qoder for $10 a month