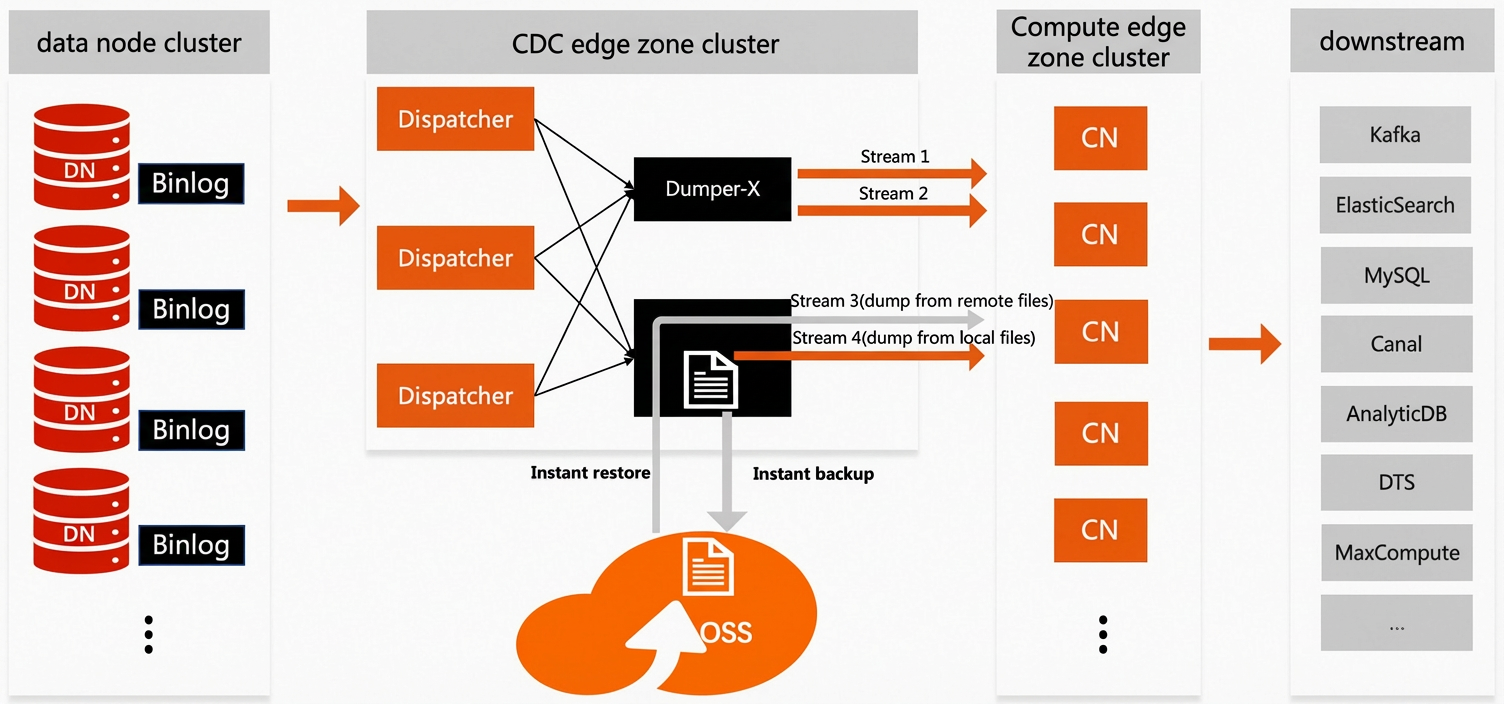
PolarDB-X provides two types of binary log (binlog) subscription services. You can use both types at the same time.
Single-stream (Global Binlog): This service merges the binary logs from all data nodes (DNs) into a single, global queue. This creates a log stream that guarantees transactional integrity and order. It provides strong data consistency. For example, in a fund transfer scenario, a downstream MySQL database connected to PolarDB-X can query a consistent balance at any time using Global Binlog.
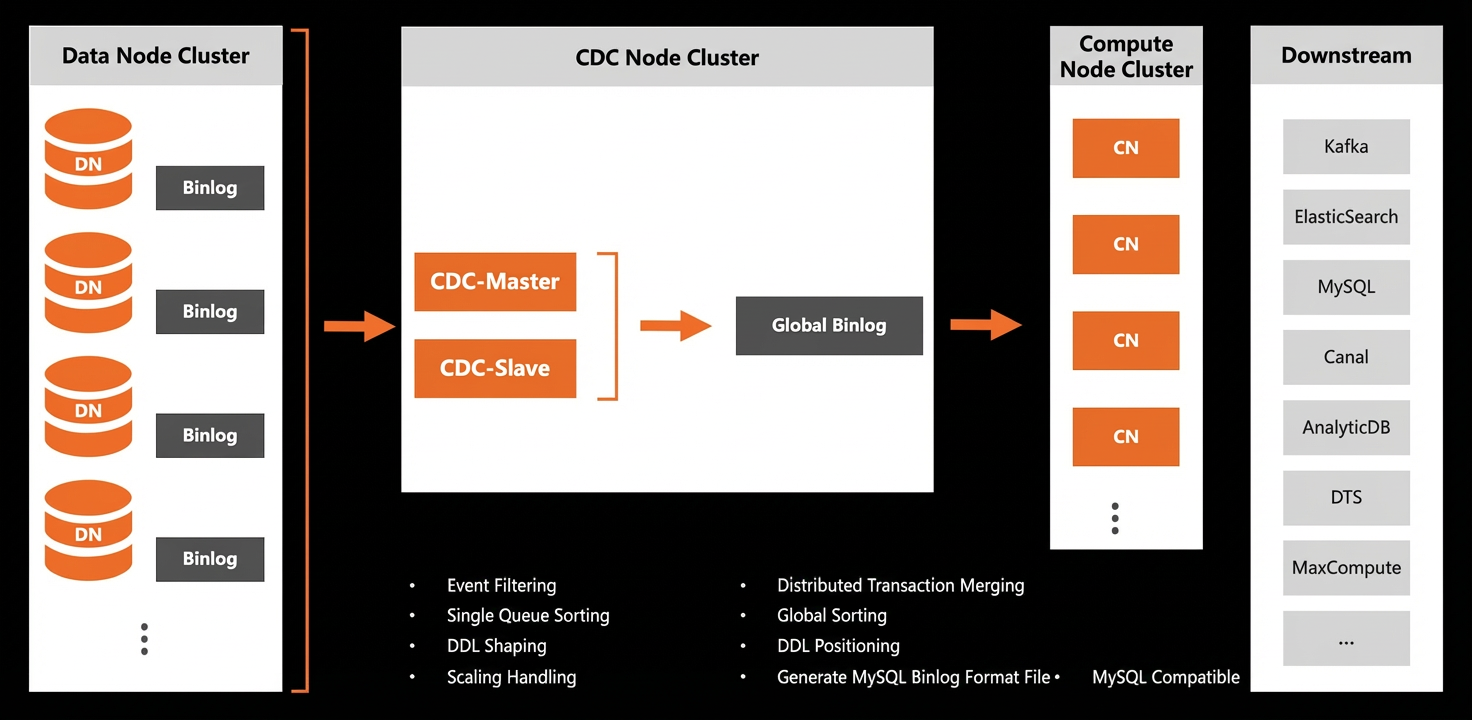
Multi-stream (Binlog-X): This service does not merge the binary logs from all DNs into a single queue. Instead, it hashes and distributes data across multiple log streams. This approach sacrifices some transactional integrity for greater extensibility. It addresses the single-point bottleneck issue that occurs in single-stream binary logging for large-scale clusters.
Single-stream binlog
This service merges the original binlog files from all DNs into a single queue. It then sorts and merges them, removes internal details, and provides a log stream compatible with the MySQL binlog format and dump protocol. When you purchase a PolarDB-X instance, the single-stream binlog service is enabled by default.
Notes
The Change Data Capture (CDC) master node and secondary node replicate binlog files between them. This ensures the data is identical on both nodes. Downstream systems can then subscribe to changes using a filename and position. If a primary/secondary switchover occurs, the filename and offset remain the same.
Distributed transactions are merged only when the transaction policy is set to Timestamp Oracle (TSO). Otherwise, only eventual consistency is guaranteed. The default transaction policy for PolarDB-X is TSO.
To change the partition key value for a data row, you must perform the operation within a distributed transaction that uses the TSO policy. This ensures that the delete event appears in the binlog before the insert event, which maintains data consistency. To do this, perform one of the following operations:
Execute an `UPDATE` SQL statement to modify the partition key value.
Execute a `REPLACE` SQL statement to modify the partition key value.
Explicitly start a transaction, execute a `DELETE` statement, and then execute an `INSERT` statement with the new partition key value.
Multi-stream binlog
Multi-stream binlog is fully compatible with the MySQL binlog file format and dump protocol. You can treat each binlog stream as a standalone MySQL instance. For a single log stream, you can execute SQL commands such as `CHANGE MASTER TO...` and `SHOW BINLOG EVENTS...` to consume or view binlog data.
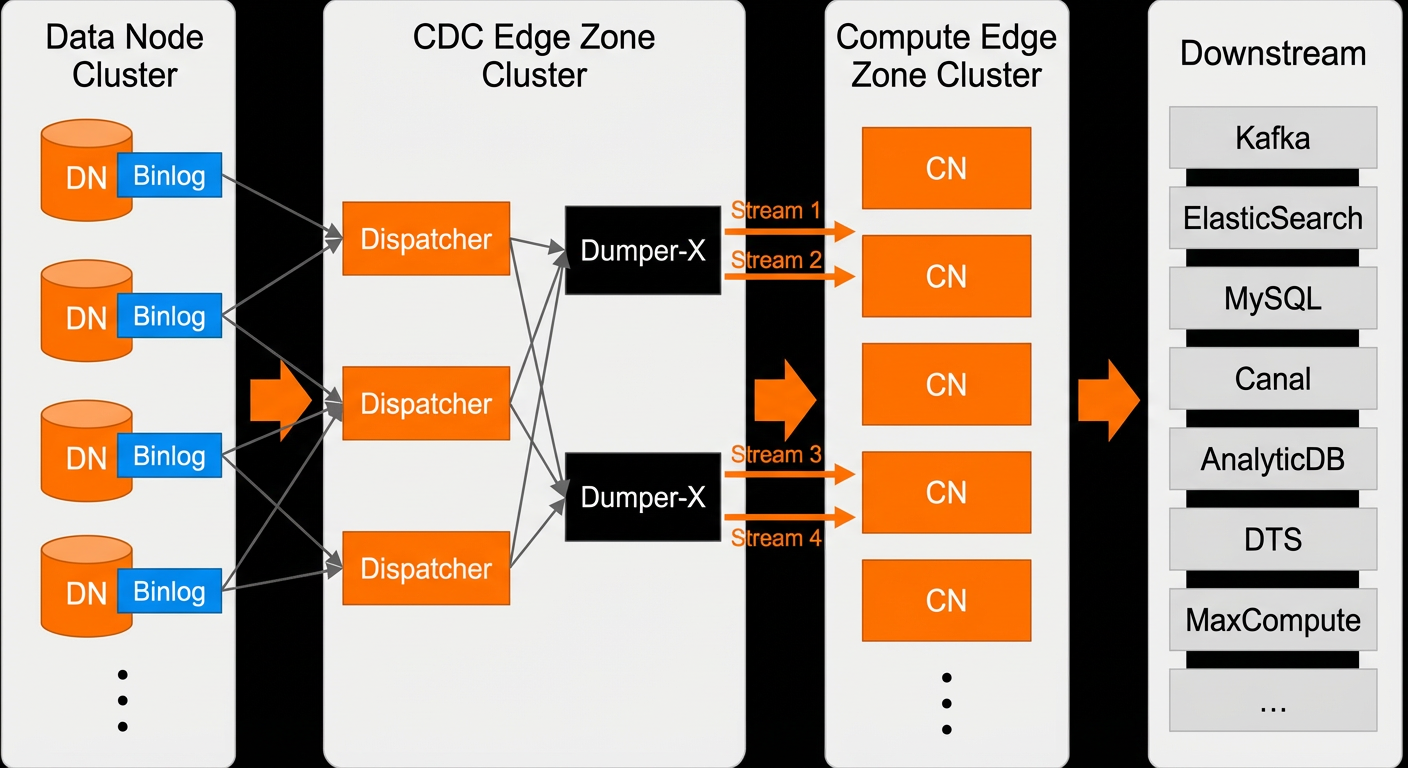
The multi-stream service is not enabled by default. You must enable it in the console. For a single PolarDB-X instance, you can enable multiple multi-stream services at the same time. Different services are completely isolated from each other. Each service can have its own stream count, data split level, and parameter rules. You can enable different types of multi-stream services as needed.
Split levels
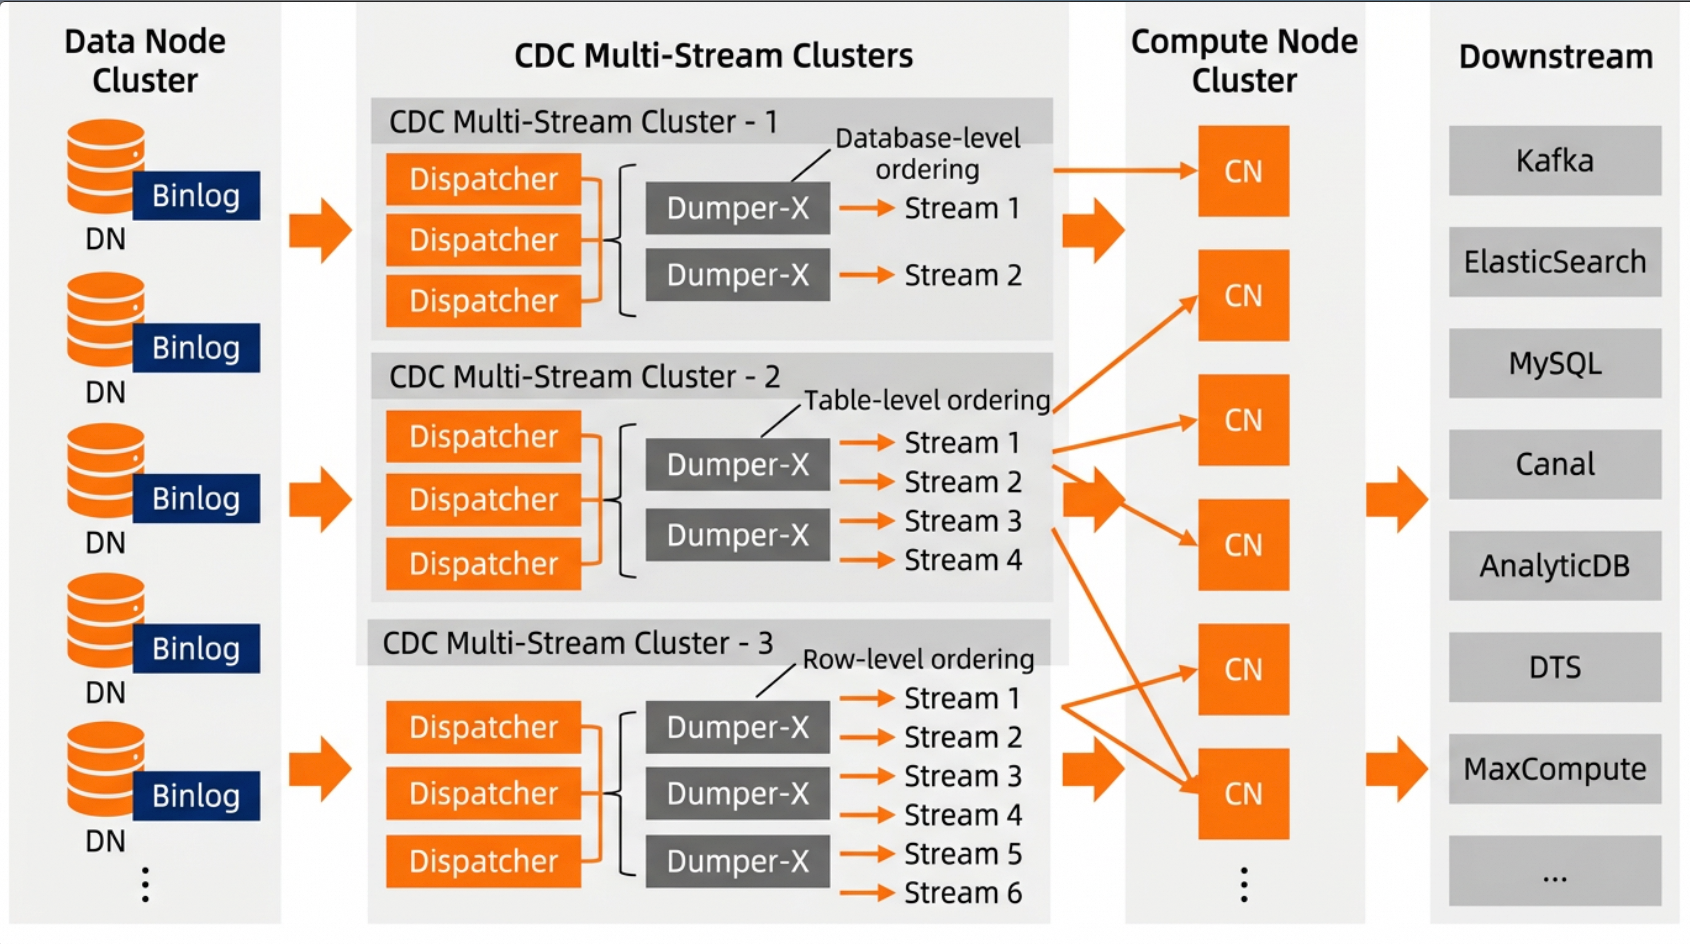
Multi-stream binlog provides three data split levels. You can set the level when you enable the multi-stream service to meet different scenario requirements.
Database-level order
Data is distributed based on a hash value calculated from the database name. This means binlog data for the same database is always routed to the same binlog stream in order. This is suitable for scenarios where a single PolarDB-X instance has many databases. If transactions do not involve cross-database operations, this policy provides both multi-stream capabilities and transactional integrity.
Table-level order
Data is distributed based on a hash value calculated from the table name. This means binlog data for the same table is always routed to the same binlog stream in order. This is suitable for scenarios with many tables where you want operations on a single table, such as DML or DDL, to remain ordered in the binlog stream.
Row-level order
Data is distributed based on a hash value calculated from the primary key of the data row. This means binlog data for the same data row is always routed to the same binlog stream in order. This is suitable for scenarios where you want to distribute data widely and do not require log data to be ordered by database or table. This policy requires tables to have a primary key. Data from tables without a primary key is discarded.
You can configure the split level at two layers: the service layer and the database/table layer. Once a configuration is set at any layer, you cannot modify it. Modifying it would cause the same data to "drift" between different streams, leading to data consistency issues. Therefore, before you enable the multi-stream service, you must evaluate your business scenario and plan the split level in advance.
Service layer
This is the default split level for the multi-stream service. If you do not set a specific split level for a database or table, the service-level default configuration is used.
Database/table layer
You can set a separate split level for a specific database or table. This configuration overrides the service-level configuration to meet specific needs.
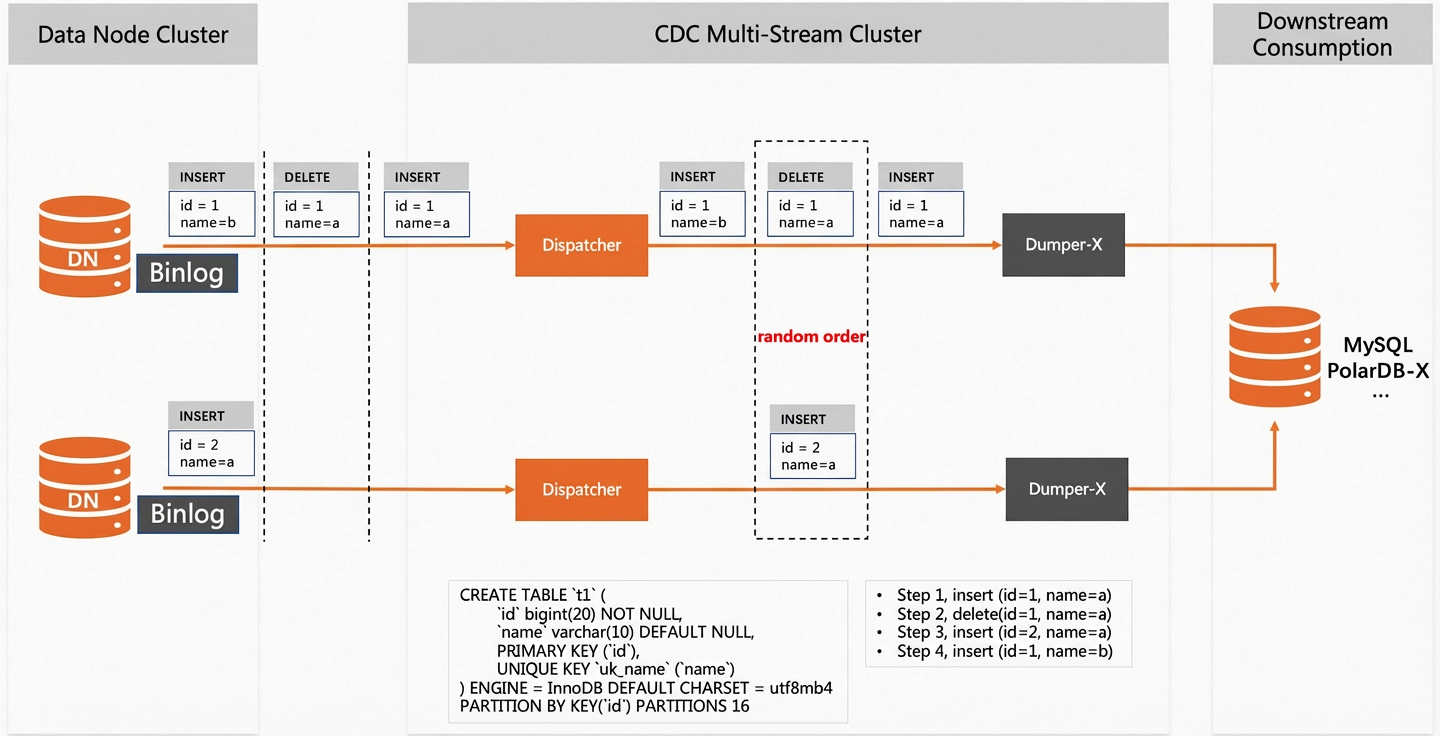
A limitation exists when you use the row-level order split level. If a table has a unique key constraint and a unique key swap occurs, distributing data by row-level order can cause data consistency issues. As shown in the following figure, the unique key value `uk(name)=a` is first held by the row with `id=1` and then by the row with `id=2`. However, the execution order of `delete(id=1,name=a)` and `insert(id=2,name=a)` in the destination database cannot be guaranteed. If `insert(id=2,name=a)` is executed before `delete(id=1,name=a)`, a write conflict occurs. If you have a similar scenario, use the table-level order split level.
Notes
After you create a multi-stream service, you cannot change the number of streams. You must plan the number of streams in advance. We recommend that the number of streams is greater than or equal to the number of DNs.
After you create a multi-stream service, you cannot change the effective split level. You must plan the split level in advance.
If you add a new data table and want to set a separate split level for it, you must configure the level before any data is written to the table.
When you use the table-level order split level, you can still rename the table. The system always distributes data based on the initial table name.
When you use the table-level order split level, you can set a separate routing rule to avoid data skew. Data skew occurs when data from large tables is concentrated in a few streams.
If you want to adjust the number of streams or the effective data split level, you can create a new multi-stream service to replace the existing one. This requires some Operations and Maintenance (O&M) adjustments to the downstream consumption pipeline.
The following table describes how Data Definition Language (DDL) statements are distributed across binlog streams.
Split level
Distribution method
Description
Database level
Unicast + Broadcast
DDL statements for `CREATE DATABASE` and `DROP DATABASE` are broadcast to every binlog stream. This is because you can set a separate split level for a table within a database. Therefore, creating and dropping databases must use broadcasting.
Other types of DDL statements are unicast to a specific binlog stream.
Table level
Unicast + Broadcast
DDL statements for `CREATE DATABASE` and `DROP DATABASE` are broadcast to every binlog stream. This is because you can set a separate split level for a table within a database. Therefore, creating and dropping databases must use broadcasting.
Other types of DDL statements are unicast to a specific binlog stream.
Row level
Broadcast
All types of DDL statements are broadcast to every binlog stream.
Transparent binlog consumption
CDC first saves the generated binlog files to a local disk. It also supports real-time uploads to remote storage, such as Object Storage Service (OSS). Files on the local disk have a short retention period. Files in remote storage have a longer retention period, such as 15 days. For files on remote storage, CDC provides transparent consumption. This masks the storage differences between local and remote locations. Downstream systems do not require any modifications to access binlog data on remote storage. Transparent consumption is supported starting from CDC version 2.0.0.