Tunnel Client is the automated data consumption framework for Tunnel Service. Before you use Tunnel Service, you need to understand the automated data processing flow, automatic load balancing, horizontal extensibility, and automated resource cleanup and fault tolerance of Tunnel Client.
Background information
Tunnel Client resolves common issues in full and incremental data processing, such as load balancing, fault recovery, checkpoints, and partition information synchronization, to ensure that data is consumed in order. When you use Tunnel Client, you only need to focus on the processing logic for each record.
For the Tunnel Client code, see GitHub.
Automated data processing flow
Tunnel Client uses periodic heartbeats to detect active channels, update the status of channels and ChannelConnects, and manage the initialization, execution, and termination of data processing tasks.
-
Initialize Tunnel Client resources
-
Change the Tunnel Client status from Ready to Started.
-
Perform the ConnectTunnel operation based on configurations in TunnelWorkerConfig, such as HeartbeatTimeout and ClientTag (client ID). This operation connects to the Tunnel server-side to obtain the ClientId for the current Tunnel Client.
-
Initialize ChannelDialer to create new ChannelConnects.
Each ChannelConnect corresponds to a single channel. The ChannelConnect records the data consumption offset.
-
Create a data processor with an automatic checkpoint feature. This feature uses the data processing callback provided by the user and the CheckpointInterval from TunnelWorkerConfig. The CheckpointInterval is the interval for recording the data offset to the server-side.
-
Initialize TunnelStateMachine for automated processing of the channel state machine.
-
-
Send heartbeats at fixed intervals
The heartbeat interval is determined by the heartbeatIntervalInSec parameter in TunnelWorkerConfig.
-
Send a heartbeat request to retrieve the latest list of active channels from the Tunnel server-side. The list contains the channel ID, version, and status for each channel.
-
Merge the channel list from the server-side with the local channel list in memory. Then, create and update ChannelConnects based on the following rules:
-
Merge: Based on the latest channel list from the server-side, if a channel ID already exists, the entry with the higher version number overwrites the old one. If a channel does not exist, it is inserted.
-
Create a ChannelConnect: If a ChannelConnect does not exist for a channel, a new ChannelConnect is created in the WAIT state. If the corresponding channel is in the OPEN state, a data processing pipeline task (ReadRecords and ProcessRecords) is started on that ChannelConnect. For more information, see the ProcessDataPipeline class in the code.
-
Update an existing ChannelConnect: After the merge, if a ChannelConnect exists for a channel, its status is updated to match the channel's status. For example, if a channel is in the CLOSE state, the ChannelConnect status is also set to Closed. This terminates the data processing pipeline task. For more information, see the ChannelConnect.notifyStatus method in the code.
-
-
-
Channel state machine
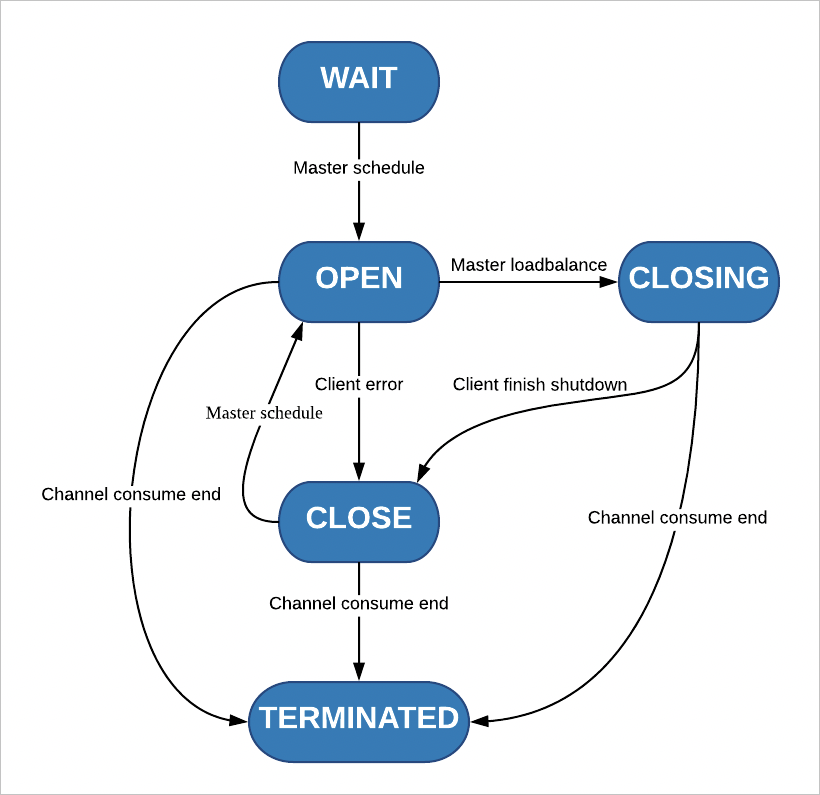
In heartbeat mode, the Tunnel server-side schedules consumable partitions to different Tunnel Clients based on the number of clients that send heartbeats. This achieves load balancing.
The Tunnel server-side uses a channel state machine to drive the consumption of each channel and perform load balancing, as shown in the following figure.
The Tunnel server-side and Tunnel Client communicate state changes through a mechanism of heartbeats and channel version number updates.
-
Each channel starts in the WAIT state.
-
An incremental channel must wait for the channel on its parent partition to finish consumption and enter the TERMINATED state. Then, the incremental channel can change to the consumable OPEN state.
-
Partitions in the OPEN state are scheduled to various Tunnel Clients.
-
When load balancing is required, the Tunnel server-side and Tunnel Client follow a scheduling protocol for channel state transitions: OPEN->CLOSING->CLOSED. After a Tunnel Client finishes consuming a full channel split or an incremental channel that has split, it reports the channel as TERMINATED.
-
Automatic load balancing and horizontal extensibility
-
When multiple Tunnel Clients consume the same tunnel (with the same TunnelId), the Tunnel server-side automatically reallocates channel resources during a client's heartbeat. Active channels are distributed as evenly as possible among all Tunnel Clients to achieve load balancing.
-
For horizontal extensibility, you can add more Tunnel Clients. The clients can run on the same machine or on different machines.
Automated resource cleanup and fault tolerance
-
Resource cleanup: If a Tunnel Client does not shut down normally, for example, due to an unexpected exit or manual termination, its resources are automatically reclaimed. This includes releasing the thread pool, calling the shutdown method registered on the channel, and closing the tunnel connection.
-
Fault tolerance: If a Tunnel Client encounters a non-parameter error, such as a heartbeat timeout, Tablestore automatically renews the connection. This ensures that data consumption continues to sync stably.