The hash join method, introduced in MySQL Community Edition 8.0, significantly improves the performance of analytical queries. PolarDB for MySQL 8.0 supports parallel execution for hash join with a growing set of strategies. This topic describes how to use the hash join feature for parallel queries in PolarDB.
Simple parallel hash join
Prerequisites
Your cluster must be a PolarDB for MySQL 8.0 Cluster Edition running revision version 8.0.2.1.0 or later. To check your version, see Query the engine version.
Parallel strategy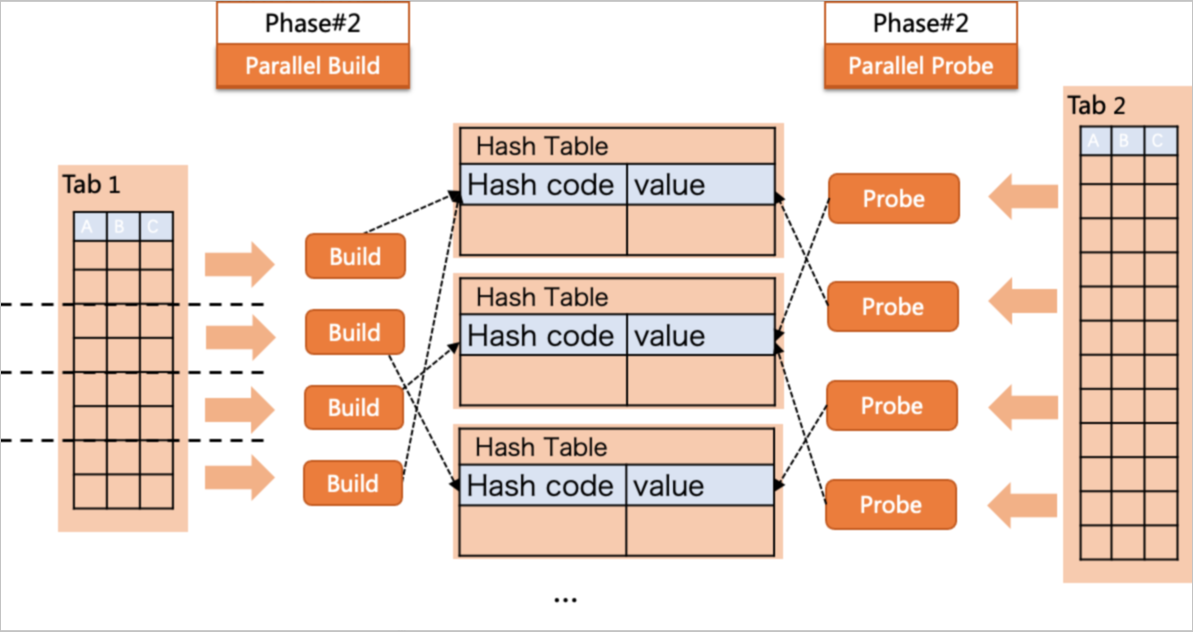
The figure shows an execution plan for a parallel query with a degree of parallelism (DOP) of 4. This means PolarDB uses four workers to concurrently scan different parts of the table t1. Each worker builds its own hash table using its portion of data from t1. These hash tables are then joined with the entire table t2. Finally, a leader gathers the results from all workers.
Usage
-
Syntax:
In PolarDB, use the
EXPLAIN FORMAT=TREEstatement to view thehash joinoperation in anexecution plan. -
Example:
The following example creates two
tablesand inserts sample data:CREATE TABLE t1 (c1 INT, c2 INT); CREATE TABLE t2 (c1 INT, c2 INT); INSERT t1(c1, c2) WITH RECURSIVE seq AS ( SELECT 1 AS a, 1 AS b UNION ALL SELECT a + 1, b + 1 FROM seq WHERE a < 1000 ) SELECT a,b FROM seq; INSERT INTO t2 SELECT * FROM t1;View the
execution planfor the SQL statement:EXPLAIN FORMAT=TREE SELECT /*+ PQ_DISTRIBUTE(t1 PQ_NONE) PQ_DISTRIBUTE(t2 PQ_NONE) */ * FROM t1 JOIN t2 ON t1.c1 = t2.c2;EXPLAIN FORMAT=TREE EXPLAIN -> Gather (slice: 1; workers: 4) (cost=10.82 rows=4) -> Parallel inner hash join (t2.c2 = t1.c1) (cost=0.57 rows=1) -> Parallel table scan on t2, with parallel partitions: 1 (cost=0.03 rows=1) -> Parallel hash -> Parallel table scan on t1, with parallel partitions: 1 (cost=0.16 rows=1)The preceding example shows a parallel execution plan with a degree of parallelism (DOP) of 4. This means that PolarDB starts four workers to execute the query. In this plan, the
t1table undergoes a Parallel Scan. The four workers scan different portions of this table. Each worker uses its portion of data fromt1to build a hash table and then performs a JOIN operation with the entiret2table. Finally, the leader gathers the results from all workers to produce the final query result.
Shuffle hash join
Prerequisites
Your cluster must be a PolarDB for MySQL 8.0 Cluster Edition running revision version 8.0.2.2.0 or later. To check your version, see Query the engine version.
Parallel strategy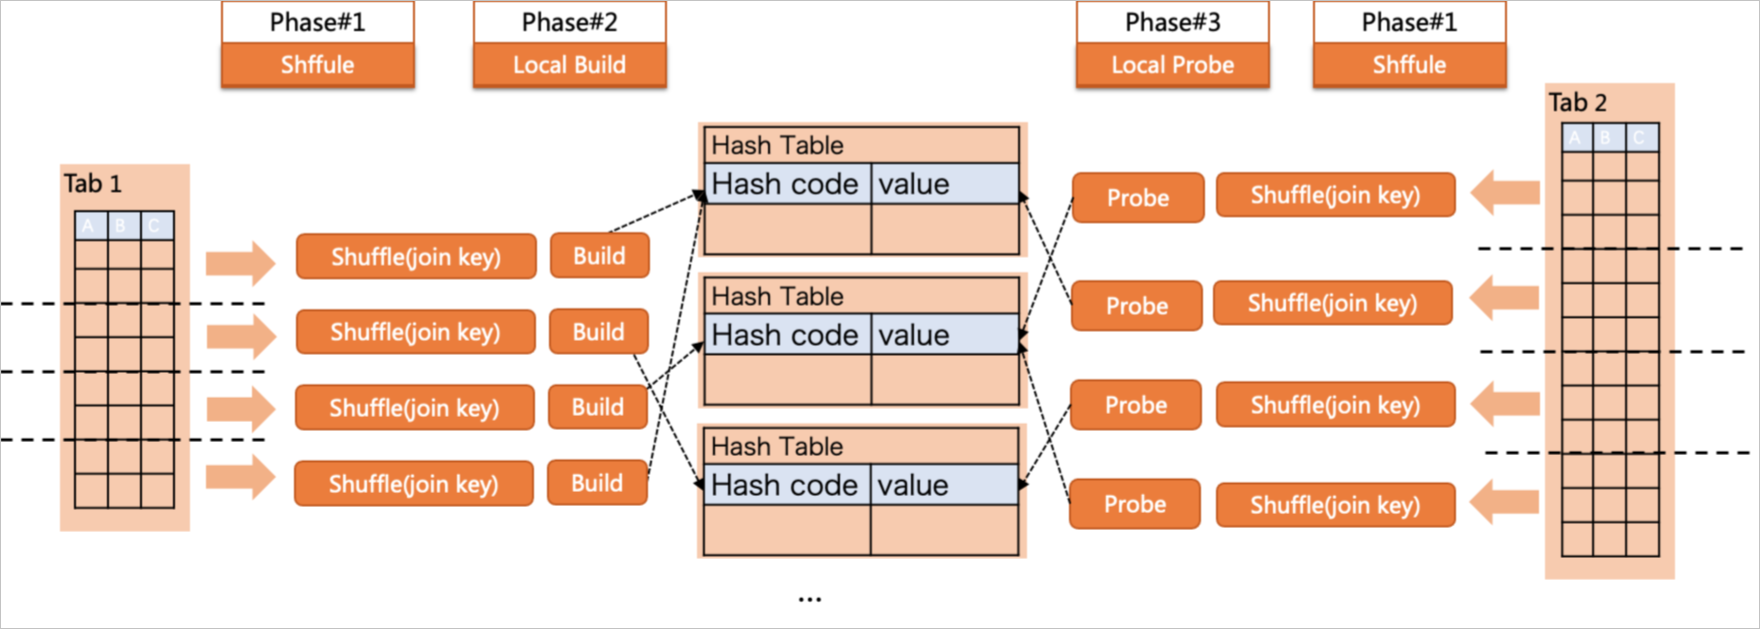
A parallel hash join executes both the build and probe phases in parallel. However, if a shared hash table is too large to fit in memory, it spills to disk, which creates I/O overhead and reduces query efficiency. The shuffle hash join strategy addresses this by repartitioning data from both tables. As shown in the figure, the process begins with a parallel scan of table t1, where multiple workers scan the table concurrently. Each worker then repartitions (shuffles) its data to a second set of workers based on the join key. This allows each worker in the second set to build a smaller, local hash table from a partition of the data in t1. After the build phase is complete, a parallel scan begins on table t2. The data from t2 is also repartitioned by the join key and sent to the workers holding the corresponding hash table partitions. Each worker then performs the probe operation on its local data partition. Finally, the leader gathers the results from all workers.
Usage
-
Syntax:
In PolarDB, use the
EXPLAIN FORMAT=TREEstatement to view thehash joinoperation in anexecution plan. -
Example:
The following example creates two
tablesand inserts sample data:CREATE TABLE t1 (c1 INT, c2 INT); CREATE TABLE t2 (c1 INT, c2 INT); INSERT t1(c1, c2) WITH RECURSIVE seq AS ( SELECT 1 AS a, 1 AS b UNION ALL SELECT a + 1, b + 1 FROM seq WHERE a < 1000 ) SELECT a,b FROM seq; INSERT INTO t2 SELECT * FROM t1;View the
execution planfor the SQL statement:EXPLAIN FORMAT=TREE SELECT * FROM t1 JOIN t2 ON t1.c1 = t2.c2;EXPLAIN FORMAT=TREE EXPLAIN | -> Gather (slice: 1; workers: 2) (cost=33.38 rows=4) -> Inner hash join (t2.c1 = t1.c1) (cost=23.08 rows=2) -> Repartition (hash keys: t2.c1; slice: 2; workers: 1) (cost=11.35 rows=2) -> Parallel table scan on t2, with parallel partitions: 1 (cost=0.65 rows=4) -> Hash -> Repartition (hash keys: t1.c1; slice: 3; workers: 1) (cost=11.35 rows=2) -> Parallel table scan on t1, with parallel partitions: 1 (cost=0.65 rows=4)