Task Scheduling (SchedulerX) manages your existing XXL-JOB jobs without requiring changes to your business code. Two paths are available: the XXL-JOB edition, which is compatible with the XXL-JOB network-layer protocol, and the SchedulerX compatibility plugin, which is compatible with the XXL-JOB SDK interfaces.
Choose a management path
Task Scheduling (SchedulerX) provides two ways to manage XXL-JOB jobs: the XXL-JOB edition and the SchedulerX compatibility plugin. For XXL-JOB workloads, use the XXL-JOB edition (Recommended). The following table compares the two paths.
| Item | XXL-JOB edition | SchedulerX compatibility plugin |
| Status | Public preview | — |
| Compatibility layer | XXL-JOB network-layer protocol | XXL-JOB SDK interfaces: the @XxlJob annotation and the JobHandler class interface |
| How it works | Built on the SchedulerX kernel, this edition manages your existing XXL-JOB client | Add the schedulerx2-plugin-xxljob dependency to your POM file |
| Code change | None: no intrusion into your code | None: manage your XXL-JOB client without modifying a single line of code |
If you are a new user, start with the XXL-JOB edition. To get started, see XXL-JOB.
Benefits
Zero maintenance and low cost
A self-managed deployment of open source XXL-JOB requires at least two servers and one database. Managed XXL-JOB jobs save both machine costs and operations staffing costs.
Compatible upgrades
Open source XXL-JOB versions are not always compatible with each other, so upgrading the SDK often forces you to refactor business code. SchedulerX works with the interfaces and annotations of every open source XXL-JOB version. You can upgrade the SDK without changing existing business code.
Large-scale jobs and precise scheduling
Open source XXL-JOB uses distributed database locks to make sure that only one node runs a job, which puts pressure on the database. Once minute-level jobs exceed 10,000, scheduling latency becomes noticeable. For second-level jobs, the latency is even greater.
SchedulerX uses a distributed architecture in which different servers schedule different jobs with no lock contention. It scales horizontally and supports millions of jobs. A dedicated architecture keeps latency and resource consumption low for second-level jobs, which makes it suitable for second-level scheduling in real-time business.
SchedulerX also supports one-time jobs: specify a point in time to run a job once, and SchedulerX destroys the job automatically after it finishes. Use one-time jobs for scenarios such as scheduled notifications and automatic order closing.
Visualization
User dashboard
User dashboard
At the top of the SchedulerX overview page, use the Namespace drop-down list to switch namespaces. The overview page contains the following areas:
-
Professional Edition statistics — Shows the total number of jobs, the number of application jobs, the number of disabled jobs, the number of online workers, and the number of job instances that are currently running.
-
Professional Edition job instance summary — Shows the number of triggers, successful executions, and failed executions in the most recent period. A line chart plots the trend of these three metrics over time.
-
Right-side pane — Contains Resource overview, which shows the number of Professional Edition and Basic Edition resources, Product news, and Quick access, which links to submit a ticket, product documentation, pricing, and Getting Started.
In the SchedulerX console, select the Job instance list tab to filter job records by conditions such as status and application ID. The list includes the Job ID/Name, Job type/Execution mode, Instance ID/Workflow instance ID, Application ID, Start time, End time, and Operator columns. A green Succeeded tag and a red Failed tag distinguish the status. In the Actions column, click Details, Logs, or Rerun to view or re-run a job instance.
Log query
On the log query page, select the Namespace and the application ID, then search by Job ID or Search field. Set a time range, such as Last 15 minutes, and click Query. The results show fields such as ip, executionId, level, and log content for each log entry, so you can review job execution status.
Thread stacks
On the job management page of the SchedulerX console, select a running job instance. The right-side panel shows the thread stack of that instance, including the thread name, the thread state such as TIMED_WAITING, and stack details such as a Thread.sleep call.
Advanced features
Job orchestration
Job orchestration
Use a workflow (DAG) to orchestrate jobs, and drag and drop nodes to build the workflow in the console. A detailed job status graph helps you understand why a downstream job failed.

Throttling
Throttling
A common scenario is overnight offline reporting. For example, many report jobs start at 01:00 or 02:00, so you must cap the number of concurrent jobs per application or the business cannot sustain the load. Jobs that reach the concurrency limit wait in a queue. If KPI reports must also finish before 09:00, give the KPI jobs a high priority. High-priority jobs preempt low-priority jobs and are therefore scheduled first.
SchedulerX supports preemptible job priority queues. Configure them in the console.

Resource isolation
Resource isolation
Isolate resources at the namespace and application levels. SchedulerX also supports permission management for multi-tenant scenarios.
Operation records
The job operation record list includes the following columns: ID, Operation time, Operation type, Operator, and Extended. Operation types include the following:
-
Deleting an application group
-
Modifying an application group
-
Granting permissions
-
Upgrading an application group
-
Enabling a job
-
Routing a job to specific workers
-
Modifying a job
At the top of the page, use the Type drop-down list to filter records by operation type. In the Actions column of each record, click View to view details.
Alerting and operations
Alerting
Alerting
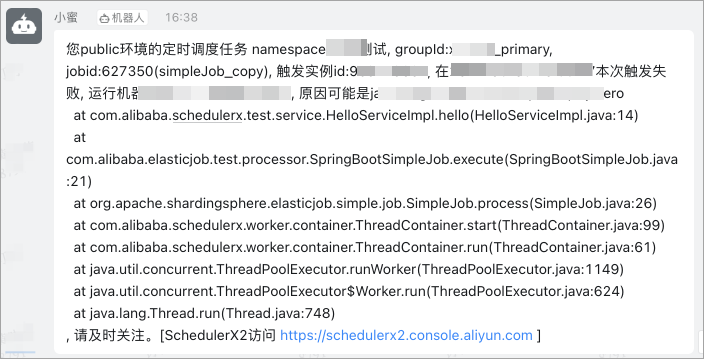
Receive alert notifications by email, DingTalk, text message, or phone call when a job fails, times out, or has no available worker. The alert content shows why the job failed.
Operations
Operations
Run a program in place, refresh data, mark a job as succeeded, view thread stacks, stop a job, and route a job to specific workers.
In the Actions column of the job list, click the more icon (the three-dot menu) to perform operations such as Disable, Copy, Delete, History, Operation records, Rerun job, and Route to specific workers.