Network connectivity enables Serverless Spark to reach data sources, servers, and services in your VPC (Virtual Private Cloud). This guide walks through configuring a network connection by connecting Spark SQL and JAR jobs to a Hive Metastore (HMS) in your VPC.
Prerequisites
A data source has been prepared. This example uses a data lake cluster created on the EMR on ECS page. The cluster includes the Hive service, and its Metadata is stored in Built-in MySQL. For more information, see Create a cluster.
Usage limits
vSwitches are supported only in the following availability zones.
Step 1: Create a network connection
-
Go to the Network Connection page.
-
Log on to the EMR console.
-
In the left navigation pane, choose EMR Serverless > Spark.
-
On the Spark page, click the target workspace name.
-
On the EMR Serverless Spark page, in the left navigation pane, click Normal Network Connection.
-
-
On the Normal Network Connection page, click Create Network Connection.
-
In the Create Network Connection dialog box, configure the following parameters and click OK.
Parameter
Description
Name
Enter a name for the connection.
VPC
Select the same VPC as the EMR cluster.
If no VPC is available, click Create VPC to create one in the VPC console. For more information, see VPCs and vSwitches.
NoteIf your Serverless Spark application needs internet access, ensure the network connection provides it. For example, you can deploy a public NAT gateway in the VPC to enable internet access for Serverless Spark instances. For more information, see Public NAT Gateway.
vSwitch
Select a vSwitch that is in the same VPC as the EMR cluster.
If no vSwitch is available in the current zone, click vSwitch to create one in the VPC console. For more information, see Create and manage vSwitches.
ImportantYou can select vSwitches only in specific zones. For more information, see Limitations.
The network connection is created when its Status changes to Succeeded.

Step 2: Add a security group rule
-
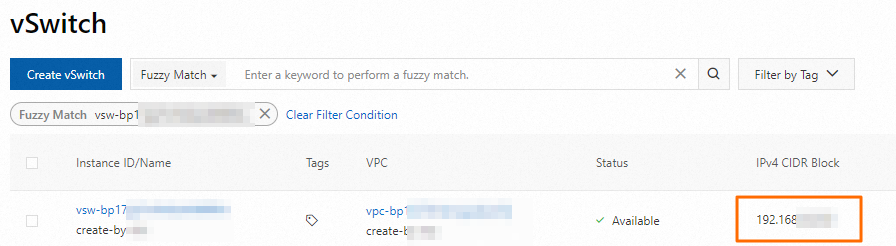
Get the CIDR block of the vSwitch used by the network connection.
Log on to the VPC console and go to the vSwitch page to locate the CIDR block of the vSwitch.
-
Add a security group rule.
-
Log on to the EMR on ECS console.
-
On the EMR on ECS page, click the cluster ID of the target cluster.
-
On the Basic Information page, in the Security section, click the link next to Cluster Security Group.
-
On the Security Group Details page, in the Rules section, click Add Rule, configure the following parameters, and then click OK.
Parameter
Description
Protocol
The allowed network protocol. Default: TCP.
NoteIf your network connection uses Kerberos authentication, we recommend that you select UDP and open port 88. For more information about Kerberos authentication, see Enable Kerberos authentication.
Source
Enter the vSwitch CIDR block from the previous step.
ImportantTo avoid security risks, do not set Authorization Object to 0.0.0.0/0.
Destination (Current Instance)
The destination port to open. For example, 9083.
-
(Optional) Step 3: Connect to Hive and query data
Skip this step if you already have a Hive table.
-
Log on to the master node of your cluster using SSH. For more information, see Log on to a cluster.
-
Start the Hive command line.
hive -
Create a table.
CREATE TABLE my_table (id INT,name STRING); -
Insert data into the table.
INSERT INTO my_table VALUES (1, 'John'); INSERT INTO my_table VALUES (2, 'Jane'); -
Query the data.
SELECT * FROM my_table;
(Optional) Step 4: Build and upload JAR artifact
To run a JAR job, you must first prepare an artifact. Skip this step for Spark SQL jobs.
-
Create a Maven project on your local machine.
-
Run the
mvn packagecommand to package the project. This command generates the sparkDataFrame-1.0-SNAPSHOT.jar file. -
On the EMR Serverless Spark page for your workspace, click Artifacts in the left navigation pane.
-
On the Artifacts page, click Upload File.
-
Upload the
sparkDataFrame-1.0-SNAPSHOT.jarfile from your local machine.
Step 5: Create and run a job
JAR job
-
On the EMR Serverless Spark page, click Development in the left navigation pane.
-
Click Create.
-
Enter a name, select as the type, and then click OK.
-
In the job editor, configure the following parameters. Leave other parameters at their default values. Then, click Run.
Parameter
Description
Main JAR Resource
Select the artifact you uploaded in the previous step. For example, sparkDataFrame-1.0-SNAPSHOT.jar.
Main Class
Enter the main class for the job. In this example, use com.example.DataFrameExample.
Normal Network Connection
Select the network connection you created in Step 1.
Spark Configuration
Configure the following properties.
spark.hadoop.hive.metastore.uris thrift://*.*.*.*:9083
spark.hadoop.hive.imetastoreclient.factory.class org.apache.hadoop.hive.ql.metadata.SessionHiveMetaStoreClientFactory
Replace
*.*.*.*with the private IP address of the HMS (Hive Metastore Service). In this example, the HMS is on the master node of your EMR cluster. You can find this address on the Nodes page of the EMR cluster by clicking the icon next to the emr-master node group.
-
After you run the job, go to the Execution Records section at the bottom of the page and click Log Exploration in the job's Actions column.
-
On the Log Exploration tab, you can view the job logs.
Spark SQL job
-
Create and start an SQL session. For more information, see Manage SQL sessions.
-
Normal Network Connection: Select the network connection you created in Step 1.
-
Spark Configuration: Configure the following properties.
spark.hadoop.hive.metastore.uris thrift://*.*.*.*:9083
spark.hadoop.hive.imetastoreclient.factory.class org.apache.hadoop.hive.ql.metadata.SessionHiveMetaStoreClientFactory
Replace
*.*.*.*with the private IP address of the HMS (Hive Metastore Service). In this example, the HMS is on the master node of your EMR cluster. You can find this address on the Nodes page of the EMR cluster by clicking the icon next to the emr-master node group.
-
-
On the EMR Serverless Spark page, click Development in the left navigation pane.
-
On the Development tab, click the
 icon.
-
In the Create dialog box, enter a name such as users_task, set the Type to the default SparkSQL, and then click OK.
-
In the new job editor, select the catalog, database, and your running SQL session. Enter the following query and click Run.
SELECT * FROM default.my_table;NoteWhen deploying SQL code that uses an external Metastore to a workflow, ensure that your SQL statements specify table names in the
db.table_nameformat and that you select a default database in thecatalog_id.defaultformat from the Catalog option in the upper-right corner of the UI.The query results appear in the Execution Results section at the bottom of the page.
