You can use Data Transmission Service (DTS) to synchronize data from a self-managed Oracle database to DataHub, allowing you to perform real-time data analysis with big data products like Realtime Compute for Apache Flink.
Prerequisites
-
The self-managed Oracle database is version 9i, 10g, 11g, 12c, 18c, or 19c.
-
The self-managed Oracle database runs in ARCHIVELOG mode, and its archived logs have a reasonable retention period and are accessible. For more information, see ARCHIVELOG.
-
Supplemental logging, including supplemental_log_data_pk and supplemental_log_data_ui, is enabled. For more information, see Supplemental Logging.
You have created a project in your DataHub instance to receive the synchronized data. For more information, see Create a project.
Limitations
Category | Description |
Limits on the source database |
|
Other limits |
|
Billing
|
Synchronization type |
Pricing |
|
Schema synchronization and full data synchronization |
Free of charge. |
|
Incremental data synchronization |
Charged. For more information, see Billing overview. |
Supported synchronization topologies
One-way one-to-one synchronization
One-way one-to-many synchronization
One-way cascade synchronization
One-way many-to-one synchronization
For more information, see Introduction to data synchronization topologies.
Supported SQL operations
INSERT, UPDATE, and DELETE.
Database account permissions
Database | Required permissions | Account creation and authorization |
Self-managed Oracle database | DBA | CREATE USER and GRANT. Important If you need to perform synchronization but are not allowed to grant DBA permissions, you must enable archive and supplemental logging and grant fine-grained permissions to the Oracle database account as described in the following sections. |
Enable logging and grant fine-grained permissions to an Oracle database account
If you need to synchronize data from an Oracle database but the database administrator (DBA) permission cannot be granted to the database account, you can enable archive logging and supplemental logging, and grant fine-grained permissions to the account.
-
Enable archive logging and supplemental logging.
Log type
Procedure
Archive logging
Execute the following statements to enable archive logging:
shutdown immediate;
startup mount;
alter database archivelog;
alter database open;
archive log list;
Supplemental logging
Enable supplemental logging at the database or table level based on your business requirements.
NoteYou can enable database-level supplemental logging to ensure the stability of Data Transmission Service (DTS) tasks. You can enable table-level supplemental logging to reduce the disk usage of the source Oracle database.
-
Enable database-level supplemental logging
-
Execute the following statement to enable minimal supplemental logging:
alter database add supplemental log data; -
Execute the following statement to enable primary key and unique key supplemental logging at the database level:
alter database add supplemental log data (primary key,unique index) columns;
-
-
Enable table-level supplemental logging
-
Execute the following statement to enable minimal supplemental logging:
alter database add supplemental log data; -
Enable table-level supplemental logging by using one of the following methods:
-
Execute the following statement to enable primary key supplemental logging at the table level:
alter table table_name add supplemental log data (primary key) columns; -
Execute the following statement to enable table-level supplemental logging for all columns:
alter table tb_name add supplemental log data (all) columns ;
-
-
-
-
Grant fine-grained permissions to an Oracle database account.
Oracle versions 9i to 11g
# Create a database account named rdsdt_dtsacct and grant permissions to the account.
create user rdsdt_dtsacct IDENTIFIED BY rdsdt_dtsacct;
grant create session to rdsdt_dtsacct;
grant connect to rdsdt_dtsacct;
grant resource to rdsdt_dtsacct;
grant execute on sys.dbms_logmnr to rdsdt_dtsacct;
grant select on V_$LOGMNR_LOGS to rdsdt_dtsacct;
grant select on  all_objects to rdsdt_dtsacct;
grant select on  all_tab_cols to rdsdt_dtsacct;
grant select on  dba_registry to rdsdt_dtsacct;
grant select any table to rdsdt_dtsacct;
grant select any transaction to rdsdt_dtsacct;
-- v$log privileges
grant select on v_$log to rdsdt_dtsacct;
-- v$logfile privileges
grant select on v_$logfile to rdsdt_dtsacct;
-- v$archived_log privileges
grant select on v_$archived_log to rdsdt_dtsacct;
-- v$parameter privileges
grant select on v_$parameter to rdsdt_dtsacct;
-- v$database privileges
grant select on v_$database to rdsdt_dtsacct;
-- v$active_instances privileges
grant select on v_$active_instances to rdsdt_dtsacct;
-- v$instance privileges
grant select on v_$instance to rdsdt_dtsacct;
-- v$logmnr_contents privileges
grant select on v_$logmnr_contents to rdsdt_dtsacct;
-- system tables
grant select on sys.USER$ to rdsdt_dtsacct;
grant select on SYS.OBJ$ to rdsdt_dtsacct;
grant select on SYS.COL$ to rdsdt_dtsacct;
grant select on SYS.IND$ to rdsdt_dtsacct;
grant select on SYS.ICOL$ to rdsdt_dtsacct;
grant select on SYS.CDEF$ to rdsdt_dtsacct;
grant select on SYS.CCOL$ to rdsdt_dtsacct;
grant select on SYS.TABPART$ to rdsdt_dtsacct;
grant select on SYS.TABSUBPART$ to rdsdt_dtsacct;
grant select on SYS.TABCOMPART$ to rdsdt_dtsacct;
grant select on v$database to rdsdt_dtsacct;
grant select on dba_objects to rdsdt_dtsacct;
grant select on DBA_TAB_COMMENTS to rdsdt_dtsacct;
grant select on dba_tab_cols to rdsdt_dtsacct;
Oracle versions 12c to 19c that use the multitenant architecture
# Switch to the pluggable database (PDB). Create a database account named rdsdt_dtsacct and grant permissions to the account.
ALTER SESSION SET container = ORCLPDB1;
create user rdsdt_dtsacct IDENTIFIED BY rdsdt_dtsacct;
grant create  session to rdsdt_dtsacct;
grant connect  to rdsdt_dtsacct;
grant resource to rdsdt_dtsacct;
grant execute on sys.dbms_logmnr to rdsdt_dtsacct;
grant select on  all_objects to rdsdt_dtsacct;
grant select on  all_tab_cols to rdsdt_dtsacct;
grant select on  dba_registry to rdsdt_dtsacct;
grant select any table to rdsdt_dtsacct;
grant select any transaction to rdsdt_dtsacct;
-- v$log privileges
grant select on v_$log to rdsdt_dtsacct;
-- v$logfile privileges
grant select on v_$logfile to rdsdt_dtsacct;
-- v$archived_log privileges
grant select on v_$archived_log to rdsdt_dtsacct;
-- v$parameter privileges
grant select on v_$parameter to rdsdt_dtsacct;
-- v$database privileges
grant select on v_$database to rdsdt_dtsacct;
-- v$active_instances privileges
grant select on v_$active_instances to rdsdt_dtsacct;
-- v$instance privileges
grant select on v_$instance to rdsdt_dtsacct;
-- v$logmnr_contents privileges
grant select on v_$logmnr_contents to rdsdt_dtsacct;
grant select on sys.USER$ to rdsdt_dtsacct;
grant select on SYS.OBJ$ to rdsdt_dtsacct;
grant select on SYS.COL$ to rdsdt_dtsacct;
grant select on SYS.IND$ to rdsdt_dtsacct;
grant select on SYS.ICOL$ to rdsdt_dtsacct;
grant select on SYS.CDEF$ to rdsdt_dtsacct;
grant select on SYS.CCOL$ to rdsdt_dtsacct;
grant select on SYS.TABPART$ to rdsdt_dtsacct;
grant select on SYS.TABSUBPART$ to rdsdt_dtsacct;
grant select on SYS.TABCOMPART$ to rdsdt_dtsacct;
-- V$PDBS privileges
grant select on V_$PDBS to rdsdt_dtsacct;
grant select on v$database to rdsdt_dtsacct;
grant select on dba_objects to rdsdt_dtsacct;
grant select on DBA_TAB_COMMENTS to rdsdt_dtsacct;
grant select on dba_tab_cols to rdsdt_dtsacct;
grant select_catalog_role TO rdsdt_dtsacct;

# Switch to the container database (CDB). Create a database account and grant permissions to the account.
ALTER SESSION SET container = CDB$ROOT;

# Create a database account named rdsdt_dtsacct and grant permissions to the account. You must modify the default parameters of the Oracle database.
alter session set "_ORACLE_SCRIPT"=true;
create user rdsdt_dtsacct IDENTIFIED BY rdsdt_dtsacct;
grant create session to rdsdt_dtsacct;
grant connect to rdsdt_dtsacct;
grant select on v_$logmnr_contents to rdsdt_dtsacct;
grant LOGMINING TO rdsdt_dtsacct;
grant EXECUTE_CATALOG_ROLE to rdsdt_dtsacct;
grant execute on sys.dbms_logmnr to rdsdt_dtsacct;
grant select on v$database to rdsdt_dtsacct;
grant select on dba_objects to rdsdt_dtsacct;
grant select on DBA_TAB_COMMENTS to rdsdt_dtsacct;
grant select on dba_tab_cols to rdsdt_dtsacct;
Oracle versions 12c to 19c that use a non-multitenant architecture
# Create a database account named rdsdt_dtsacct and grant permissions to the account.
create user rdsdt_dtsacct IDENTIFIED BY rdsdt_dtsacct;
grant create  session to rdsdt_dtsacct;
grant connect  to rdsdt_dtsacct;
grant resource to rdsdt_dtsacct;
grant select on V_$LOGMNR_LOGS to rdsdt_dtsacct;
grant select on  all_objects to rdsdt_dtsacct;
grant select on  all_tab_cols to rdsdt_dtsacct;
grant select on  dba_registry to rdsdt_dtsacct;
grant select any table to rdsdt_dtsacct;
grant select any transaction to rdsdt_dtsacct;
-- v$log privileges
grant select on v_$log to rdsdt_dtsacct;
-- v$logfile privileges
grant select on v_$logfile to rdsdt_dtsacct;
-- v$archived_log privileges
grant select on v_$archived_log to rdsdt_dtsacct;
-- v$parameter privileges
grant select on v_$parameter to rdsdt_dtsacct;
-- v$database privileges
grant select on v_$database to rdsdt_dtsacct;
-- v$active_instances privileges
grant select on v_$active_instances to rdsdt_dtsacct;
-- v$instance privileges
grant select on v_$instance to rdsdt_dtsacct;
-- v$logmnr_contents privileges
grant select on v_$logmnr_contents to rdsdt_dtsacct;
grant select on sys.USER$ to rdsdt_dtsacct;
grant select on SYS.OBJ$ to rdsdt_dtsacct;
grant select on SYS.COL$ to rdsdt_dtsacct;
grant select on SYS.IND$ to rdsdt_dtsacct;
grant select on SYS.ICOL$ to rdsdt_dtsacct;
grant select on SYS.CDEF$ to rdsdt_dtsacct;
grant select on SYS.CCOL$ to rdsdt_dtsacct;
grant select on SYS.TABPART$ to rdsdt_dtsacct;
grant select on SYS.TABSUBPART$ to rdsdt_dtsacct;
grant select on SYS.TABCOMPART$ to rdsdt_dtsacct;
grant LOGMINING TO rdsdt_dtsacct;
grant EXECUTE_CATALOG_ROLE to rdsdt_dtsacct;
grant execute on sys.dbms_logmnr to rdsdt_dtsacct;
grant select on v$database to rdsdt_dtsacct;
grant select on dba_objects to rdsdt_dtsacct;
grant select on DBA_TAB_COMMENTS to rdsdt_dtsacct;
grant select on dba_tab_cols to rdsdt_dtsacct;
Procedure
Purchase a data synchronization instance. For more information, see Purchase procedure.
NoteWhen purchasing, select Oracle for the source instance and DataHub for the destination instance.
- Log on to the Data Transmission Service console.
Note
If you are automatically redirected to the Data Management (DMS) console, you can click the
 icon in the lower-right corner and then click
 to return to the classic DTS console.
- In the navigation pane on the left, click Data Synchronization.
- In the top navigation bar of the Data Synchronization page, select the region where the destination instance is located.
- Find the purchased data synchronization instance and click Configure Synchronization Channel.
Configure the source and destination instances.
Category
Setting
Description
N/A
Synchronization task name
DTS automatically generates a task name. For easy identification, specify an informative name. The name does not need to be unique.
Source instance information
Instance type
Select Self-managed Database on ECS.
NoteIf the source is a self-managed database, you must complete certain preparations. For more information, see Preparation overview.
Instance region
The region of the source instance that you selected when you purchased the data synchronization instance. This cannot be changed.
ECS instance ID
Select the ID of the ECS instance that hosts the self-managed Oracle database.
Database type
This is fixed as Oracle and cannot be changed.
Port
Enter the service port for the self-managed Oracle database. The default is 1521.
Instance type
Non-RAC Instance: Select this option. You must also enter the SID.
RAC instance: RAC instances are not supported.
Database account
Enter the account for the self-managed Oracle database. For permission requirements, see Database account permissions.
Database password
Enter the password for the database account.
Destination instance information
Instance type
This is fixed as DataHub and cannot be changed.
Instance region
The region of the destination instance that you selected when you purchased the data synchronization instance. This cannot be changed.
Project
Select the DataHub Project.
-
In the lower-right corner of the page, click Set Whitelist and Next.
If the source or destination database is an Alibaba Cloud database instance, such as an ApsaraDB RDS for MySQL or ApsaraDB for MongoDB instance, DTS automatically adds the CIDR blocks of DTS servers to the IP address whitelist of the instance. If the source or destination database is a self-managed database hosted on an Elastic Compute Service (ECS) instance, DTS automatically adds the CIDR blocks of DTS servers to the security group rules of the ECS instance, and you must make sure that the ECS instance can access the database. If the self-managed database is hosted on multiple ECS instances, you must manually add the CIDR blocks of DTS servers to the security group rules of each ECS instance. If the source or destination database is a self-managed database that is deployed in a data center or provided by a third-party cloud service provider, you must manually add the CIDR blocks of DTS servers to the IP address whitelist of the database to allow DTS to access the database. For more information, see Whitelist DTS server IP addresses.
WarningAdding the public IP address blocks of the DTS service, either automatically or manually, may pose security risks. Using this product, you acknowledge that you understand and accept the potential security risks and that you must implement basic security measures. These measures include, but are not limited to, strengthening password security, limiting the ports open to each CIDR block, using authentication for internal API calls, and regularly checking and restricting unnecessary CIDR blocks. Alternatively, you can connect through a private network using a leased line, VPN Gateway, or Smart Access Gateway.
Configure the synchronization policy and objects.
Setting
Description
Initial synchronization
Select Initial schema synchronization.
NoteWhen you select Initial schema synchronization, DTS synchronizes the schema of the selected objects, such as tables, to the destination DataHub instance during the initialization phase.
Select synchronization objects
In the Source Objects box, click the objects you want to synchronize, and then click the
 icon to move them to the Selected Objects box.Note
You can select objects at the table level.
By default, the names of the synchronized objects remain unchanged. If you need to change the name of an object in the destination instance, use the object name mapping feature. For more information, see Set the names of synchronized objects in the destination instance.
Select additional column rule
When DTS synchronizes data to DataHub, it adds extra columns to the destination Topic. Data synchronization will fail if the names of these additional columns conflict with existing column names in the destination Topic. Based on your business needs, select Yes or No for Enable New Naming Rule for Additional Columns.
WarningBefore you select a rule, check whether the additional columns will conflict with existing columns in the destination Topic. For information about the rules and definitions of additional columns, see Additional column names and definitions.
Map names
Change the names of synchronized objects in the destination instance. For more information, see Map databases, tables, and columns.
Connection retry duration
If DTS cannot connect to the source or destination instance, it retries for 720 minutes (12 hours) by default. You can also specify a custom retry duration. If DTS reconnects to the source or destination instance within the specified duration, the synchronization task automatically resumes. Otherwise, the task fails.
NoteYou are billed for task run time during connection retries. Customize the retry duration based on your business needs, or release the DTS instance as soon as the source and destination instances are released.
Optional: In the Selected Objects box, move your pointer over the Topic name, click the Edit button that appears, and then set the Shardkey (the key used for partitioning) in the dialog box that opens.
After you complete the preceding configurations, click Precheck and Start in the lower-right corner of the page.
NoteBefore the synchronization task is officially started, a precheck is performed. The synchronization task can only be started after the precheck passes.
If the precheck fails, click the
 icon next to a specific check item to view the failure details.
Follow the prompt to fix the issue and run the precheck again.
If you do not need to fix the warning check items, you can also select Ignore, Ignore Warning Items and Rerun Precheck to skip the warning check items and run the precheck again.
- After Precheck Passed is displayed in the Precheck dialog box, close the dialog box. The synchronization task starts automatically.
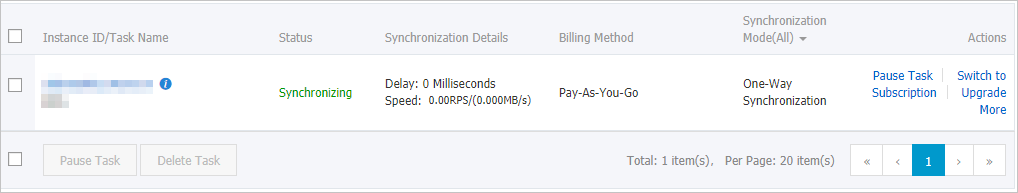
- Wait until the synchronization channel is initialized and the task enters the Synchronizing state.
The Data Synchronization page displays the status of data synchronization jobs.
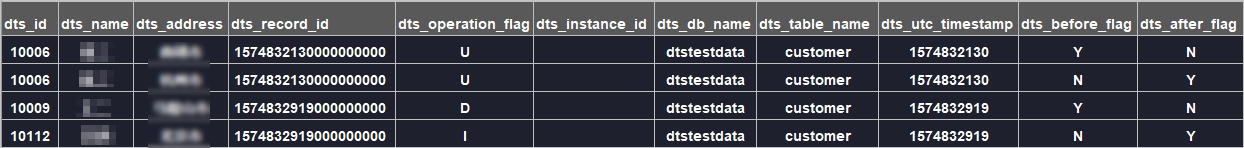
DataHub topic schema
When DTS synchronizes incremental data to a DataHub topic, it adds metadata columns to the topic.
In this example,id,name, andaddressare data fields. When the previous naming rules are used, DTS adds thedts_prefix to all fields, including the original fields from the source. When the new naming rules are used, DTS does not add a prefix to the original source fields.
Previous column name | New column name | Type | Description |
|
| String | Unique ID of the incremental log entry. Auto-increments for each new entry. In disaster recovery scenarios, rollback may cause ID duplication. For UPDATE operations, both log entries (pre-update and post-update) share the same |
|
| String | The operation type. Valid values: |
|
| String | The server ID of the database. |
|
| String | The database name. |
|
| String | The table name. |
|
| String | The operation timestamp in UTC. This is also the timestamp of the log file. |
|
| String | Indicates whether the row values are pre-update values. Valid values: |
|
| String | Indicates whether the row values are post-update values. Valid values: |
Before and after flag values
The dts_before_flag and dts_after_flag columns indicate whether a row in the topic represents the state before or after a data change.
Operation | Log entries generated | dts_before_flag | dts_after_flag | Row content |
INSERT | 1 |
|
| The newly inserted values. |
DELETE | 1 |
|
| The deleted values. |
UPDATE (first entry) | 2 (same |
|
| Pre-update values. |
UPDATE (second entry) | 2 (same |
|
| Post-update values. |
INSERT operation
The log entry contains the newly inserted values. dts_before_flag is N and dts_after_flag is Y.
UPDATE operation
DTS generates two log entries with the same dts_record_id, dts_operation_flag, and dts_utc_timestamp values. The first entry captures the pre-update values (dts_before_flag=Y, dts_after_flag=N). The second entry captures the post-update values (dts_before_flag=N, dts_after_flag=Y).

DELETE operation
The log entry contains the deleted values. dts_before_flag is Y and dts_after_flag is N.

What's next
After the synchronization task is running, use Alibaba Cloud Realtime Compute for Apache Flink to analyze the data in the DataHub project. For more information, see What is Alibaba Cloud Realtime Compute for Apache Flink?