Dataphin lets you create quality rules to validate tables and simplify data quality monitoring. This topic shows you how to configure these rules.
Prerequisites
Before you can configure a quality rule, you must add a monitoring object. For instructions on how to add a monitoring object, see Add a monitoring object or .
Permissions
Super administrators, quality administrators, custom global roles with the Quality Rule - Manage permission, and custom project roles with the Project quality management - Quality rule management permission within the table's project can configure schedules, alerts, exception archive tables, scoring weights, and runtime configurations for quality rules.
Quality owners can configure schedules, alerts, exception archive tables, scoring weights, and runtime configurations for quality rules on the monitoring objects they own.
Quality owners and regular users also require read permission on Dataphin tables. To apply for this permission, see Apply for, renew, and revoke table permissions.
The permissions required to perform operations depend on the target object. For more information, see Quality rule operation permissions.
Quality rule configuration
You can configure quality rules in two ways: custom configuration and monitoring by referencing a data standard. The second method requires the data standard module to be enabled.
Custom configuration allows you to quickly create quality rules from built-in or custom quality rule templates. It also supports custom SQL for flexible monitoring.
Monitoring by referencing a data standard applies the quality rules from the data standard mapped to the current asset object, which helps enforce standard constraints.
Validation Rules
If a weak monitoring rule triggers, the system sends an alert so you can promptly handle the exception. If a strong monitoring rule triggers, the system automatically stops the job containing the table to prevent dirty data from flowing downstream and sends an alert.
Trial Run VS. Run
A trial run and a run differ in their execution and how their results are handled. A trial run is a simulated execution to verify that a quality rule works correctly; its results are not saved to the quality report. In contrast, a run executes the quality rule at a scheduled time and saves its results to the quality report for analysis.
Quality Rule Configuration
On the Dataphin homepage, click Governance > Data Quality in the top menu bar.
In the left-side navigation pane, click Quality Rule. On the Dataphin Table page, click the name of the target object to go to the Quality Rule Details page, and then configure the quality rule.
Custom configuration
Hover over the target data table and select Create Quality Rule > Custom, or click Create Quality Rule to open the Create Quality Rule dialog box.
In the Create Quality Rule dialog box, configure the parameters.
Parameter
Description
Basic information
Rule Name
The custom name of the quality rule. The name cannot exceed 256 characters.
Rule Strength
You can select Weak rule or Strong rule.
Weak rule: If you select Weak rule, a failed quality rule validation triggers an alarm but does not block the downstream task node.
Strong rule: If you select Strong rule, an alert is triggered when the quality rule validation fails. If downstream tasks exist (such as in code check scheduling or task-triggered scheduling), these tasks are blocked to prevent the spread of dirty data. If no downstream tasks exist (such as in periodic quality scheduling), only an alert is triggered.
Description
The custom description of the quality rule. The description cannot exceed 128 characters.
Configuration Method
Create from Template: Create quality rules quickly by using general-purpose system templates or custom business templates.
System Template: The built-in parameters are configurable. This method is suitable for creating general-purpose rules.
Custom Template: Parameters are preset and do not require configuration. This method is typically used for creating rules that contain business logic.
Custom SQL: Flexibly define quality monitoring rules by using SQL. This method is suitable for complex scenarios.
Rule Template
Select a rule template from the drop-down list. Options include completeness, uniqueness, timeliness, validity, consistency, stability, and custom SQL.
Completeness: Includes field null value validation and field empty string validation.
Uniqueness: Includes field uniqueness validation, field group count validation, and field duplicate value count validation.
Timeliness: Includes time function comparison, single-table time field comparison, and two-table time field comparison.
Validity: Includes field format validation, field length validation, field value range validation, code table reference comparison, and data standard code table reference comparison (requires the data standard module to be enabled).
Consistency: Includes single-table field value consistency comparison, single-table field statistical value consistency comparison, single-field business logic consistency comparison, two-table field value consistency comparison, two-table field statistical value consistency comparison, two-table field business logic consistency comparison, and cross-source two-table field statistical value consistency comparison.
Stability: Includes table stability validation, table volatility validation, field stability validation, and field volatility validation.
Custom SQL: Includes custom statistical metric validation and custom data detail validation.
For more information, see Template type descriptions.
Rule Type
The rule type depends on the template and is its most basic attribute. It can be used for description and filtering purposes.
Monitoring Granularity
When the configuration method is custom SQL, you can configure the monitoring granularity. You can select Table to monitor the entire table or Field to monitor a specific field.
Template configuration
Template Information
When you select a quality rule template, its configuration information is displayed. To modify the configuration, go to the Quality Rule Template page.
Rule configuration
Rule Configuration
The rule configuration varies based on the selected rule template. For more information, see Configure parameters for Dataphin tables.
Specific configurations include the following:
Filter data in the source table: This feature is disabled by default. If you enable it, you can configure filter conditions for the source table, such as partition filters or regular data filters. The filter conditions are directly appended to the validation SQL. If the source table requires partition filtering, we recommend that you configure a partition expression in the schedule configuration. After configuration, the validation partition becomes the minimum granularity for viewing the quality report.
When the rule template is Consistency/two-table field statistical value comparison or Consistency/cross-source two-table field statistical value comparison, you can enable Filter data in the target table. If enabled, you can configure filter conditions for the target table, such as partition filters or regular data filters. The filter conditions are directly appended to the validation SQL.
Validation configuration
Rule Validation
After a data quality rule is validated, the result is compared with the anomaly validation configuration. If the conditions are met, the validation fails and triggers subsequent processes such as alerting.
The available metrics for anomaly validation depend on the template and configuration. Multiple AND/OR conditions are supported. We recommend using fewer than three conditions in your configuration.
For more information, see Validation configuration descriptions.
Archive configuration
Anomaly Archiving
This feature is Off by default. If you turn it On, the system archives anomalous data to a file or table. After quality validation, you can download and analyze the archived anomalous data.
Archiving Mode supports Archive only anomalous fields and Archive complete records.
Archive only anomalous fields: This mode archives only the monitored anomalous fields after deduplication. This mode is suitable for cases where a single field is sufficient to identify anomalous data.
Archive complete records: This mode archives the entire record containing the anomalous data. This mode is suitable for cases where the complete record is needed to locate the anomaly.
NoteBecause archiving complete records significantly increases the amount of archived data, we recommend using the 'Archive only anomalous fields' mode in most cases.
Archiving Location supports Default file server and Custom anomaly archiving table. If no anomaly archiving table has been created, click Manage Anomaly Archiving Tables to create one. For more information, see Add an anomaly archiving table.
Default file server: This refers to the system file server configured during Dataphin deployment. You can download anomalous data directly from the Validation Records > Validation Details page, or access the default file server to obtain the data. When you use the default file server, a maximum of 100 anomalous data entries can be archived for each validation run. This is suitable for scenarios with small data volumes.
Custom anomaly archiving table: If you want to store more anomalous data or consolidate anomalous data from different validation records for subsequent comparative analysis, we recommend specifying a custom archive table. Each quality rule can record up to 10,000 anomalous data entries per run. In addition to downloading the anomalous data from a single validation on the Validation Records page, you can also directly access the archive table and customize its lifecycle for greater flexibility.
NoteA summary of anomalous data generated by all rules in the current run can be downloaded. The download is limited to 10,000 entries. To view more data, we recommend archiving it to a specified anomaly archiving table and then accessing the table directly.
The anomaly archiving table must meet specific format requirements. Otherwise, data may not be written correctly, which affects its usability. For more information, see Add an anomaly archiving table.
When the computing engine is Transwarp TDH 6.x or Transwarp TDH 9.3.x and you select a custom anomaly archiving table, you can select Display field comments in the header of the anomaly data table. If selected, the downloaded anomaly data table includes comment information for each field.
Business attribute configuration
Attribute Information
The specifications for entering business attributes depend on how the quality rule attributes are configured. For example, if the
department in chargeattribute is configured as an enumeration with multiple selectable values (such as Big Data Department, Business Department, and Technology Department), the corresponding field in the quality rule creation form will be a multi-select drop-down list with these options.If the value type for the
rule ownerfield is custom input with a field length of 256, you can enter up to 256 characters for this attribute when you create the quality rule.If an attribute's input method is Range, configure it as follows:
Range: This option is typically used for continuous numerical values or dates. You can select from the operators >, >=, <, and <=. For more information about attribute configuration, see Create and manage quality rule attributes.
Schedule configuration
Scheduling Method
Select a configured schedule. If you have not decided on a scheduling method, you can create the quality rule first and configure the schedule later. To create a new schedule, see Create A Schedule.
Quality score configuration
Scoring Method
Two scoring methods are supported: quality validation status and data qualification ratio.
Quality validation status: Scores the rule based on the validation status of its last successful run. A passing validation receives 100 points, and a failing validation receives 0 points.
Data qualification ratio: Uses the percentage of valid data from the last successful validation run as the score. For example, if the data format validity is 80%, the quality score is 80.
Different rule templates support different scoring methods. The following templates only support the Quality validation status scoring method:
Under the uniqueness category: field group count validation and field duplicate value count validation.
Under the consistency category: single-table field statistical value consistency comparison and cross-source two-table field statistical value consistency comparison.
All templates in the stability category.
Under the custom SQL category: custom statistical metric validation.
Quality Score Weight
The quality score weight of the quality rule, which is used to calculate the quality score of the monitored object. You can select an integer from 1 to 10.
Click OK to save the custom rule configuration.
You can click Preview SQL to compare the current configuration with the last saved version to review SQL changes.
NoteThe Preview SQL button is unavailable if key information is incomplete.
The left pane shows the SQL preview of the last saved configuration, and the right pane shows the preview of the current configuration. The left pane is empty if you have not saved a configuration.
Reference a data standard for monitoring
Hover over the target data table and select Create Quality Rule > Reference Data Standard for Monitoring.
In the Reference Data Standard for Monitoring dialog box, select the data standard rules that you want to reference. You can filter the standard rules by templates such as validity, uniqueness, completeness, and stability, or search by object name.
In the dialog box, you can modify the rule name and enable or disable the effective status. You can also click the standard code in the Associated Standard column to view standard details, or click the
 icon in the Actions column to view the quality rule.Note
After you reference a rule, you cannot modify its configuration details. However, you can configure its schedule and change its strength.
Click Add Selected Rules to finish referencing the data standard rules.
Rule Configuration List
After you create a quality rule, you can view, edit, perform a trial run, run, and delete it in the rule configuration list.

Area | Description |
① Filter and search area | Search by object or rule name. Filter by rule type, rule template, rule strength, trial run status, effective status, and rule source. Note If you configure a business attribute to be searchable or filterable and the attribute is enabled, you can use it to search or filter the rule list. |
② List area | Displays rule configuration details, such as Object Type/Name, Rule Name/ID, Trial Run Status, Effective Status, Rule Type, Rule Template, Rule Strength, Schedule Type, and Related Knowledge Base Document. Click the
|
③ Actions area | You can perform operations such as view, clone, edit, trial run, run, schedule configuration, associate knowledge base document, quality score configuration, and delete.
|
④ Batch operations area | You can perform batch operations, including trial run, run, configure schedule, enable, disable, modify business attributes, associate knowledge base document, quality score configuration, export rules, and delete.
|
 icon to customize the columns in the list.
 icon next to the rule name to view the standard details.
 icon after the rule name.
 icon to View Trial Run Logs.
Create A Schedule
When configuring a scheduling rule, you can reuse the configuration of an existing schedule. Each table supports a maximum of 20 scheduling rules.
You can configure a maximum of 10 schedules for a single rule.
The system automatically deduplicates identical schedule configurations.
For Hologres partitioned tables, we recommend using task-triggered scheduling.
The validation scope acts as a filter condition in the quality check statement, controlling the scope of each run. It also serves as the basic unit for downstream processes, such as quality reports, and represents the minimum viewing granularity.
On the Quality Rule Details page, click the Scheduling Configuration tab, and then click Create Schedule to open the Create Schedule dialog box.
In the Create Schedule dialog box, configure the parameters.
Parameter
Description
Schedule Name
Specify a custom name for the schedule. The name can be up to 64 characters long.
Scheduling type
The supported types are time-based scheduling, data update-triggered scheduling, and task-triggered scheduling.
time-based scheduling: Runs data quality checks periodically at a specified time. This scheduling type is suitable for scenarios where data is generated at predictable times.
Scheduling cycle: Running quality rules consumes computing resources. To avoid impacting production tasks, avoid running multiple quality rules concurrently. Supported scheduling cycles are Day, Week, Month, Hour, and Minute.
If the system time zone (your user center time zone) differs from the scheduling time zone (configured in Management Center > System Settings > Basic Settings), the rule is executed based on the system time zone.
Fill in Recommended Time: You can click Fill in Recommended Time to have the system suggest a time based on the average completion time of the task that generates data for the current table.
data update-triggered scheduling: When a code task runs, the system checks if data has been updated within the specified validation scope for the current table. This type is suitable for tables modified by various tasks or for critical tables that require monitoring for every change.
NoteWe recommend setting the validation scope to the partitions updated by the task. For non-partitioned tables, the entire table is validated. This allows the system to automatically detect and validate all data changes, ensuring no updates are missed.
task-triggered scheduling: Executes the configured quality rule after a specified task runs successfully or before it runs. It can be triggered by tasks of various node types, including SQL, Offline Pipeline, Python, Shell, Virtual, Dlink, Spark_jar, Hive_MR, and Database SQL. This type is for scenarios where specific, recurring tasks modify the table.
NoteYou can select only tasks from the production environment as triggering tasks. If a strong rule is configured and the scheduled quality check fails, it may affect production tasks. Please use this feature with caution based on your business requirements.
Supported engine types are MaxCompute, E-MapReduce 3.X, E-MapReduce 5.x, CDH 5.X, CDH 6.X, FusionInsight 8.X, AsiaInfo DP 5.3, Cloudera Data Platform 7.x, Lindorm (computing engine), Transwarp TDH 6.x, and Transwarp TDH 9.3.x.
Trigger Time: Select when to trigger the quality check. Options include Trigger After All Tasks Run Successfully, Trigger After Each Task Runs Successfully, and Trigger Before Each Task Runs.
Trigger Job: Allows the following roles to select a job node from a production project to trigger a job. You can search by the node output name or select a job from the Recommended Jobs or All Jobs list.
Project administrators of Prod/Basic projects, users with the Operations system role for Prod projects, users with the Developer system role for Basic projects, and users with a custom project role that has Project Quality Management - Quality Rule Management permissions can select task nodes from production projects.
Custom global roles with the Quality Rule - Manage permission can select task nodes in all production projects.
Recommended Tasks: Displays lineage tasks where the current table is an output, as well as tasks whose node output name matches the
Domain/Project.Tableformat. This corresponds to the task scope defined in Asset Catalog-Asset Details-Output Information.All Tasks: Displays all production tasks that the current user has operational permissions on.
NoteWhen you set the trigger condition to 'Trigger after all jobs run successfully', select jobs that have the same scheduling cycle to avoid delays in rule execution and the generation of quality check results due to different scheduling cycles.
When the trigger condition is set to 'Trigger before each run of each job', Recommended Jobs displays the lineage tasks that use the current table as input.
Scheduling Condition
This feature is disabled by default. When enabled, the schedule runs only if this condition is met; otherwise, the instance is skipped.
Business date/Execution Date: If the scheduling type is time-based scheduling (which does not support Execution Date), data update-triggered scheduling, or task-triggered scheduling, you can configure a date-based condition. You can use a General Calendar or a Custom Calendar. For information about creating a custom calendar, see Create a public calendar.
If you select General Calendar, you can set conditions based on Month, Day of Week, or Date. See the following figure for an example:

If you select Custom Calendar, you can set conditions based on Date Type or Tag. See the following figure for an example:

Instance type: If the scheduling type is data update-triggered scheduling or task-triggered scheduling, you can configure the instance type. The options are scheduled instance, backfill instance, and manual instance. See the following figure for an example:

NoteConfigure at least one rule. To add a rule, click + Add Rule.
You can configure up to 10 scheduling conditions.
You can set the relationship between conditions to AND or OR.
Validation scope
For time-based scheduling or task-triggered scheduling, the validation scope must be a Custom validation scope. For data update-triggered scheduling, the validation scope can be either Partitions updated by task
or a Custom validation scope.
Partitions updated by task: If a task updates one or more partitions, the quality check runs on those updated partitions.
NoteIn dynamic partition scenarios, the partition might not be resolved, and no quality check will be performed.
Volatility check rules, such as those that check partition size, partition row count, or field statistics, require a specified partition and do not support the Partitions updated by task option.
For non-partitioned tables, if data is updated, the entire table is checked.
Custom validation scope: For scenarios where partitions cannot be automatically parsed, you can define a custom validation scope by specifying a partition expression based on the business date or execution date.
Partition expression: This is an editable drop-down list. You can either enter the partition expression directly, such as
ds='${yyyyMMdd}', or select a built-in expression and modify it for quick configuration. For more details on supported expressions, see Built-in partition expression types.NoteIf you have multiple conditions to validate, you can connect them by using and or or, such as
province="Zhejiang" and ds<=${yyyyMMdd}.If a filter condition is configured in the quality rule, the system combines it with the validation scope expression using an AND operator. Both conditions are then used to filter the data for the check.
The partition expression supports a full table scan.
Important: A full table scan consumes significant computing resources and is not supported by all checks. We recommend configuring a partition expression to avoid a full table scan.
Validation Scope Preview: By default, the preview is based on the current business date.
Click OK to complete the schedule configuration.
Scheduling Configuration List
After you create a schedule, you can view, edit, clone, and delete it in the scheduling configuration list.

Area | Description |
①Filter and search area | Search by schedule name. Filter by time-based scheduling, data update-triggered scheduling, or task-triggered scheduling. |
②List area | Displays the Schedule Name, scheduling type, Last Updater, and Last Update Time for each schedule. |
③Actions area | You can edit, clone, or delete a schedule.
|
Alert Configuration
You can create different alert configurations for your rules to customize notifications. For example, you can configure phone call alerts when strong rules are triggered and SMS alerts when weak rules are triggered. If a single rule matches multiple alert configurations, you can define a policy to determine which configuration applies.
You can create up to 20 alert configurations for each monitored object.
Click the Alert Configuration tab, and then click the Create Alert Configuration button to open the Create Alert Configuration dialog box.
In the New Alert Configuration dialog box, configure the parameters.
Parameter
Description
Scope
You can select All Rules, All Strong Rules, All Weak Rules, or Custom.
NoteFor each monitored object, you can create one alert configuration for each of the following scopes: All Rules, All Strong Rules, and All Weak Rules. New rules automatically use the configuration that matches their strength. To modify a configuration for one of these scopes, you must edit the existing one.
The Custom scope lets you select up to 200 existing rules for the current monitored object.
Alert configuration name
The name must be unique for each monitored object and can be up to 256 characters long.
Alert recipient
Configure the alert recipients and notification channels. You must select at least one alert recipient and one notification channel.
Alert recipient: You can choose from Custom, On-call Schedule, and Quality Owner.
You can configure up to five custom alert recipients and up to three on-call schedules.
Notification channel: You can select from Phone Call, Email, SMS, DingTalk, Feishu, WeCom, and Custom Channel. You can manage these notification channels in Configure Channel Settings.
Click OK to save the alert configuration.
Alert Configuration List
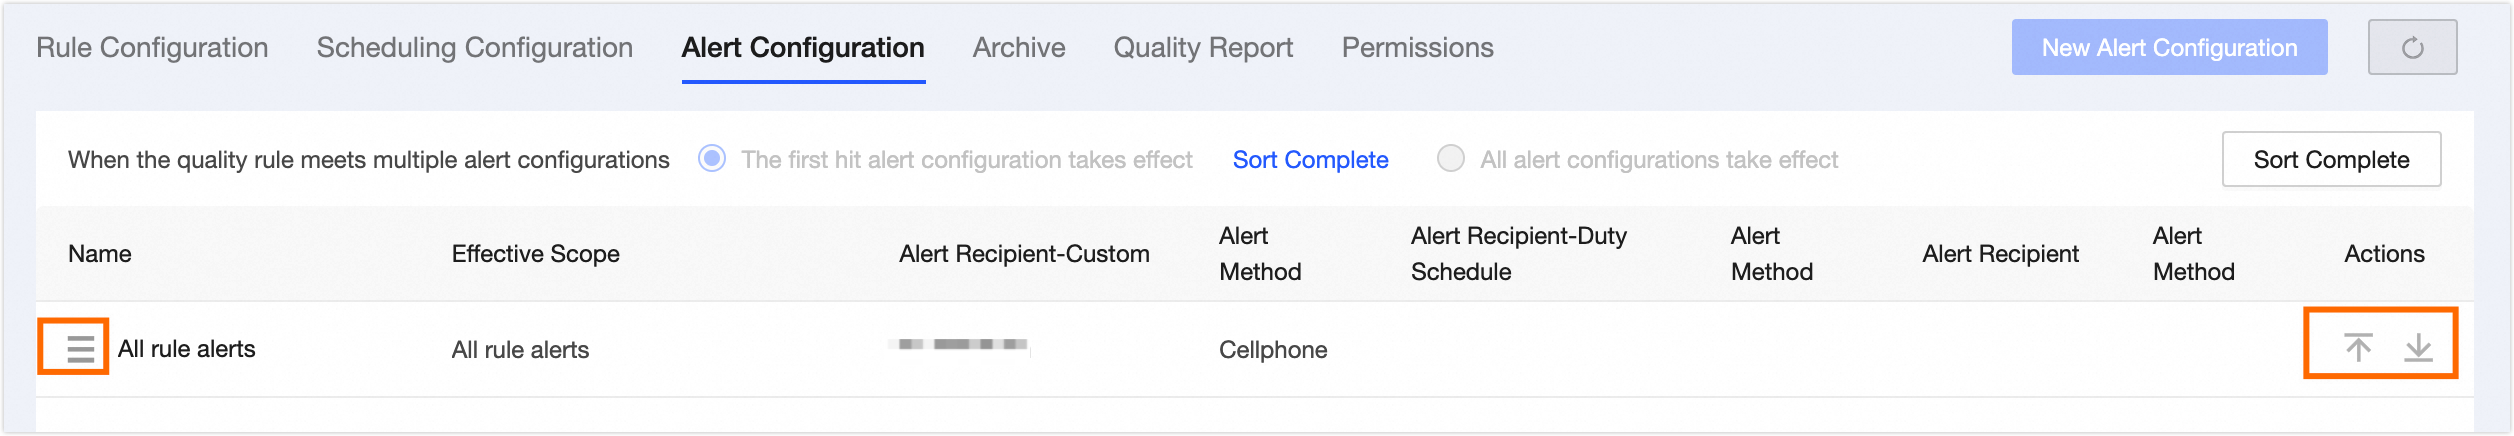
After you create an alert configuration, you can sort, edit, or delete it.

No. | Description |
① Sorting area | You can define a policy for when a quality rule matches multiple alert configurations:
|
② List area | This area displays the name, scope, specific recipients, and corresponding notification channels for each alert configuration. Scope: For custom alert configurations, you can view the names of the configured objects and rules. If a configured rule is deleted, its name is no longer visible. We recommend updating the alert configuration in this case.
|
③ Actions area | You can edit and delete your alert configurations.
|
 icon or use the icons in the Actions column to move it. From left to right, the icons are Move to Top and Move to Bottom. Click Finish Sorting when you are done.

Add An Anomaly Archive Table
An anomaly archive table stores records that fail quality rule checks.
Click the Exception Archiving tab, then click + Add Exception Archiving Table. The Add Exception Archiving Table dialog box opens.
In the Add Exception Archiving Table dialog box, configure the following parameters.
For Add Method, select Create Table or Select Existing Table. Because the
anomaly archive tableincludes additional quality checkcolumns, anomaly data is archived separately and not written to the original data table.Create Table: Specify a custom table name or use the default, current_table_name_exception_data. The name must be no more than 128 characters long and can contain only letters, digits, underscores (_), and periods (.). The new table is created in the same database or
data sourceas the monitored table.If the monitored table is a
physical table, theanomaly archive tableis created in the sameprojectas the monitored table.If the monitored table is a
dimension logical tableorfact logical table, theanomaly archive tableis created in the sameprojectby default. You can also manually specify aprojectwithin the sameworkspace, for example,projectA.table_name.If the monitored table is a
summary logical table, specify aprojectname within the sameworkspacefor the archive table. Otherwise, the table is automatically created in one of the projects within the monitored table'sworkspace.The
anomaly archive tablemust contain allcolumnsfrom the monitored table, in addition tocolumnsfor quality checks. The DDL statement is structured as follows:create table current_table_name_exception_data (dataphin_quality_tenant_id varchar(64) comment 'tenant ID' , dataphin_quality_rule_id varchar(64) comment 'quality rule ID', dataphin_quality_rule_name varchar(256) comment 'quality rule name', dataphin_quality_column_name varchar(1024) comment 'validated column name', dataphin_quality_watch_task_id varchar(128) comment 'monitored object task ID', dataphin_quality_rule_task_id varchar(64) comment 'rule task ID', dataphin_quality_validate_time varchar(64) comment 'quality check time', dataphin_quality_archive_mode varchar(32) comment 'anomaly archiving mode, ONLY_ERROR_FIELD/FULL_RECORD', dataphin_quality_error_data string comment 'anomaly data', ljba_id bigint comment 'ljba_primary key', ljb_id bigint comment 'ljb_primary key', col_tinyint tinyint comment 'column type is TINYINT and lowercase', col_tinyint_02 tinyint comment '2', col_smallint smallint comment 'column type is SMALLINT and lowercase', col_smallint_02 smallint comment '4', col_int int comment 'column type is INT and lowercase', col_int_02 int comment '6', col_bigint bigint comment 'column type is BIGINT and lowercase', col_bigint_02 bigint comment '8', col_float float comment 'column type is FLOAT and lowercase', col_float_02 float comment '10', col_double double comment 'column type is DOUBLE and lowercase', col_double_02 double comment '11', col_decimal decimal(38,18) comment 'column type is DECIMAL(38,18) and lowercase', col_decimal_02 decimal(38,18) comment '12', col_varchar varchar(500) comment 'column type is VARCHAR(500) and lowercase', col_varchar_02 varchar(500) comment '13', col_char char(10) comment 'column type is CHAR(10) and lowercase', col_char_02 char(10) comment '14', col_string string comment 'column type is STRING and lowercase', col_string_02 string comment '15', col_date date comment 'column type is DATE and lowercase', col_date_02 date comment '16', col_datetime datetime comment 'column type is DATETIME and lowercase', col_datetime_02 datetime comment '17', col_timestmap timestamp comment 'column type is TIMESTAMP and lowercase', col_timestmap_02 timestamp comment '18', col_boolean boolean comment 'column type is BOOLEAN and lowercase', col_boolean_02 boolean comment '19', col_binary binary comment 'column type is BINARY and lowercase', col_binary_02 binary comment '20', col_array array<int> comment 'column type is ARRAY<int> and lowercase', col_array_02 array<string> comment '21', col_map map<string,string> comment 'column type is MAP<string, string> and lowercase', col_map_02 map<string,int> comment '22', ds string comment 'date partition, yyyyMMdd' ) partitioned by (dataphin_quality_validate_date string comment 'validation date (partition column)');
Select Existing Table: Select a table from the same
projectordata source. The selected table must contain all thecolumnsfrom the monitored table and the additional quality checkcolumns. Click View Exception Archiving Table DDL to view the requiredCREATE TABLEstatement. The format is as follows:create table current_table_name_exception_data (dataphin_quality_tenant_id varchar(64) comment 'tenant ID' , dataphin_quality_rule_id varchar(64) comment 'quality rule ID', dataphin_quality_rule_name varchar(256) comment 'quality rule name', dataphin_quality_column_name varchar(1024) comment 'validated column name', dataphin_quality_watch_task_id varchar(128) comment 'monitored object task ID', dataphin_quality_rule_task_id varchar(64) comment 'rule task ID', dataphin_quality_validate_time varchar(64) comment 'quality check time', dataphin_quality_archive_mode varchar(32) comment 'anomaly archiving mode, ONLY_ERROR_FIELD/FULL_RECORD', dataphin_quality_error_data string comment 'anomaly data', ljba_id bigint comment 'ljba_primary key', ljb_id bigint comment 'ljb_primary key', col_tinyint tinyint comment 'column type is TINYINT and lowercase', col_tinyint_02 tinyint comment '2', col_smallint smallint comment 'column type is SMALLINT and lowercase', col_smallint_02 smallint comment '4', col_int int comment 'column type is INT and lowercase', col_int_02 int comment '6', col_bigint bigint comment 'column type is BIGINT and lowercase', col_bigint_02 bigint comment '8', col_float float comment 'column type is FLOAT and lowercase', col_float_02 float comment '10', col_double double comment 'column type is DOUBLE and lowercase', col_double_02 double comment '11', col_decimal decimal(38,18) comment 'column type is DECIMAL(38,18) and lowercase', col_decimal_02 decimal(38,18) comment '12', col_varchar varchar(500) comment 'column type is VARCHAR(500) and lowercase', col_varchar_02 varchar(500) comment '13', col_char char(10) comment 'column type is CHAR(10) and lowercase', col_char_02 char(10) comment '14', col_string string comment 'column type is STRING and lowercase', col_string_02 string comment '15', col_date date comment 'column type is DATE and lowercase', col_date_02 date comment '16', col_datetime datetime comment 'column type is DATETIME and lowercase', col_datetime_02 datetime comment '17', col_timestmap timestamp comment 'column type is TIMESTAMP and lowercase', col_timestmap_02 timestamp comment '18', col_boolean boolean comment 'column type is BOOLEAN and lowercase', col_boolean_02 boolean comment '19', col_binary binary comment 'column type is BINARY and lowercase', col_binary_02 binary comment '20', col_array array<int> comment 'column type is ARRAY<int> and lowercase', col_array_02 array<string> comment '21', col_map map<string,string> comment 'column type is MAP<string, string> and lowercase', col_map_02 map<string,int> comment '22', ds string comment 'date partition, yyyyMMdd' ) partitioned by (dataphin_quality_validate_date string comment 'validation date (partition column)');
Lifecycle: This option is available only for data tables that use MaxCompute as the compute engine. If you create a new table, you can specify a custom number of days, or select 7 days, 14 days, 30 days, or 360 days. If you select an existing table, the system displays the lifecycle that is configured for the table.
Max Archived Records: This setting is available only for tables that use the
MaxComputeorHadoop seriescompute engine. This setting limits the number of anomaly records archived from a singlequality ruleexecution. If the number of anomalies exceeds this limit, the system archives only the specified number of records. Although excess records are not saved to the archive table, you can view them in thelog. The default is 10,000 records per check. Select 10,000, 100,000, 500,000, or All, or enter any positive integer.NoteA large
anomaly archive tablecan affect query performance. Configure this setting to meet your business requirements.
Click OK to add the
anomaly archive table.Select Automatically set as effective archive table after creation to make this table the default archive destination for new quality rules.
Anomaly Archive Table List
After a table is successfully added, the first one is the effective archive table by default. Click the name of an anomaly archive table to view its table structure. Additionally, you can set an archive table as the effective archive table, delete it, or edit it.
Set as Effective Archive Table: When you set a table as the
effective archive table, all quality rules configured for custom archiving will begin archiving anomaly data to this table.Delete: This action removes only the reference to the
anomaly archive tablefrom the configuration; it does not delete the underlyingphysical table. You can re-add the reference later.Edit: This option is available only for tables that use the
MaxComputeorHadoop seriescompute engine. Use this option to modify thelifecycleand themaximum number of archived records.
Quality Report
Click the quality report tab to view the rule check overview and rule check details.
You can quickly filter rule check details by abnormal result, partition time, or keywords in the rule or object name.
In the Operations column of the rule check details list, click the
 icon to view the rule check details.
In the Operations column of the rule check details list, click the
 icon to view the execution log.
Configure Quality Rule Permissions
Click the permission management tab to configure the view details permission. This permission determines which members can view validation records, quality rule details, and quality reports.
view details: Select all members or only members with quality management permission for the current object.
Click OK to save the configuration.
Quality Rule Running Configuration
If a
quality ruletask exceeds therun timeout, it is automatically terminated, and itsexecution resultis set to failed. You can view theexecution logon thecheck recorddetails page.For a failed
quality ruletask that is retried, you can view theexecution logfor all retry attempts on thecheck recorddetails page.The latest
running configurationapplies to allquality rulesfor amonitored object, including new rules and existing rules that have not yet been executed.
Click the Running Configuration tab, and then click Edit at the bottom to configure the following parameters.
Parameter
Description
Coverage
Specifies the scope of rules affected by this configuration. Options include: All rules, All strong rules, All weak rules, and Custom.
Run timeout
The maximum allowed run time for a
quality ruletask. The run time does not include time spent waiting for resources or scheduling. If a task exceeds thisrun timeout, the system stops the task and sets itsexecution resultto failed. The default is 1 hour. You can specify a value between 0 and 2 hours, with up to two decimal places.Automatic retry
Determines whether to automatically rerun a failed
quality ruletask. This feature is disabled by default. If you enableautomatic retry, you can configure the retry attempts and retry interval.Retry attempts: The number of times to retry a failed task. The default is 1. You can specify an integer from 1 to 3.
Retry interval: The interval in minutes between
retry attempts. The default is 0. You can specify an integer from 0 to 10.
Click OK to save the
running configuration.
Next Steps
After configuring quality rules, you can view them on the table rule list page in Dataphin. For more information, see View the monitoring object list.