Fluid with JindoFS: An Acceleration Tool for Alibaba Cloud OSS
By Wang Tao (Yangli), Che Yang (Biran)
Fluid
Fluid is an open-source native orchestration and acceleration engine for a distributed dataset on Kubernetes, which mainly serves data-intensive applications in cloud-native scenarios, such as big data applications, AI applications and so on. By using the data layer abstraction provided by Kubernetes service, data can be flexibly and efficiently moved, replicated, converted and managed between storage sources such as HDFS, OSS, and Ceph, and cloud-native application computing in Kubernetes upper layers.
The specific data operations are transparent to users, so users no longer have to worry about the efficiency of accessing remote data and the convenience of managing data sources. And making the O&M and scheduling decisions for Kubernetes is no longer a problem. Users only need to access the abstracted data through the most natural Kubernetes native data volumes. The remaining tasks and underlying details are all submitted to Fluid.
Currently, the Fluid project focuses on dataset orchestration and application orchestration. Dataset orchestration caches data of the specified dataset to a Kubernetes node with a specified feature, while application orchestration schedules the specified application to a node that can or has stored the specified dataset. The two can also be combined to provide collaborative orchestration, which schedules the node resources based on the needs of the dataset and application.
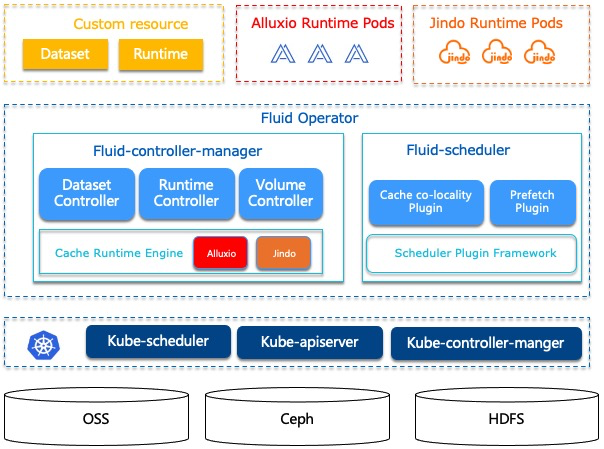
Then, it is about the dataset in Fluid. A dataset is a logically related set of data that is used by computing engines, such as Spark for big data and TensorFlow for AI scenarios. The intelligent application and scheduling of datasets will create core value in the industry. Actually, there are multiple dimensions for dataset management, such as security, version management, and data acceleration.
From the dimension of data acceleration, dataset management is provided. In Dataset, Runtime, an execution engine, is defined to implement capabilities such as dataset security, version management, and data acceleration. Runtime defines a series of lifecycle interfaces, and the interfaces can be implemented to support dataset management and acceleration. Currently, the Runtime supported by Fluid includes AlluxioRuntime and JindoRuntime.
Fluid is designed to provide an efficient and convenient data abstraction for AI and cloud-native big data applications. It abstracts data from storage for the following functions:
- Fuse data and computing through data affinity scheduling and distributed caching engine acceleration, thus accelerating the data access of computing.
- Make the data independent from the storage for management. Implement resource isolation through namespaces in Kubernetes for secure data isolation.
- Combine the data from different storage for computing, which is likely to eliminate the data islanding effect caused by the differences between different storage.
JindoRuntime
To learn about JindoRuntime of Fluid, JindoFS should be introduced first. It is the engine layer of JindoRuntime.
JindoFS is a big data storage optimization engine developed by Alibaba Cloud for Object Storage Service (OSS). Fully compatible with Hadoop file system interfaces, JindoFS provides a more flexible and efficient computing storage solution for users. At present, JindoFS has been verified to support all computing services and engines in Alibaba Cloud E-MapReduce (EMR), including Spark, Flink, Hive, MapReduce, Presto, Impala and so on. JindoFS supports two storage modes, block storage mode and cache mode. In Block storage mode, files are stored as data blocks in OSS and data backup can be used locally to accelerate caching. Metadata is managed by a local namespace service. As thus, file data can be built through local metadata and block data. The cache mode stores files on OSS. This mode is compatible with the existing OSS file system. Users can access the original directory structure and files through OSS. Additionally, this mode caches data and metadata, which improves the performance of data reading and writing. With this mode, users can seamlessly connect to the existing data in OSS without migrating data to OSS. In terms of data synchronization, users can select different metadata synchronization policies as needed.
In Fluid, JindoRuntime uses the cache mode of JindoFS to access and cache remote files. For the usage of JindoFS alone in other environments to access OSS, download JindoFS SDK for deployment and usage as instructed in the user guide. JindoRuntime is an execution engine implementing the data management and caching of Dataset based on the JindoFS distributed system developed by the Alibaba Cloud EMR team.
Fluid manages and schedules JindoRuntime to achieve dataset visibility, auto scaling, data migration, and computing acceleration. Compatible with the native Kubernetes environment, using and deploying JindoRuntime on Fluid can be easily implemented without much preparation. Considering the object storage features, the Navite framework is adopted to optimize the performance. And cloud data security features such as password-free and checksum verification are also supported.
Advantages of JindoRuntime
JindoRuntime provides access and cache acceleration of Alibaba Cloud OSS and enables the use of massive OSS files as easily as the local disk can do by means of the Portable Operating System Interface (POSIX) of FUSE. It has the following features:
1. Excellent Performance
- Outstanding reading/writing performance of OSS: JindoRuntime enhances the efficiency and stability of reading and writing by deeply integrating OSS. The OSS access interface and the cold data access performance, especially in reading and writing small files, are optimized through the native layer.
- Multiple distributed cache policies: JindoRuntime supports single TB level file caching and metadata caching policies, performing prominently in large-scale AI training and practical testing in data lake scenarios.
2. Safety and Reliability
- Authentication security: Support password-free access of Security Token Service (STS) and native secret key encryption of Kubernetes in Alibaba Cloud.
- Data security: Adopt security policies such as checksum verification and client data encryption to protect cloud data and user information.
3. Ease of Use
JindoRuntime is compatible with the native Kubernetes environment. It connects the data volume through custom resource definitions. And it can be easily used and deployed without much preparation.
4. Lightweight
Since the underlying layer is based on C++, the overall structure is lightweight with low extra overhead of the various OSS access interfaces.
JindoRuntime's Performance
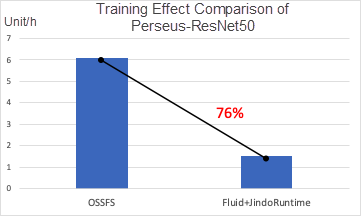
Arena was used to train the ResNet-50 model on ImageNet dataset based on the Kubernetes cluster. When the local cache is opened, JindoRuntime based on JindoFS performed significantly better than the open source OSSFS with the training time reduced by 76 percent. This test is described in detail in subsequent articles.
Quick-start Guide to JindoRuntime
It is simple to use JindoRuntime. It takes only about 10 minutes to deploy the required JindoRuntime environment with the basic Kubernetes and OSS environments. Do as follows:
- Create a namespace
kubectl create ns fluid-system- Download
[fluid-0.5.0.tgz](http://smartdata-binary.oss-cn-shanghai.aliyuncs.com/fluid/332cache/fluid-0.5.0.tgz) - Use Helm to install Fluid
helm install --set runtime.jindo.enabled=true fluid fluid-0.5.0.tgz- View the running status of Fluid
$ kubectl get pod -n fluid-system
NAME                                         READY   STATUS    RESTARTS   AGE
csi-nodeplugin-fluid-2mfcr                   2/2     Running   0          108s
csi-nodeplugin-fluid-l7lv6                   2/2     Running   0          108s
dataset-controller-5465c4bbf9-5ds5p          1/1     Running   0          108s
jindoruntime-controller-654fb74447-cldsv     1/1     Running   0          108s
The number of csi-nodeplugin-fluid-xx should be the same as the number of nodes in Kubernetes cluster.
- Create a dataset and JindoRuntime
Before creating a dataset, create a secret to store the fs.oss.accessKeyId and fs.oss.accessKeySecret of OSS to prevent the plaintext from exposure. Then, Kubernetes will encrypt the created secret and fill the key and secret information into the mySecret.yaml file.
apiVersion: v1
kind: Secret
metadata:
  name: mysecret
stringData:
  fs.oss.accessKeyId: xxx
  fs.oss.accessKeySecret: xxx
Generate secret:
kubectl create -f mySecret.yamlCreate a resource.yaml file that contains two parts:
- The first part contains a dataset and ufs dataset information. Create a Dataset CRD object in which the source of the dataset is described.
- Create a JindoRuntime in the second part. It is equivalent of starting a JindoFS cluster for cache services.
apiVersion: data.fluid.io/v1alpha1
kind: Dataset
metadata:
  name: hadoop
spec:
  mounts:
    - mountPoint: oss://<oss_bucket>/<bucket_dir>
      options:
        fs.oss.endpoint: <oss_endpoint>
      name: hadoop
      encryptOptions:
        - name: fs.oss.accessKeyId
          valueFrom:
            secretKeyRef:
              name: mysecret
              key: fs.oss.accessKeyId
        - name: fs.oss.accessKeySecret
          valueFrom:
            secretKeyRef:
              name: mysecret
              key: fs.oss.accessKeySecret
---
apiVersion: data.fluid.io/v1alpha1
kind: JindoRuntime
metadata:
  name: hadoop
spec:
  replicas: 2
  tieredstore:
    levels:
      - mediumtype: HDD
        path: /mnt/disk1
        quota: 100Gi
        high: "0.99"
low: "0.8"- mountPoint: oss:/// indicates the path on which UFS is mounted. The path does not include endpoint information.
- fs.oss.endpoint: It is the endpoint information of the oss bucket, which can be the address of public networks or inner networks.
- replicas: It represents the number of workers for creating the JindoFS cluster.
- mediumtype: Currently, JindoFS only supports HDD, SSD, or MEM.
- path: It refers to the storage path. Currently, only one disk is supported. Another disk is also required to store files such as log when choosing MEM as cache.
- quota: It means the maximum cache capacity in unit Gi.
- high/low: Each is the upper/lower limit of water level.
kubectl create -f resource.yamlCheck the status of the dataset:
$ kubectl get dataset hadoop
NAME     UFS TOTAL SIZE   CACHED   CACHE CAPACITY   CACHED PERCENTAGE   PHASE   AGE
hadoop 210MiB 0.00B 180.00GiB 0.0% Bound 1h- Create an application container to experience acceleration
Create an application container or submit a machine learning task to enjoy the JindoFS acceleration service.
Next, create an application container app.yaml to use this dataset. The acceleration effect is displayed by comparing the time of multiple access of the same data.
apiVersion: v1
kind: Pod
metadata:
  name: demo-app
spec:
  containers:
    - name: demo
      image: nginx
      volumeMounts:
        - mountPath: /data
          name: hadoop
  volumes:
    - name: hadoop
      persistentVolumeClaim:
        claimName: Hadoop
Create the application container with kubectl:
kubectl create -f app.yamlView the file size:
$ kubectl exec -it demo-app -- bash
$ du -sh /data/hadoop/spark-3.0.1-bin-hadoop2.7.tgz
210M  /data/hadoop/spark-3.0.1-bin-hadoop2.7.tgz
The cp observation time for the file is 18 seconds:
$ time cp /data/hadoop/spark-3.0.1-bin-hadoop2.7.tgz /dev/null

real  0m18.386s
user  0m0.002s
sys 0m0.105s
Checking the dataset cache, 210 megabytes of data has been cached locally.
$ kubectl get dataset hadoop
NAME     UFS TOTAL SIZE   CACHED   CACHE CAPACITY   CACHED PERCENTAGE   PHASE   AGE
hadoop   210.00MiB       210.00MiB    180.00GiB        100.0%           Bound   1h
To prevent the effects of other factors such as page cache, delete the previous application container and create the same application to access the same file. Since the file has been cached by JindoFS, the time required for the second access is much shorter.
kubectl delete -f app.yaml && kubectl create -f app.yamlThe cp observation time for the file is 48 milliseconds which is 300 times shorter.
$ time cp /data/hadoop/spark-3.0.1-bin-hadoop2.7.tgz /dev/null

real  0m0.048s
user  0m0.001s
sys 0m0.046s-
Clean up the environment
- Delete the application and the application container
- Delete JindoRuntime
kubectl delete jindoruntime Hadoop- Delete dataset
kubectl delete dataset HadoopThe quick start and understanding of JindoFS on Fluid as well as final environment cleanup are demonstrated in this simply example. For detailed introductions of more features and use of Fluid JindoRuntime, see subsequent articles.
- GitHub address of the Fluid project: https://github.com/fluid-cloudnative/fluid
- Home page of the Fluid project: http://pasa-bigdata.nju.edu.cn/fluid/index.html
About the Authors
Wang Tao, nicknamed Yangli, is an EMR development engineer at Alibaba Computing Platform Business Department. Currently, he is engaged in the development and optimization of open source big data storage and computing.
Che Yang, nicknamed Biran, is a senior technical expert for Alibaba cloud-native application platform. He is involved in the development of Kubernetes and container-related products. He is the main author and maintainer of GPU shared scheduling especially focusing on constructing a machine learning platform system based on cloud-native technologies.
Read previous post:
Simple Introduction: Building Dubbo-go from Scratch and Dubbo Usage
Read next post:
RocketMQ-Spring: The Most Popular Messaging Implementation in the Spring Ecosystem
-

-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Comments
-
-
Alibaba Cloud Native Community
831 posts | 61 followers
Follow
Related Products
-
 Hybrid Cloud Distributed Storage
Provides scalable, distributed, and high-performance block storage and object storage services in a software-defined manner.
Learn More -
 OSS(Object Storage Service)
An encrypted and secure cloud storage service which stores, processes and accesses massive amounts of data from anywhere in the world
Learn More -
 Storage Capacity Unit
Plan and optimize your storage budget with flexible storage services
Learn More -
 Hybrid Cloud Storage
A cost-effective, efficient and easy-to-manage hybrid cloud storage solution.
Learn More
More Posts by Alibaba Cloud Native Community
- Best Practices for Skill Evaluation and Optimization Based on Alibaba Cloud AgentLoop
- DeepSeek Harness Evaluation Practice Based on Alibaba Cloud AgentLoop
- 97.1% Lower Gateway Latency: Open-Source Higress vs. Alibaba Cloud AI Gateway Serverless Enterprise Edition
- Alibaba Cloud's Open-Source AI Agent Handbook, 3K+ GitHub Stars
- DeepSeek Harness: A Practical Guide to Comprehensive Observability
- Alibaba Cloud AI Gateway Intelligent Routing Is Now Live
- After Everything Becomes a Plugin: A New Paradigm for Agent Engineering
- AgentScope Service: Open-Source Agent Control Plane with DeepSeek Harness Support
- Seamless AI Safety: Integrating Qwen3Guard into Higress with Zero Code Changes
- DeepSeek's SuperAgent and Our Practice